What You Actually Need When Building a Troubleshooting Guide Roadmap
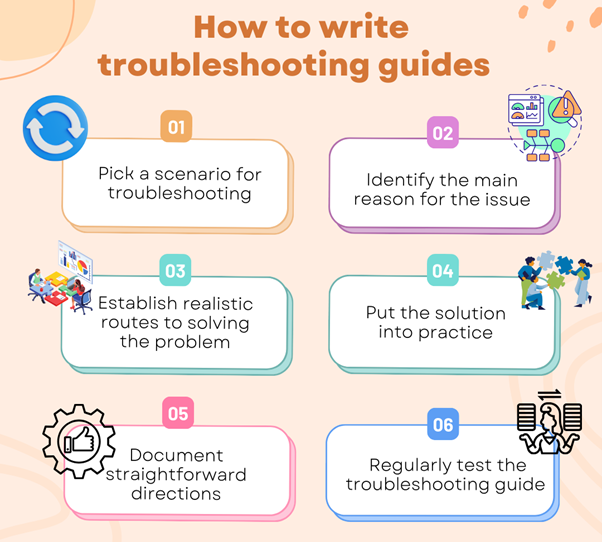
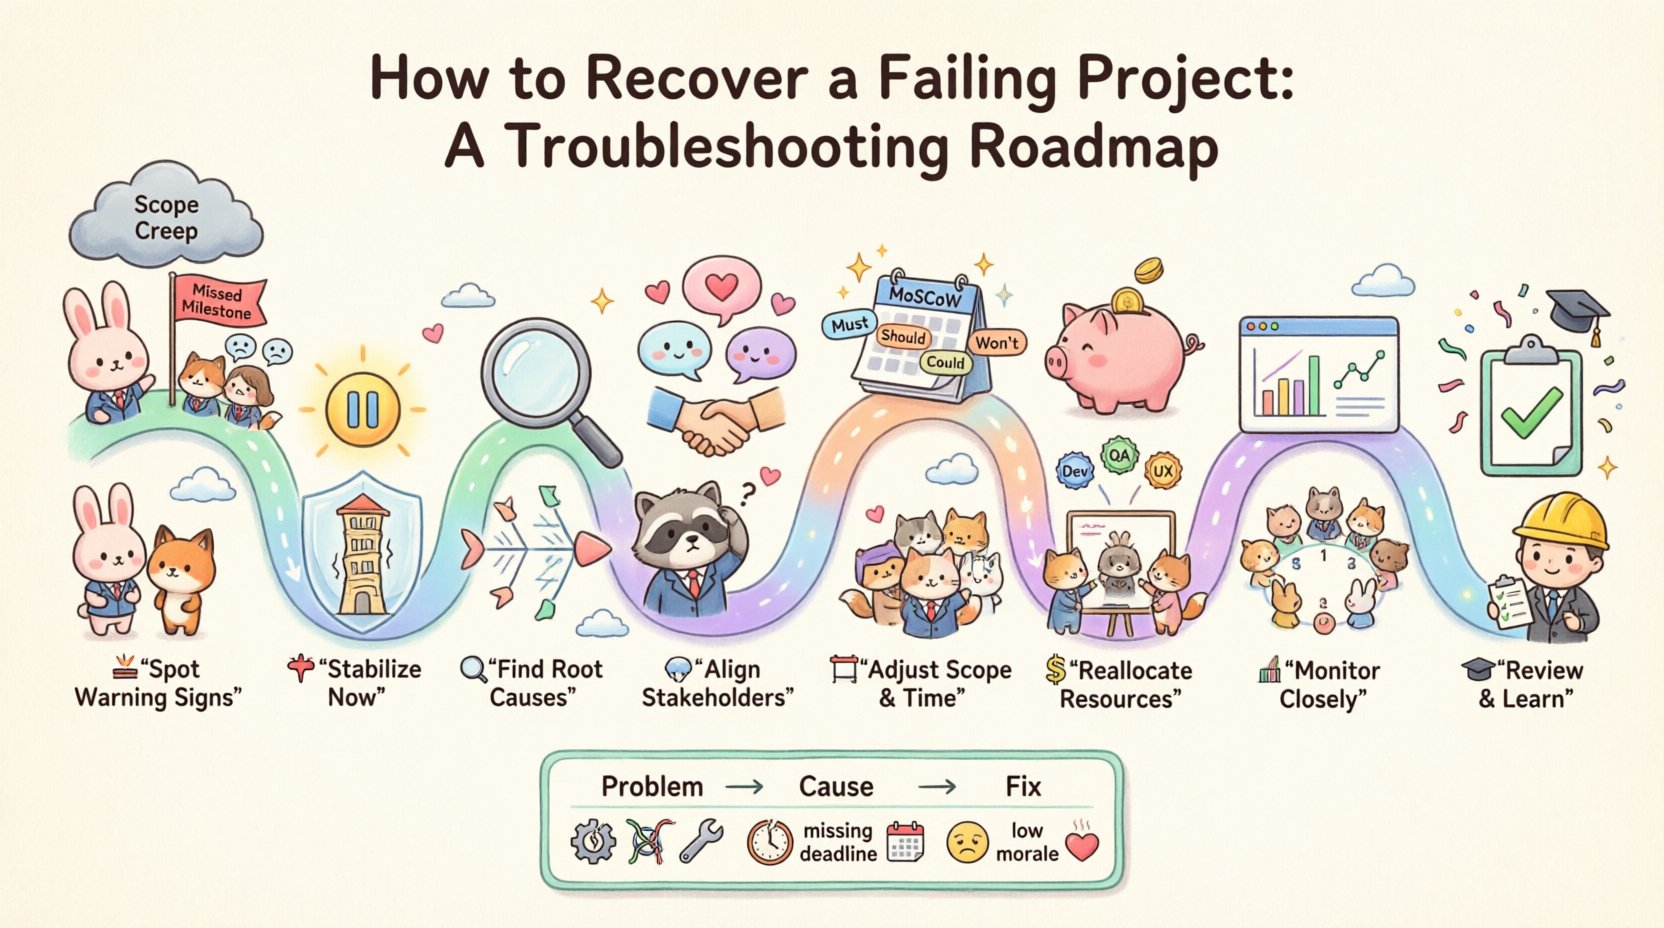
The most common mistake I see teams make is starting with a template instead of starting with their incident logs. I spent three years watching companies copy-paste troubleshooting frameworks from other industries, then wonder why their engineers ignored them during actual outages. The problem isn't the format. It is the gap between what the guide assumes the reader knows and what the reader actually knows when they are reading it at 2 AM with an active production incident. A Troubleshooting Guide Roadmap works when it mirrors the actual decision tree engineers follow, not when it reads like documentation written by someone who has never logged into a server. I built my first real one after we had a cascading failure in a microservices mesh that took four hours to diagnose because every engineer on call was checking different things in isolation. The fix wasn't better tools. It was getting everyone onto the same diagnostic path within the first ten minutes.
The Practical Architecture of a Troubleshooting Guide Roadmap
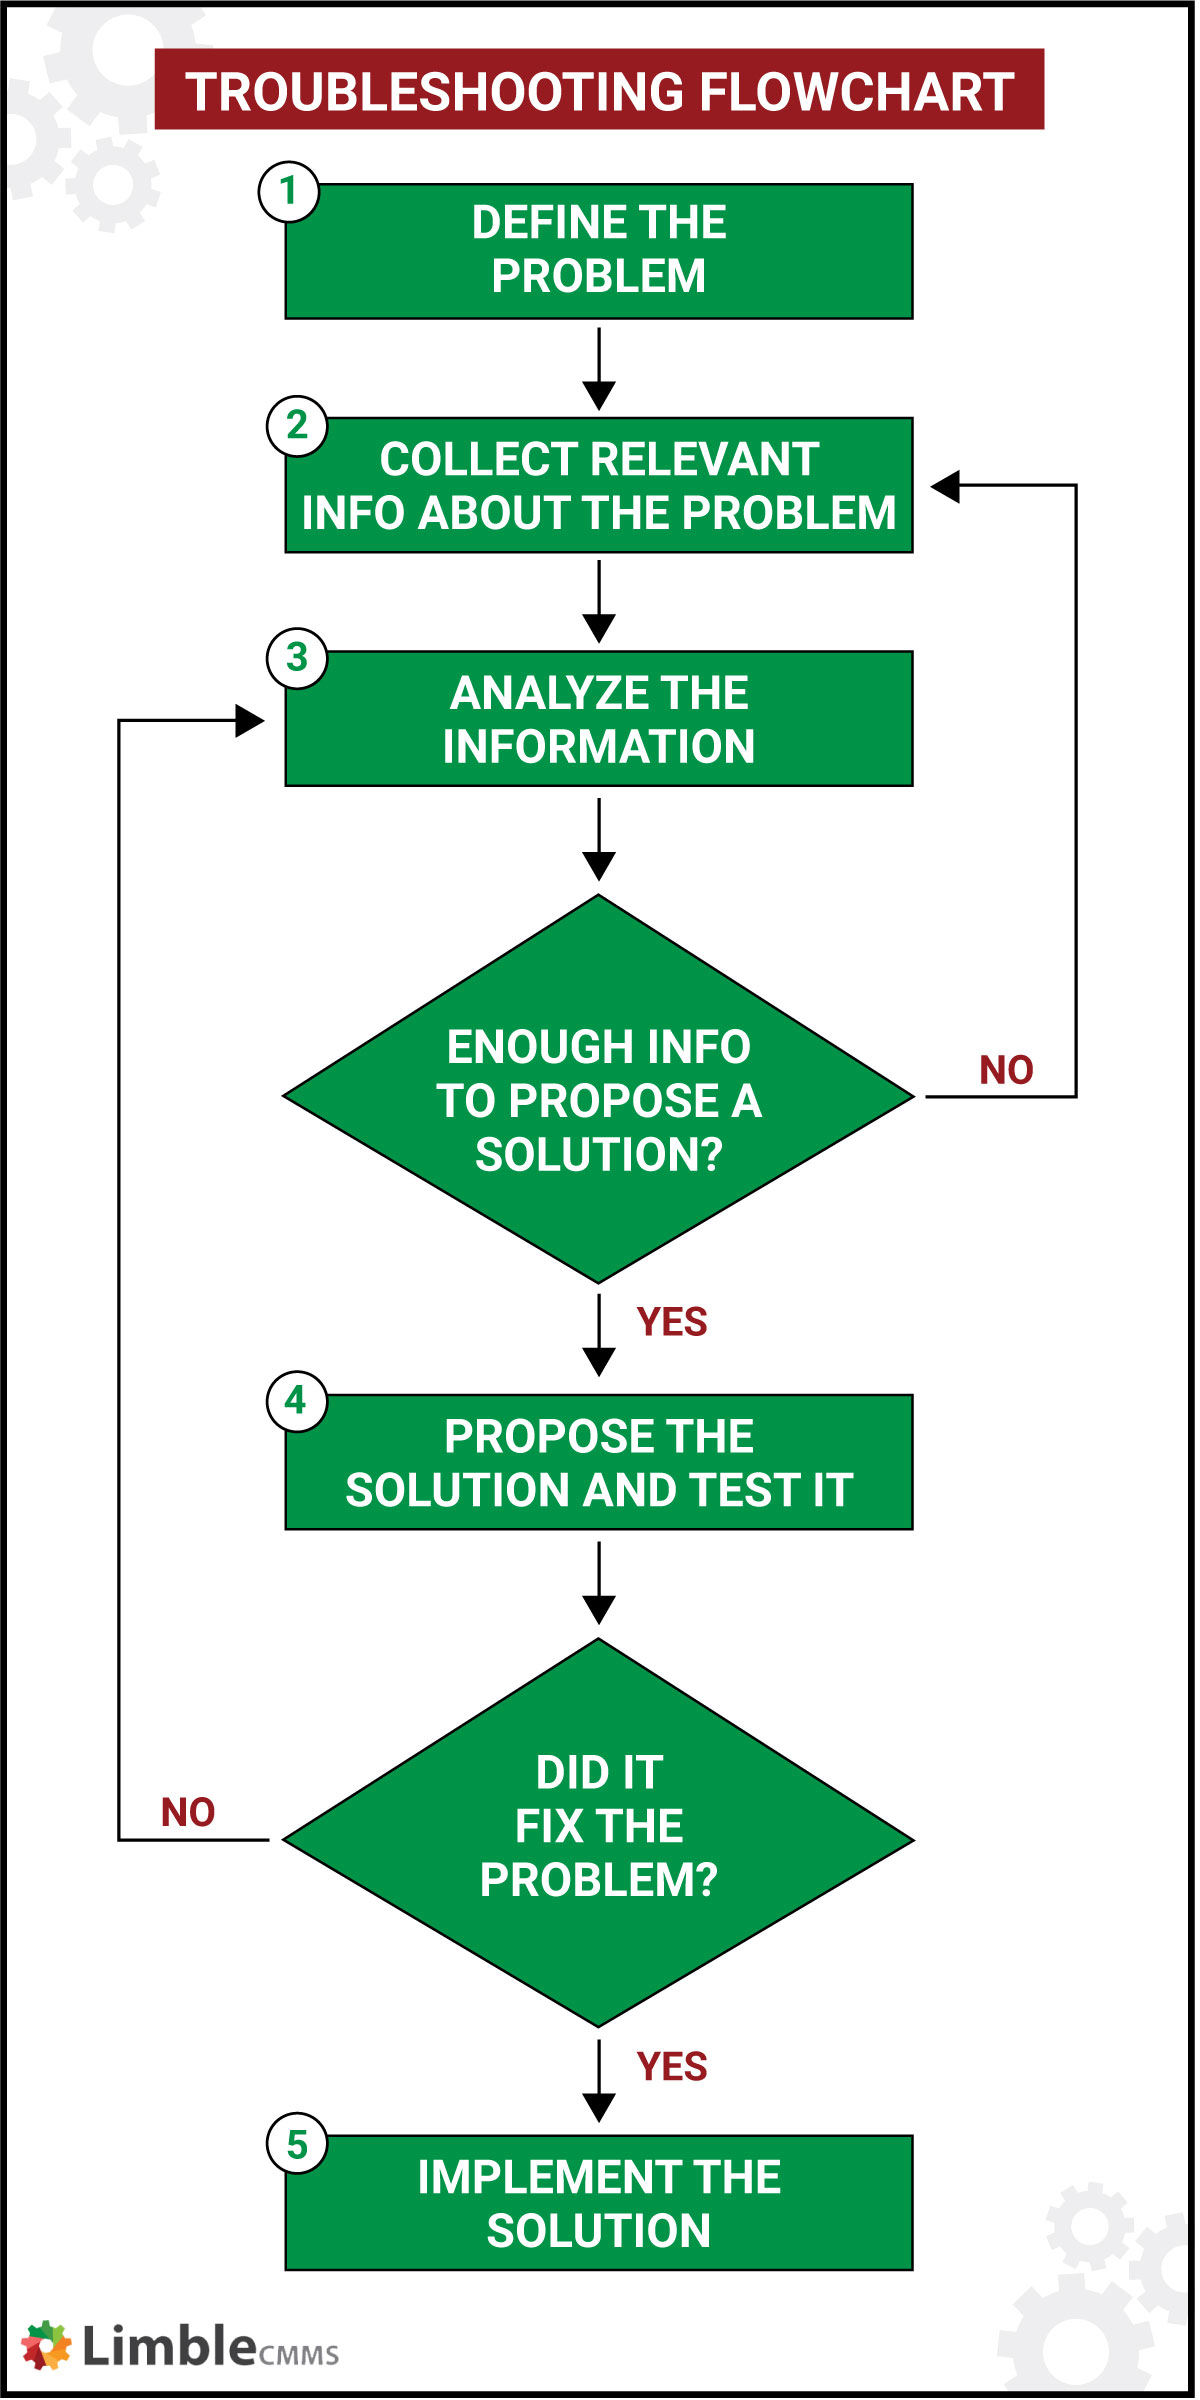
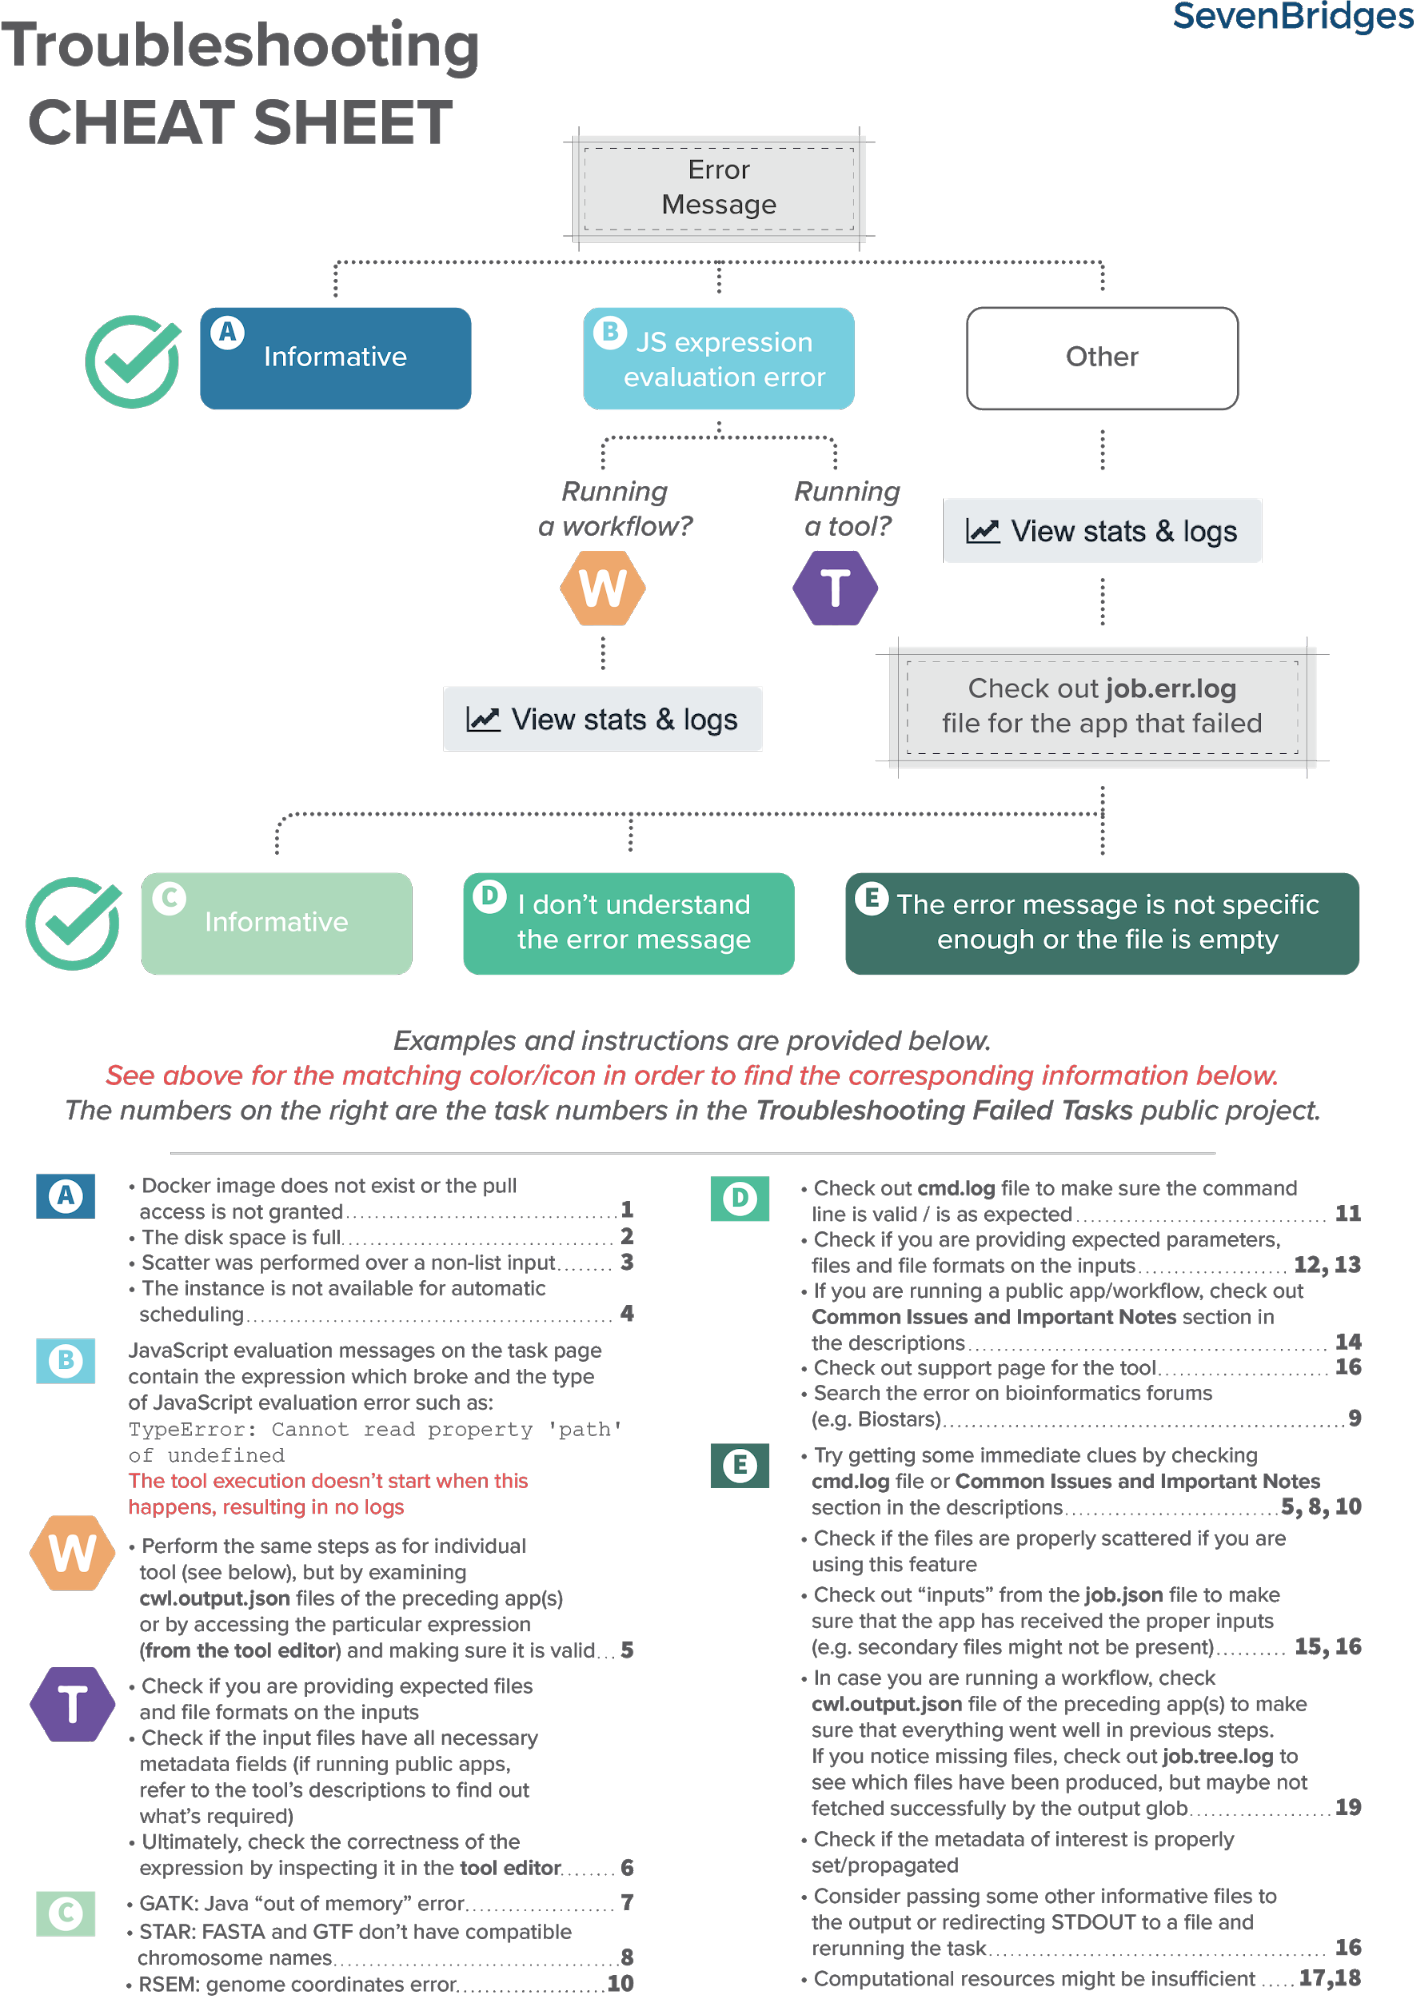
The structure you need is fundamentally a branching logic map, not a linear document. Each node represents a question you ask the system. Each branch is a yes or no answer that sends the engineer down a different path. I use a modified fault tree analysis approach, but stripped of the academic overhead. The key is keeping the decision points binary whenever possible. Complex multi-state branches create cognitive load under pressure. Here is how I actually build one from scratch. I start by pulling the top twenty incidents from the past year. Not the theoretical failures, not the near-misses that got lucky, the actual ones where someone woke up at an unreasonable hour and had to figure something out without clear guidance. I categorize each incident by symptom cluster. You will notice patterns emerge quickly. In my experience, roughly sixty percent of all production issues fall into three or four symptom buckets. The remaining forty percent is the noise that your roadmap should acknowledge but not try to fully preempt. The roadmap itself lives in a markdown file in your repository, not in a separate wiki. This matters more than people admit. Engineers check code before they check documentation during incidents. If the guide is two clicks away in some internal wiki, it will not get checked. The roadmap becomes part of the codebase itself. Review it during incident postmortems. If an incident exposed a branch you missed, add that branch before the next on-call rotation starts.
Decision Node Design That Actually Works
Every decision node needs a clear observable action, a expected result, and a timeout threshold. The timeout is the part nobody includes but the part that saves the most time. When you tell someone to check a service health endpoint, do you also tell them how many seconds to wait before deciding the endpoint is unresponsive? I add a thirty-second cooldown on all network-dependent checks. In practice, this cuts the average initial diagnosis window from twenty minutes down to roughly seven minutes during my team's incidents. Another thing that beginners consistently miss: include the commands directly in the node text, not as separate reference links. When someone is reading the guide under stress, copy-pasting a command from a separate link adds friction and creates opportunities for errors. The command should be visible and ready to execute. I format mine as inline code blocks within each decision node. It takes slightly more space, but the time savings during an active incident are significant. I also make sure each node specifies the minimal permissions required to execute the check. This sounds trivial until someone spends twelve minutes realizing their service account lacks read access to a particular metric namespace. I encountered this exact scenario during a cloud migration. The roadmap assumed all engineers had platform-admin privileges. Half the team could not complete the first three diagnostic steps. Once I added permission requirements to each node, the average time to reach a conclusive diagnosis dropped substantially on the next incident.
Get the Full Details

When the Roadmap Breaks Down
No Troubleshooting Guide Roadmap covers everything. They fail in three predictable scenarios. The first is novel failure modes that do not match any existing symptom cluster. This happens more often than engineers want to admit. The second is when the environment changes faster than the roadmap can be updated. I have seen roadmaps go stale within six months after a major infrastructure migration because nobody updated the diagnostic nodes to reflect the new tooling. The third is when the guide assumes a level of automation that does not exist. If the roadmap says "trigger the automated failover" but the failover requires a manual approval step, the guide is lying to the reader. When novel failure modes occur, the roadmap should explicitly include a fallback path. I route these cases to a dedicated escalation node that describes how to gather evidence rather than how to resolve the issue. Sometimes the goal of a troubleshooting session is not to fix the problem immediately. It is to collect enough structured data so that the next incident of the same type can be handled faster. This is a pragmatic acknowledgment that some problems require research before they require action. The staleness problem is addressed through a simple versioning and review cadence. Every roadmap change gets a version number. I require a review after any P1 or P2 incident that was not covered by an existing node. This catches gaps before they compound. Teams that skip this step find their roadmaps becoming worse than useless over time because they provide false confidence during incidents.
Measurement and Iteration
The only metric that matters for a troubleshooting roadmap is mean time to diagnosis. Not mean time to resolution, which involves remediation work beyond the scope of the guide. Track MTD per incident and compare it against the baseline before the roadmap existed. In my case, adding a properly structured roadmap reduced median MTD from forty-two minutes to eleven minutes across our incident types. The outliers still exist, but the floor improved dramatically because engineers no longer wasted the first twenty minutes figuring out where to even begin. Also track how many times engineers deviate from the roadmap during an incident. If deviation rates are high, the guide is either wrong or poorly matched to how your engineers actually think. I found that my team consistently skipped the preliminary system health checks I included early in the guide. They went straight to application logs. The fix was not to force them to follow the roadmap. It was to move the log-checking step earlier in the sequence and keep the system health checks as a lightweight pre-flight checklist instead of a mandatory opening section. A Troubleshooting Guide Roadmap is not a document you write once and archive. It is a living artifact that gets refined through every incident your team experiences. The value comes from the discipline of updating it after each relevant failure, not from the initial effort of building it. Write it, test it under pressure, break it, fix it, repeat. The roadmap will be better for the wear.