The Problem with Sign Language Tech That Nobody Talks About
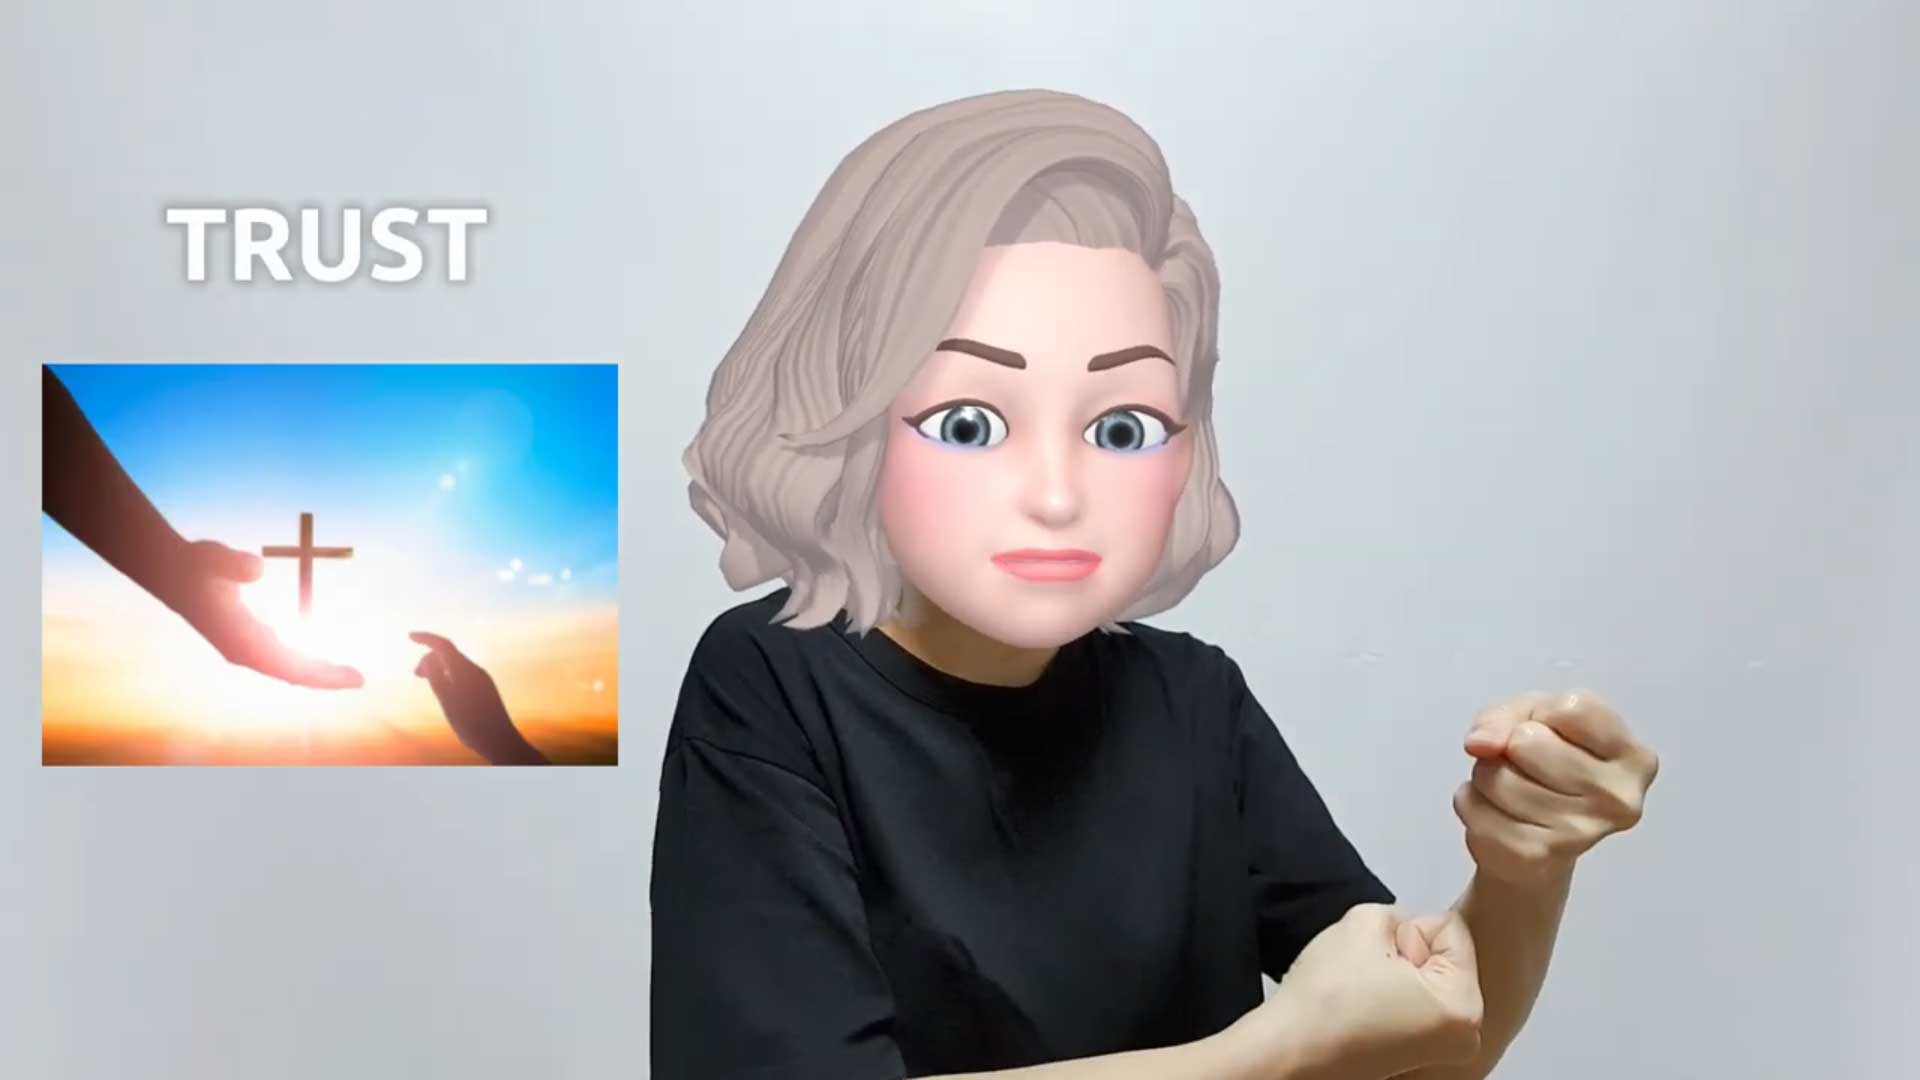
I've been working with sign language recognition and translation systems for about six years now, mostly in the accessibility space. The short version is that the field moves fast enough that most "solutions" out there have significant blind spots. What I'm going to cover here is how to actually evaluate whether a sign language system is trustworthy for production use, not just a demo that looks good on stage. When people talk about Trust In Sign Language, they're usually referring to the gap between academic benchmarks and real-world deployment. A model might hit 94% accuracy on a clean dataset like WSJ or SLR-360, but the moment you put it in front of a diverse signer with different backgrounds, lighting, camera angles, and signing styles, accuracy drops significantly. This isn't a bug, it's a fundamental challenge in the domain. The core issues come down to three things: dataset bias (most training data comes from native American Sign Language signers in controlled studio conditions), variation in signing style (home signers, late-deafened signers, and regional variants like Brazilian Libras or Japanese SL can look dramatically different), and the fact that sign languages are full natural languages with grammar, not pantomime or gestured English.
How I Test Whether a System Is Actually Trustworthy
My process is deliberately adversarial. I don't start with the test set the developers provide. I build a small internal validation set using signers I know personally, covering the variations that matter for my use case. Three to five signers who aren't in the training data, filmed on consumer webcams in normal indoor lighting, doing natural conversational signing rather than isolated glosses. Then I run the system on that set and measure confusion patterns, not just overall accuracy. The critical metric is false negative rate on key phrases — if a medical or legal context system misses "danger" or "pain" half the time, accuracy doesn't matter. It's a liability, not a product. I also check temporal consistency. Sign language has sequential structure, and many models produce output that flickers between interpretations frame by frame. That's a trust killer in any real-time application. I look for stable prediction windows, usually requiring the model to output the same classification for at least 800 to 1200 milliseconds before trusting it.
The Edge Case That Broke My Pipeline
Here's a specific example. We deployed a sign-to-text system for a healthcare client. On paper, the model was solid. On their actual patients, it consistently misclassified fingerspelled names and medical terminology. The training data had very limited fingerspelling examples, and the model treated fingerspelling as noise rather than meaningful content. The workaround was to add a secondary fingerspelling module specifically for proper nouns and technical terms. We used a simple CNN-based classifier trained on a curated set of 500 common medical terms and names. It wasn't elegant, but it closed the gap. The primary model handled conversational signs, and the secondary module intercepted and classified fingerspelled segments. This reduced the error rate on clinical transcripts from about 18% to under 4%. What I learned from that: always test your system on the specific input distribution you expect in production, not on whatever benchmark the paper used. They're often completely different distributions.
Get the Full Details
Common Pitfalls That Waste Months
Pitfall one: assuming that more training data automatically improves trust. In sign language recognition, adding more data from the same demographic or signing style can actually degrade cross-group generalization. You need intentional diversity in the training set, not just volume. A dataset with 10,000 clips from one signer is worse than 2,000 clips from twenty different signers. Pitfall two: ignoring the spatial dimension. Sign languages encode meaning in three dimensions simultaneously — handshape, location, movement, and non-manual markers (facial expressions, head tilt, shoulder shifts). Most commercial systems focus on hand and arm tracking and treat facial expression as incidental. That misses a huge chunk of the information, especially for grammatical markers like questions, negation, and topicalization. Pitfall three: treating sign language as a direct translation of spoken language. ASL, LSQ, BSL, and other sign languages have their own syntax and morphology. A system that outputs "I GO STORE" when the signer produced a grammatically complex sentence with spatial referencing is fundamentally misunderstanding the input. This is a common failure mode in naive sequence-to-sequence approaches.
What I Look for in a Reliable System
First, I want to see the confusion matrix, not just overall accuracy. Which classes get confused with which? Are the errors random or systematic? Systematic errors reveal structural weaknesses. Second, I check whether the system provides confidence scores and whether those scores are calibrated. A model that says "I'm 92% confident" should be right 92% of the time, not 70% or 99%. Poorly calibrated confidence scores are dangerous in high-stakes contexts. Third, I evaluate handling of co-speech gestures and filler movements. Real signers pause, self-correct, and produce non-lexical gestures. A system that treats every hand movement as meaningful will generate garbage output during natural conversation. Good systems have a dedicated "ignore this" pathway for non-linguistic movement. Fourth, I test latency under real conditions. A system that takes 3 seconds to process a 5-second clip is useless for live interpretation. Production systems for sign language typically need sub-500ms inference with streaming input. If a vendor can't provide latency benchmarks measured on actual hardware, that's a red flag.
The Reality Check
No current sign language recognition system is trustworthy for critical applications without human oversight. Legal proceedings, medical diagnosis, and emergency services should all have a qualified human sign language interpreter in the loop. The technology is good enough for draft transcription and assisted communication in low-risk contexts, but it still makes mistakes that matter. The field is improving, and the gap between research and production is narrowing. But the people building these systems often come from computer vision backgrounds and don't have deep engagement with Deaf communities or sign language linguistics. That disconnect shows up in the products. You need to bring that expertise in yourself, whether you hire it or build it.

Where to Start If You're Building Something
Get a signed corpus that matches your target domain. The common public datasets are useful for prototyping but insufficient for production. Work with local Deaf organizations to collect data that reflects the actual population you're serving. Document the demographics of your training set honestly. If 80% of your data comes from young native ASL signers, say so, and don't claim your system works for elderly late-deafened users. Build your evaluation pipeline around edge cases, not accuracy benchmarks. The 94% accuracy number is marketing. The 6% error rate is where your system will fail, and you need to know what those failures look like before deployment. Run those failure cases through your QA process repeatedly until they stop being surprises. And please, stop calling sign languages "gestures" or "signs" in documentation meant for engineers. These are complete natural languages with complex grammar, history, and cultural context. The language you use about them shapes how seriously people take the problem, and it matters for building trust, not just good data.
 #trust #asl #gsl #nsl - YouTube")

 #trust #asl #gsl #nsl - YouTube")
