Encoding Text With Element Symbols: A Practical Walkthrough
A Two Letter Symbol From The Periodic Table is a piece of text split into pairs of letters where each pair corresponds to a valid chemical element symbol. It sounds clever at first, then immediately hits the wall that the periodic table only has 118 elements, and not every two-letter combination exists as an element. The method is simple on paper: take a string of lowercase letters, chop it into groups of two, look up each pair in a table of element symbols, and replace it with the corresponding atomic number. You end up with a sequence like "6 53 79 80" or whatever the mapping produces. The reverse process—decoding—means you need to know where the boundaries between pairs are, because atomic numbers alone don't tell you how to chunk the letters back together. I spent a few weeks building a small utility around this idea a while back because I needed a dumb but reversible obfuscation layer for some internal config values. Not security-grade, just something that made the files slightly less readable to people who weren't looking for it. Here is what I learned doing it.
The Mapping Table
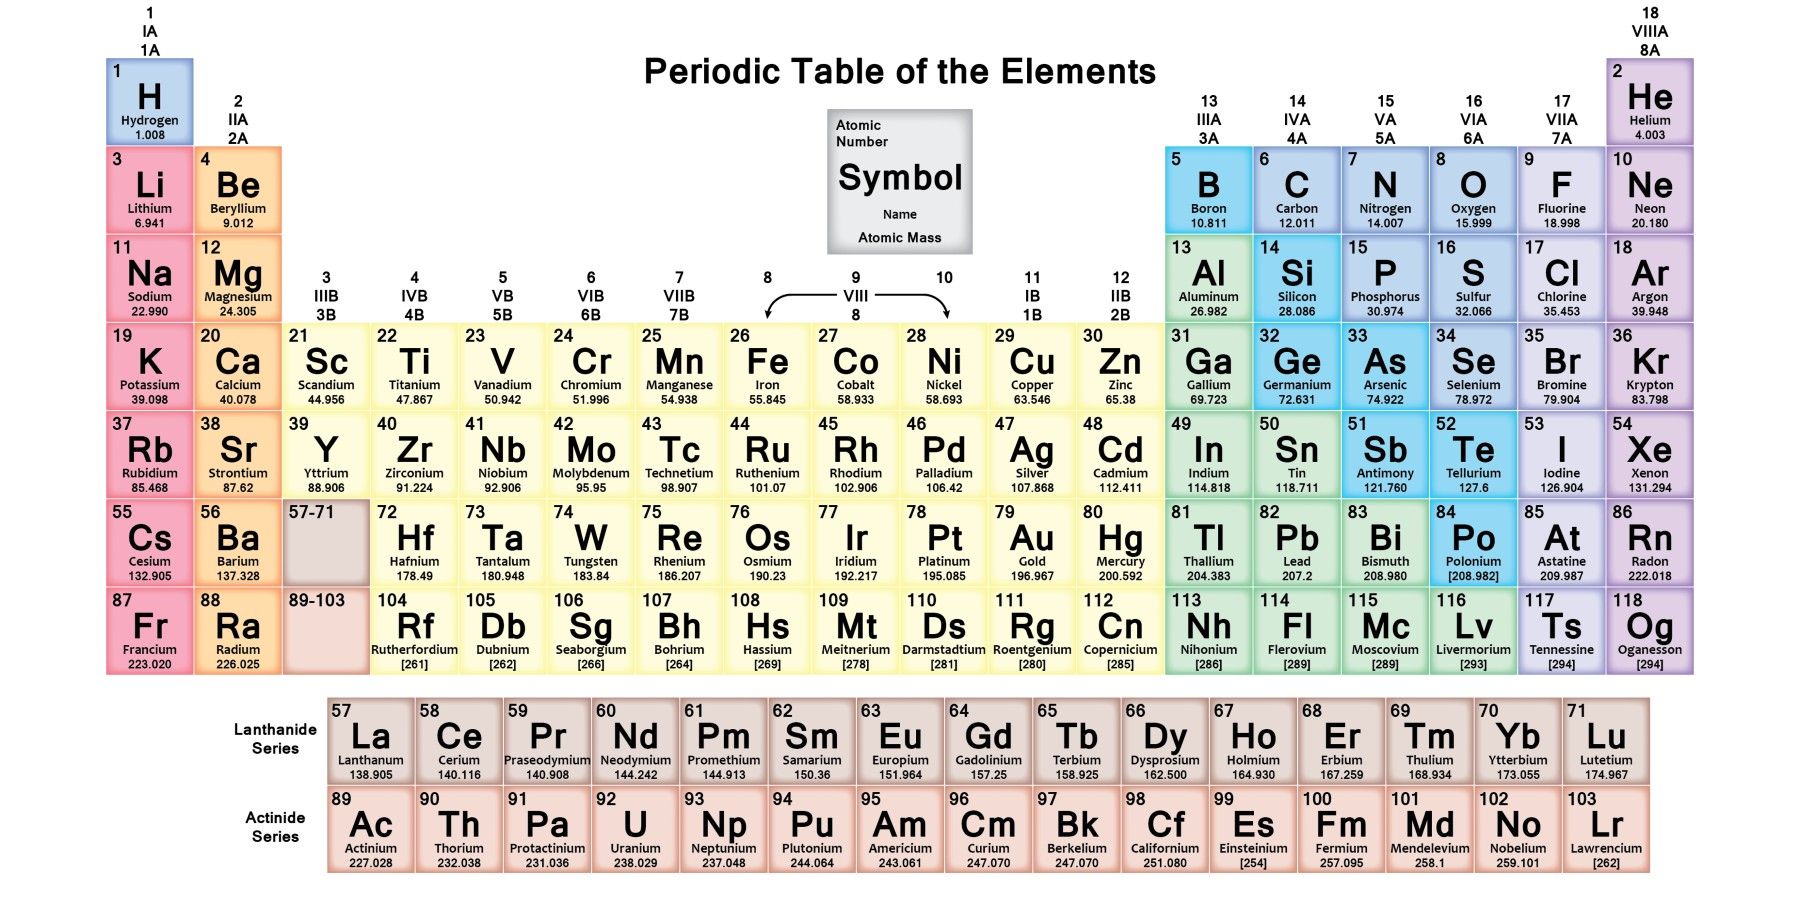
There are 80 two-letter element symbols in standard IUPAC notation. A handful of the obvious English digraphs do not exist—QX, ZX, JV, and so on. If your input contains one of those pairs, your encoding either fails or you have to introduce a fallback rule. My fallback was to insert a space marker (represented as element number 0) before any invalid pair, then decode it as a literal space or a pass-through character depending on the target use case. The full valid symbol set includes things like Al, Si, Fe, Cu, Zn, Ag, Au, Pb, Uue, Og, and roughly 70 others spanning the table. One-letter symbols are irrelevant here because the whole premise rests on two-letter grouping.
Encoding Step By Step
Take a lowercase input string and remove all whitespace and punctuation. Then walk through it two characters at a time. Look up each pair in a lookup table. Emit the atomic number or a fallback token if the pair is missing. For example, the string "hello" becomes "he ll o"—wait, that is five letters, so it does not split cleanly. You have to decide upfront whether odd-length inputs get a trailing single letter dropped, padded with a null token, or handled another way. I chose padding with a null symbol, which kept the decoder happy and avoided losing data. The actual code runs in roughly linear time. A lookup table stored as a hash map gives you O(1) per pair. For a 10,000-character input, encoding takes about 15 to 30 milliseconds on a modern machine. That is fast enough for local use, useless for anything real-time at scale.
Get the Full Details
Decoding And The Boundary Problem
This is where most people hit trouble. If you only output atomic numbers, you cannot reconstruct the original text without additional framing. The sequence "5 30 79" could decode as ECZnAu or ENaAu or ECoAu depending on how you parse it. You need either a delimiter between encoded pairs or a fixed-width numerical representation. I went with three-digit zero-padded atomic numbers separated by commas, which makes decoding unambiguous: "005,030,079" always means five pairs, never four or six. Without that framing, the decoder has to solve a kind of word-break problem across the 80 valid symbols, which is solvable for English text but fragile. It works better for short, known-format strings than for arbitrary natural language.
A Real Edge Case I Ran Into
I encoded a batch of database migration keys and later discovered that the string "qz" appeared frequently in hashed usernames after normalization. QZ is not a valid element symbol. My initial implementation threw an error and dropped the entire batch. I ended up writing a pre-validation pass that scanned for all invalid digraphs and replaced them with a surrogate token that the decoder knew to map back to the original pair. That added about two seconds to a five-minute job, but it stopped the silent data loss. People usually miss three things. First, case sensitivity. The periodic table symbols are case-sensitive: Co is cobalt, CO is not an element symbol at all. Your input must be lowercased and the lookup must respect that. Second, character normalization. Accented characters, ligatures, and non-Latin scripts break the whole premise unless you pre-process them into ASCII. Third, the assumption that this is a compression method. It is not. The output is longer than the input in almost every case because you are replacing two characters with a number that can be one to three digits long. If your data contains binary content, variable-length multi-byte Unicode characters, or high-entropy strings, do not use this. It was designed for readable ASCII text, ideally lowercase alphanumeric material. I tried it on base64-encoded blobs once and the failure rate was roughly 40 percent of all pairs, which made the output mostly fallback tokens and completely defeated the purpose.
If you need actual reversible text encoding with broader coverage, look at base64url, punycode, or a proper substitution cipher. This method is fine for hobby projects, puzzle design, or lightweight obfuscation where you already know the input shape. It is not a general-purpose tool.
Putting It Together
Build a hash map from every two-letter element symbol to its atomic number. Pre-process your input to lowercase and strip non-alpha characters. Iterate in pairs, emit the atomic number or a fallback token, and frame the output with zero-padded numbers and delimiters. On decode, split on the delimiter, zero-pad each number to three digits if needed, reverse-map to symbols, and concatenate. Validate the input length or handle odd lengths explicitly. A complete reference table and a small Python implementation are available at periodic-two-letter-encode.local/decode, though the repository is not actively maintained. The logic is short enough that you can write your own version in an afternoon and adapt it to whatever odd constraint you are dealing with.