Why Most People Mess Up Independent T-Tests
I spent about three years doing quality control at a mid-size automotive parts supplier before I ever heard of an independent two sample t test. We were comparing yield rates between two shift teams — morning versus night. The numbers looked clean on paper. I ran the test, got a p-value of 0.03, and wrote it up as statistically significant. My manager looked at it and asked a question I couldn't answer: were these measurements actually independent? Turns out each shift shared the same batch of raw material, and we'd been testing parts from the same production run. The shifts weren't independent samples — they were nested within batches. That little detail inflated our significance every single time. It took me about six months of messing around with mixed-effects models before I stopped making that mistake. That's the kind of thing people don't teach you in a stats 101 class. The Two Sample T Test works great when your assumptions line up. When they don't, it gives you answers that sound right but are actually misleading. Here's how to use it properly without falling into the same trap.
When You Should Use Two Sample T Test and When You Shouldn't
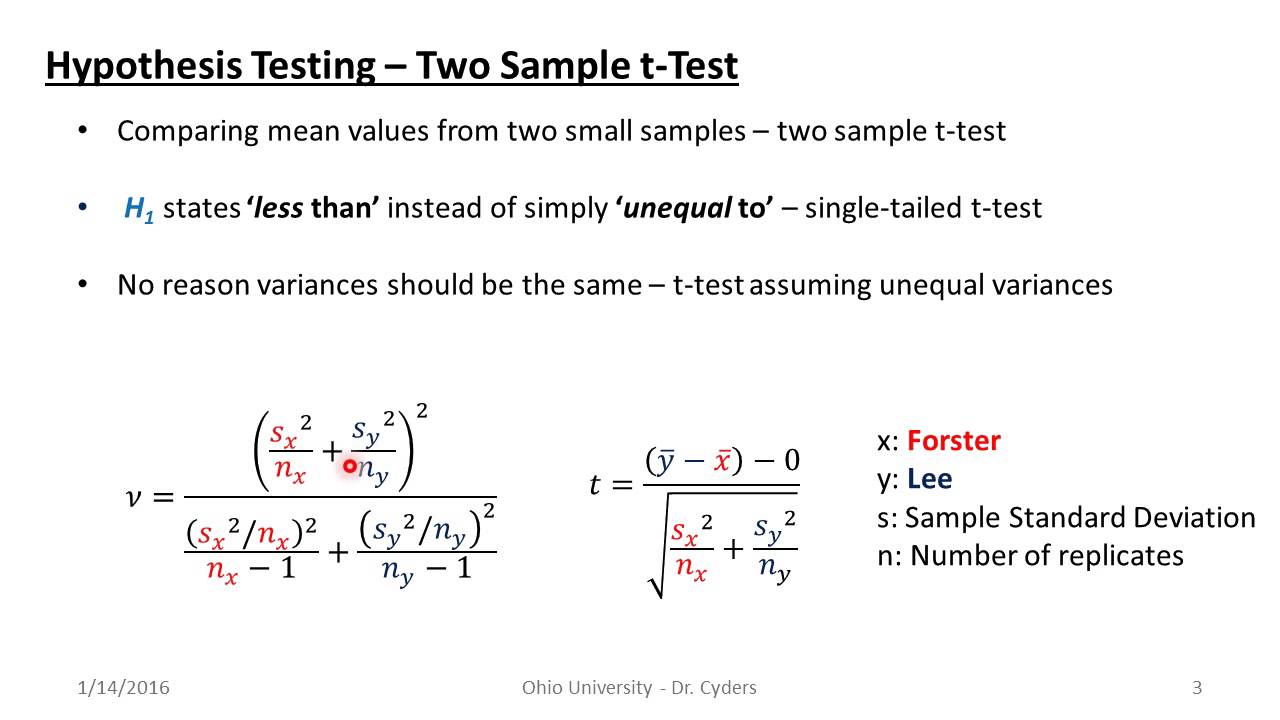
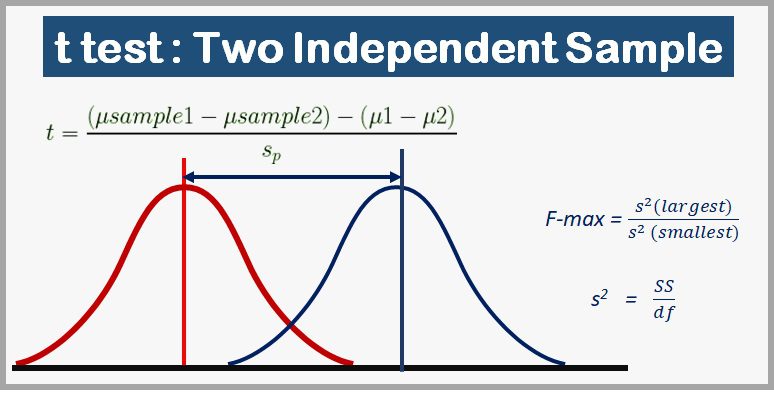
The basic idea is straightforward: you have two groups, you want to know if their means differ, and you're working with continuous data. Group A might be a treatment group. Group B might be a control. You pull a sample from each, calculate the means and standard deviations, and then run the test. The test statistic follows a t-distribution under the null hypothesis that the two population means are equal. But here's what most people skip over — and it's the part that matters more than the formula itself. You need to decide whether to use the pooled variance version or the Welch's version. The pooled version assumes equal population variances. Welch's doesn't. In practice, assuming equal variances when they're actually different is one of the most common errors I see, and it biases the p-values in a direction that depends on your sample sizes. If your larger group also has the larger variance, the pooled test becomes anti-conservative — it tells you results are significant when they aren't. The Welch version is almost always the safer default. It adjusts the degrees of freedom downward to account for unequal variances, and it converges to the pooled result when the variances happen to be similar anyway. I used to run Levene's test first to check for equal variances. Then I switched. Levene's test has low power with small samples, which means you often fail to reject equal variances when they're actually different. Using Welch's by default means you're protected either way. SPSS does this automatically if you tell it to. R's t.test function uses Welch's by default since version 3.0. Just don't override it unless you have a strong reason.
The other assumption — normality — gets way more attention than it deserves. The t-test is remarkably robust to violations of normality, especially with sample sizes above 20 or 30 per group. What actually matters more is whether your data has heavy tails or extreme outliers. A few outliers can completely distort the mean and standard deviation, which are the two numbers this test runs on. I once had a dataset of patient recovery times where three values were ten times the rest due to data entry errors. The t-test said p
0.001. After correcting the errors, it was p = 0.24. Same direction of difference, completely different conclusion. Always plot your data before running any test.
Get the Full Details
Running the Test Step by Step
Let me walk through a concrete example. Say you're comparing the breaking strength of two types of plastic for a packaging application. You take 15 samples of Type A and 12 samples of Type B. Your null hypothesis is that the mean breaking strengths are equal. Your alternative is that they're not equal — a two-tailed test, since you'd care about Type A being stronger OR weaker. In R, the command looks like this: t.test(group_A, group_B, var.equal = FALSE, alternative = "two.sided")
The output gives you the t-statistic, degrees of freedom (which Welch's adjusts), the p-value, and a 95% confidence interval for the difference in means. The confidence interval is actually more informative than the p-value. If it doesn't include zero, your result is significant at the 0.05 level — that's just the mathematical relationship between the two. But the interval also tells you the magnitude of the difference, which the p-value never does. A result can be statistically significant but practically meaningless if the confidence interval is very tight around a tiny difference. For the plastic example, let's say you get a t-value of 2.14 with roughly 24 degrees of freedom and a p-value of 0.043. The 95% confidence interval for the difference runs from 0.8 to 15.2 MPa. You'd report it as: the mean breaking strength of Type A was significantly higher than Type B (t(24) = 2.14, p = 0.043), with a difference of 8.0 MPa (95% CI: 0.8 to 15.2). That's a complete and honest summary. Don't add "therefore Type A is better" — statistical significance doesn't equal practical superiority. You need to know whether a 8 to 15 MPa difference matters for your application.
Common Pitfalls That Will Cost You Credibility
One thing that comes up constantly: people run multiple t-tests instead of using ANOVA when they have more than two groups. If you compare three treatments by running three separate t-tests at alpha = 0.05, your actual Type I error rate balloons to about 0.14. That's not a typo. The math is 1 minus 0.95 cubed. Use ANOVA with post-hoc corrections, or use Tukey's HSD. It's not harder and it's the right thing to do. Another frequent issue is paired versus unpaired data. If you measure the same subjects before and after a treatment, that's a paired t-test, not an independent two sample t test. The paired test accounts for within-subject correlation and is usually more powerful. I've seen both directions of this mistake — people treating paired data as independent (losing power) and treating independent data as paired (getting invalid results because the pairing doesn't actually exist). Sample size estimation is another area where people cut corners. You should ideally calculate your required sample size before collecting data, not after. The rule of thumb for detecting a medium effect size (Cohen's d around 0.5) with 80% power and alpha = 0.05 is roughly 64 subjects total — 32 per group. If you're looking for a small effect, you need over 600. This isn't negotiable if you want your study to be meaningful. Post-hoc power analysis is essentially meaningless because it's just a function of your p-value and sample size.

What the Test Can't Tell You
The two sample t test answers one question: is there a difference in means between two independent groups? It does not answer whether the difference is important, whether it will replicate, or what the underlying distribution looks like. It also assumes your observations are independent within and between groups, your data is approximately normally distributed within each group, and ideally your variances are roughly equal (though Welch's handles that). If your data is ordinal or heavily skewed, consider a non-parametric alternative like the Mann-Whitney U test. It tests for stochastic dominance rather than a difference in means, which is a different question but often more appropriate for messy real-world data. The test also doesn't handle missing data. If you have 20 subjects per group but 5 are missing values, you can't just drop them without potentially introducing bias. Listwise deletion reduces your power and may make your groups non-comparable. Multiple imputation or model-based approaches are better, though they require more work. Finally, there's the replication crisis to keep in mind. A single significant p-value from a two sample t test is weak evidence by itself. The field is moving toward reporting effect sizes with confidence intervals, pre-registering hypotheses, and running larger studies. The t-test is still useful — it's a fundamental tool — but it's only one piece of a proper analysis pipeline. Treat it like a calculator, not an oracle.