Comparing Two Proportions Without Overthinking It
I spent years wading through survey data and clinical trial results where the question was always the same: does group A differ from group B? The Two Sample Z Test For Proportions is what most people reach for first. It is straightforward, widely available in every statistics package, and almost always the wrong tool if your samples are small or your proportions sit near zero or one. That said, when the conditions line up, it gets the job done in about ten seconds. The setup is simple. You have two independent groups, each with a binary outcome—success or failure, conversion or no conversion, disease present or absent. You want to know whether the underlying population proportions differ. The null hypothesis says they are equal. The alternative says they are not, or that one is larger than the other if you are running a one-sided test.
When the Two Sample Z Test For Proportions Actually Works
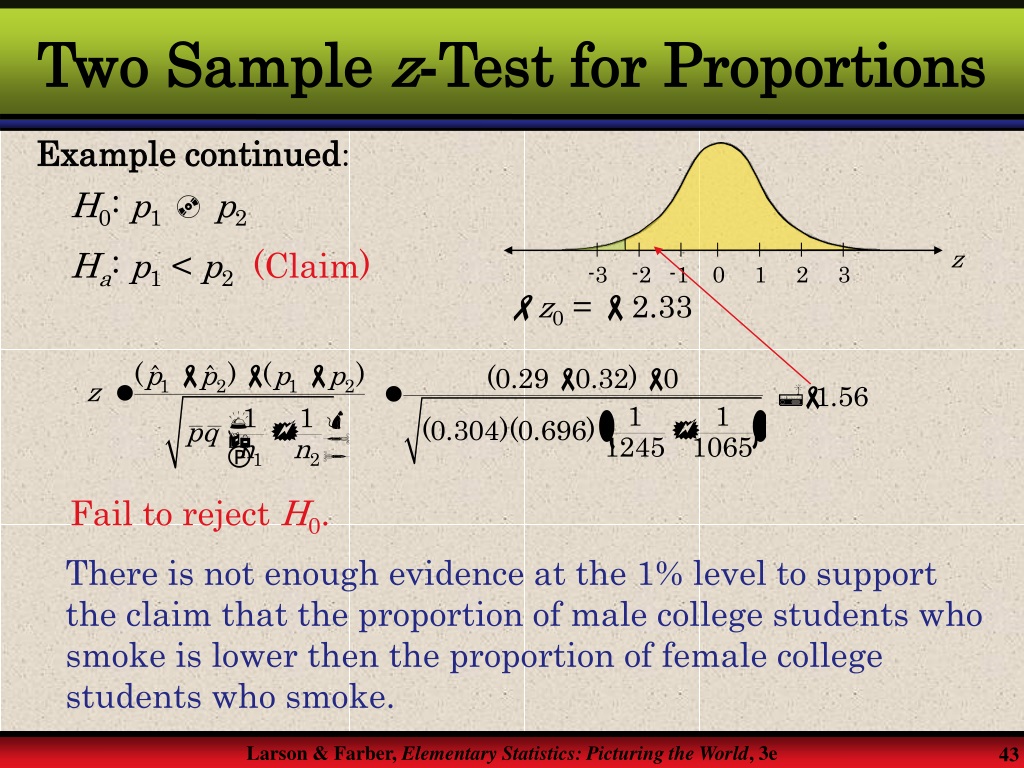
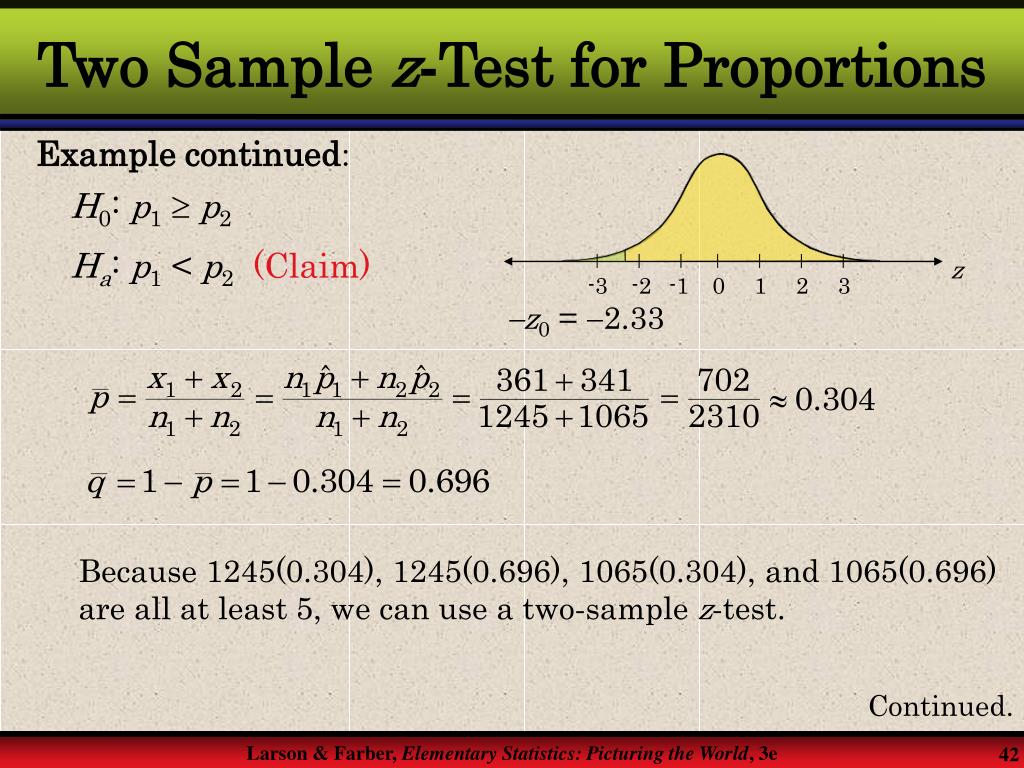
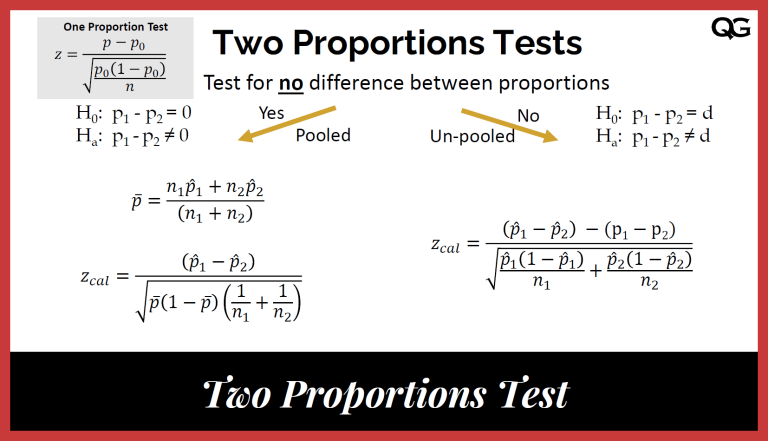
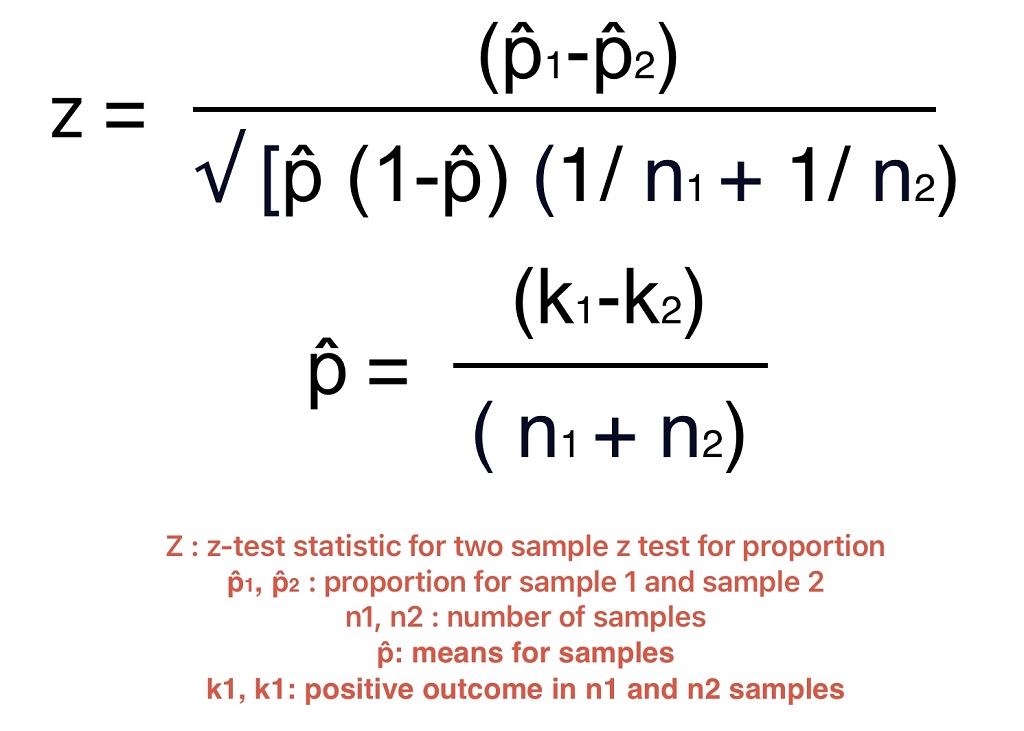
Before you run anything, check the sample sizes. Both groups need enough successes and failures to make the normal approximation sensible. The usual rule of thumb is at least ten expected successes and ten expected failures in each sample. If either group falls short, the z-test becomes unreliable, and you should switch to Fisher's exact test or a permutation approach. I learned this the hard way when I was analyzing a rare adverse event in a Phase II trial. One treatment arm had only three events out of 180 patients, which looked fine on paper but wrecked the approximation. The z-test spit out a p-value around 0.04, but the exact test gave 0.12. The regulatory reviewers spotted it immediately, and I had to redo the analysis with Fisher's method. Took about twenty minutes once I knew what to look for. Under the null hypothesis, both samples come from the same population proportion. That means you estimate a pooled proportion by combining all successes across both groups and dividing by the total sample size. The test statistic is the difference between the two sample proportions, divided by the standard error computed from that pooled estimate. The resulting value follows approximately a standard normal distribution when the assumptions hold. Most software handles this calculation automatically, but it helps to understand what is happening under the hood. The pooled proportion matters because it reflects the null hypothesis directly. If you skip pooling and use the separate sample proportions instead, you end up with a different standard error, and the test becomes less powerful under H0. That version is closer to what you would use for a confidence interval, where you are not assuming the null is true.
Working Through a Real Example
Say you are comparing conversion rates between two landing pages. Page A gets 120 conversions out of 1,500 visitors. Page B gets 98 conversions out of 1,400 visitors. The sample proportions are 0.08 and 0.07, respectively. The pooled proportion is 218 divided by 2,900, which gives about 0.0752. The standard error comes out to roughly 0.0077. The observed difference is 0.01, so the z-statistic is about 1.30. The two-sided p-value is around 0.19, which is nowhere near conventional significance. You would fail to reject the null and conclude there is no clear evidence of a difference. This example is deliberately simple. In practice, you would feed the raw counts into R, Python, or any statistical package, and it would return the statistic, the p-value, and optionally a confidence interval for the difference. The computation takes fractions of a second. What matters more is interpreting the result correctly and checking whether the assumptions were met.
Get the Full Details
Common Pitfalls I See Repeatedly
The biggest mistake I encounter is applying the test when the data are paired or matched. If your observations are linked in some way, the independence assumption breaks, and the z-test will give misleading results. In those cases, you need McNemar's test or a generalized estimating equation framework. I once reviewed a study where someone compared infection rates before and after an intervention in the same hospitals. The test was not just inappropriate; it invalidated the entire conclusion. Another frequent error is treating statistical significance as practical importance. With large samples, even minuscule differences become significant. A two percentage point gap might yield p
0.001 if your sample is big enough, but the real-world impact could be negligible. Always report the effect size and consider whether the difference matters in context. The test tells you about evidence against the null, not about the magnitude of a meaningful change. A third issue is multiple testing. If you run the Two Sample Z Test For Proportions across dozens of subgroups without adjusting for comparisons, you will find apparent differences that are purely due to chance. The family-wise error rate inflates quickly, and false positives become likely. Bonferroni correction is conservative but straightforward. Scheffe-type procedures or false discovery rate control offer alternatives when you need more power. Pick a strategy before you start analyzing, and stick to it.
Limitations You Should Accept Early
The z-test depends on large-sample theory. When proportions are very small or very large, or when sample sizes are modest, the approximation deteriorates. The normal curve does not resemble the true sampling distribution in those scenarios, and p-values become unreliable. Switch to exact methods or Monte Carlo simulation. The computational cost is usually low, and the improvement in accuracy is worth the few extra minutes. The test also assumes independent observations within and between groups. Violations of this assumption, whether from clustering, repeated measures, or convenience sampling, undermine the validity of the result. I have seen this bite researchers who treated all responses from a single clinic as independent, ignoring the intra-cluster correlation. The effective sample size was much smaller than the raw count suggested, and the reported significance evaporated once the design effect was accounted for. If you need to adjust for covariates or control for confounding, the simple two-sample z-test is inadequate. Logistic regression or other multilevel models provide more flexibility. They require more setup time, but they handle real-world complexity that the basic test cannot. I usually start with the z-test for quick checks, then move to regression for formal analysis.
Practical Steps for Running the Test
Collect your data as two counts of successes and totals, or as raw binary outcomes grouped by treatment. Verify independence, sample size conditions, and the absence of pairing. Compute the pooled proportion, the standard error, and the z-statistic. Look up the p-value from the standard normal distribution. Compare against your chosen alpha level, usually 0.05 for exploratory work or 0.01 for confirmatory studies. In R, the prop.test function runs this test with Yates' continuity correction by default, which makes it slightly conservative. Setting correct = FALSE disables the correction and gives the pure z-test approximation. In Python, statsmodels.proportion.proportions_ztest performs the same calculation. Both return the z-statistic and p-value quickly. Add a confidence interval for the difference if you need to communicate the effect size alongside the hypothesis test. Document your choices clearly. State whether you used pooling, whether you applied any correction, and which alpha level guided your decision. This transparency matters more than the test itself when others evaluate your work. Reviewers and collaborators appreciate knowing exactly what you did and why.

What to Do When the Test Fails
If your sample sizes are small or your proportions are extreme, use Fisher's exact test. It computes the exact probability of observing your data under the null, without relying on approximations. The calculation is slower for large tables, but modern computers handle it without difficulty. For moderate tables, it usually finishes in under a second. If your data are paired, use McNemar's test. It focuses on discordant pairs and accounts for the dependence structure. Ignore the pairing, and you risk inflated Type I error or loss of power, depending on the correlation direction. If you have covariates or hierarchical structure, fit a logistic regression model with random effects or robust standard errors. The output includes adjusted odds ratios and p-values that respect the study design. The modeling step takes longer, perhaps fifteen to thirty minutes depending on your familiarity, but the results are far more defensible.
Recording and Reporting Results
Always report the sample sizes, the observed proportions, the test statistic, the p-value, and the confidence interval for the difference. A complete report lets readers assess both statistical and practical significance. Leaving out any of these elements makes it harder for others to judge the quality of your analysis. Include a brief note about assumption checks. Mention whether the success-failure condition held, whether independence was reasonable, and whether you considered adjustments for multiple testing. This level of detail takes only a few sentences but strengthens the credibility of your findings considerably. Save your code and raw data when possible. Reproducibility saves time on follow-up analyses and makes it easier to address reviewer questions. I keep a simple script for each project that reruns the full analysis with one command. It usually takes less than five minutes to execute, and it prevents the frustration of reconstructing an old analysis from memory.
My Typical Workflow
I start by examining the raw counts and proportions. If anything looks suspicious, I check for data entry errors or unusual clustering. Then I run the z-test for a quick initial assessment. If the assumptions are satisfied and the result is clear, I am done. If there is ambiguity, I move to exact methods or regression, whichever fits the design. The whole process typically takes between ten and forty minutes, depending on complexity. I rarely rely on the z-test alone for publication-quality work. It serves as a fast diagnostic, not a final answer. The field has moved toward models that handle real-world complications better, and the basic test can look naive if presented without context. Pair it with sensitivity checks and clear reporting, and it remains a useful part of the toolkit.

References for Further Reading
For a thorough treatment of the theory, Agresti's Categorical Data Analysis covers the z-test and its alternatives in depth. His examples are grounded in actual research problems, which makes the material accessible without sacrificing rigor. For implementation details, the statsmodels documentation provides clear examples in Python, and the R help pages for prop.test and fisher.test cover usage and options. If you want to explore permutation and bootstrap methods for comparing proportions, Good's Permutation Tests offers practical guidance. The approach is computationally intensive for very large datasets, but it scales reasonably well with modern hardware and avoids distributional assumptions entirely.
Final Thoughts
The Two Sample Z Test For Proportions remains a standard tool for comparing two independent groups with binary outcomes. It is easy to apply, fast to compute, and widely understood. Use it when the conditions are met and the question is simple. Step away from it when the data are small, paired, clustered, or confounded. The alternatives are readily available, and knowing when to switch is what separates competent analysis from careless application. In my experience, most misuses come from habit rather than ignorance, and a brief pause to check assumptions prevents the majority of errors.