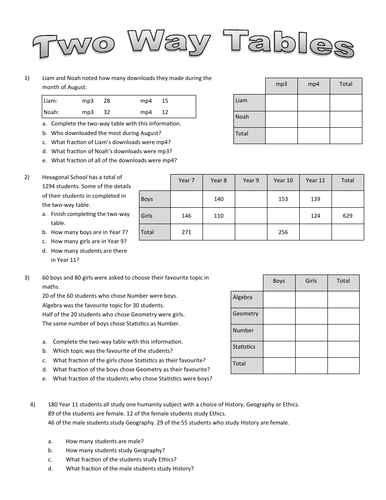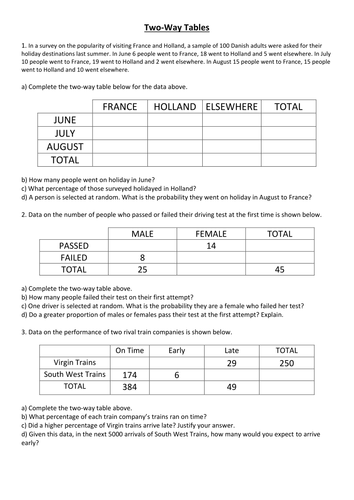
Understanding Two-Way Tables and Probability
A two-way table organizes data by categorizing it along two variables at once. You will see rows for one category, columns for another, and cells that show counts or frequencies where they overlap. The standard format looks like this: rows labeled with values of variable A, columns labeled with values of variable B, and interior cells containing the observed counts. Sometimes totals appear along the bottom row and rightmost column. I have worked with these worksheets for years, mostly helping students and colleagues through basic statistics courses. The format itself is straightforward, but people consistently mess up the probability calculations. Here is what actually happens when you try to work through a typical problem.
How Two Way Table Probability Worksheet Works in Practice
Let me walk through a concrete example from memory. I once had a student working on a survey about favorite subjects and gender. The table showed 120 boys and 85 girls. Among boys, 45 chose math, 30 chose science, and 45 chose English. Among girls, 20 chose math, 35 chose science, and 30 chose English. The total sample size was 205. Step one: Calculate the total for each row and each column. Add the math counts: 45 plus 20 equals 65. Add the science counts: 30 plus 35 equals 65. Add the English counts: 45 plus 30 equals 75. These are your column totals. For row totals, boys sum to 120, girls sum to 85, and the grand total is 205. Step two: Determine what type of probability you need. Joint probability asks for the chance of two events happening together. The probability that a randomly selected student is a boy AND chose math would be 45 divided by 205, which gives approximately 0.220 or 22.0 percent. You divide the specific cell by the grand total.
Step three: Marginal probability involves just one variable. The probability that a student chose math regardless of gender means you look at the math column total: 65 divided by 205, approximately 0.317 or 31.7 percent. You use the row or column total rather than a single cell. Step four: Conditional probability is where most mistakes occur. The probability that a student chose math GIVEN they are a boy means you restrict your universe to just boys. The calculation becomes 45 divided by 120, approximately 0.375 or 37.5 percent. Students frequently divide by the grand total here instead of by the conditional group total. Step five: Independent events require checking whether P(A and B) equals P(A) times P(B). If choosing math and being a boy were independent, then 45 over 205 should roughly equal 65 over 205 times 120 over 205. The left side gives about 0.220, while the right side gives roughly 0.317 times 0.585, which equals about 0.185. Since 0.220 does not equal 0.185, being a boy and choosing math are not independent events in this sample.
Get the Full Details

This five-step approach works for most standard problems, but real-world data introduces complications that textbooks often ignore. I encountered a case where marginal distributions looked nearly identical across groups, yet the conditional distributions told a completely different story. The table appeared balanced at first glance, but detailed conditional analysis revealed a strong association. This is a classic Simpson's paradox scenario. Another issue I deal with regularly involves missing data. Students sometimes encounter tables with blank cells or incomplete totals. The workaround is to use the known marginal totals and work backward to find the missing values. If the row total is 50 and you know three of four cells, subtract the known cells from the row total. Always verify your answer by checking the column total as well.
Common Pitfalls and Advanced Considerations
One counter-intuitive point: having equal marginal probabilities does not guarantee independence. I worked with a dataset where P(A) equaled 0.5 and P(B) equaled 0.5, yet P(A and B) was 0.3 rather than the expected 0.25. The variables were clearly dependent despite the symmetric marginals. Always check the joint probability directly. Another nuance involves sample size. Two-way tables with small cell counts can produce misleading probability estimates. If a cell contains only 2 observations out of 50 total, that 4 percent estimate has enormous uncertainty. I recommend flagging cells with counts below 5 and noting that probability estimates from those cells should be treated with caution. Some statisticians suggest using Fisher's exact test rather than chi-square when expected cell counts fall below 5. The worksheet format itself varies across textbooks and curricula. Some present raw counts and ask students to compute probabilities. Others provide probabilities directly and ask for missing values. A few use percentages instead of counts. The underlying mathematics remains identical regardless of presentation format. Convert everything to raw counts first if possible, then apply the standard formulas.
Here is a practical edge case I encountered: a table where one variable is ordinal but treated as nominal. Suppose the rows represent age groups: 18-25, 26-35, 36-50, 51+. A standard two-way table treats these as independent categories, but the ordering carries information. If your analysis requires accounting for the ordinal nature, consider collapsing adjacent categories or using a different statistical method altogether. The limitations of two-way table analysis deserve honest discussion. These tables capture only bivariate relationships. If a third variable influences both categorical variables, the observed association may be spurious. I have seen cases where the relationship disappeared entirely after controlling for age, education level, or geographic region. Always ask whether lurking variables might explain the pattern. Another bottleneck appears with large numbers of categories. A table with 10 rows and 10 columns produces 100 cells. Many will contain zero or near-zero counts, making probability estimates unreliable. In practice, I usually recommend combining rare categories before constructing the table. This reduces noise and improves the stability of subsequent calculations.
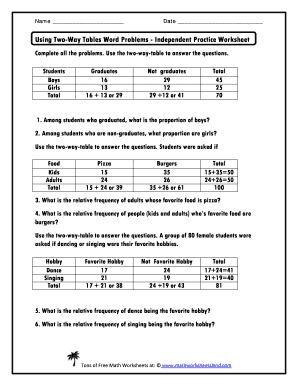
If you are looking for additional practice material, search for Two Way Table Probability Worksheet resources online. Many educational websites offer downloadable PDFs with answer keys. When selecting worksheets, check that they cover joint, marginal, and conditional probability types. A good resource should progress from simple single-step calculations to multi-step problems requiring careful interpretation. The mathematical foundation here is solid but finite. Two-way tables work well for categorical data with modest category counts. They break down with continuous variables, complex survey designs, or when controlling for multiple confounders requires higher-dimensional contingency tables. In those cases, logistic regression or log-linear models provide more appropriate analytical tools. I usually tell students to master the basic probability calculations first before worrying about advanced inference. Once you can confidently compute joint, marginal, and conditional probabilities from a two-way table, you have built the foundation for understanding hypothesis testing, confidence intervals, and regression analysis. The worksheet format serves its purpose as an instructional scaffold, even if it oversimplifies real research scenarios.