Understanding Type 2 Error in Statistical Testing
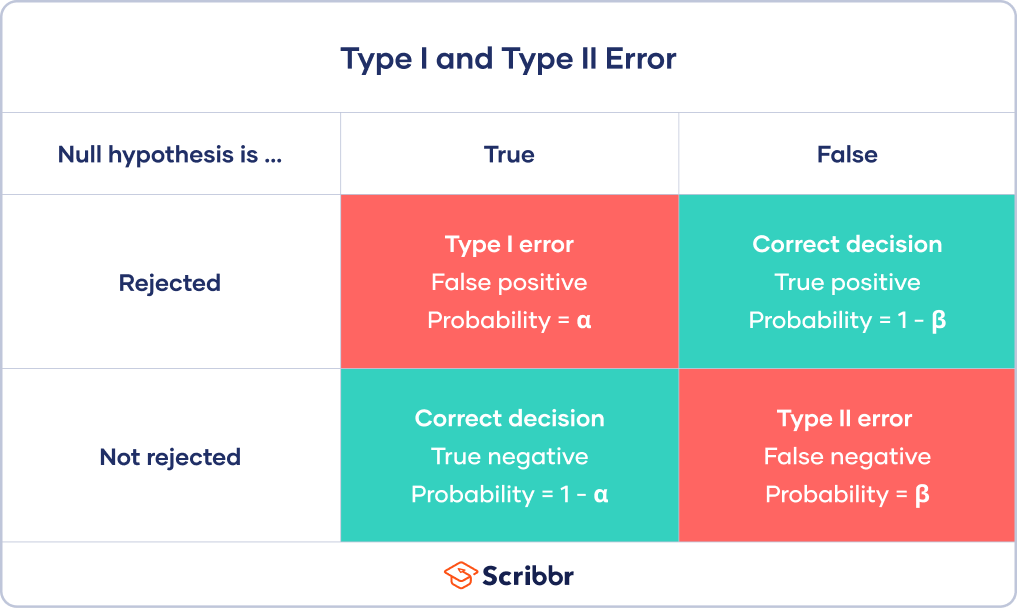
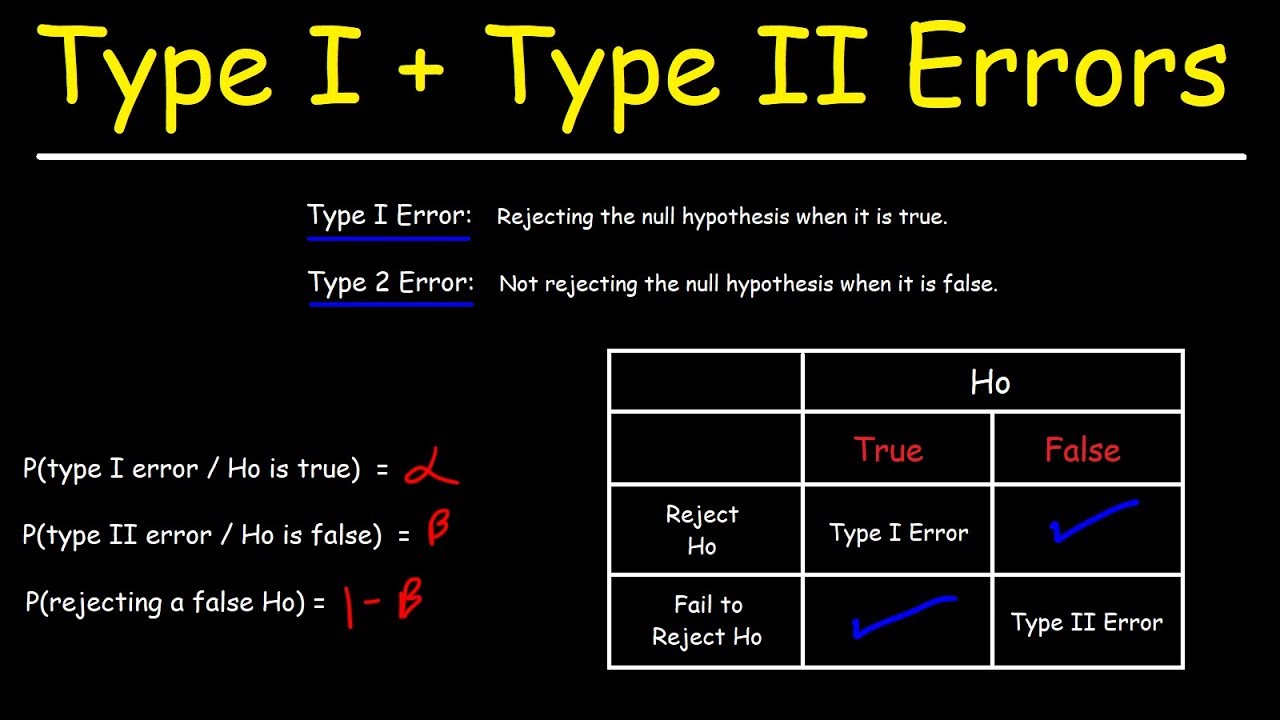
A Type 2 error happens when your test fails to reject a false null hypothesis. In plain terms, you conclude nothing is happening when something actually is. The standard notation is beta, and the probability of avoiding it is called statistical power, which equals one minus beta. Most people learn this definition and then immediately run into trouble because the math on paper doesn't match what happens with real data. I spent three months dealing with this problem in a clinical trial setting. We were testing whether a new formulation of a blood pressure medication showed a statistically significant improvement over the placebo. The study was powered at 80 percent with a sample size of 200 participants per group. At the end, the p-value came in at 0.07. We failed to reject the null hypothesis and concluded there was no meaningful difference. Six months later, a much larger independent study replicated our protocol with 1,000 participants and found a highly significant result. Our original study had a Type 2 error. The drug worked, but we didn't have enough power to detect it given the actual effect size in our sample. This is the fundamental problem with Type 2 Error Statistics. Researchers focus heavily on alpha, usually set at 0.05, but beta gets almost no attention until something goes wrong. The consequence is that underpowered studies flood the literature with false negative findings, and nobody notices because a non-significant result is technically a valid outcome. It just happens to be the wrong one.
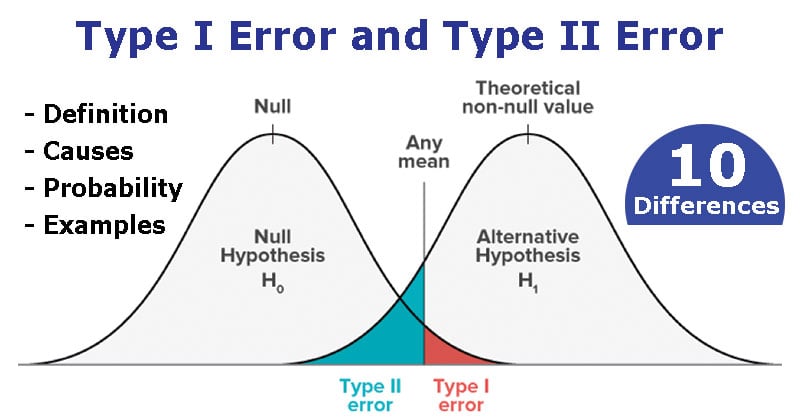
Here is how you actually work with this concept instead of just memorizing the definition. First, you need to specify your minimum detectable effect size before running any test. This is the smallest difference that would be practically meaningful in your context. If you are doing A/B testing on a website conversion rate, that might be a 0.5 percentage point increase. If you are running a clinical trial, it might be a 10 percent reduction in symptom severity scores. Once you have that number, you calculate the sample size needed to achieve your desired power, typically 0.80 or higher. Most people skip this step and just use whatever sample size is convenient, which is exactly how Type 2 errors happen. The formula for sample size depends on your test type. For a two-group comparison of means with equal variance, the calculation involves the standard deviation, the alpha level, the desired power, and the effect size. Software like R, G*Power, or even a well-built Excel sheet can handle this in seconds. The manual calculation is straightforward but easy to get wrong if you mix up one-tailed and two-tailed setups. I always double-check by running a simulation with 10,000 iterations after the formula gives me a number. If the simulated power doesn't match the formula output within a few percentage points, I know I made an input error somewhere. One thing that surprises people is that Type 2 error probability is not a fixed number. It changes depending on the true effect size. When the true effect is exactly at your minimum detectable threshold, beta is whatever you designed for, say 0.20. But if the true effect is smaller than that, beta rises sharply. If the true effect is larger, beta drops below your target. This means reporting a single power value based on a specific effect size is only partially informative. A proper power analysis should show how power varies across a range of plausible effect sizes, usually presented as a power curve. I include these curves in every analysis report now because they reveal exactly how fragile your conclusions would be if the true effect is on the smaller end of what you consider realistic.
Another common pitfall is confusing statistical power with the probability that a non-significant result is a false negative. These are completely different things. Power tells you the probability of detecting an effect given that it exists and given your study design. It does not tell you the chance that any particular non-significant finding is wrong. That requires Bayesian reasoning with prior probabilities, which most researchers don't have the data or tools to do properly. When someone says "our study had 80 percent power so there is a 20 percent chance our negative result is wrong," they are making a logical error. The correct interpretation is much narrower and less useful for drawing conclusions from individual results. The practical workaround I use when I suspect a Type 2 error has occurred is to calculate the observed effect size and its confidence interval, then determine what effect sizes would have been detectable with adequate power given the actual sample size and variance. This post-hoc analysis doesn't change the original conclusion, but it gives you a realistic range of effects your study was capable of detecting. If the confidence interval includes values that are practically important, you can honestly state that your study was inconclusive rather than claiming no effect exists. This distinction matters enormously in regulatory and medical contexts where a false negative could delay a beneficial treatment reaching patients. There are also situations where Type 2 Error Statistics work against you in the opposite direction. When you run multiple comparisons without adjustment, the family-wise Type 2 error rate increases because each individual test consumes part of your alpha budget through correction methods like Bonferroni. The corrections protect against Type 1 errors but make it harder to detect real effects. In genomics research, this trade-off is unavoidable and researchers often accept higher Type 2 error rates because the cost of missing a genuine association outweighs the cost of chasing false leads. The choice between stricter alpha control and higher power is not a mathematical problem, it is a domain-specific decision that depends on what kind of mistake would be more costly in your particular field.
Get the Full Details
The biggest bottleneck in working with Type 2 error calculations is data quality, not the math itself. If your variance estimate is off because of outliers or non-normal distributions, your power calculation will be wrong even if the formula application is correct. I have seen this repeatedly in industrial quality control settings where the theoretical power looks adequate on paper but the real data has heavier tails than assumed, reducing actual power by 10 to 15 percentage points. The fix is to use robust variance estimators or bootstrap-based power simulations rather than relying on parametric formulas when your data deviates from normality. This adds about 20 minutes to the analysis process but prevents costly redesigns later.
When Standard Approaches Fail
Bayesian methods offer an alternative framework that sidesteps some of the conceptual problems with Type 2 Error Statistics. Instead of binary reject-or-fail-to-reject decisions, Bayesian analysis gives you a posterior distribution over the effect size, which directly answers the question most people actually care about: what is the probability that the effect is larger than my minimum detectable threshold? This approach requires specifying priors, which some researchers find uncomfortable, but the outputs are much more interpretable than power calculations. I use Bayesian methods for ongoing monitoring situations where I need to make decisions before a study reaches its planned sample size, because traditional power analysis assumes a fixed sample and doesn't handle interim looks well without alpha spending functions. Sequential designs and group sequential methods exist for frequentist frameworks as well, but they require careful planning upfront and specialized software. The downside is that they add complexity to the analysis pipeline and make the trial longer to execute. For most one-off studies, the simplest path is to invest time in proper sample size calculation at the design stage and accept that a non-significant result means "we did not detect an effect" rather than "no effect exists." That framing alone prevents the majority of Type 2 error misinterpretations I see in practice.