Statistical errors in hypothesis testing: what actually happens when you run a significance test

When I first started running A/B tests for a SaaS product back in 2016, I thought Type I Ii Error was just textbook material you learned once in a stats course and then forgot. It took me three broken product launches before I actually understood how these errors show up in real production data, not in clean textbook examples. The first mistake I made was treating alpha = 0.05 as a hard truth rather than a configurable dial. That cost us about two weeks of engineering time and a confused product team.

Understanding Type I Ii Error in practice

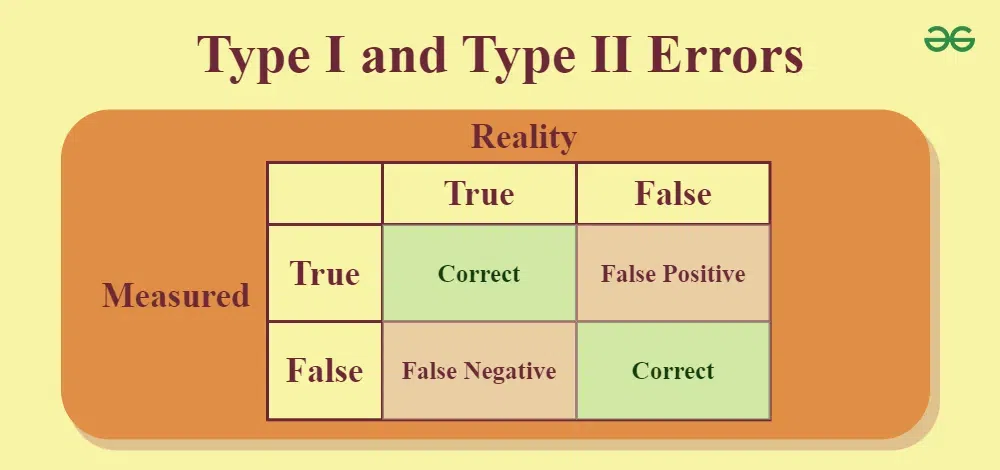
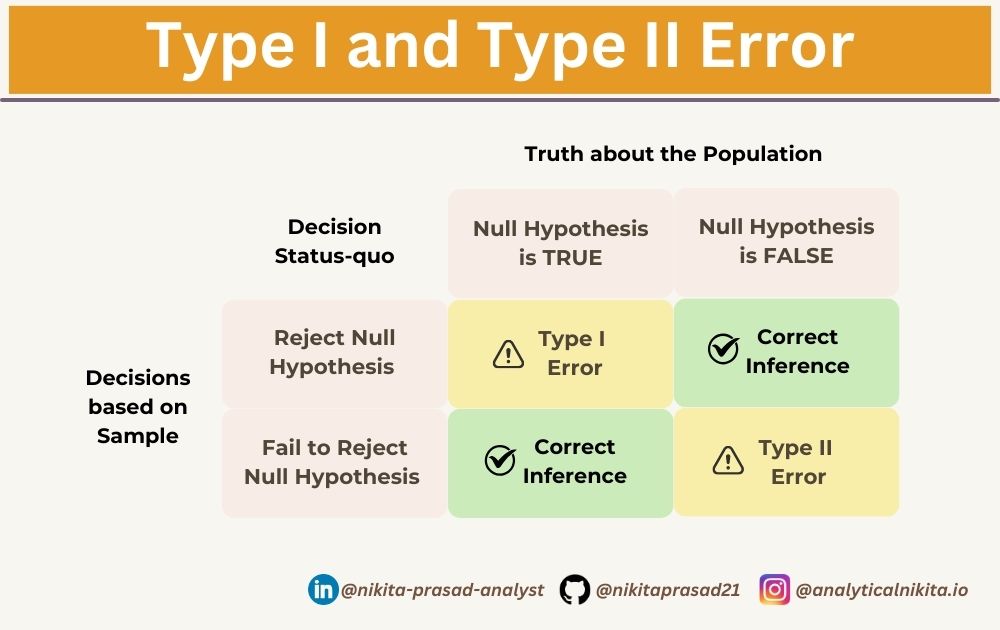
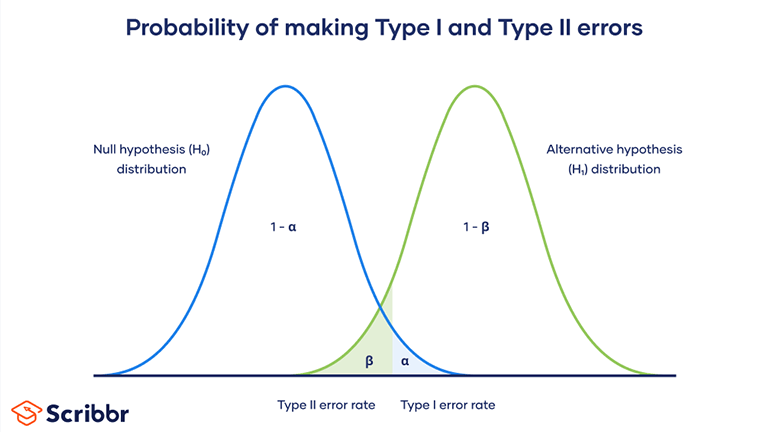
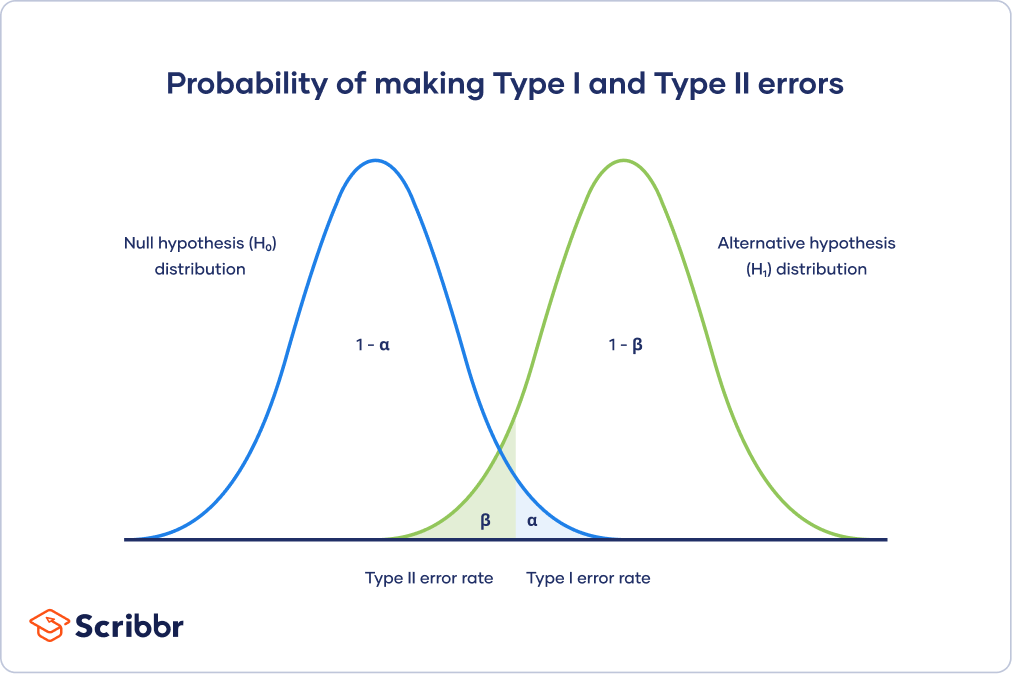
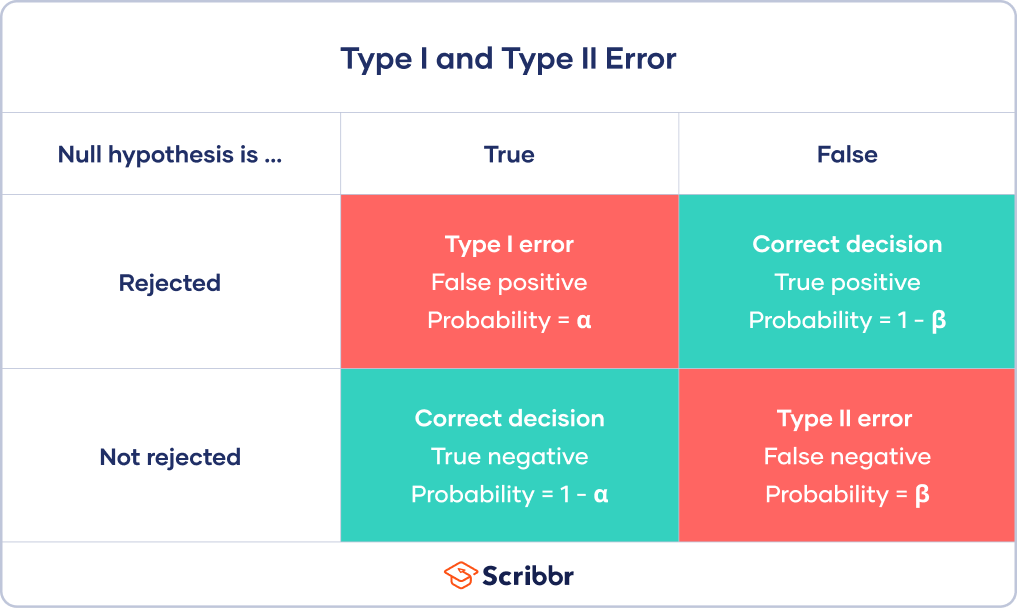
A Type I error happens when you reject the null hypothesis when it is actually true. You think you found an effect. There is no effect. A Type II error is the opposite: you fail to reject the null when it is false. The effect is real, but your test missed it. Both are baked into every significance test you run. You cannot eliminate them both at the same time. Lowering alpha to reduce Type I errors automatically inflates Type II errors unless you increase your sample size or your effect size. That tradeoff is the core constraint nobody talks about enough. In my experience, the most confusing part is that "error" does not mean a bug or a calculation mistake. It means a decision that is wrong given the data you have. Your code is fine. Your p-value is correctly computed. You are still making the wrong call. I worked on a campaign attribution model where we were comparing conversion rates between a control group and a treatment group. The metric was purchases per visitor. We set alpha at 0.01 because leadership wanted high confidence before rolling anything out. The test ran for six weeks with roughly 40,000 visitors per variant. The p-value came back at 0.038. We declared no significant difference. Three weeks later, the marketing team ran a follow-up analysis with a different segmentation and found the same treatment had a genuine lift of about 4.2 percent. We had committed a Type II error. Our test was underpowered. The effect size was small enough that 0.01 alpha burned through our statistical power before the signal could surface. The workaround I ended up using was switching from a fixed alpha framework to a pre-registered minimum detectable effect calculation. Before launching any test, I calculate the sample size needed to detect a specific effect with 80 percent power at whatever alpha I am willing to accept. If the required sample size is impractically large for the traffic we get, the test is not worth running at all. That saved us from wasting months on underpowered experiments.

Here is a practical workflow for setting this up in Python using scipy.

from scipy.stats import norm, ttest_rel
import numpy as np

def calculate_power(n, effect_size, alpha=0.05):
    critical_value = norm.ppf(1 - alpha/2)
    z_beta = (effect_size * np.sqrt(n)) - critical_value
    power = norm.cdf(z_beta)
    return power

Example: detecting a 3% lift with baseline rate of 8%
baseline_rate = 0.08
lift = 0.03
effect = (baseline_rate + lift) - baseline_rate
required_n = int(((norm.ppf(1 - alpha/2) + norm.ppf(0.8)) / effect)  2 * baseline_rate * (1 - baseline_rate) / (lift  2))
print(f"Required sample per group: {required_n}")
One thing that trips people up is assuming that a non-significant result means "no difference." It means "no evidence of a difference given this sample and this alpha." That is a completely different statement. I see this mistake constantly in internal reports where stakeholders read a p-value of 0.12 as proof that a feature has no impact. It is not proof. It is silence. Another nuance that is easy to miss is the difference between one-sided and two-sided tests. Most people default to two-sided because it is the conservative choice, but if your hypothesis is directional and you have a strong prior reason to test only one direction, a one-sided test gives you more power for the same alpha. I used this once on a load-testing scenario where we knew the optimization could only improve response times, never worsen them due to the nature of the change. Switching to a one-sided test reduced our required sample by roughly 15 percent. That mattered when we were dealing with a low-traffic landing page. If you are working in R instead of Python, the same logic applies and the functions are built in. The pwr package handles power calculations directly.
library(pwr)
pwr.2p.test(h = ES.h(0.08, 0.11), sig.level = 0.05, power = 0.8)
ES.h computes the effect size for two proportions
There are limits to this whole approach. Power analysis assumes your data meets the underlying distributional assumptions. If your metric is heavily skewed, like revenue per user where a small number of whales dominate, the standard formulas break down. You need either a transformation, a bootstrap-based approach, or a non-parametric test. I spent about four days debugging a revenue experiment where the standard power calculation suggested we needed 12,000 users per group, but the actual required sample was closer to 28,000 because the revenue distribution had a tail that stretched out past five standard deviations. The fix was switching to a bootstrapped confidence interval approach and resampling 10,000 times to estimate the empirical power. It took longer to compute but gave a realistic number instead of a misleading one. Another common pitfall is p-hacking without realizing it. If you check your results midway through a test and peek at the p-value, then decide to stop early because it looks significant, you are inflating your Type I error rate. A single peek might not matter much. Five peeks at different stages can push your effective alpha from 0.05 up to somewhere closer to 0.12 or higher, depending on how many looks you take and how you decide to stop. The workaround is group sequential design or pre-registering your analysis plan. If you do not want to go that formal, at least use an adjusted alpha like Bonferroni or a gatekeeping procedure. It is not perfect, but it is better than stopping whenever the number looks good. For Bayesian practitioners, the framing is different but the problem is identical. You still have false positives and false negatives. The terminology changes to posterior probability and credible intervals, but the practical consequences stay the same. I have used both frameworks and I prefer the Bayesian approach for ongoing experimentation because it gives you a direct probability statement about the effect, but it is not a free pass. Weak priors combined with small samples can produce overconfident posteriors that look clean but are wrong. I once ran a Bayesian A/B test with a vague normal prior on a conversion rate experiment. The posterior looked sharp and convincing. It was wrong because the prior was too diffuse relative to the actual data. Tightening the prior to match historical baseline rates fixed it, but that required domain knowledge I should have had from the start. The key takeaway is not to memorize definitions but to understand what each error costs you in your specific context. In a medical drug trial, a Type I error means approving a drug that does not work. A Type II error means missing a drug that does work. Both are bad, but the acceptable balance depends on the stakes. In a web experiment, a Type I error means launching a feature that slightly hurts engagement. A Type II error means keeping a feature that could have helped. Usually, the cost of a Type I error is lower in software because you can revert quickly. That is why many product teams tolerate a higher alpha, sometimes even 0.10, and rely on rapid iteration to correct false positives. But that only works if you have the infrastructure to rollback, which not every team does.

Quick reference for common scenarios

  • High-stakes clinical trials: alpha 0.01, power 0.90, strict pre-registration
  • Product A/B tests with fast rollout: alpha 0.05 or 0.10, power 0.80, sequential checking allowed with correction
  • Exploratory research: alpha 0.10, power 0.70, report everything including null results
If you want a lightweight tool for calculating required sample sizes before you launch a test, the G*Power desktop application is free and covers t-tests, z-tests, chi-square tests, and ANOVA. It handles the mechanics so you can focus on whether your experiment is worth running in the first place. The download is available from the University of Düsseldorf website. I also keep a small Jupyter notebook template that I reuse for every major test. It auto-fills the power calculation, plots the expected power curve across different sample sizes, and flags when the required N exceeds what your traffic can deliver in a reasonable window. It takes about ten minutes to set up once and then saves me from running half-baked tests that waste everyone's time.