Understanding Hypothesis Testing Errors in Practice
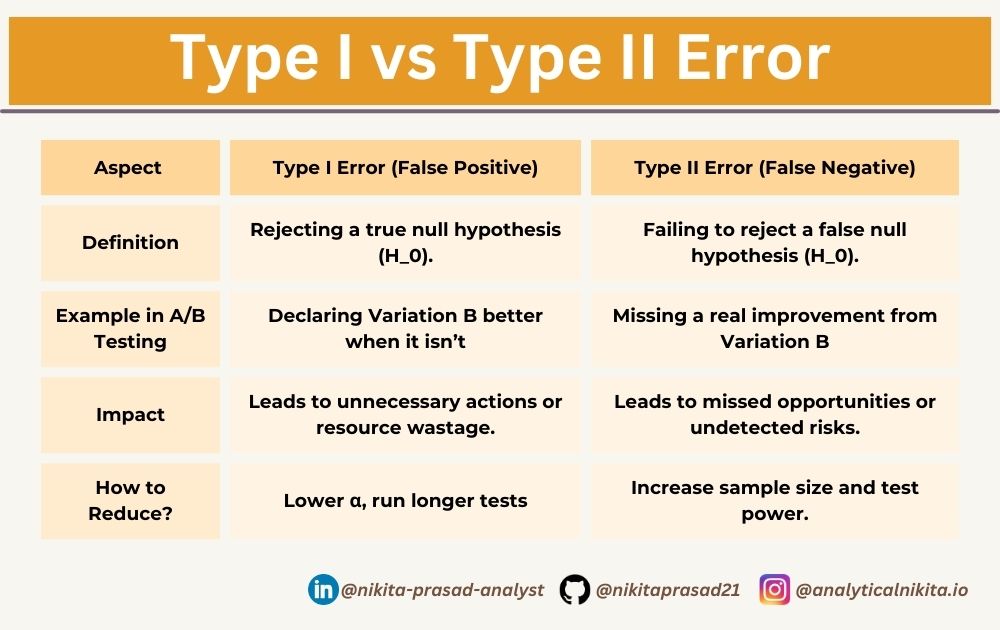
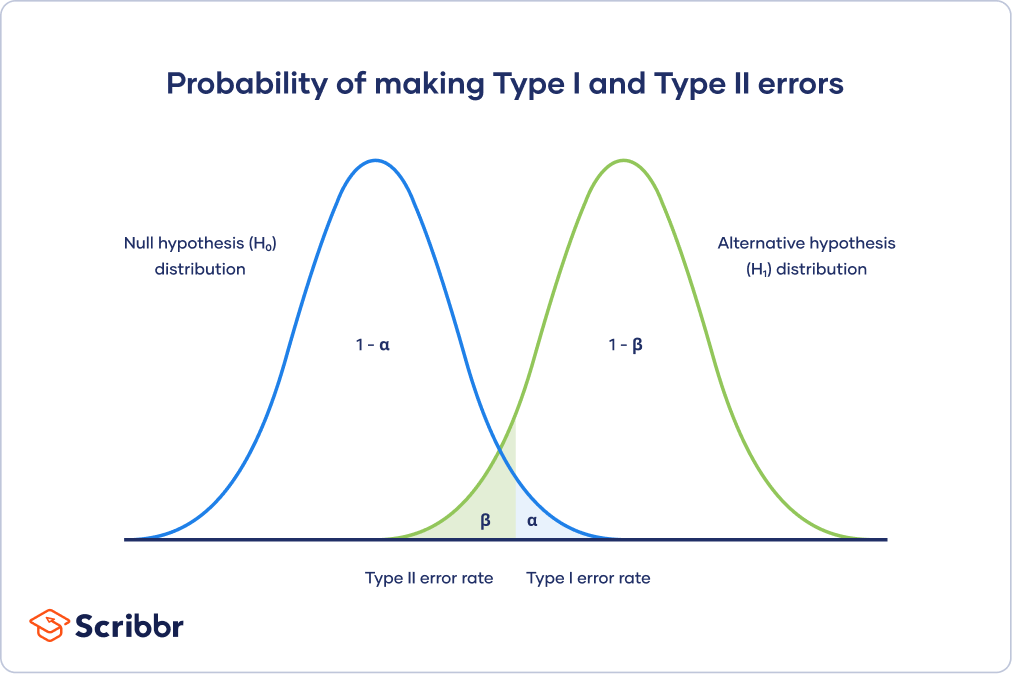
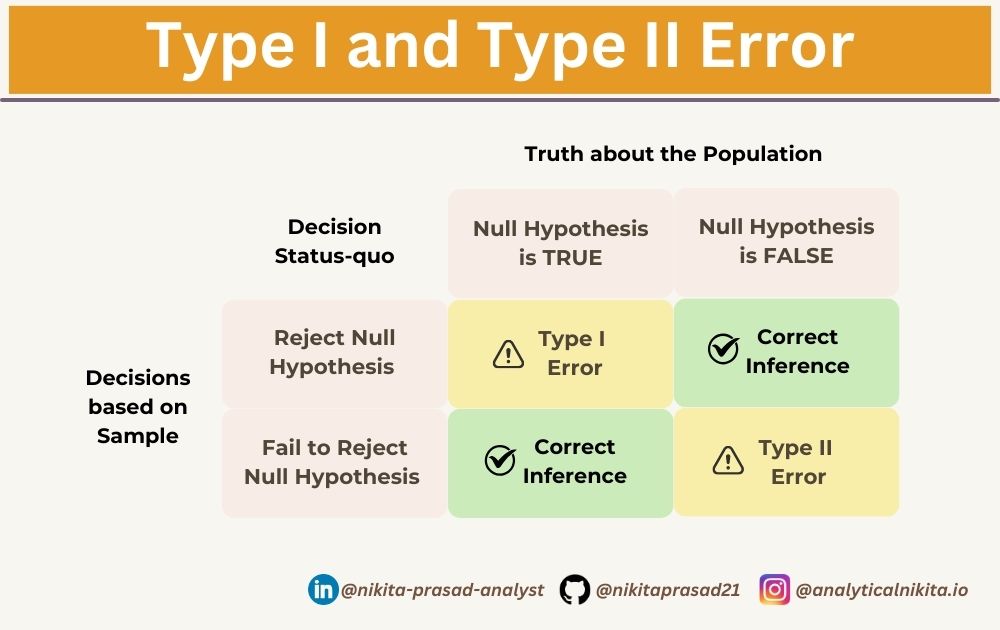
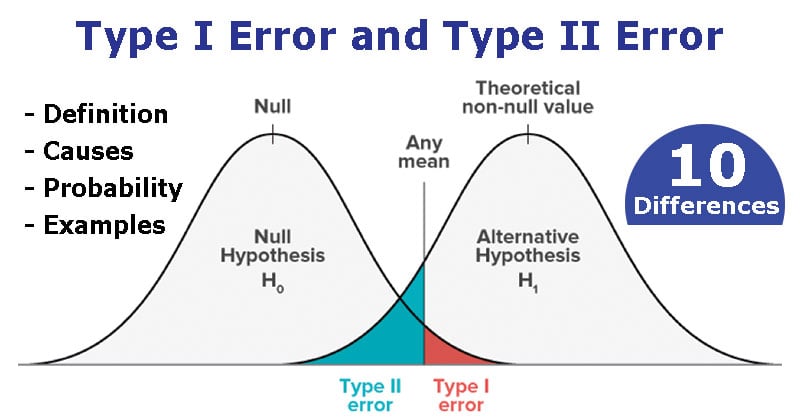
When you run a statistical test, you're basically making a bet about whether a pattern in your data is real or just noise. The thing nobody tells you early on is that you can lose that bet in two completely different ways, and they don't feel the same at all. A Type I error is when you reject a null hypothesis that's actually true. You think you found something, but you didn't. A Type II error is the opposite — you fail to reject a null hypothesis that's actually false. You missed a real effect. I spent three years working on clinical trial data before this really clicked for me, and even then it took a specific failure to make it stick. The problem is that most textbooks present these errors as symmetrical counterparts when they're really not. They behave differently under pressure, they carry different costs, and the tradeoff between them isn't a clean lever you can dial up and down. Here's what actually happens when you pick an alpha level. If you set alpha at 0.05, you're accepting a 5% chance of a false positive. But lowering alpha to 0.01 doesn't just cut your false positive rate — it also widens your confidence intervals and reduces statistical power, which means your Type II error rate goes up. Every time you try to be more careful about false positives, you become less sensitive to real effects. That's the fundamental tension, and it's not something you solve, you just manage it.
Power analysis is where people usually go wrong. I've seen teams calculate power at 80% and call it done without thinking about what the consequences would be if that power number was wrong. My workaround for this was to run a sensitivity analysis across multiple effect size assumptions rather than picking a single point estimate. I'd model scenarios at the minimum clinically important effect, the likely effect based on prior literature, and a optimistic upper bound. This took about 45 minutes extra in the planning phase but saved us from deploying an underpowered study that would have been expensive and ethically questionable to run. The counter-intuitive part that most beginners miss is that Type I and Type II errors aren't independent. When you have a small sample size, both error rates can be high simultaneously. People assume that if they control alpha properly they're fine, but with n=30 per group you might have alpha=0.05 AND power of only 0.45. That means you're more likely to miss a real effect than to falsely detect one. The error landscape looks completely different at small sample sizes than the textbook diagrams suggest. Another thing that doesn't get enough attention is the difference between fixed-sample and sequential designs. In a fixed-sample approach you collect all your data and then test. In a sequential design you can peek at the data periodically and stop early. The problem is that every peek inflates your effective Type I error rate if you don't adjust for it. I learned this the hard way when our internal review board flagged a phased trial because the interim analysis used unadjusted boundaries. We had to redo the statistical section with alpha spending functions, which added about two weeks to our protocol development. The fix involved using the O'Brien-Fleming spending function, which is conservative early and lets more alpha leak through at later looks.
For practical implementation, you need to think about your domain first. In drug safety trials, Type I errors are much more expensive because a false positive could lead to rejecting a beneficial treatment. Here you might set alpha at 0.005 or even lower and accept higher Type II error rates. In exploratory genomics research where you're screening thousands of markers, the calculation flips — you're worried about the flood of false positives, so you use Bonferroni correction or false discovery rate methods like Benjamini-Hochberg. The Benjamini-Hochberg procedure controls the expected proportion of false discoveries among rejected hypotheses rather than the family-wise error rate, which is much less conservative and usually more appropriate for high-dimensional data. If you're working in R, the pwr package handles basic power calculations. For more complex designs you'd use WebPower or the simr package for simulation-based power analysis. Python users typically go with statsmodels.stats.power. The simr package in R is worth the extra learning curve because it lets you run simulation-based power analyses for mixed-effects models, which analytical formulas can't handle well. Common pitfalls to avoid:
Get the Full Details
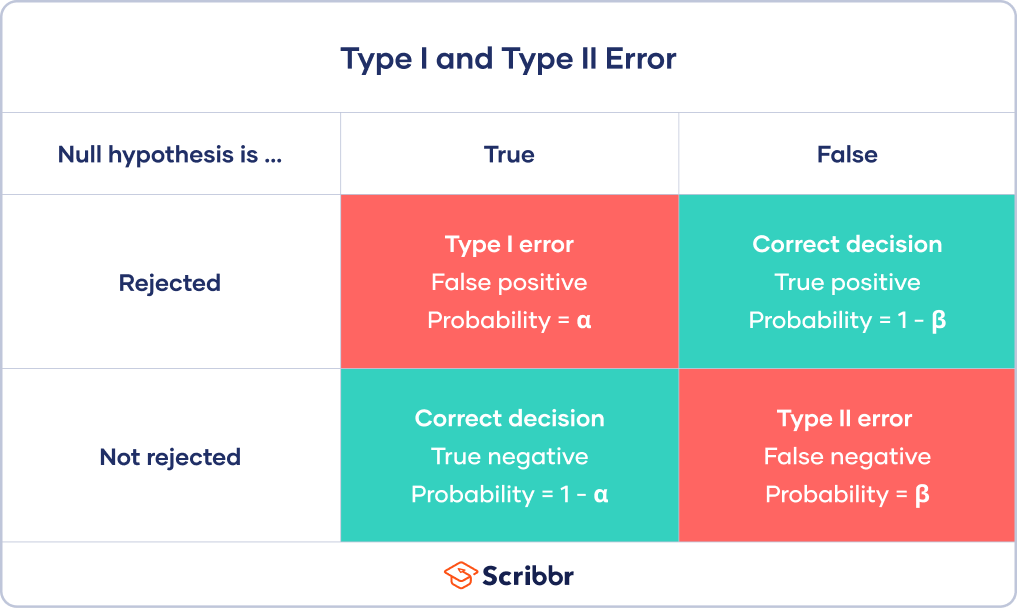
Don't confuse statistical power with practical significance. A study can have 90% power to detect an effect size of d=0.05, which is statistically significant but meaningless in any real-world context. Always anchor your power calculation to a minimally important effect size, not just whatever the data happens to show in a pilot study. Don't treat beta as the mirror image of alpha. They operate on different scales and have different distributions under the alternative hypothesis. Planning for beta=0.2 is standard, but in many fields beta=0.1 or even beta=0.05 is more appropriate, especially for confirmatory studies. The biggest limitation of this whole framework is that it only works within the null hypothesis significance testing paradigm. If your question is about estimation rather than decision-making, confidence intervals and equivalence testing give you more information than a binary reject-or-fail-to-reject outcome. Many researchers I work with are shifting toward estimation-based approaches precisely because the Type I/Type II framework forces a false dichotomy on nuanced data.
Bayesian approaches sidestep this problem entirely by giving you the probability of hypotheses rather than the probability of data under a null. But they introduce their own complications around prior specification and computational cost. For most practical applications, sticking with frequentist methods and being explicit about your error tolerances is still the right call.