Setting Up Experiments Without Losing Your Mind
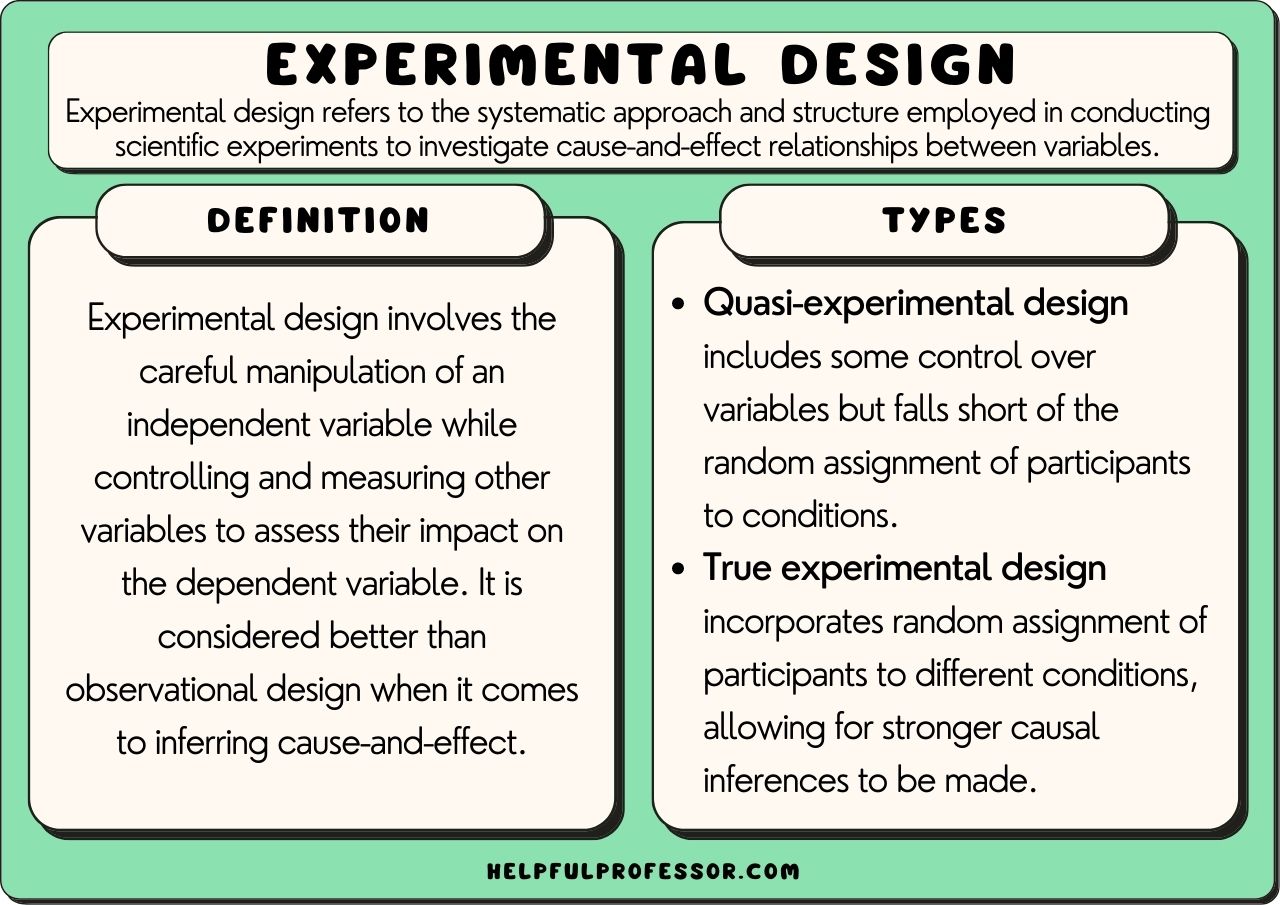
Most people come to experimental design because they need to test something and they know that guessing doesn't count anymore. The basic idea is simple enough: you manipulate one thing and watch what changes. The part that actually matters is choosing which structure fits your situation, and that is where things get tricky fast. I spent years watching teams waste months on designs that couldn't answer their own questions. The most common failure I saw was people picking a design because it looked clean on paper instead of because it matched their constraints. You need to understand what each type actually does before you commit to one.
Types Of Experimental Design
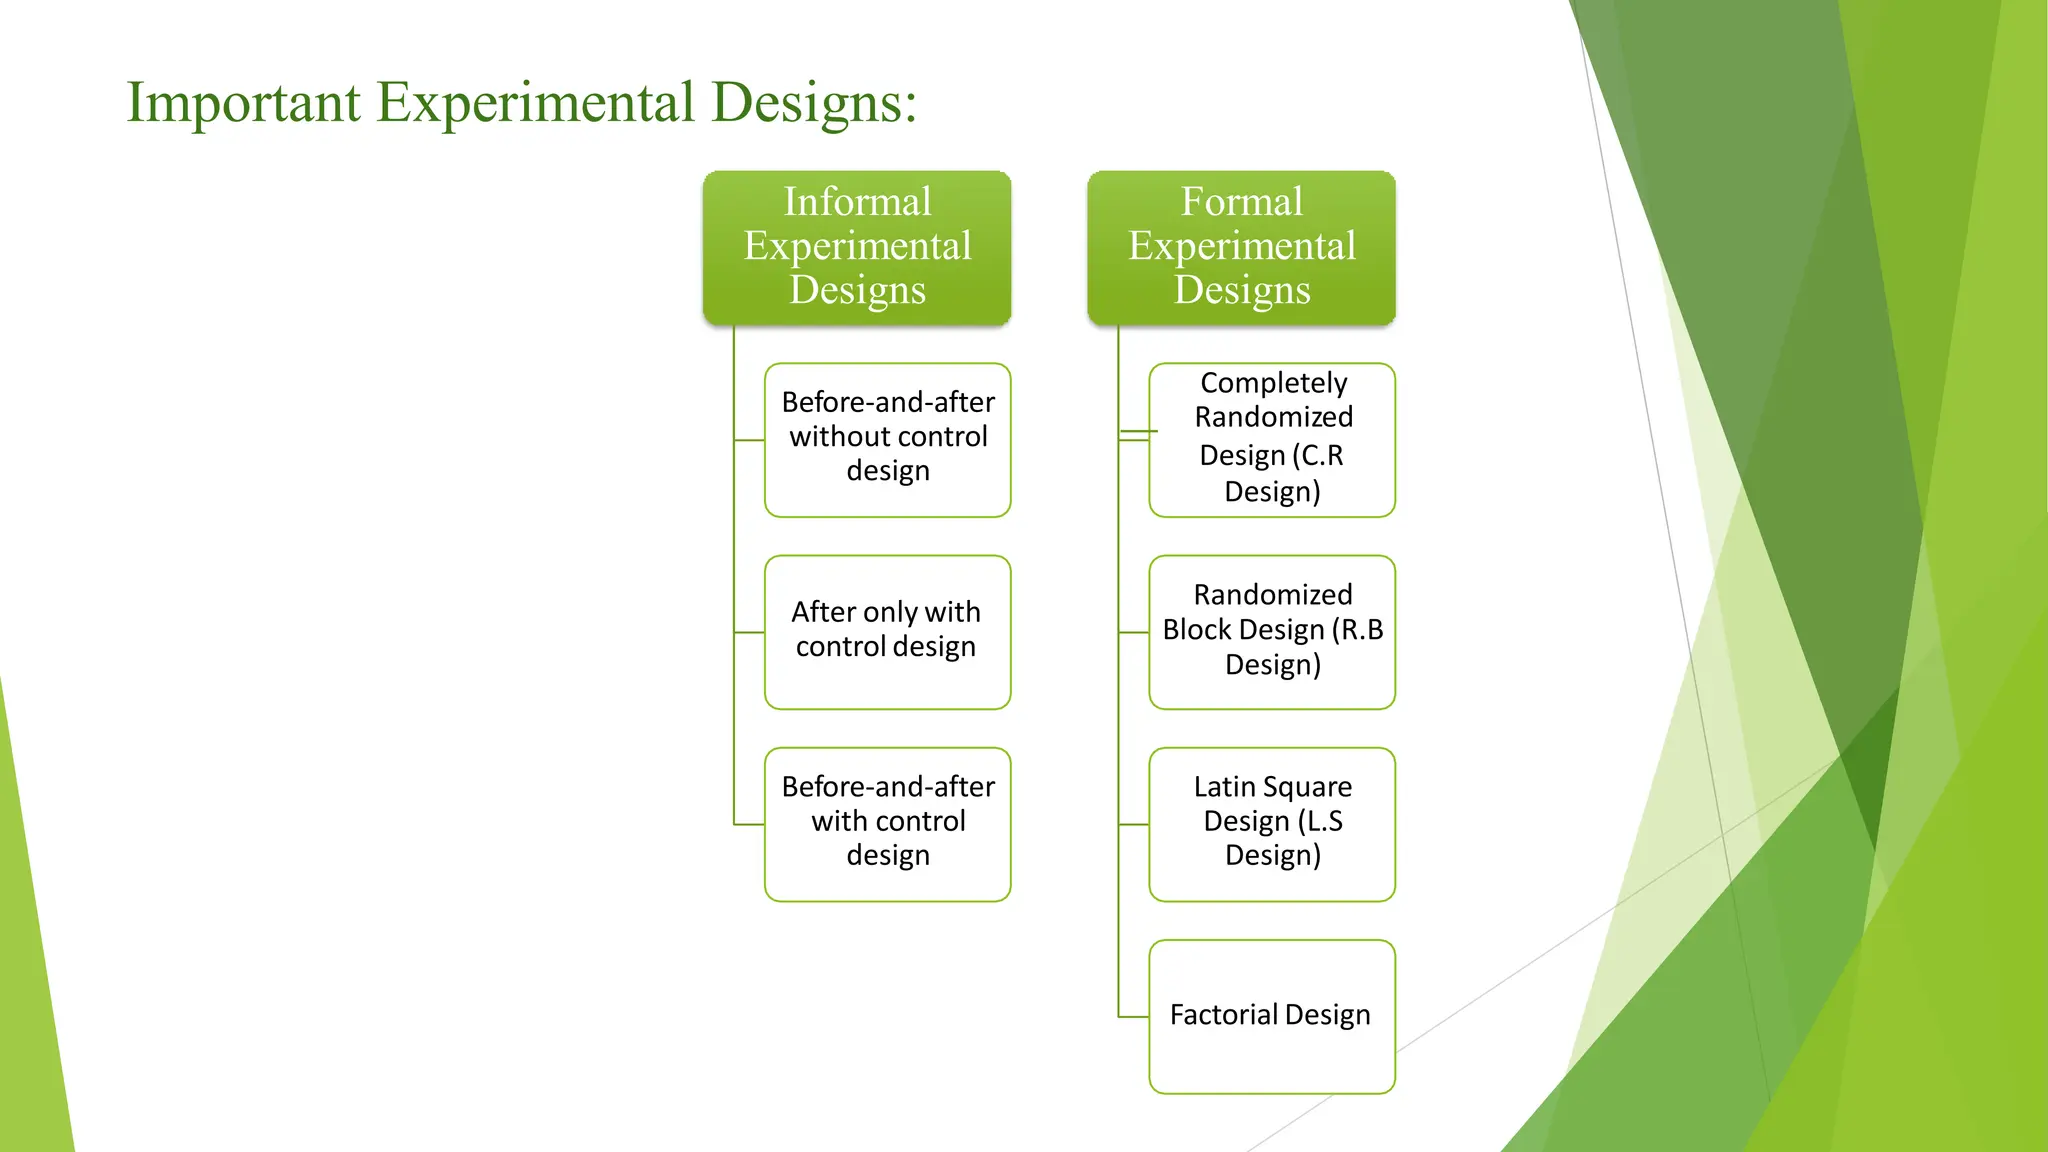
Completely Randomized Design (CRD) is the baseline. Every unit gets randomly assigned to a treatment with no blocking or grouping. It is simple, it is honest, and it works when your experimental units are fairly homogeneous. If you have a lot of background noise in your material, CRD will drown your signal. I once ran a CRD on a batch of raw material that looked uniform but had a hidden moisture gradient across the warehouse floor. The results were all over the place and I spent three weeks trying to figure out why before I realized the design itself was the problem, not the data collection. Randomized Complete Block Design (RCBD) solves that problem by grouping similar units together into blocks. Within each block, treatments are randomized independently. This removes one source of variability from your error term. The tradeoff is that you need to know what the blocking factor is before you start, and if you pick the wrong one, you waste degrees of freedom for nothing. In practice, blocking works well for things like batches, locations, or time periods. It does not work well when the blocking factor interacts with your treatment in ways you did not predict. Factorial Designs let you test multiple factors at the same time instead of one at a time. A full 2^k factorial with two levels and k factors gives you main effects and every interaction in a single experiment. The downside scales exponentially: a 2^5 design needs 32 runs minimum, and a 2^6 needs 64. When I was designing a process optimization study with five factors, the full factorial was impossible within budget. I ended up using a fractional factorial, specifically a 2^(5-1) half-fraction, which gave me the main effects and two-factor interactions I needed in just 16 runs. I had to be careful about aliasing though. Two-factor interactions got confounded with each other, so I could not estimate everything simultaneously. Resolution V fractions avoid that but cost more runs.
Latin Square Design controls for two sources of nuisance variation at once, usually rows and columns. Each treatment appears exactly once in each row and once in each column. It is elegant and efficient when your constraints are truly two-dimensional. The catch is that it assumes no interaction between the row and column factors, and that assumption is often wrong. I ran into this when testing a coating process across different oven positions and different technician shifts. The Latin square looked perfect on paper until I noticed the interaction term was significant, which meant the design was quietly lying to me about the treatment effects. Cross-Over Designs let each subject serve as their own control by exposing them to multiple treatments in sequence. This is common in pharmaceutical trials and some manufacturing applications where subjects are expensive or hard to recruit. The major issue is carryover effect, where the first treatment leaves a residue that influences the response to the second. A proper washout period between stages is essential, and sometimes the washout needs to be longer than you initially think. In one study I worked on, the washout period we planned was insufficient and the carryover effect skewed the second period results. We had to redesign the entire experiment rather than try to correct it statistically after the fact. Split-Plot Designs come up when some factors are harder to change than others. You randomize the hard-to-change factor at the whole-plot level and the easy-to-change factor at the subplot level. This sounds wasteful but it is honest about your constraints. Agricultural field trials are the classic example where you cannot easily rerandomize irrigation treatment across every subplot. Industrial settings matter too, like when a temperature change requires a full reheat cycle. The statistical analysis is more complex because you have two error terms, but modern software handles it without much trouble. What trips people up is forgetting that the whole-plot and subplot errors are different and testing treatment effects against the wrong error term.
Get the Full Details

Choosing between these designs usually comes down to three questions: what sources of variability are you dealing with, how many factors do you need to test, and what are your resource constraints. There is no universal best option. A factorial design is better than anything else for screening, but it is terrible if you only have room for twelve runs and five factors. RCBD is straightforward until your blocks become too heterogeneous and you need mixed models instead. Latin squares are efficient right up until they are not, and then you are stuck with a compromised analysis. The field also includes derivative and specialized versions of these core types. Balanced incomplete block designs handle situations where you cannot fit all treatments into a single block. Strip-plot designs extend split-plot to two directions of hard-to-change factors. You will encounter these when someone tells you their problem is unique, which it almost never is. The standard designs have been around long enough that most practical problems map onto a known structure with minor adjustments. One thing nobody warns beginners about is the fragility of your assumptions. ANOVA, which underpins most of these designs, assumes normality, homogeneity of variance, and independence. Violate any of those and your p-values are garbage. I have seen entire projects go nowhere because someone ran a standard RCBD analysis on data that was clearly heteroscedastic. A quick residual plot would have caught it. Always check your diagnostics before you trust the output.
If you are starting out, begin with whatever design is simplest for your situation and escalate complexity only when necessary. Do not reach for a factorial because it sounds sophisticated. Do not avoid blocking because it feels like extra work. The right design is the one that matches your actual constraints and still answers the question you care about. Everything else is just complexity for its own sake.