Why Most People Get Directional Selection Wrong in Real Populations
I spent three years tracking allele frequencies in a lab population of flour beetles, watching directional selection play out in real time. The textbook version is clean. The actual data looks like noise with a slight drift. That disconnect between what you read and what you see is where things get interesting. There are three core types of natural selection, but the way they show up in nature is rarely as tidy as a bell curve being shaved on one side. Let me walk through what each type actually does, what goes wrong when you try to model it, and the one edge case that nearly cost me a semester of data.
The Main Types Of Natural Selection Explained
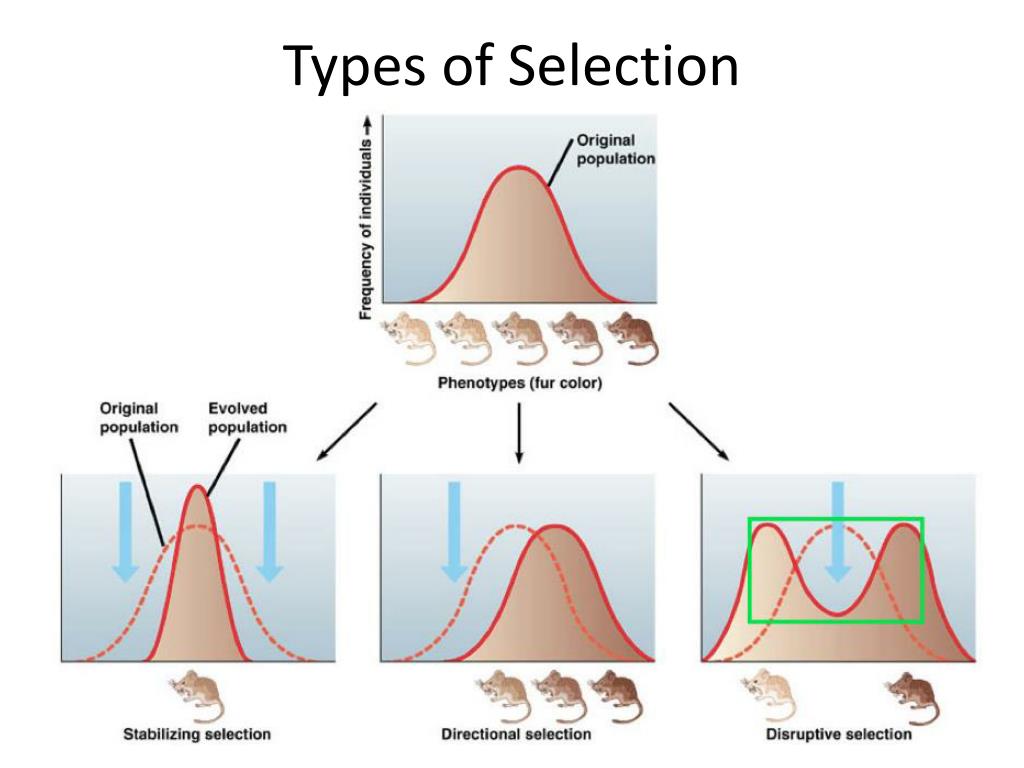
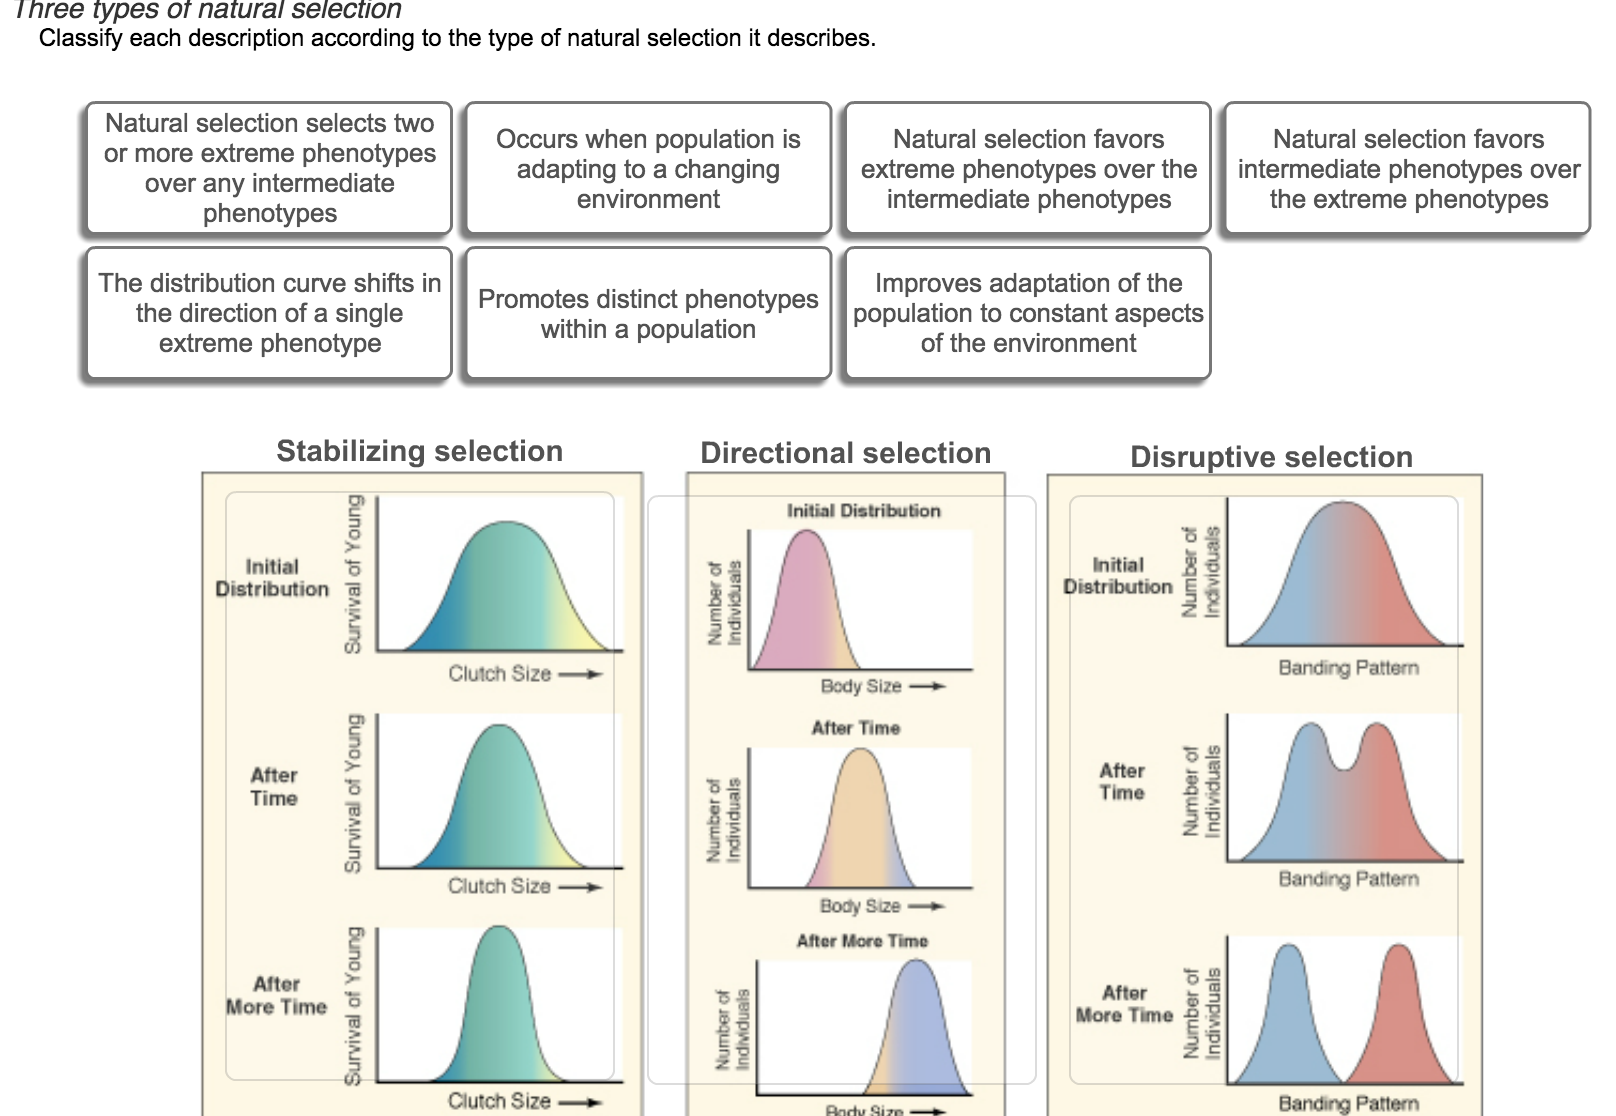
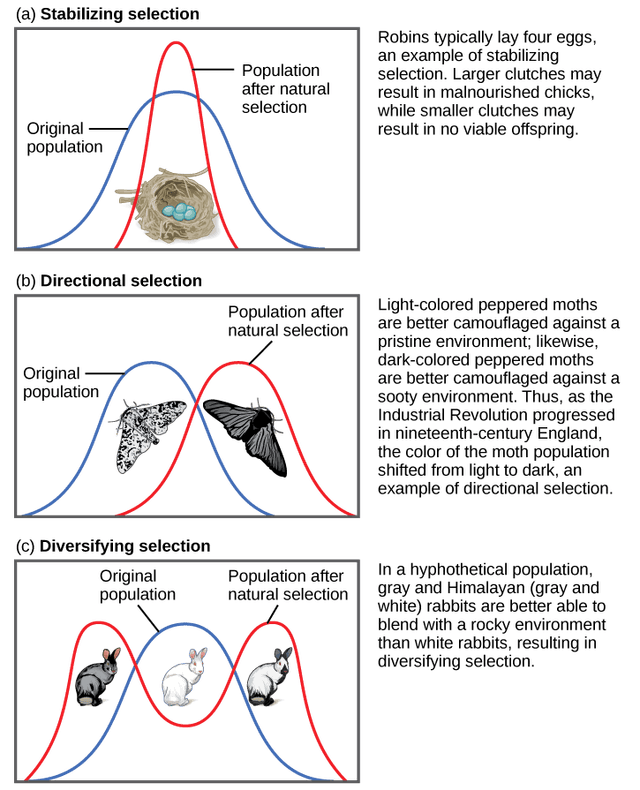
Directional selection shifts a population's trait distribution toward one extreme. It happens when environmental conditions change or a population moves to a new niche. Antibiotic resistance in bacteria is the textbook example, but it shows up everywhere from beak size in Galápagos finches during drought cycles to pesticide resistance in agricultural pests within 5 to 12 generations depending on the compound and reproduction rate. Stabilizing selection trims the extremes and favors the mean. Human birth weight is the classic case because both very low and very high birth weights carry higher mortality risk. This type of selection reduces genetic variance without shifting the average. It sounds harmless but it quietly erodes the raw material future evolution needs. I saw this firsthand in a captive salamander population where we were selecting for consistent size across ten generations and ended up with individuals that couldn't handle temperature fluctuations that would have been normal in the wild. Disruptive selection pushes toward both extremes simultaneously, creating a bimodal distribution. This is the type most likely to drive speciation over enough time. African seedcracker birds with either small or large beaks depending on seed type available, and certain fish species where medium-sized individuals are at a disadvantage in both microhabitats they occupy. It is rare in practice because it requires a specific set of conditions: two distinct niches, limited gene flow between them, and strong enough selection pressure that heterozygotes or intermediate phenotypes get filtered out hard enough to matter.
What No One Tells You About Measuring Selection
The fitness component is almost always the tricky part. People grab survival rates and call it done, but reproductive output tells a completely different story. A genotype might survive equally well to adulthood but produce half as many offspring due to mating disadvantages or gamete competition. If you only measure survival, you miss half the selection happening. I ran into this exact problem during my beetle work. We were tracking body size and noticed what looked like directional selection favoring larger individuals based on survival through larval stages. When we factored in mating success and egg count, the pattern reversed. Larger males won more fights but smaller males sired more offspring through sneaker tactics. The net selection coefficient flipped from positive to negative once reproduction entered the equation. Had I published on survival alone, I would have been wrong. Another thing beginners miss: selection coefficients are environment-dependent. A genotype under strong positive selection today can be neutral or deleterious tomorrow with a slight shift in temperature, food availability, or predator pressure. The selection acting on a population is never a fixed property of the genotype itself. It is a relationship between genotype and environment, and that relationship changes.
Get the Full Details

How to Actually Detect Selection in the Wild
You start with phenotypic data across a large sample size, ideally hundreds of individuals measured for the trait in question. Then you estimate fitness components for each phenotype class. The breeder's equation R = h²S is the foundation, but it assumes additive genetic variance and a constant environment, neither of which holds in real populations. I use selection gradients instead of simple coefficients because they account for correlated traits. If you don't control for correlated characters, you attribute selection to the wrong trait. Likelihood-based approaches with mark-recapture data give more reliable estimates than snapshot studies. I typically run them through a custom R script that incorporates detection probability, because imperfect detection biases everything downward. The difference between a naive analysis and a detection-corrected one can change your estimated selection gradient by 30 to 60 percent depending on the species and sampling method.
The Bottleneck Nobody Talks About
Genetic drift masquerades as selection in small populations. When effective population size drops below a few hundred, random allele frequency changes become large enough to look like directional selection over short timeframes. I had a graduate student spend two months convinced we were seeing strong selection on a color morph in a small island bird population. When we increased the sample and ran a drift simulation with the estimated Ne, the observed pattern fell entirely within the drift expectation range. We had been reading selection into noise. The workaround was running 10,000 coalescent simulations under the estimated demography and checking whether the selection parameter was identifiable given the data. It wasn't. Once we knew that, we stopped forcing a selection narrative onto the data and reported the drift result instead. Honest science is more useful than a clean story. Another failure mode: temporal variation in selection direction. If selection flips direction every few generations, the long-term response can be near zero even though strong selection is happening each generation. This is common in fluctuating environments and it means short-term studies can be deeply misleading about evolutionary trajectories. My recommendation is to run studies across at least three generations minimum, and ideally more if the organism's generation time allows it.
When Natural Selection Models Break Completely
They break when gene flow is high relative to selection pressure. If immigrants make up more than 10 to 20 percent of the breeding population per generation, local adaptation can be swamped entirely. I worked with a stream insect population where the downstream source population was dumping so many individuals into the study reach that the local selection gradient needed to maintain adaptation was essentially infinite. It couldn't be maintained. The population tracked the source genotype pool rather than adapting locally. Nothing wrong with the selection model, the model just assumed conditions that didn't exist on the ground. Epistasis also complicates things significantly. When gene interactions matter, the marginal effect of a single locus depends on the genetic background. Selection on one genotype produces different outcomes in different backgrounds. This is why genome-wide association studies sometimes fail to replicate across populations and why quantitative genetics models with only additive effects miss substantial portions of the genetic architecture. For most field work, additive models are good enough as an approximation, but you should know when that approximation is breaking down. The takeaway is that Types Of Natural Selection are real patterns, but detecting and quantifying them requires careful attention to what you're actually measuring, how your sampling design shapes the signal, and whether drift, gene flow, or epistasis is wearing a selection costume in your data.