Understanding The Different Kinds Of RNA And What Actually Matters
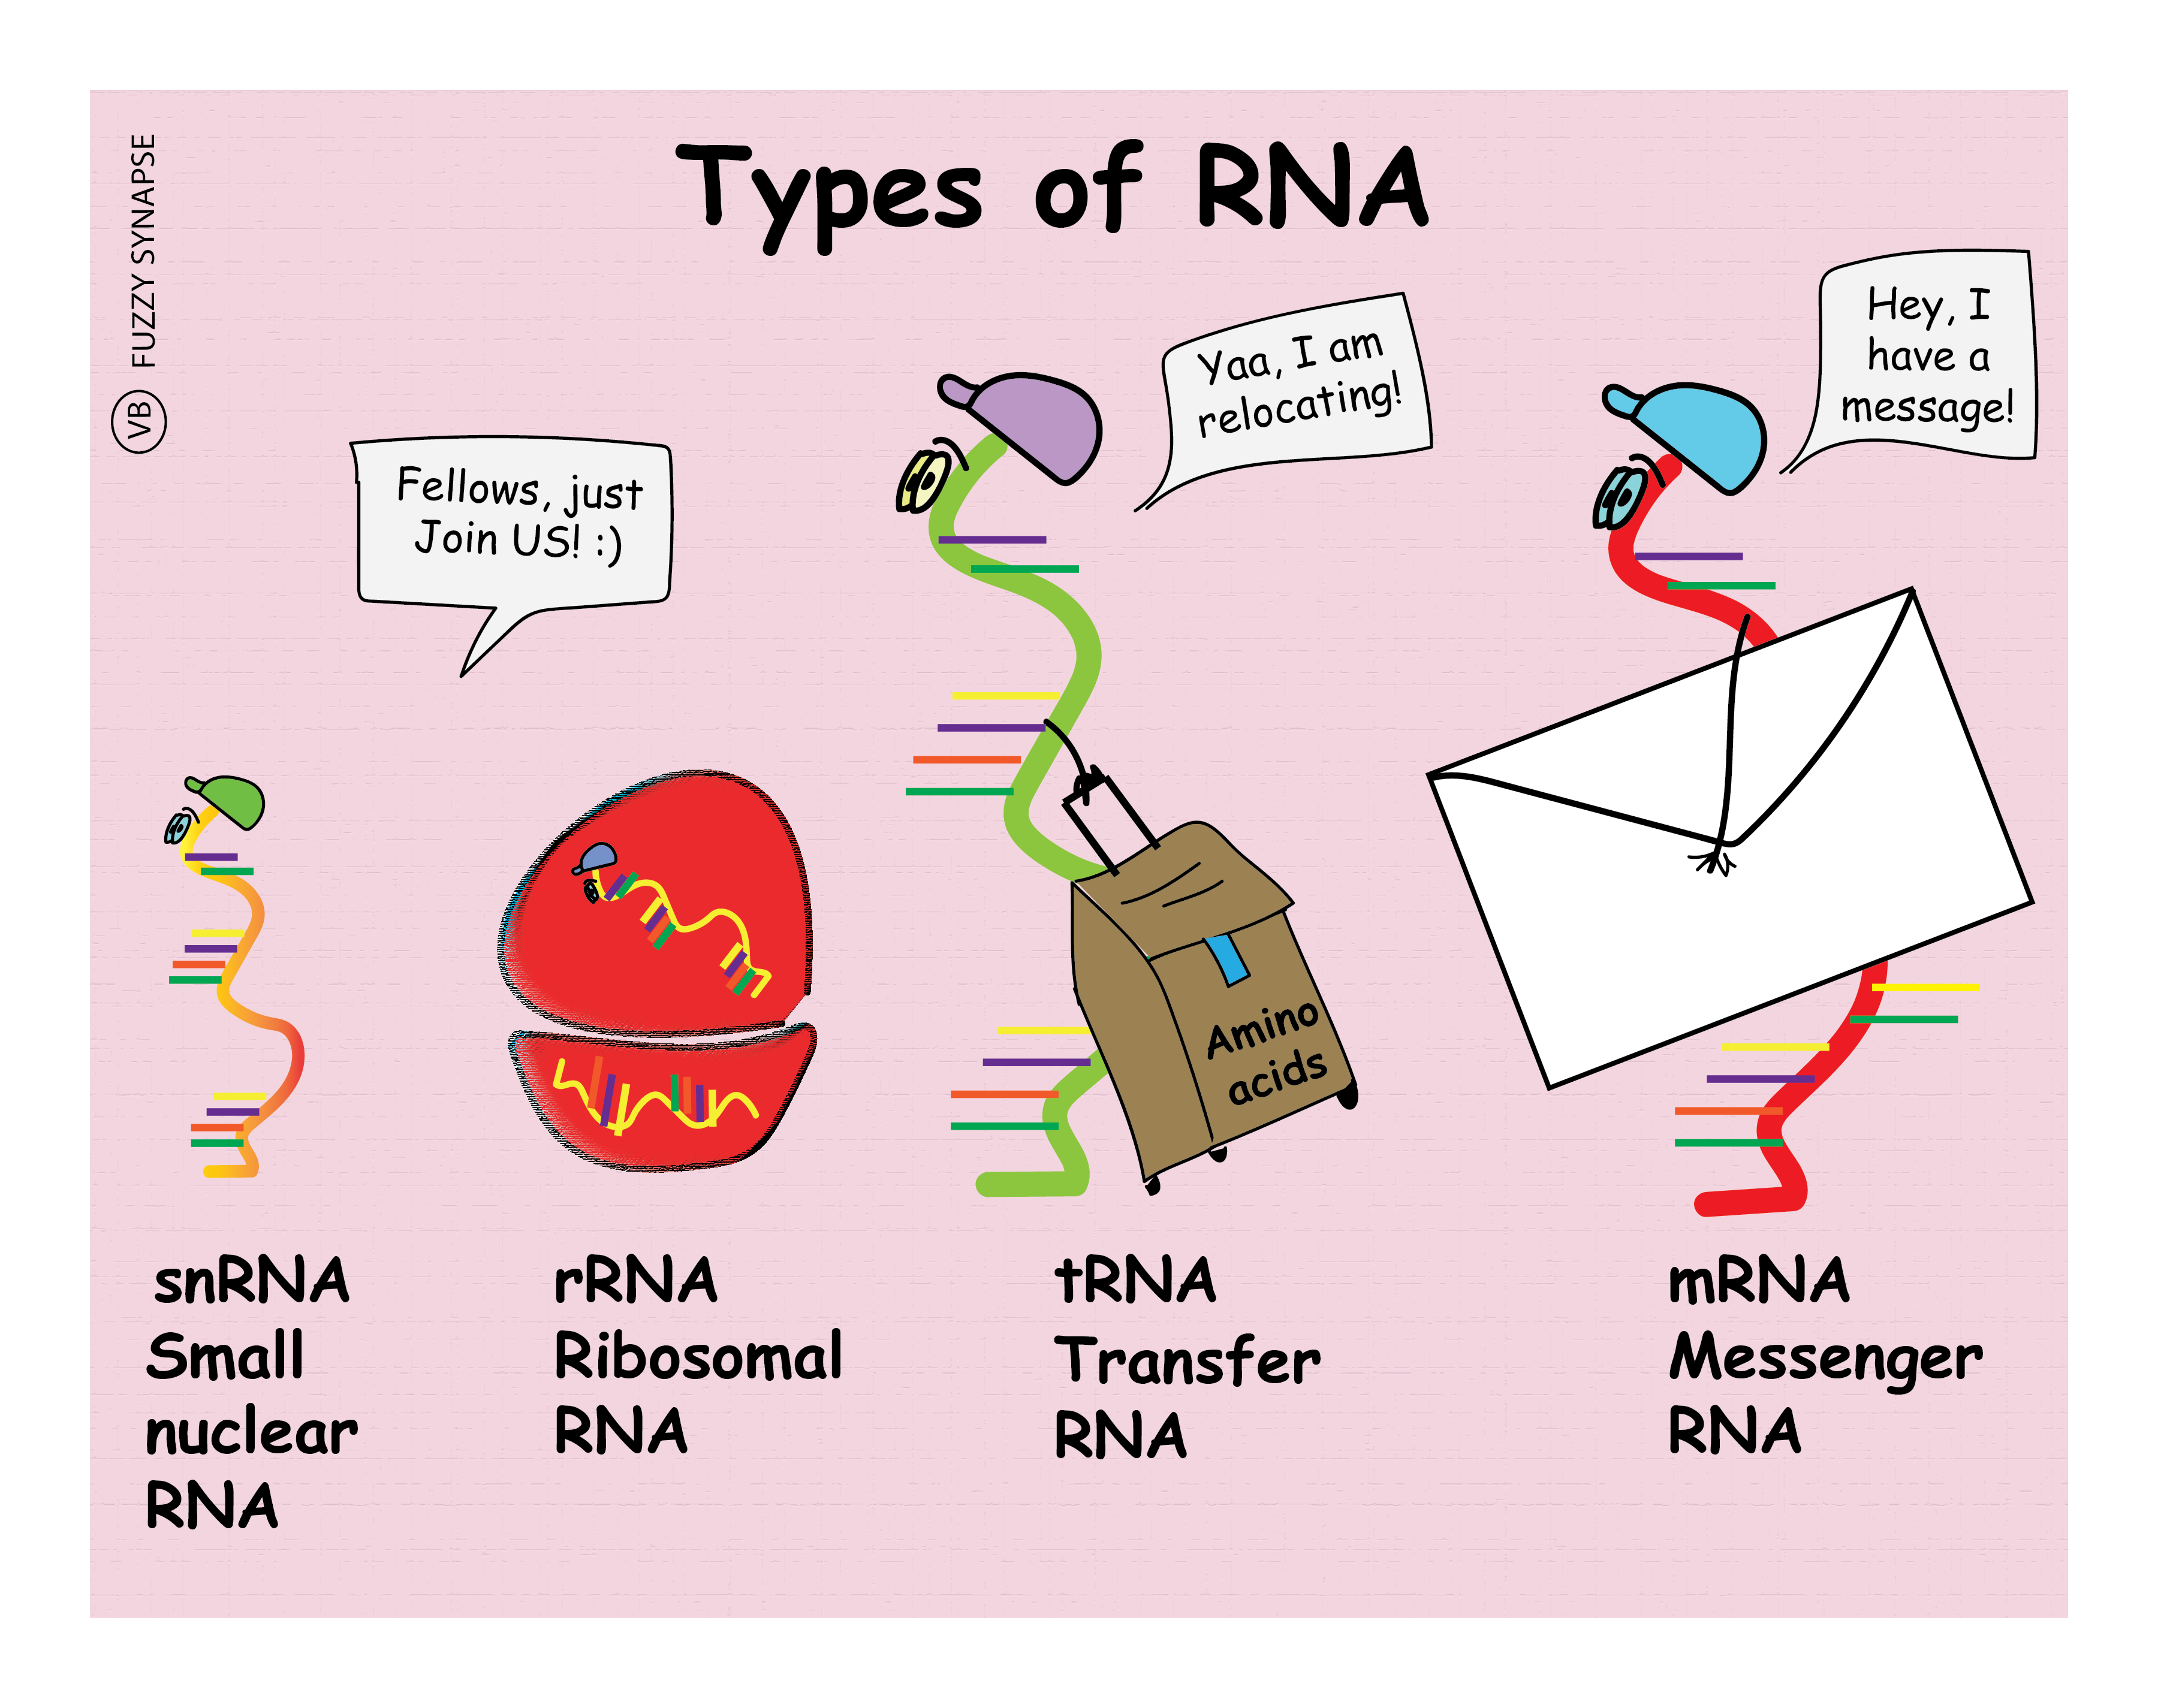
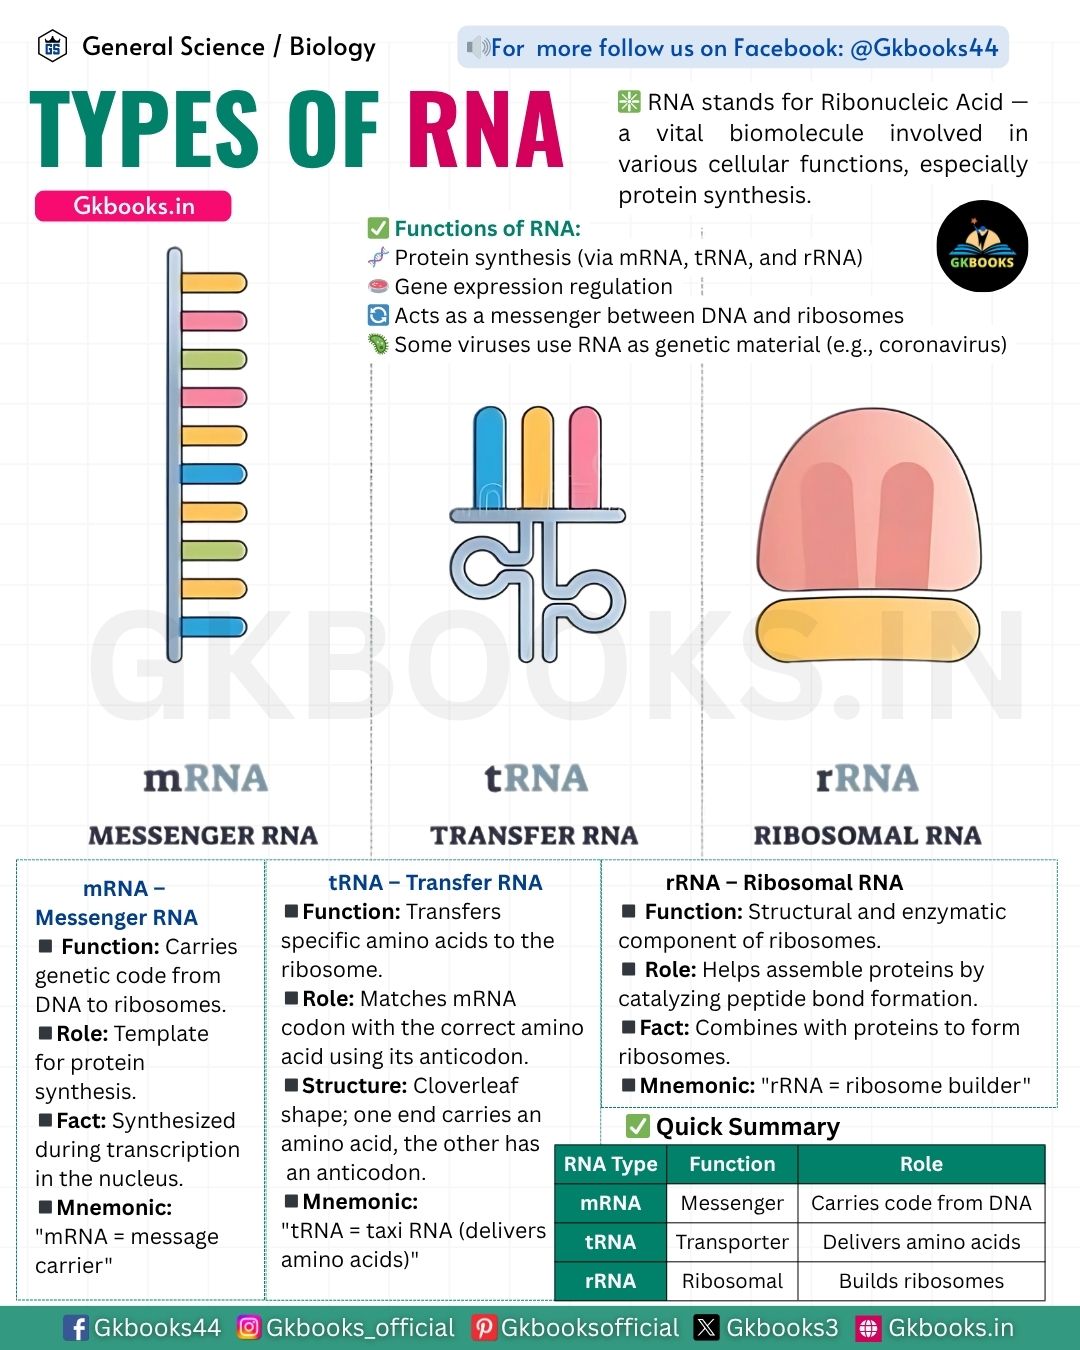
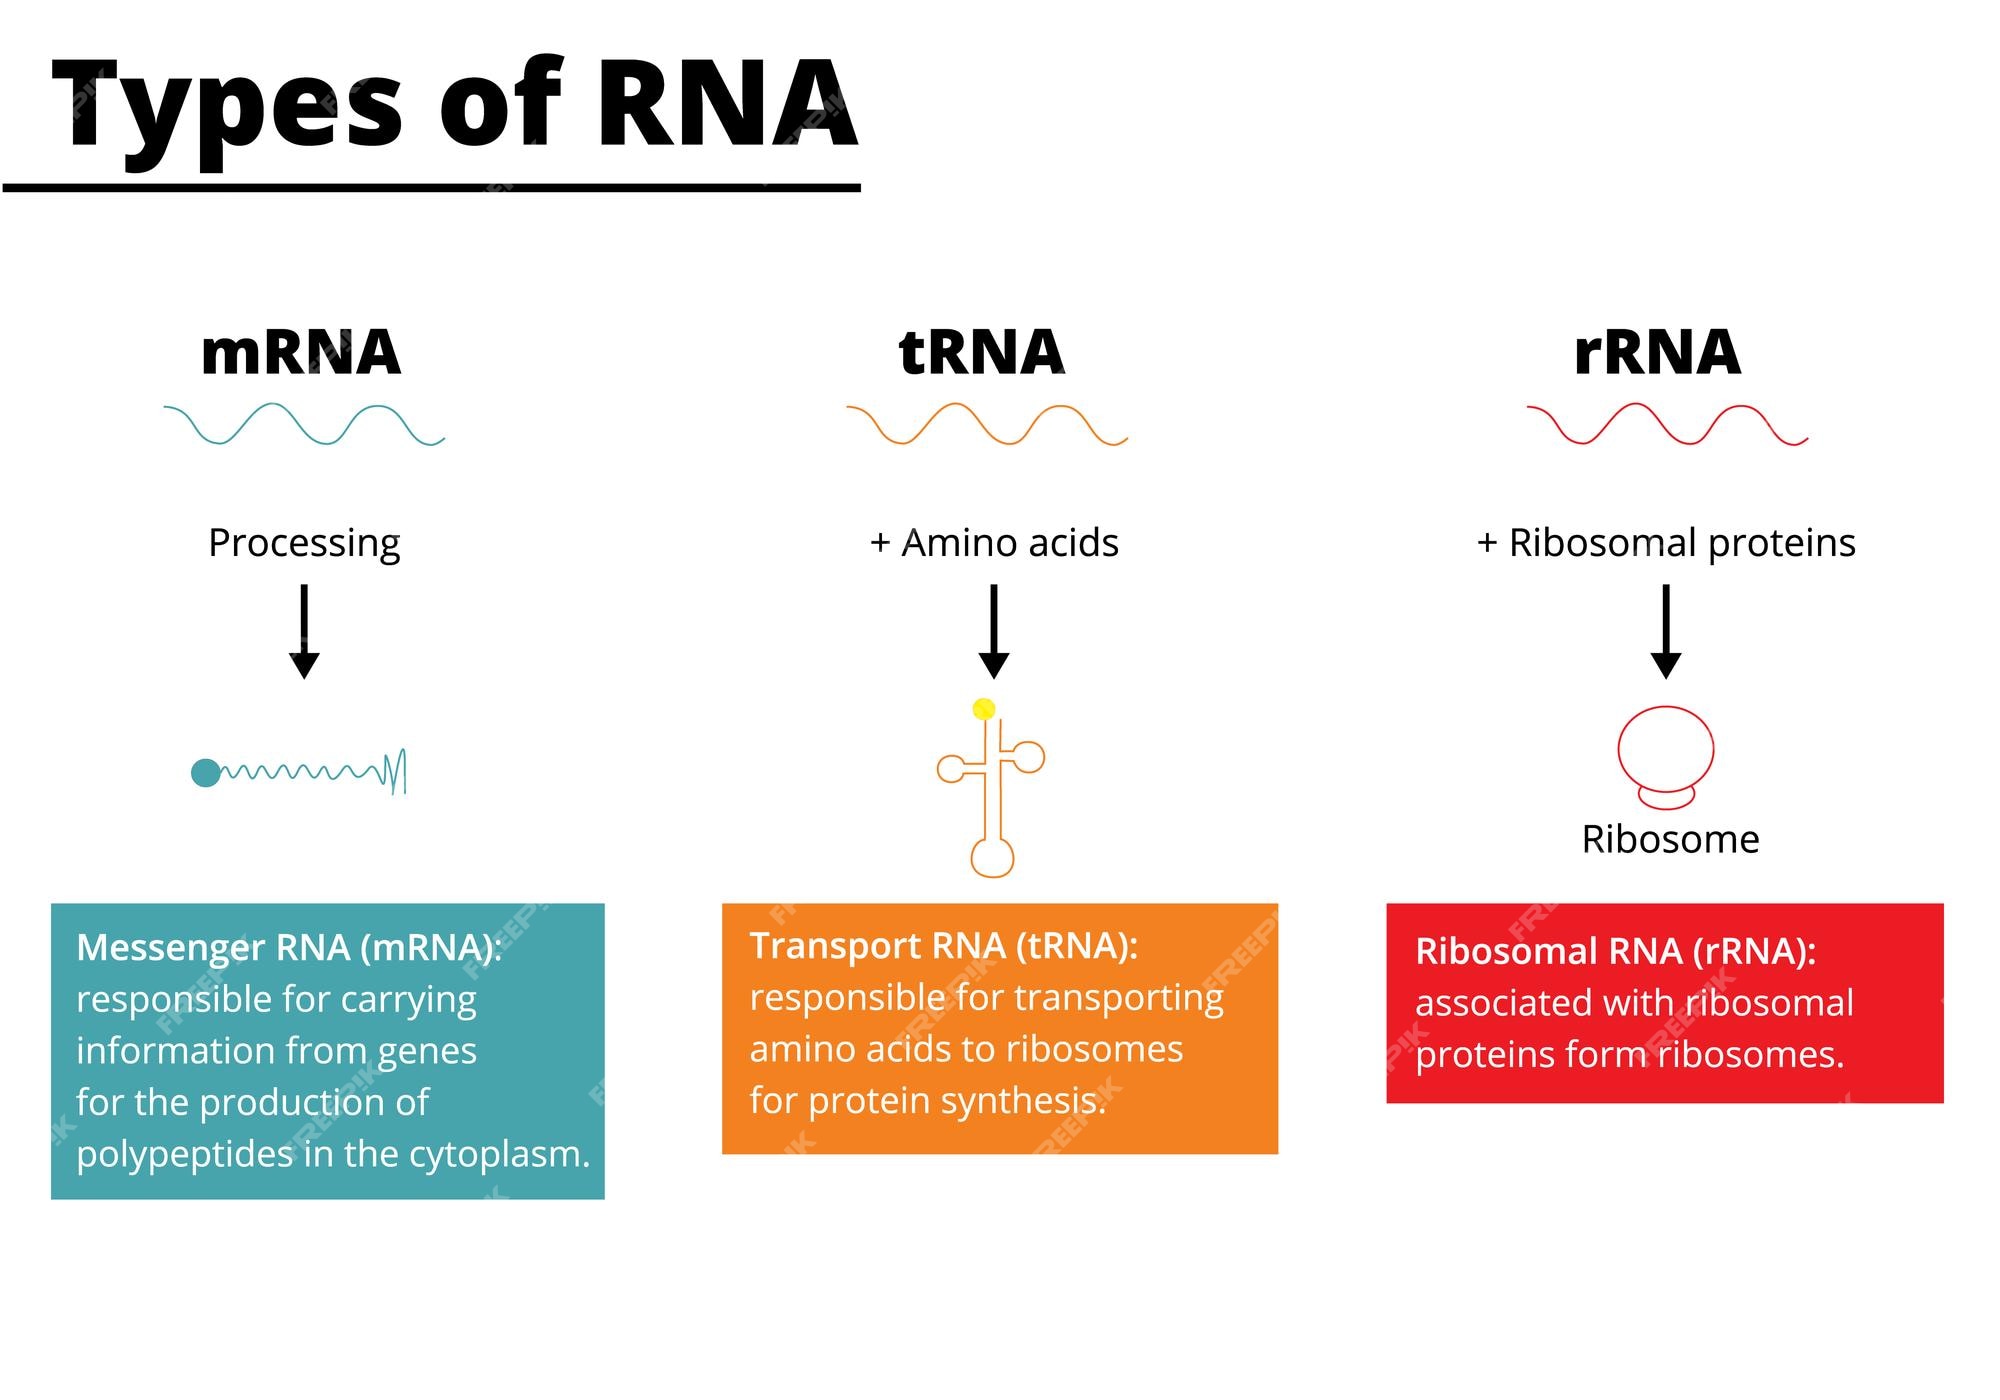
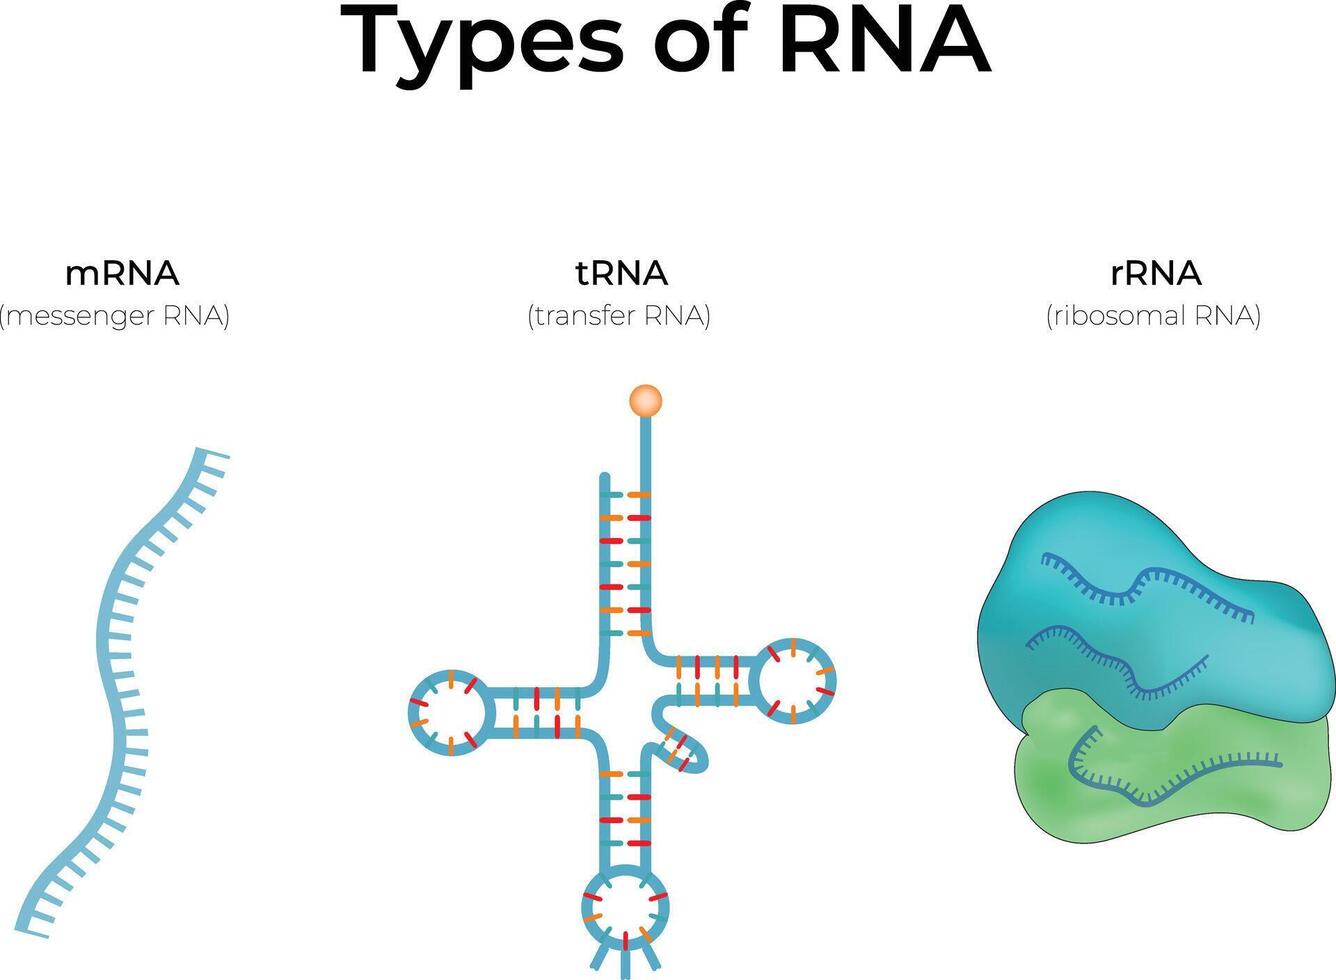
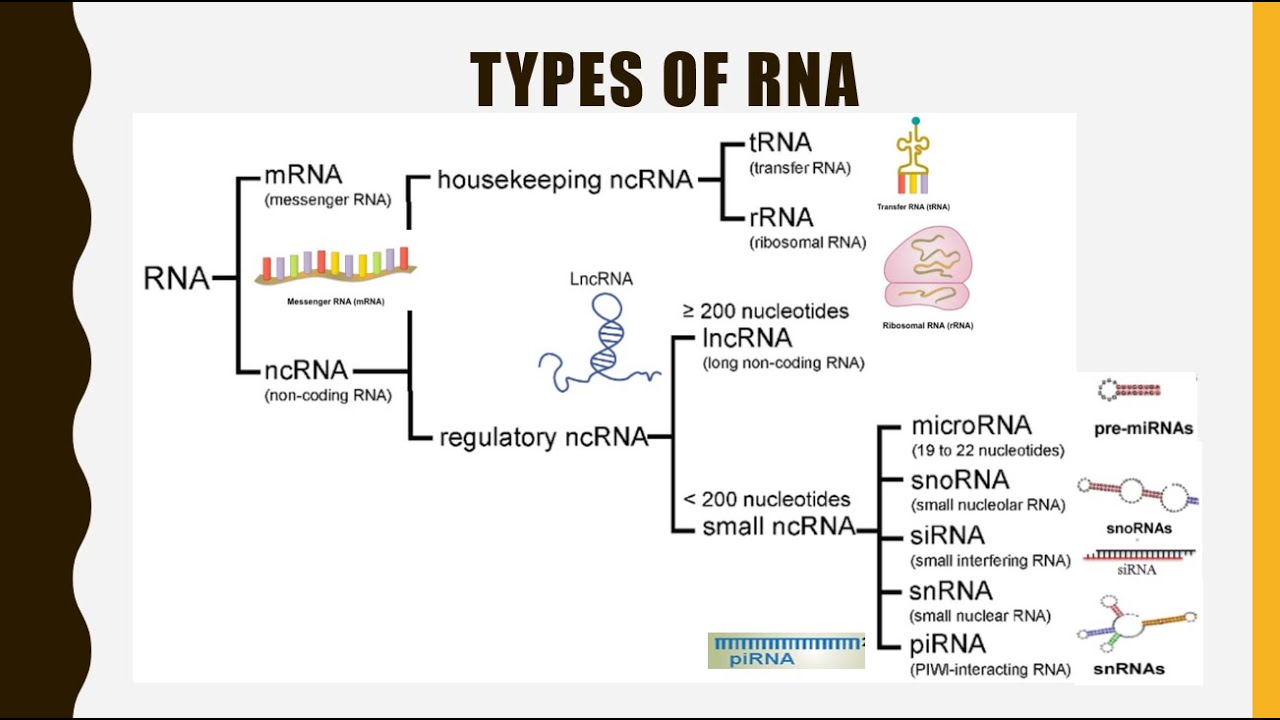
RNA is everywhere in molecular biology, but most people stop at the three main types they learned in undergrad. That's fine for a basic explanation, but if you're actually working with RNA in a lab or doing anything beyond memorizing for an exam, you need to know about the smaller, messier kinds too. I spent way too many hours troubleshooting RNA-seq data before I really understood why non-coding RNAs kept showing up in my preparations. mRNA carries the coding instructions from DNA to the ribosome. That's the textbook version. In practice, mRNA is also the most unstable type you'll deal with because it has those long untranslated regions and isn't protected by much. I once lost an entire sample batch because I left a tube on the bench for twelve minutes after adding the lysis buffer. Yeah, it happens. tRNA is the adapter molecule. It reads the codon on the mRNA and brings the right amino acid. There are about 40 to 60 different tRNAs in most cells, each one specific to an amino acid. The structure is pretty conserved — that cloverleaf secondary structure that folds into an L-shape in three dimensions. If you're doing anything with translation in vitro, getting the tRNA quality right matters more than people realize. Degraded tRNA will silently kill your protein expression without any obvious warning signs until you've already spent hours on the reaction.
rRNA makes up the structural and catalytic core of the ribosome. The big subunit in bacteria has the 23S and 5S, while the small one has the 16S. In eukaryotes it's 28S, 5.8S, and 18S. When you run a bioanalyzer trace of total RNA, those two sharp rRNA peaks you see — the 28S and 18S — are basically your quality metric. A good sample shows a 28S band that's roughly twice as intense as the 18S. If that ratio looks wrong, your RNA is degraded and there's no easy fix after the fact.
Types Of R N A Beyond The Basics
MicroRNA, or miRNA, is about 22 nucleotides long and regulates gene expression post-transcriptionally. It binds to complementary sequences on target mRNAs and either blocks translation or promotes degradation. The weird thing about miRNA is how promiscuous the binding can be. A single miRNA might regulate hundreds of different mRNAs, and a single mRNA can be targeted by multiple miRNAs. That's why functional validation is basically mandatory if you're claiming a miRNA-mRNA interaction. In silico prediction tools will give you a list, but half of it won't hold up under real conditions. Long non-coding RNA, or lncRNA, is anything over 200 nucleotides that doesn't code for protein. This category is huge and still poorly understood. Some lncRNAs have genuine biological functions, like XIST in X-chromosome inactivation. Others might just be transcriptional noise. Distinguishing between the two is one of the hardest problems in the field right now. I worked on a project where we spent three months trying to validate a lncRNA that looked really interesting in the sequencing data, and in the end we couldn't show any functional effect beyond what we'd expect from random transcription. Small interfering RNA, or siRNA, is another regulatory type. It's usually 20 to 25 nucleotides and works through the RNA interference pathway. siRNA is basically the same machinery as miRNA but typically more specific because it's usually perfectly complementary to its target. This is why siRNA became the go-to tool for knockdown experiments. You design the sequence, synthesize it, and add it to your cells. That simplicity is also what makes it dangerous — off-target effects are real and happen a lot more than people admit. A single nucleotide mismatch can change your whole results, and you won't necessarily know it happened.
Get the Full Details
Small nuclear RNA, or snRNA, is involved in splicing. These are the components of the spliceosome, which cuts out introns from pre-mRNA. The main ones are U1, U2, U4, U5, and U6. If snRNA function is disrupted, you get abnormal splicing patterns, and that can lead to disease. There are also small nucleolar RNAs, or snoRNAs, which mainly guide chemical modifications of other RNAs, especially rRNA. The two main classes are the H/ACA box snoRNAs and the C/D box snoRNAs. They do very different things — one guides pseudouridylation and the other guides 2'-O-methylation. Circular RNA, or circRNA, has been getting a lot of attention lately. These are covalently closed loops with no free ends, which makes them unusually stable compared to linear RNA. Some circRNAs act as miRNA sponges, soaking up miRNAs and preventing them from reaching their targets. The evidence for this is solid for a few well-studied examples, but it's probably not the general rule. Most circRNAs might just be byproducts of back-splicing with no real function.
Practical Considerations When Working With RNA
If you're handling RNA experimentally, the single most important thing is RNase contamination. RNases are everywhere — on your skin, in dust, on lab equipment. They're also extremely stable and hard to destroy. Standard autoclaving doesn't reliably inactivate them. The workarounds are decontamination solutions containing denaturants, using certified RNase-free consumables, and working quickly on ice. I once spent a full day repeating an RNA extraction because someone used a regular pipette tip box near an open RNA sample. You'd be surprised how far RNase can travel on a contaminated surface. Another thing that trips people up is that not all RNA types can be captured the same way. Standard poly-A selection works great for mRNA because it has that polyadenylated tail, but it completely misses non-polyadenylated RNAs like most lncRNAs, circRNAs, and bacterial transcripts. If your research question involves any of those, you need a different library preparation strategy, often ribosomal depletion instead of poly-A capture. I learned this the hard way when I was designing an RNA-seq experiment and realized halfway through that my library prep method would have erased every circRNA in my samples. The quantification methods also vary depending on what you're measuring. Spectrophotometry with a Nanodrop is quick but it can't distinguish between different RNA types. It just tells you total nucleic acid concentration. If you need to know the integrity or the relative abundance of specific RNAs, gel electrophoresis or a bioanalyzer is necessary. Fluorometric methods like Qubit are better for accurate quantification because they're nucleic acid-specific and less affected by contaminants.
Storage is another area where people make mistakes. RNA should be kept at minus 80 degrees Celsius for long-term storage. Freeze-thaw cycles degrade it, so aliquot your samples immediately after preparation. If you're storing RNA at minus 20 in a standard freezer, it will degrade over weeks. I've seen people do this and then wonder why their qPCR efficiency dropped to barely above fifty percent. The math doesn't add up and there's nothing wrong with the primers — the RNA was just sitting in the wrong temperature for too long.
Common Pitfalls
One thing that beginner researchers consistently underestimate is the variability between RNA types in the same sample. When you do bulk RNA-seq, you're averaging across thousands of cells, and rare cell types or low-abundance transcripts can get lost in the noise. Single-cell RNA-seq fixes that to some extent, but it introduces its own problems like dropouts where a transcript is present but not detected. Neither method gives you a complete picture. Another issue is that RNA structure matters more than people think. Secondary structures like hairpins and G-quadruplexes can interfere with reverse transcription and cause premature termination. If you're doing RT-qPCR and getting weird amplification curves, check whether your target region has strong secondary structure. Template-switching methods or using thermostable reverse transcriptases can help mitigate this, but you need to know it's a problem first. The biggest misconception I see is that more RNA input is always better. For many applications, excess RNA can actually be detrimental. It can saturate enzymatic reactions, increase the chance of contamination, and in sequencing applications, it can lead to over-clustering on the flow cell. The optimal input amount depends entirely on what you're doing, and the manufacturers' recommendations are usually starting points rather than rules.
RNA biology is more complex than the basic textbooks suggest, and the types keep getting refined as new techniques emerge. Understanding what you're working with and what each type actually does in practice matters more than memorizing definitions. The experimental realities — contamination, degradation, method selection — are what separate a working protocol from one that fails quietly.