Why Bother With a Checklist at All
JavaScript projects accumulate enough moving parts that remembering every lint rule, bundle step, and edge case by memory is a losing bet. A well-structured checklist doesn't make you lazy, it makes you consistent. I've seen senior engineers miss the same security gotcha on three separate projects because nobody caught it during review. A checklist catches that. The thing most people get wrong is assuming a JavaScript checklist is just a list of linter rules. It's not. It's a sequence of checkpoints across your entire workflow. Setup, build, testing, deployment, security, performance, documentation. Each stage has its own traps.
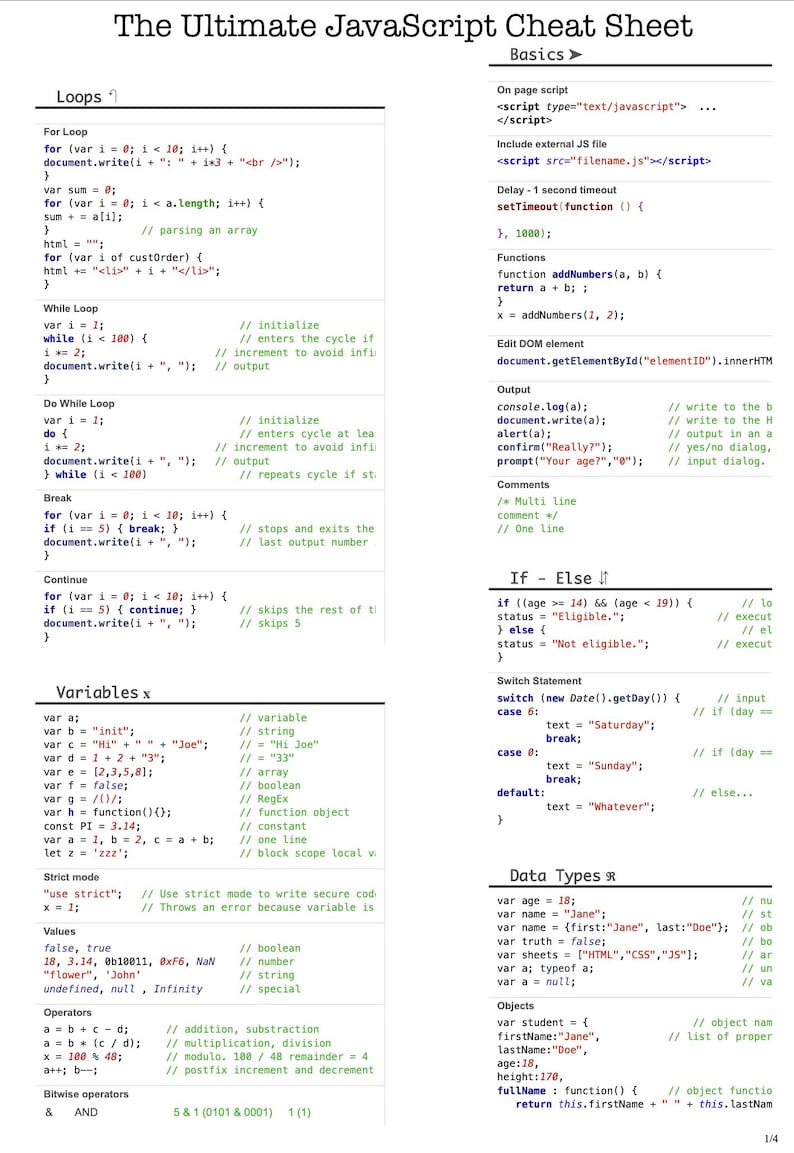
The Ultimate Guide For JavaScript Checklist
Here's what I actually use. I'm not going to break this down into neat pedagogical sections because that's not how any of this works in practice. Real projects are messy, and the checklist needs to reflect that. Start with your package.json. Verify the engine field is set explicitly. This sounds minor until someone clones your repo on Node 18 when your code requires 20. I had a production bug where optional chaining with nullish coalescing behaved differently on an older runtime because the CI environment was misconfigured. Took me four hours to find because I assumed the version match was checked. Check your .nvmrc or .node-version file exists if you use version managers. Then verify your ESLint configuration covers the rules you actually care about. Most templates ship with way too many rules or way too few. I disable the ones that cause more arguments than they prevent. Space-before-function-paren is not worth the war it starts in a team.
TypeScript setup deserves its own line item even if you aren't using it heavily. tsconfig.json should have strict mode enabled. No implicitly any. If you're forcing casts with as or non-null assertions throughout your codebase, your type safety is theater. I once audited a codebase and found 400 non-null assertions. That's not a project using TypeScript, that's a project pretending to use TypeScript. Check your .gitignore is complete. node_modules, dist, .env files, coverage reports. I've pushed .env files to git twice now. Both times the API keys were rotated within an hour. The checklist entry here is simple: run git-check-ignore on your sensitive files before the first commit.
Get the Full Details
Build and Bundling
Verify your build tool configuration handles tree shaking correctly. This means checking that your imports are static and not dynamically generated at runtime. Dynamic imports are fine, but they won't be tree-shaken. If you're using something like: const module = await import(variable), that's intentional, but document it. Otherwise you might be shipping three hundred kilobytes of unused code and wondering why your load time is terrible. Check for sourcemap configuration. In development, source maps are essential. In production, they're a security and performance decision. Some teams leave them enabled by default. They shouldn't. I configure my builds to generate production sourcemaps separately and upload them to a private bucket.sourcemaps let anyone trace your source code from the browser console. Bundler size analysis should be a checklist item, not an afterthought. Run a bundle report on every major merge. If your vendor chunk grew by forty percent without a corresponding feature, investigate. I once found that importing an entire date library for a single formatting function added nearly sixty kilobytes to the production bundle. The fix was swapping to a lighter alternative.
Testing
Most JavaScript projects have insufficient test coverage for edge cases. The common pattern is testing the happy path and calling it done. I structure my checklist around gap analysis: what happens when the API returns empty, null, or a 500 error. What happens when the user submits invalid data. What happens when two async operations race. Mock your network calls properly. Using nock or MSW instead of stubbing fetch globally prevents side effects between tests. I learned this the hard way when a authentication test started failing intermittently because another test had monkey-patched the global fetch and never cleaned up. Fifteen minutes of debugging that a proper mock setup would have prevented entirely. Snapshot tests are useful but dangerous if treated as gospel. They catch regressions but they also encourage mindless accepting of broken snapshots. Every time you run jest --update-snapshot, review what actually changed. Don't bulk-accept. I've caught cases where a component was rendering garbage and the snapshot just matched the garbage.
Check your test timeout configuration. Default timeouts are often too aggressive for integration tests involving real databases or external APIs. I set explicit timeouts per test suite and document why. A ten-second timeout for a database query test is normal. A ten-second timeout for a unit test means your test is doing something wrong.
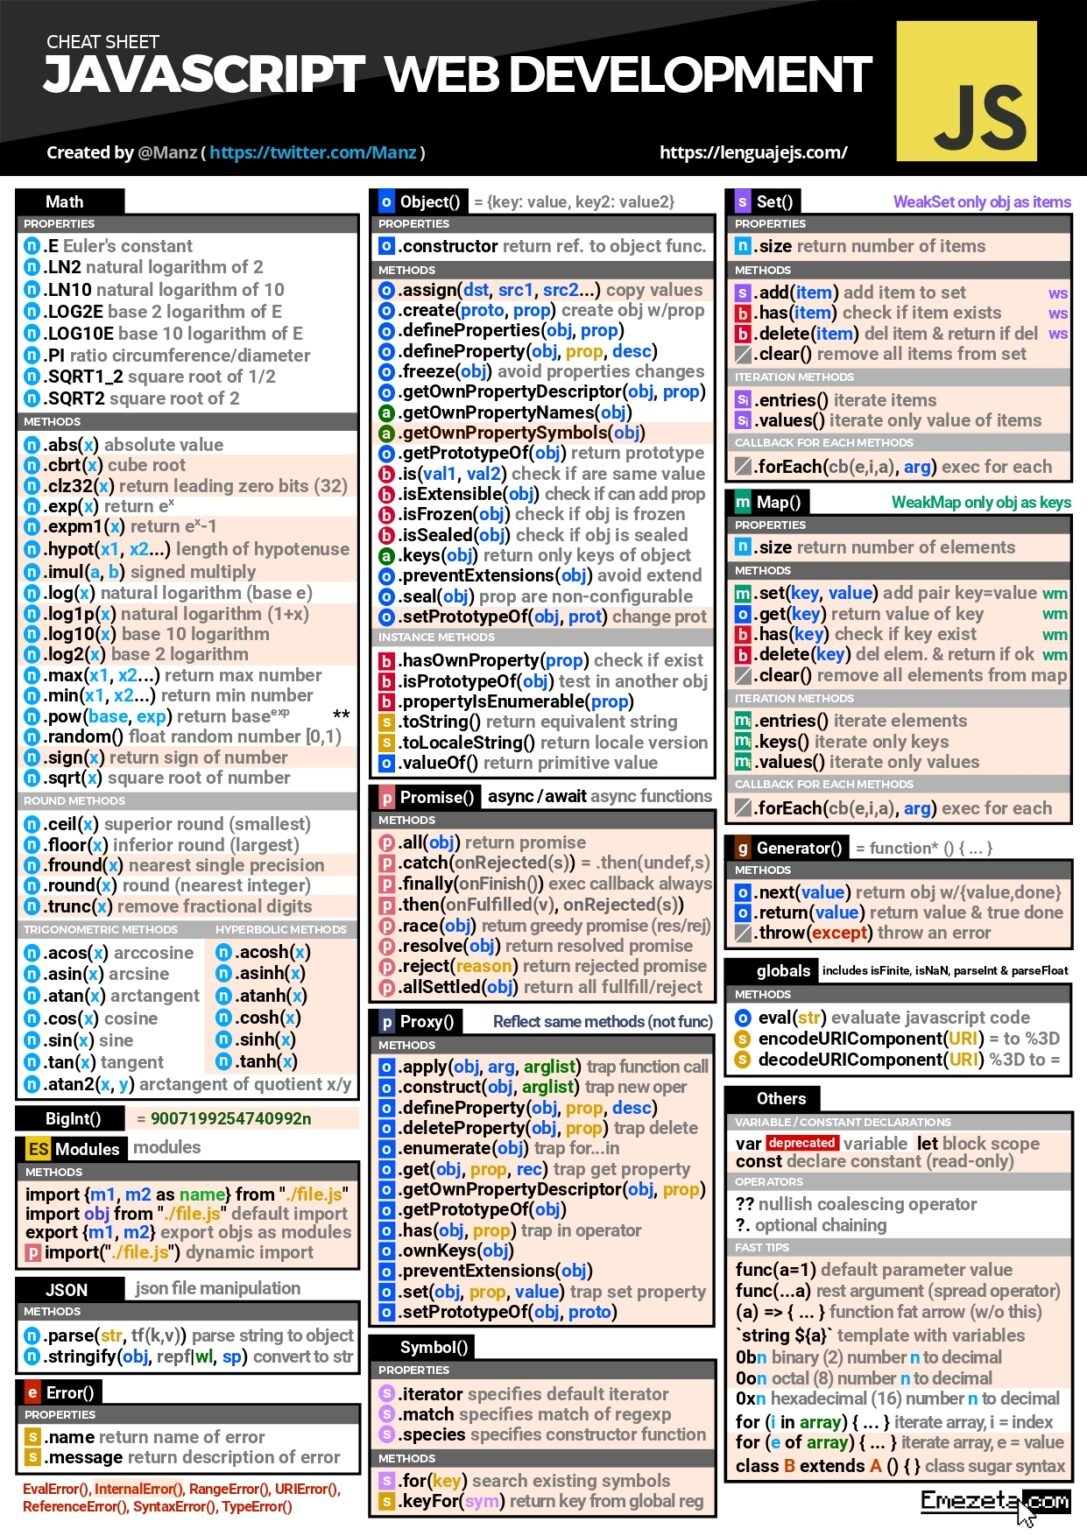
Security
This is where I get blunt because most teams skip it. Run a dependency audit on every deployment. npm audit, yarn audit, or your package manager's equivalent. More importantly, run npm audit --production to focus on what's actually shipped. Development dependencies can have vulnerabilities without affecting your users, and cluttering your CI with those warnings is useless. XSS is still the most common vulnerability in JavaScript applications. Even if you're using React or Vue with their built-in escaping, custom HTML injection through dangerouslySetInnerHTML, v-html, or innerHTML bypasses everything. I check every instance of raw HTML rendering in my codebase. If you're building a rich text editor, document your sanitization strategy. DOMPurify is fine, but misconfigured DOMPurify is worse than no sanitization at all. CSRF protection matters more than people think in single-page applications. If your API accepts state-changing requests without proper token validation, you're vulnerable. The checklist item here is verifying that sensitive endpoints require either a custom header, a CSRF token, or are using SameSite cookie attributes. Modern browsers enforce SameSite by default now, but relying on browser behavior instead of server-side validation is fragile.
I encountered a specific issue once where a JWT verification library had a known vulnerability in its algorithm negotiation. The library accepted HS256 tokens when configured for RS256, which allowed signature forgery. The fix was pinning the exact version and adding a verification that the algorithm matched expectations. This wasn't caught by any linter or automated tool. It required reading the library's source and understanding the crypto implications.
Performance
Lighthouse audits should be part of your deployment pipeline. Not a weekly thing, a every-deployment thing. Configure it to fail the build if critical metrics drop below thresholds. Core Web Vitals aren't vanity metrics. They directly affect conversion rates and search rankings. I've seen page load times increase from 1.2 seconds to 4.8 seconds after a refactor that added unnecessary re-renders. The culprit was a context provider wrapping too much of the component tree. Check for unnecessary re-renders in React applications. React.memo, useMemo, and useCallback are tools, not solutions. Wrapping everything in memo is worse than nothing because it creates false confidence. Profile before optimizing. The Chrome DevTools profiler is free and accurate. Use it. Lazy loading routes and components is standard practice now. But verify your lazy-loaded bundles are actually being loaded on demand. I've reviewed projects where lazy imports were written but the bundler configuration merged them back together anyway. Check your output chunks.
Code Quality and Conventions
Consistent code style matters more than any specific style choice. A project using Prettier with a agreed-upon config is better than a project where every developer formats code differently. The argument about tabs versus spaces is irrelevant. The argument about no one having format-on-save configured is valid. TypeScript strictness should increase over time, not decrease. I've seen projects start with strict mode and then systematically disable checks because they were "too noisy." That's the wrong direction. If a type error surfaces, fix the type, don't silence the checker. A project that turns off noImplicitAny halfway through is a project that gave up on type safety. Dead code elimination is harder than it sounds. Unused functions, unused imports, unreachable branches. These accumulate silently. I run eslint-plugin-unused-imports and ts-prune regularly. The output is usually larger than people expect.
Deployment and CI/CD
Your CI pipeline should run the full checklist automatically. Linting, type checking, testing, security auditing, bundle analysis. If a human has to remember to run anything before deploying, you're already behind. I've seen staging environments diverge from local setups enough that bugs that passed all local checks failed in production. Environment parity matters. Rollback strategy should be documented and tested. Automated deployments without a tested rollback path are a single bad commit away from an outage. I keep a runbook for rolling back to the previous version. It should take less than five minutes to execute. Secret management is non-negotiable. Environment variables in CI, not in code. HashiCorp Vault, AWS Secrets Manager, or whatever your infrastructure supports. I've seen projects store API keys in .env files that get committed to version control, then discover it six months later when a junior developer pushes a PR with their local credentials.
Documentation
README files should answer three questions: what does this do, how do I run it, and where do I find the important details. Most READMEs fail at the second question. Installation instructions that assume prior knowledge are not installation instructions. API documentation should match the actual implementation. Outdated docs are worse than no docs because they build false confidence. I generate documentation from code annotations where possible and manually update it when the code changes. If updating docs feels like a chore, your documentation process is broken. Changelogs matter for projects with multiple contributors. Keep one. It doesn't need to be elaborate. Date, category, description is sufficient. When something breaks in production and you need to know what changed recently, searching git commits is slower than reading a changelog.
Common Pitfalls I Keep Encountering
Mutable default values in function parameters. function foo(items = []) creates a new array each call in modern JavaScript, but this isn't universally understood and older codebases may still have the anti-pattern. More dangerously, mutable defaults in objects: function foo(config = {}) gets worse when nested properties are mutated. Use structuredClone or explicit defaults. Promise error handling gaps. Every Promise chain needs a catch, and every async function needs error handling. Unhandled promise rejections crash Node.js processes in versions prior to 15. I set --unhandled-rejections=throw in production environment configurations to force the issue. Event listener cleanup. In single-page applications, components mount and unmount without page reloads. Event listeners attached to window, document, or global stores that aren't cleaned up cause memory leaks. I check for useEffect cleanup functions in React and equivalent lifecycle hooks in other frameworks. Every addition needs a removal.
When Checklists Fail
A checklist is a safety net, not a substitute for understanding. I've seen teams treat checklist completion as proof of quality, then ship code that worked technically but was unmaintainable. Complex functions with unclear naming, coupled modules with no abstraction boundaries, hardcoded values scattered through the codebase. These don't show up in any automated check. The biggest limitation is that checklists don't scale well across teams. A checklist that works for a five-person team breaks down at twenty because the context switching cost becomes enormous. In larger organizations, I recommend modularizing checklists by role and responsibility. The person writing the API endpoint checks different items than the person configuring the deployment pipeline. Another failure mode is checklist fatigue. When every item becomes a checkbox to tick without thought, the checklist becomes worthless. I review mine quarterly and remove items that haven't caught anything in six months. Stale checklist items are worse than no checklist items because they create false confidence.
If you're starting fresh and want a structured approach, the items above cover the areas that matter. If you already have a checklist, audit it against these categories and fill the gaps. The goal isn't a comprehensive list, it's catching the things you actually forget.