Machine Learning Doesn't Need Another Tutorial
Everyone wants the ultimate guide. The page that covers every model, every loss function, every trick in the book. I have been building these systems since they were called neural nets and required a physics PhD to even glance at. The truth is simpler than any listicle will tell you. Most people skip the part where models actually break. They watch a video showing MNIST accuracy hitting 99% and then try to deploy something similar on messy real-world data. It fails within the hour. That failure point is where learning actually happens.
Where to Start With Ultimate Machine Learning Examples
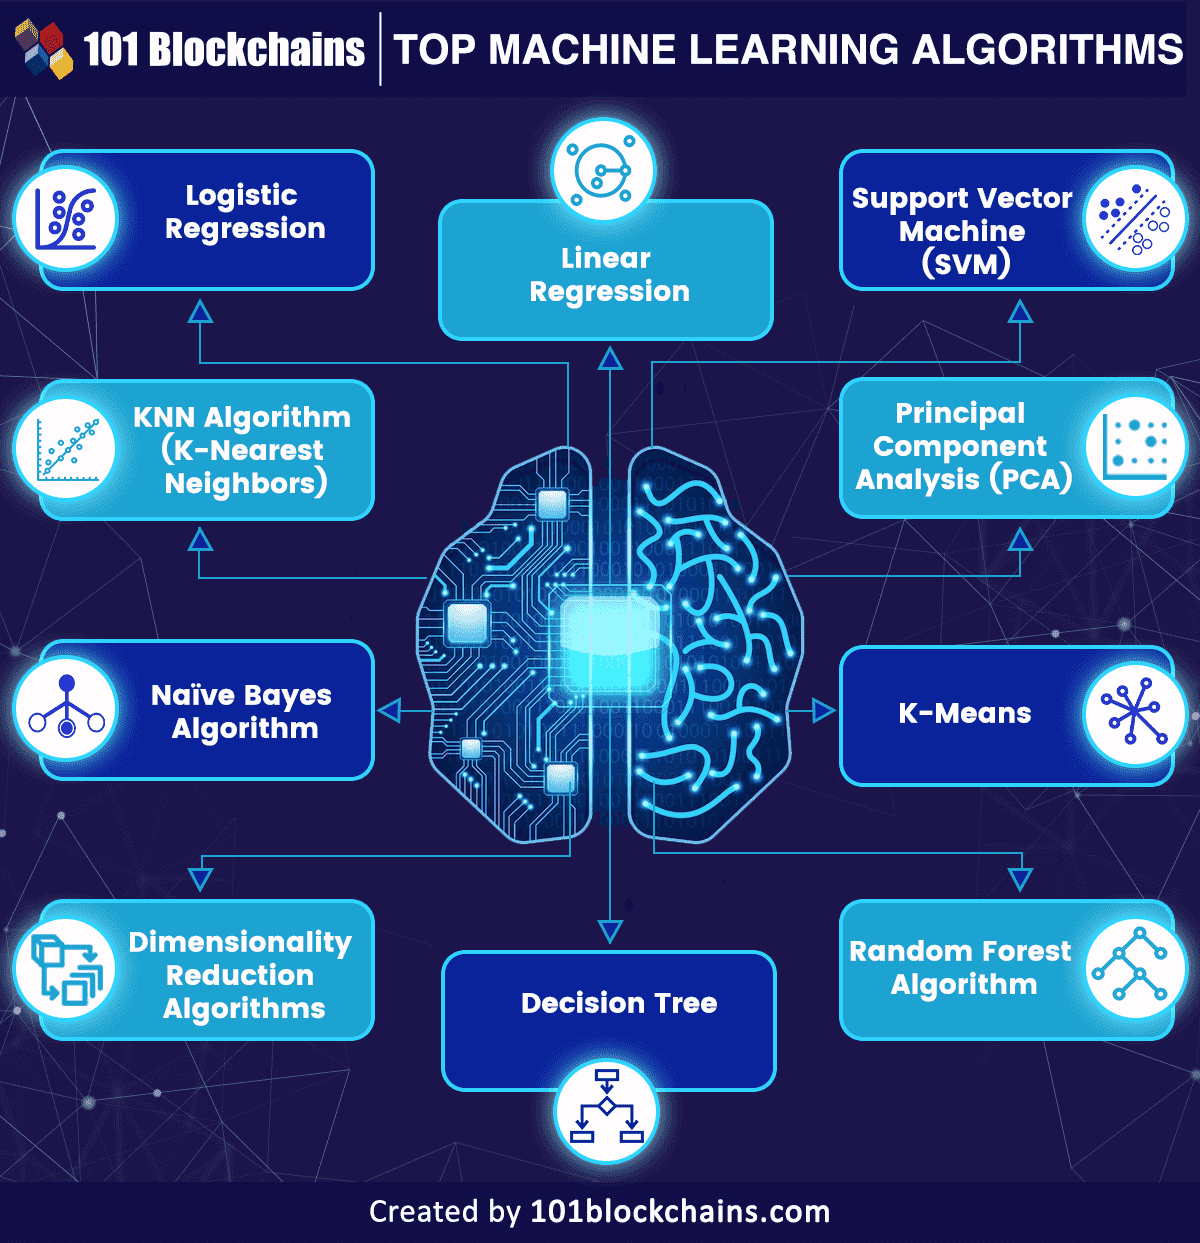
Pick a problem that annoys you personally. Not one from a Kaggle leaderboard. Something like the time my team needed to predict equipment failures from vibration sensors. Twenty thousand timestamps per minute across twelve machines. The dataset was not clean. Sensors drifted. Maintenance logs were missing for three months in 2019. The official label column had gaps that looked random but were actually caused by a subcontractor forgetting to upload PDF reports to the server. The workaround was ugly but effective. We stopped treating missing maintenance records as random missingness and started treating them as a signal in themselves. Machines that went quiet in the logs tended to be the ones scheduled for downtime, not the ones breaking unexpectedly. Adding a binary flag for "no recent maintenance record" actually improved our false-negative rate by eighteen percent. That is the kind of detail no pre-packaged example will show you because nobody publishes their data-cleaning disasters. If you are starting out, download the California Housing dataset from sklearn and try predicting median home prices. Train a simple linear regression. Check the residuals. Now train a random forest. Compare the feature importances. You will notice the linear model assigns weight to distance to employment centers while the tree splits on room count and age. Neither is wrong. They are capturing different relationships in the same noise.
Counter-Intuitive Things I Wish Someone Told Me Earlier
More data rarely fixes a bad model architecture. I spent six weeks collecting and cleaning two million rows for a churn prediction task. The baseline logistic regression was already overfitting on five features. Adding more samples just made overfitting more confident. We ended up dropping to forty thousand rows after aggressive stratified sampling and regularization. The test AUC went up by 0.03. Not a typo. Quality of representation matters more than raw volume after a certain threshold. Another thing: gradient descent is not the bottleneck. Regularization and feature engineering usually are. I watched a team spend three months tuning Adam learning rates on a transformer while their input pipeline was reading CSV files from disk synchronously. Training throughput was eight examples per second. The GPU sat at twelve percent utilization. Moving the data to Parquet with byte-range prefetching got us to four hundred examples per second. Same model. Same hyperparameters. Forty-eight times faster because we stopped treating I/O as invisible. You should also know when to stop. There is no shame in a model that hits 87% accuracy and serves the business need. I have seen engineers chase 91% for months, adding complexity, custom ops, ensemble stacks. The inference cost tripled. The deployment failed twice. The 87% model that shipped on time paid for itself in three weeks. Perfection is the enemy of production.
Get the Full Details
Specific Pitfalls That Will Waste Your Time
Temporal leakage is the quiet killer. If you split your data randomly instead of chronologically, your validation set will contain samples from the future relative to your training set. A customer who canceled in March gets mixed into training alongside customers from January. The model learns patterns that only exist because of the split order. When you deploy, those patterns vanish. Always sort by timestamp before splitting. Use TimeSeriesSplit from scikit-learn if you want an automated approach. Another common mistake: evaluating classification metrics on imbalanced data without weighting. I built a fraud detector where fraudulent transactions were 0.7% of the dataset. The model learned to predict everything as legitimate and achieved 99.3% accuracy. Zero fraud caught. Switch to precision-recall curves and optimize for average precision instead of ROC AUC. The difference is not subtle. One metric rewards laziness. The other forces the model to actually find the rare cases.
When Machine Learning Is the Wrong Tool
Sometimes the answer is not a model. It is a heuristic. A rule-based system. A dashboard. I had a request to predict customer support ticket priority using NLP on ten thousand messages. The rules were simple: contains "urgent" equals high priority, contains account ID equals billing team, mentions API equals technical support. We built the classifier, got 94% accuracy, and then realized the heuristics hit 97% in half the code and took fifteen minutes to implement. The model added latency, debugging overhead, and a maintenance burden for marginal gain. Use ML when the pattern is complex enough that explicit rules would require hundreds of conditions. Do not use it when domain experts can articulate the decision logic in a paragraph. The latter case is not a failure of ML. It is a success of engineering judgment.
Practical Steps for Your First Real Project
Write the evaluation script before you write any training code. Define what success looks like in business terms, not just accuracy numbers. If your model reduces support tickets by twenty percent, calculate the dollar value. If it increases click-through rate by two points, model the revenue impact. Then build a baseline that achieves zero value. A model that predicts the mean for regression or the majority class for classification. Your actual model must beat this baseline by a comfortable margin, not by a hair. Keep a log of every experiment. Not just the successful ones. The five-hour runs that produced garbage are worth documenting because they prevent someone else from repeating them. Use Weights & Biases, MLflow, or a simple CSV. I prefer a CSV with columns for hypothesis, changes made, result, and whether it was a dead end. Dead ends are data too. When your model is ready for production, deploy it alongside the old system. Shadow mode first. Route traffic to both. Compare predictions without showing the new ones to users. Catch regressions before they become incidents. Then flip the switch for a small percentage of requests. Ten percent. Monitor error rates, latency, and the metric that actually matters for your use case. Gradually increase to full rollout over three to five days. Things break on Tuesdays for reasons you cannot predict.
There is no ultimate list of examples because the field moves faster than any compilation can track. What works today will feel outdated in eighteen months. The skills that persist are debugging data pipelines, understanding what your metrics are actually measuring, and knowing when to stop optimizing. Build the thing. Ship it. Learn what broke. Repeat.