What Uniform Distribution Actually Looks Like When You're Using It
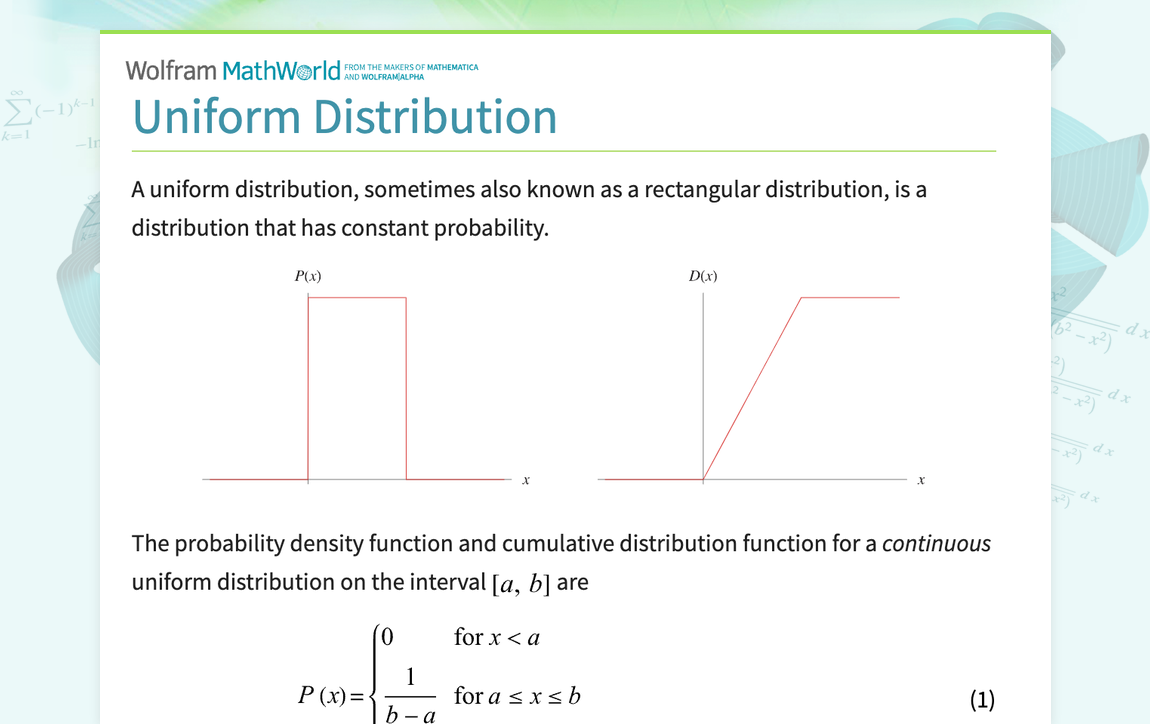
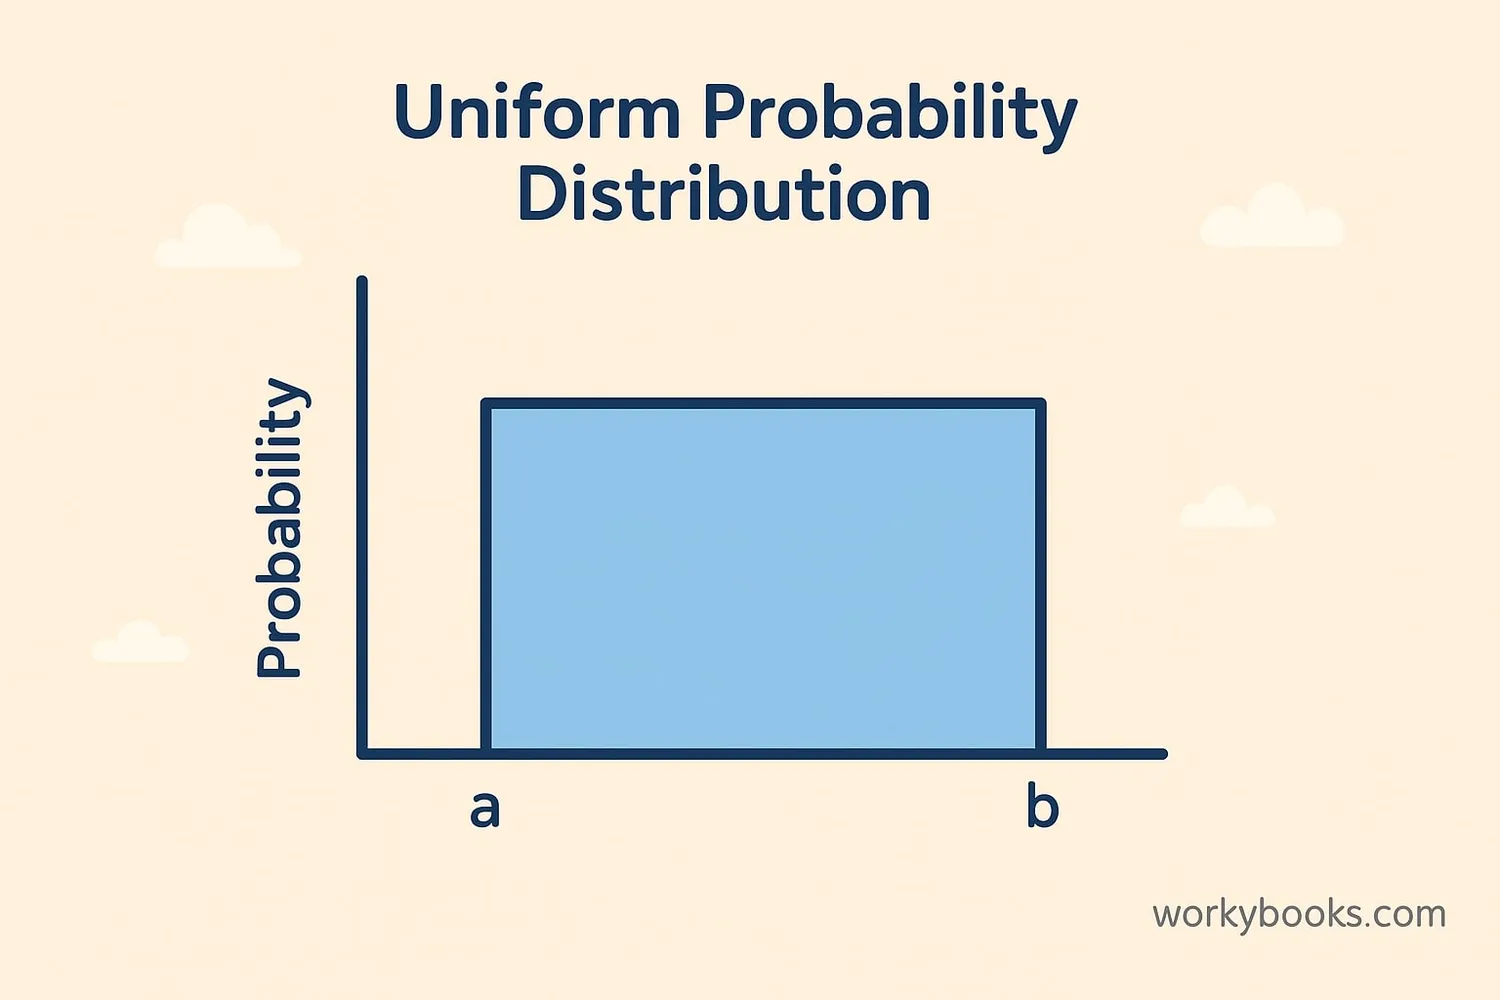
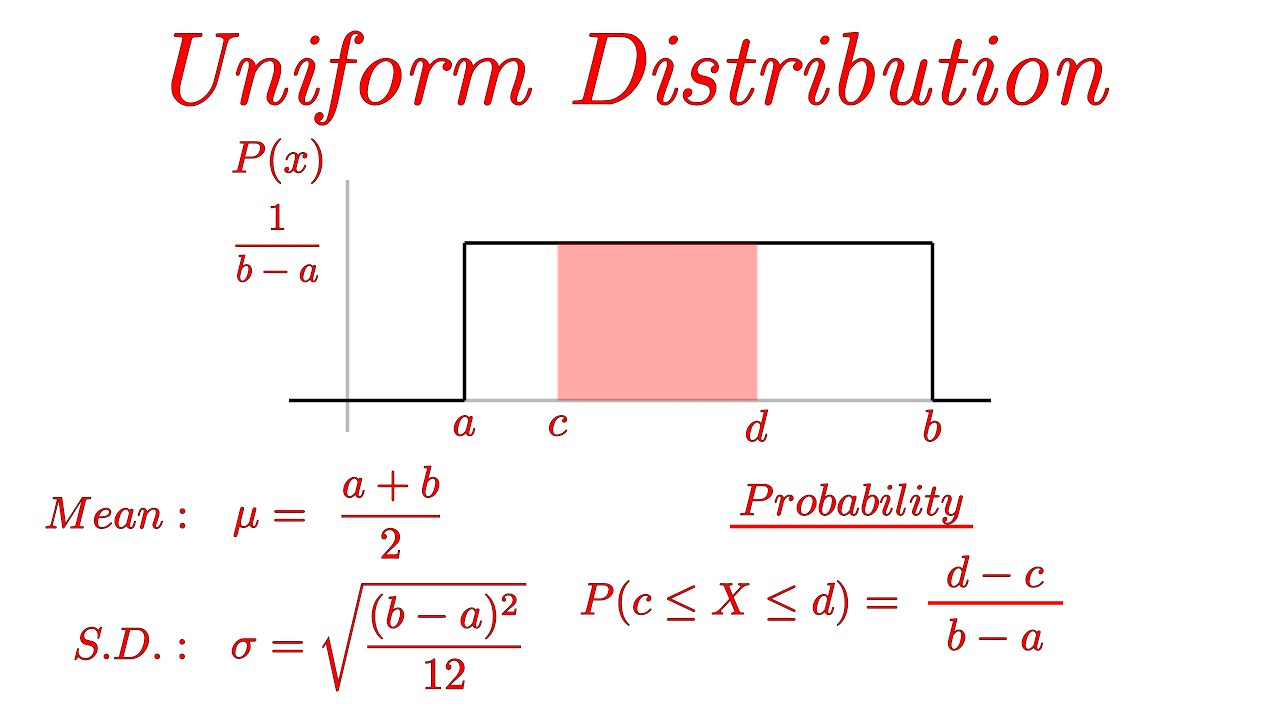
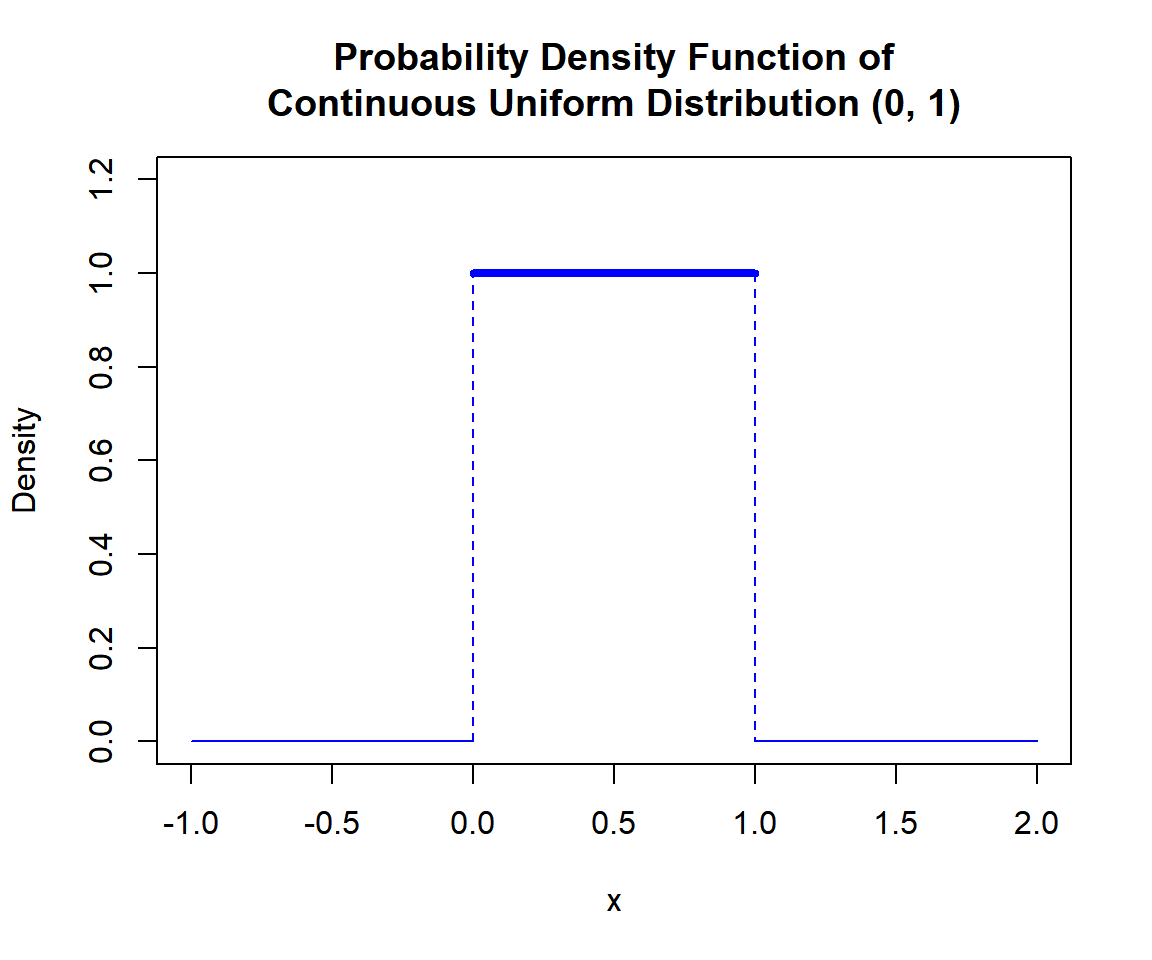
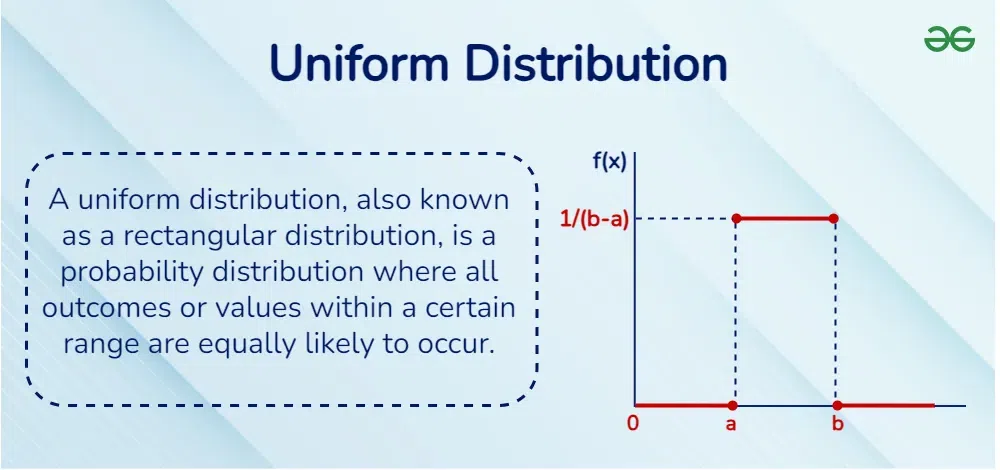
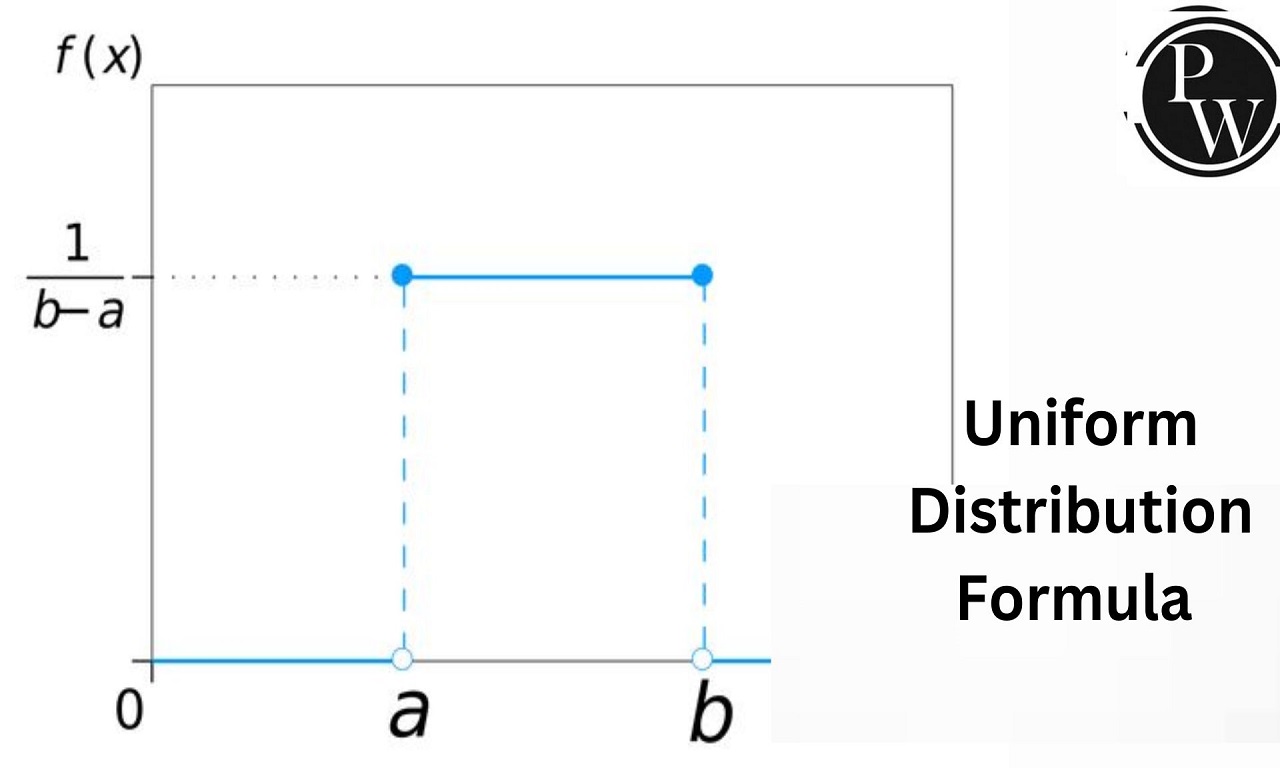
Most people learn about the uniform distribution in a stats class and then never think about it again until they need random numbers that aren't skewed. It is straightforward on paper. The probability density is constant between two bounds, a and b. Everything outside that range has zero probability. The mean is (a+b)/2 and the variance is (b-a)^2/12. That is the whole thing. The problem is that the textbook version assumes you care about theory, and most of the people actually using this in practice do not. I have spent years working with Monte Carlo simulations and A/B testing infrastructure, and the uniform distribution shows up constantly. Not because it is particularly exciting, but because it is the baseline. When someone says "generate a random number between 1 and 100," they are asking for a discrete uniform distribution. When someone says "pick a value evenly across this range," they mean the continuous version. The confusion between these two costs people time. A lot of time. Here is what actually happens when you try to use a uniform distribution in a production system. You call a random number generator, you multiply by a range, you shift by an offset. It works fine until you realize that the generator's period is shorter than your sample space. Then you get cycles. I once ran a simulation where I needed about 50 million unique uniform samples for a parameter sweep. I was using a linear congruential generator with a modulus of 2^31. The samples started repeating after roughly 2 billion calls, which seemed fine. But the particular values I was seeding it with caused a correlation spike around iteration 847,000. The output wasn't uniform anymore. It was subtly, dangerously non-uniform. I switched to a Mersenne Twister and the problem went away entirely. The take-away is that the algorithm generating your uniform numbers matters more than you think.
How to Actually Implement It Correctly
Start by deciding whether you need discrete or continuous. This distinction is not optional. If you are assigning people to test groups and you need them to land on integer IDs, you need discrete. If you are sampling a temperature value from a range for a physics simulation, you need continuous. Mixing them up introduces bias that compounds over thousands of iterations. For continuous uniform distribution on [a, b], the standard approach is to generate a value from U(0,1) and scale it. In code, that looks like a * r + b where r is your base random float and a and b define the bounds. Most languages have a built-in function that does exactly this. Python's random.uniform() does it. NumPy's np.random.uniform() does it with vectorization if you need arrays. R's runif() does it with proper handling of edge cases. Pick the tool that matches your stack and move on. For discrete uniform distribution over integers from a to b inclusive, you generate a uniform float in [0,1), multiply by (b-a+1), and floor it. Then add a. The +1 is critical because off-by-one errors in discrete uniforms are the most common bug I see. I have seen it in code review a hundred times. Someone writes rand() % n and wonders why their distribution is slightly uneven when n does not divide the generator's modulus evenly. This is called modulus bias and it is a real thing. If you are generating numbers in a range that is not a power of two, and you are using a modulo operation, your distribution will not actually be uniform. The fix is rejection sampling. Generate a random number, reject it if it falls outside the largest multiple of n that fits in your generator's range, and map the rest uniformly. This usually costs you less than 50 percent extra calls in the worst case, and it makes the output actually uniform.
Where Uniform Distribution Fails Completely
The uniform distribution assumes equal likelihood across the entire range. This is often wrong. In real systems, values cluster. Response times follow exponential or lognormal distributions. User behavior follows power laws. If you model something as uniform when it is actually skewed, your confidence intervals will be wrong and your predictions will be off. I once built a load testing tool that assumed request latency was uniformly distributed between 50ms and 500ms. The actual latency had a long right tail. The tool underestimated p99 latency by a factor of three because it had no mechanism to generate those extreme values. It produced a perfectly uniform distribution and a completely wrong model of reality. Another failure mode is when you need correlation between variables. A uniform marginal distribution does not imply independence. If you generate two independent uniform variables and combine them, you get a uniform distribution over a square. But if the real phenomenon has a structure, like a circular dependency or a conditional constraint, plain uniform sampling misses it entirely. In those cases you need something like importance sampling or a Markov chain Monte Carlo method that respects the structure. The uniform distribution is also computationally expensive to generate at scale if you need cryptographically secure randomness. The default generators in most languages are fast but predictable. They are fine for simulations and games. They are not fine for security. If you need secure uniform samples, you have to pull from the operating system's entropy pool, which is slower and has limited throughput. On a typical server, you can expect maybe ten thousand secure random integers per second before the pool drains. If your application needs more, you need to batch or pre-generate.
Get the Full Details
Practical Edge Case: Reproducible Uniform Sampling
One issue that comes up constantly is reproducibility. You need your uniform samples to be identical across runs for debugging or regression testing. Setting the seed works for simple cases. But if you are running parallel threads and each thread draws from the same generator without proper synchronization, you get overlapping sequences. I encountered this in a distributed simulation where four processes were each supposed to generate independent uniform samples for a parameter grid. Without explicit seed management, the sequences overlapped significantly because the fork happened before the generator advanced far enough. The workaround was to use a counter-based generator like PCG or Xorshift128+, where each thread gets its own independent stream derived from the master seed. This is not a uniform distribution problem per se, but it is a practical problem that arises whenever you use uniform sampling in a parallel context. Counter-based generators give you provably independent streams with no overlap risk, and they are fast enough that the performance cost is negligible. If your data is bounded but you expect most values near the center, use a triangular or beta distribution instead. If your values span orders of magnitude, use a log-uniform distribution. If you are doing Bayesian inference and need a prior over a continuous range, a flat uniform prior is technically uninformative, but it can cause problems with improper posteriors if your model has symmetries. In that case a weakly informative normal or half-normal prior is safer. The uniform distribution is a valid choice in specific situations, and it is the wrong choice in many more. The core principle is simple. Use it when you genuinely have no reason to believe any sub-range is more likely than any other. If you have any information at all, encode it in the distribution you choose. A uniform prior is a statement of ignorance, and sometimes ignorance is the honest answer. Often it is not.
For implementation, Python's numpy.random.Generator.uniform() handles the continuous case well. For discrete with no modulus bias, use numpy.random.Generator.integers(a, b+1, endpoint=True). For cryptographic use, use os.urandom() or the secrets module. For parallel work, use a counter-based generator. These choices are not theoretical. They are the differences between correct output and output that looks correct until it is too late.