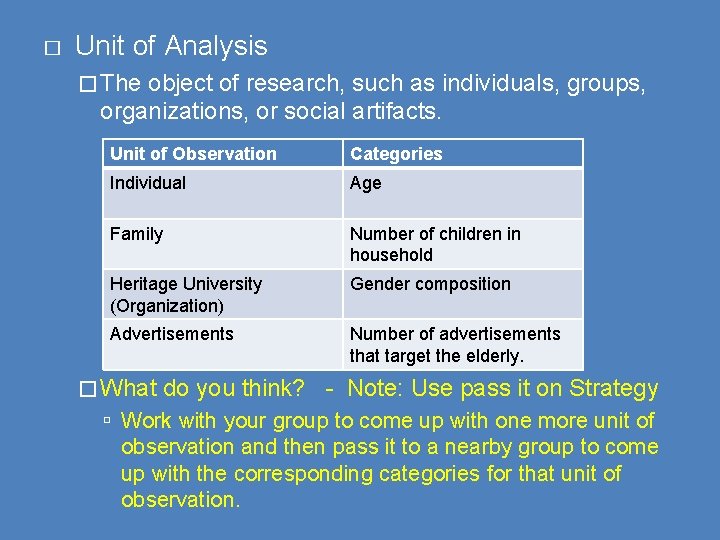
Unit Of Analysis Statistics
The first thing most people get wrong about Unit Of Analysis Statistics is that it's just a definition problem. It's not. It's a design decision that cascades through your entire study. Pick the wrong unit and your standard errors are inflated, your conclusions are wrong, and you won't know it until after you've written three drafts of the results section. Here's how I determine the unit before touching any data. Step one: map the hierarchy. If you're looking at employee satisfaction across hospital departments, you have employees within departments within hospitals. The unit of analysis could be any of those three levels, but only one makes sense for your question. Step two: write the question in the form "How does X affect Y at the level of ______?" If you can't fill in that blank with a single noun, you haven't defined your unit yet. Step three: check your sampling frame against that noun. If your data was collected at one level but your analysis targets another, you're already in trouble. I've seen this play out repeatedly. A research team was studying academic performance across schools in a state district. They collected test scores from 12,000 students across 85 schools. The natural question seemed to be about student-level outcomes. But when they ran their regression at the student level, the R-squared was barely above zero and the residuals showed massive clustering. The school-level variance was so large that any student-level fixed effect was essentially noise against the school effect. They switched to a multilevel model with schools as the grouping variable and the results became interpretable. The unit of analysis hadn't changed—the students were still the observational units—but the analytical framework had to account for the hierarchy. This is the difference between knowing what a unit is and actually using it correctly.
What The Unit Actually Determines
It determines your sample size. Not the number of rows in your dataset. The number of independent observations. When people report N equals 12,000 for a student-level analysis with 85 schools, they're technically correct but statistically misleading. The effective sample size for school-level inference is closer to 85, not 12,000. This is why cluster-robust standard errors or multilevel models aren't optional extras—they're the baseline requirement whenever your data has any structure. It also determines what kind of inference you're making. An ecological study uses aggregates as its unit. You might compare crime rates across cities and correlate them with poverty rates. The unit here is the city, not the individual person. The ecological fallacy happens when you assume that because city-level poverty correlates with city-level crime, poor individuals are more likely to commit crimes. That correlation doesn't hold at the individual level, and it often holds in the opposite direction. I've seen this mistake in published papers in peer-reviewed journals, so don't feel bad if it seems subtle. The unit also controls your generalizability claims. If you study organizations, you can make claims about organizations. You cannot make claims about the people inside those organizations unless you specifically designed the study for that level. This sounds obvious until someone publishes a paper about individual behavior based on organizational-level data and gets it accepted without anyone catching the mismatch.
Common Units And Their Problems
Individual person. The default. Works when you have a random sample of individuals and no clustering. This is rare in practice. Most individual-level data comes from schools, workplaces, neighborhoods, or hospitals. Even "individual" surveys often have built-in clustering through geographic or organizational sorting. Group or organization. Useful for institutional analysis. The problem is that groups are hard to sample. You rarely get a clean frame of all organizations in a population. Most group-level studies end up using convenience samples of organizations, which limits external validity significantly. I once worked on a project where we needed to study school districts across a state. We got a list of 200 districts from the state education department, but only 47 agreed to participate. The nonresponding districts were systematically larger and more urban. Our findings about curriculum policies couldn't be generalized beyond the responding districts, and everyone on the project knew it but the grant report still claimed broader applicability. That's the unit of analysis problem wearing a different hat. Time period. Panel data and time series both treat time as a unit in different ways. With panel data, you have repeated observations of the same units across time. The unit of analysis is still the individual or organization, but time becomes a dimension. With pure time series, the unit is the time period itself. The problem here is autocorrelation. Every observation is correlated with the ones before and after it, which violates the independence assumption that most statistical methods require. Newey-West standard errors or ARIMA models handle this, but they add complexity that many researchers skip, producing results that look clean but are actually invalid.
Get the Full Details

Events or transactions. Common in criminology, economics, and marketing. Each event is an observation. The issue is that events cluster in time and space. A spike in fraud transactions on a particular day isn't independent of the transactions before and after it. You need event-level clustering or survival analysis depending on the question. Using ordinary regression on clustered event data gives you confidence intervals that are too narrow and p-values that are too small.
Edge Case: When The Unit Shifts Mid-Study
Here's a specific problem I ran into that took me three weeks to untangle. I was analyzing organizational compliance data from a healthcare network. We had 340 clinics, each with multiple providers. The original study design treated each provider as the unit of analysis, with clinic as a control variable. About halfway through, I realized that the outcome measure—adherence to a new billing protocol—was actually implemented at the clinic level, not the provider level. Individual providers didn't choose whether to adopt the protocol. The clinic administrator did. So the exposure was at the clinic level, but the outcome was measured at the provider level. Running the analysis at the provider level with clinic as a covariate was backwards. The treatment effect was being attributed to the wrong unit. I switched to a clinic-level analysis, aggregating provider outcomes to the clinic level first. This meant my N dropped from roughly 2,800 providers to 340 clinics. The standard errors inflated because the effective sample size shrank, and two effects that had looked significant at the provider level lost significance. The conclusion flipped entirely. If I hadn't caught this, the paper would have claimed that certain provider characteristics predicted compliance when the real driver was clinic-level policy adoption. The workaround was straightforward but time-consuming. I restructured the dataset to one row per clinic, aggregated all provider outcomes within clinics, and reran everything. The key insight was that the unit of analysis isn't whatever level your data happens to be at. It's whatever level your causal mechanism operates at. In this case, the mechanism was policy implementation at the clinic, so the clinic had to be the unit even though the data lived at the provider level.
The Nonresponse Problem That Nobody Talks About
When you define your unit as an organization, nonresponse at the unit level destroys your inference. If 40% of the organizations in your sample don't respond, and nonresponse is related to the outcome variable, your results are biased. This is worse than individual-level nonresponse because organizational nonresponse is usually systematic. Small organizations don't respond as much as large ones. Struggling organizations don't respond as much as successful ones. You can't fix this with weighting alone because you don't have the denominator—you don't know the full population of organizations to begin with. The best you can do is document the nonresponse pattern and limit your claims to the responding subset. There's also the problem of artificial aggregation. When you aggregate individual data to a group level, you lose all the within-group variation. A clinic average of provider compliance tells you nothing about whether compliance is evenly distributed or concentrated among a few providers. Both scenarios produce the same clinic-level mean. If your research question depends on the distribution within groups, aggregation obliterates that information. Multilevel models preserve both levels, but they require larger samples at every level to estimate properly. With fewer than five groups per level, multilevel models become unstable and the estimates are unreliable.
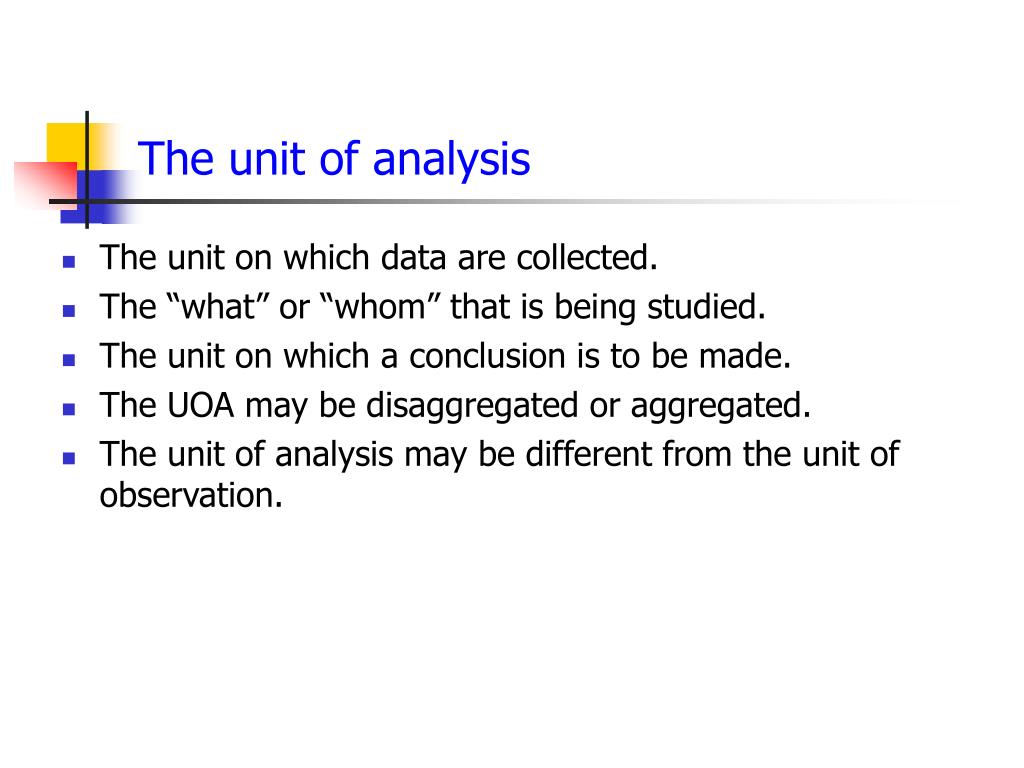
Practical Checklist Before You Analyze
Write down your unit of analysis on a separate line in your methods section. Not implied, not assumed. Written. If you can't state it in one sentence, you don't have one yet. Check whether your sampling unit matches your analysis unit. If they differ, explain the adjustment method. Check whether your causal mechanism operates at the same level as your unit of analysis. If it doesn't, either change the unit or change the mechanism description. Check your sample size at the unit level, not at the observation level. If you have 500 observations clustered within 20 groups, you have 20 units of analysis, not 500. The field of Unit Of Analysis Statistics isn't complicated. It's just ignored until it's too late. The people who get it right don't do it through fancy methods. They do it by spending ten minutes thinking about what level their question actually lives at before they open any software.