What Actually Matters When Porting Unix Systems to New Hardware
Unix has been running on everything from embedded routers to mainframes for decades. The problem isn't writing the kernel — it's making it behave predictably when the underlying silicon doesn't follow the usual x86 assumptions. Cache coherency, interrupt routing, and memory ordering models are where things fall apart most often. I spent about three weeks last year debugging a silent data corruption issue on an ARM64 embedded board running a customized BSD-derived system. The corruption only showed up under heavy sequential I/O workloads, and only when the device was thermal throttling. The root cause turned out to be a missing hardware memory barrier in a custom DMA driver. Something that would have been caught immediately in any x86 environment because x86's strong memory model hides those mistakes from you.
Understanding Unix Systems For Modern Architectures
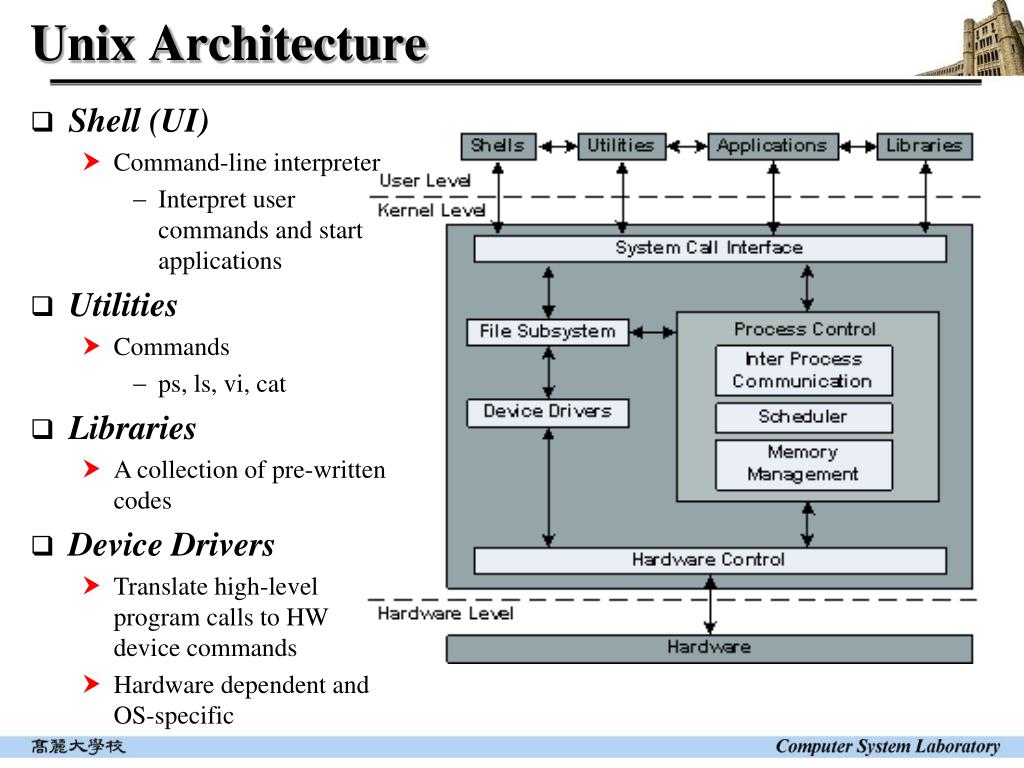
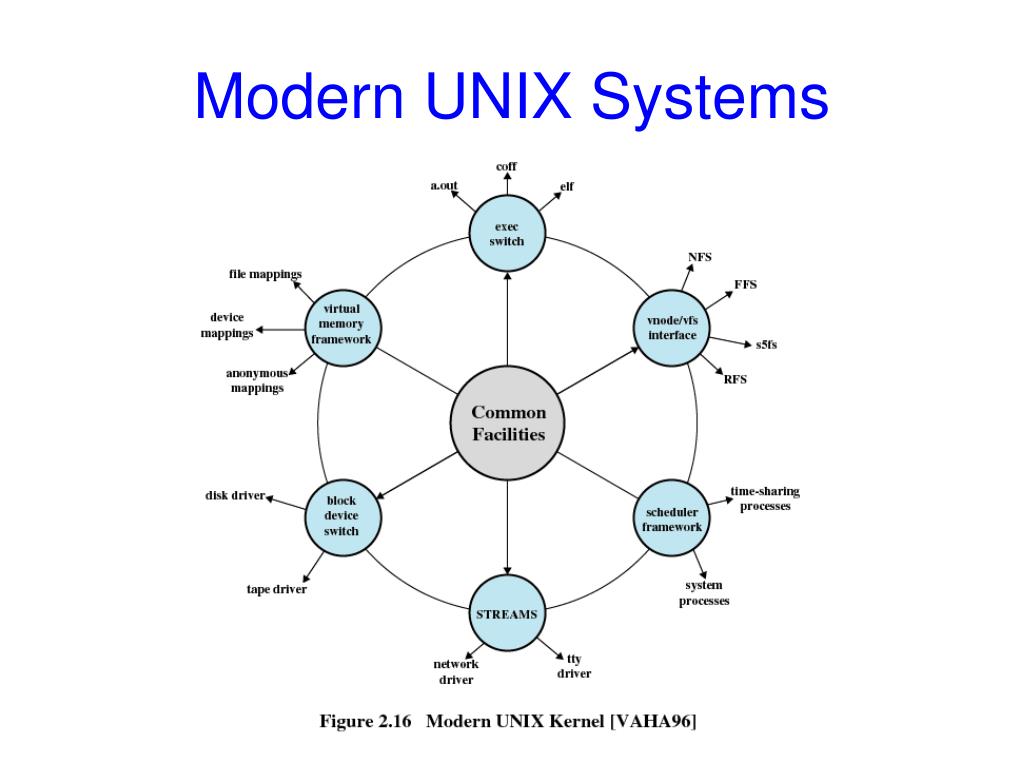
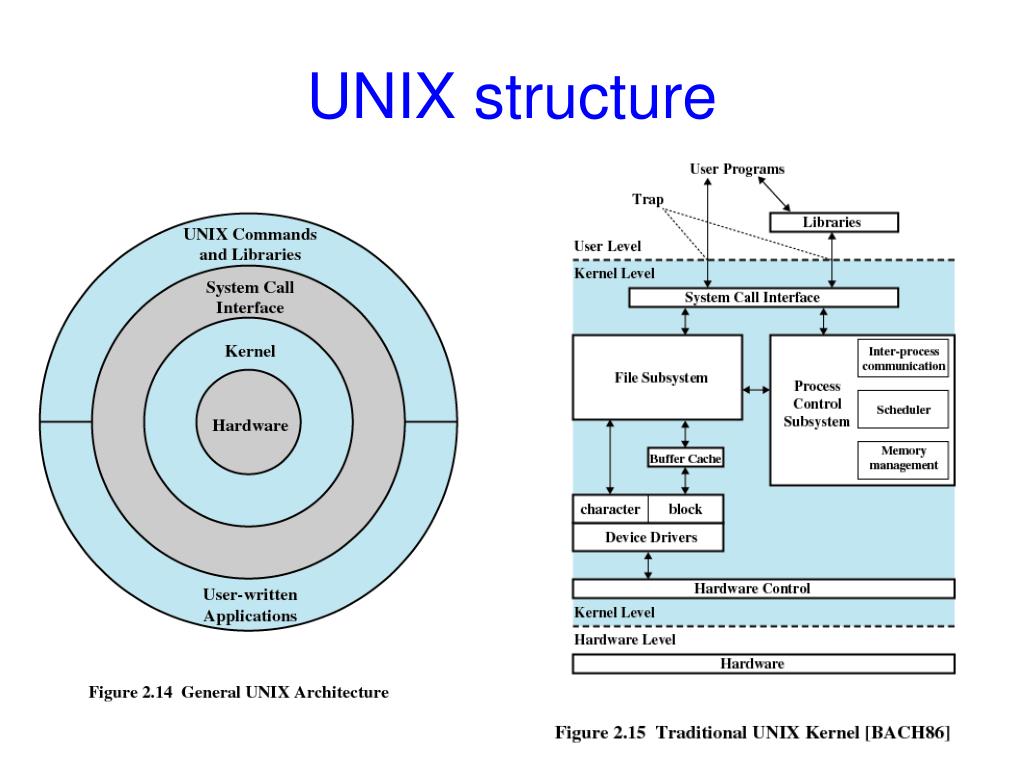
This topic isn't about learning a specific operating system distribution. It's about understanding how traditional Unix abstractions — processes, file descriptors, signals, memory mapping — translate onto hardware that doesn't look like a 1970s PDP-11. Modern architectures introduce variable cache line sizes, non-uniform memory access patterns, different exception handling mechanisms, and in some cases, completely different privilege levels that don't map cleanly onto the traditional user/kernel split Unix expects. The POSIX standard remains the anchor point. Almost everything you do should trace back to what POSIX guarantees and, just as importantly, what it deliberately leaves undefined. That's where porting nightmares begin.
Setting Up a Development Environment That Doesn't Lie to You
Don't develop directly on the target hardware unless you have to. Cross-compilation toolchains are fine for initial builds, but they hide runtime problems until the binary lands on actual silicon. I use QEMU with the appropriate machine emulation for early testing, then move to real hardware as soon as the boot sequence completes without panics. QEMU catches about 80 percent of the obvious issues. The other 20 percent are the ones that matter. Your toolchain needs to match the target's endianness, word size, and ABI correctly. I've seen build systems silently default to the host's configuration instead of the target's. Check your cross-compiler specs output before trusting any compilation result. Run arm-linux-gnueabihf-gcc -dumpspecs or whatever your target triplet is, and verify the SYSROOT and target flags actually point where you think they point.
Get the Full Details

Memory Management Across Different Architecture Models
x86 uses a four-level page table hierarchy with hardware-enforced protection. ARM64 uses up to four levels too, but the physical address size can vary significantly between implementations — 48 bits, 52 bits, sometimes more on server-class silicon. RISC-V supports multiple page sizes natively in the MMU, and if you assume a fixed 4KB page everywhere, you will miss performance opportunities and in some cases break on devices that only support larger pages. Non-temporal stores and stream processors need different treatment than cache-coherent CPUs. On architectures with weak memory ordering, explicit barriers are required around shared data structures. The Linux kernel's asm-generic/barriers.h gives you a starting reference, but every BSD-derived system implements this differently. Read your target's source for __atomic builtins and understand what memory ordering each one translates to on the actual hardware. One practical note: if you're working with an architecture that has NUMA characteristics, the OS's page allocation policy matters more than people admit. A default contiguous allocation across all nodes can fragment memory on real hardware in ways QEMU never reproduces.
Interrupt Handling and Real-Time Constraints
Modern SoCs route interrupts through GICs or APICs with complex affinity and priority schemes. Unix traditionally treats interrupts as fast software interrupts with minimal state. On platforms with hundreds of interrupt sources competing for a handful of CPU cores, that model breaks under load. CPU pinning becomes necessary, and IRQ affinity masks need explicit configuration rather than relying on the kernel's auto-balance. I worked on a project where the default interrupt distribution on an 8-core ARM platform caused periodic latency spikes of up to 40 milliseconds in a real-time audio processing pipeline. The system was functionally correct — no dropped packets, no data loss — but the jitter made it unusable for the actual application. The fix involved pinning the audio DMA completion interrupts to a dedicated core, disabling IRQ balancing for that interrupt range, and adjusting the scheduler's SMT handling on that specific CPU. That took about two days of profiling with ftrace and perf.
Filesystem and I/O Considerations
DMA alignment requirements vary significantly between architectures. x86 is forgiving — most devices accept arbitrary alignment. On many embedded ARM and RISC-V platforms, unaligned DMA transfers trigger bus errors or silently corrupt adjacent memory. Any subsystem that performs DMA — network stacks, storage drivers, audio interfaces — needs strict alignment verification during initialization. Check your buffer boundaries against ARCH_DMA_MINALIGN or the architecture-specific equivalent before sending buffers to hardware. Suspiciously slow sequential read performance on a new platform is almost always a block layer or driver issue, not an application problem. Before rewriting your I/O path, verify the queue depth settings, check whether writeback caching is enabled, and confirm the block device isn't falling back to a polling driver because an interrupt configuration failed silently during boot.

Common Pitfalls That Wasted My Time
Size-of-pointer assumptions. Code that casts file offsets to int instead of off_t works on 32-bit systems and breaks on 64-bit targets. This is still one of the most common bugs I see in ported codebases, and it causes silent data truncation rather than compilation errors. Endianness mismatches in network protocols. If you're reading raw binary protocol frames, byte order conversions must happen explicitly. The compiler won't save you. I once debugged a protocol implementation for six hours before realizing the firmware on the target chip was big-endian while the host processor was little-endian, and the byte-swap macro had been conditionally compiled out by a header include path error. Thread stack size defaults. Some architectures have much smaller default thread stacks than x86. Recursive functions or deeply nested signal handlers can overflow stacks that seem adequate on desktop systems. Check pthread_attr_getstacksize defaults for your target and adjust for known-deep call paths.
What This Approach Doesn't Solve
Unix Systems For Modern Architectures won't help if your hardware vendor provides incomplete or undocumented silicon specifications. Driver development on poorly documented ARM SoCs from lesser-known manufacturers is essentially reverse engineering with deadlines. There is no workaround for that except patience, logic analyzers, and reading other people's kernel patches for similar chips. This methodology also doesn't compensate for inadequate testing coverage. Cross-compiling and booting successfully is not the same as the system being correct under real workloads. Stress testing on actual hardware with temperature variation, voltage fluctuation, and sustained load is mandatory for any deployment that can't afford intermittent failures. I usually run memtest86+ equivalents, stress-ng with architecture-specific threads, and custom I/O loops for at least 24 hours before considering a build stable. If you need faster iteration cycles and can accept virtualized hardware behavior, using KVM with custom CPU configuration passes is a reasonable alternative to physical hardware testing for many workloads. The trade-off is that KVM won't catch hardware-specific edge cases involving PCIe enumeration, power management states, or peripheral controller quirks.