Set Theory and the Symbol You Keep Forgetting
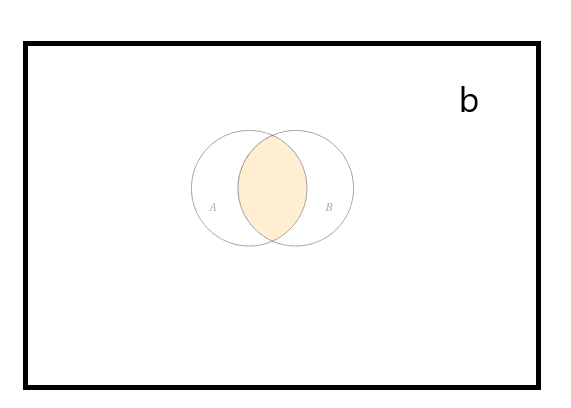
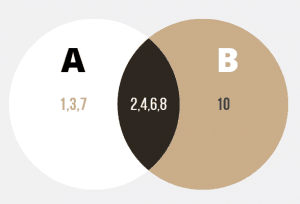
The intersection operator in set theory looks like an upside-down U and goes by a dozen different names depending on who you ask. Most people just call it the upside down U in math context, which works fine until you try explaining it to someone who actually knows what it means. The symbol itself is straightforward: it shows you the elements that two or more sets share in common. That is it. The confusion comes from how quickly it gets glossed over in introductory courses and then picked back up later when people are supposed to already know how to use it fluently. I spend most of my time dealing with probability and discrete structures, so I am constantly running intersections through my head without even thinking about the notation. Here is the practical way to handle it. You take two sets, A and B, and write A B. Every element that appears in both sets survives. Everything else gets filtered out. If A = {1, 2, 3, 4} and B = {3, 4, 5, 6}, then A B = {3, 4}. That is the entire operation. It is not conditional. It does not change based on what comes next in a problem unless you are nesting intersections with unions, and even then the logic stays the same. The part that trips people up is associativity. Intersection is associative, meaning (A B) C gives you the same result as A (B C). You can chain them in any order without reorganizing the expression. I learned this the hard way during a graduate qualifiers exam when I was given three overlapping intervals and asked to find their common region. I drew it out on scrap paper first instead of trusting my memory, and that saved me. The intervals were [0, 5], [2, 7], and [3, 9]. The intersection came out to [3, 5]. If I had tried to do that in my head while under time pressure, I would have written [2, 5] and lost points for the lower bound being wrong. Always sketch the overlap when intervals are involved.
Another thing that nobody explains well is how intersection behaves with empty sets and universal sets. The intersection of any set with the empty set is always the empty set. That sounds obvious until you are working with complements and De Morgan's laws and you forget that A A' = . A U, where U is the universal set, just gives you A back. These are the identities you need to memorize because they show up constantly in proofs, and losing track of them mid-argument makes your work look sloppy even when the rest is correct.
Where the Symbol Actually Shows Up
Beyond pure set theory, intersection appears everywhere. In probability, the intersection of two events E and F represents both events occurring simultaneously, written as E F. The probability of that is P(E F), which equals P(E) × P(F) only when the events are independent. When they are not independent, you have to use conditional probability: P(E F) = P(E|F) × P(F). This distinction matters more than students usually realize. I once had a colleague who treated every joint probability as if the events were independent, which led to a model that underestimated overlap by roughly 40 percent in a risk assessment project. We caught it during a peer review because we kept comparing the intersection method against a Monte Carlo simulation, and the numbers diverged badly. In Boolean algebra, intersection maps directly to the AND operation. In computer science, set intersection is a fundamental operation in databases and search indexing. If you are building a search engine that needs to find pages matching multiple query terms, you are essentially computing intersections of term-document inverted indices. The efficiency of that depends heavily on how you represent the sets. Bit vectors work well when your universe is small and fixed. Hash sets scale better when the universe is large but the actual sets are sparse. I switched a colleague's intersection routine from nested loops to hash-based lookups once and cut the runtime from about 30 seconds down to under 200 milliseconds on a dataset with roughly a million elements. The improvement was not magic, it was just doing O(n) lookups instead of O(n²) comparisons. Digital signal processing uses intersection implicitly through convolution kernels, though nobody calls it that. Image processing libraries compute overlaps between masks and regions all the time. If you have ever used a Gaussian blur or a morphological erosion operator, you have seen intersection-like logic at work. The difference is that these operations live in continuous space rather than discrete set space, so the mechanics shift but the underlying idea stays identical.
Get the Full Details
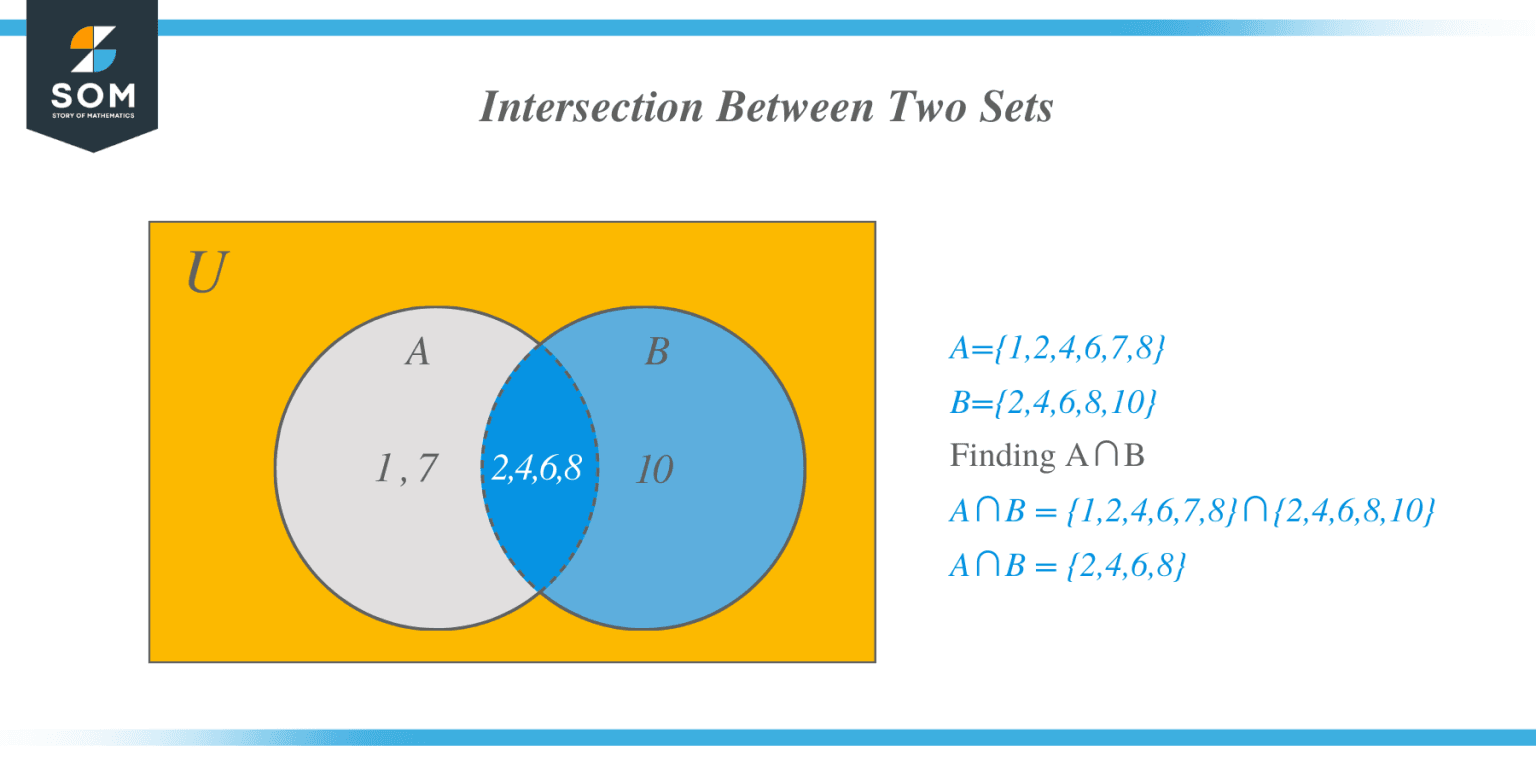
Common Mistakes and How to Avoid Them
The most frequent error is confusing intersection with union. Union uses a capital U and means "either or both." Intersection uses the upside-down U and means "both only." I still see people mixing these up on midterms, and it is usually because the visual similarity between and is doing the damage. Remember that holds water, like a bowl, and the common elements sit inside it. spills outward. That visual trick works because it is grounded in what the symbols actually look like, not some arbitrary mnemonic. Another mistake is assuming that intersection always shrinks a set. That is true for proper subsets but not universally. If A is a subset of B, then A B = A. The result is not smaller than A, it is equal to A. Beginners sometimes write A B = B in this case, which is backwards. The intersection takes the smaller set when one contains the other. This comes up constantly in measure theory and topology, so getting it wrong there makes everything downstream fail. Disjoint sets are a special case that deserves attention. Two sets are disjoint if their intersection is empty. The empty set is disjoint from every set, including itself, which sounds contradictory until you write it out formally: A = for any A. This property is why independence in probability requires P(E F) = P(E)P(F). If two events are disjoint and both have nonzero probability, they cannot be independent. Mutual exclusivity and independence are incompatible unless one of the events is impossible. I have seen this misunderstood in introductory statistics courses, and it causes real problems when people build decision trees or Bayesian networks without checking the underlying assumptions.
Limitations and When to Use Something Else
Intersection as a concept is clean, but it has real limits. It does not generalize well to fuzzy sets without modification. In fuzzy set theory, you replace intersection with a t-norm, usually the minimum or product operator. If you are working with approximate membership values between 0 and 1, the classical intersection definition breaks down. You need to pick a t-norm and stick with it consistently, or your results become ambiguous. I worked on a project where the team mixed minimum-based and product-based intersections in the same pipeline without documenting it, and the final output was internally inconsistent in ways that took three weeks to trace back. Another limitation is computational cost when dealing with massive sets. Naive intersection algorithms scale poorly. If you need to intersect thousands of large sets repeatedly, consider using bit-level parallelism or external sorting approaches. PostgreSQL's jsonb type implements set operations natively and handles intersections efficiently because it stores data in a sorted, duplicate-free format. If you are doing this kind of work outside a database, look into libraries like Google's abseil or Rust's petgraph, which have optimized set intersection routines. Multiset intersection is another edge case. Standard intersection assumes sets with unique elements. If your data contains duplicates, you need multiset intersection, where each element's multiplicity in the result is the minimum of its multiplicities in the input multisets. This shows up in linguistics and bioinformatics but is rarely covered in standard curricula. If your problem involves multisets, the classical intersection definition will give you wrong answers, and you need to switch to the multiset version explicitly.
Quick Reference
Notation: A B reads as "A intersection B." Definition: A B = {x : x A and x B}. Identity elements: A = and A U = A.
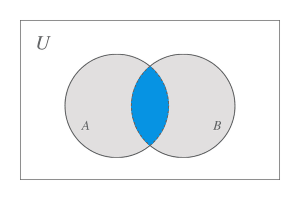
Commutative: A B = B A. Associative: (A B) C = A (B C). Distributive over union: A (B C) = (A B) (A C).
De Morgan's law: (A B)' = A' B'. Probability: P(A B) = P(A|B)P(B). Disjoint condition: A B = if and only if A and B share no elements.
If you are starting out, practice with Venn diagrams until the logic feels automatic, then move to formal proofs. The diagrams help you catch mistakes early, and the proofs teach you to justify every step. Most people skip the formal part and rely on intuition, which works until the problems get abstract enough that intuition fails. I still draw diagrams even now for problems I could solve mentally. It takes ten extra seconds and prevents errors that take hours to debug.