Understanding US Crime Statistics by Demographic Group
Crime data in the United States is collected through several federal programs, with the FBI Uniform Crime Reporting (UCR) program and the National Crime Victimization Survey (NCVS) being the primary sources. When analysts break these numbers down by race and ethnicity, they are working with complex datasets that require careful interpretation. The process involves pulling arrest data, victimization reports, and population estimates, then cross-referencing them to produce meaningful rates per 100,000 residents. The Department of Justice publishes annual crime statistics that include racial breakdowns for arrests and contacts with law enforcement. Getting raw numbers is straightforward — you download the tables fromucr.fbi.gov or use the ICPSR archive at the University of Michigan. The harder part is understanding what the numbers actually represent and what they do not represent. Arrest rates reflect who police arrest, not necessarily who commits crimes. Victimization surveys capture reports from victims and often reveal different patterns than arrest data alone. I spent considerable time working with county-level arrest data a few years back, trying to reconcile FBI supplied race categories with state-level reporting that used different classifications. Some states reported only "white" and "black," others included "Asian" and "Native American" as separate lines, and a handful collapsed everything into three broad buckets. My workaround was to map each state's coding scheme to the Census racial framework and apply conversion weights where the FBI provided ratio tables. This usually took about four to six hours per state for a full multi-year dataset, depending on how clean the original documentation was.
How the Data Collection Actually Works
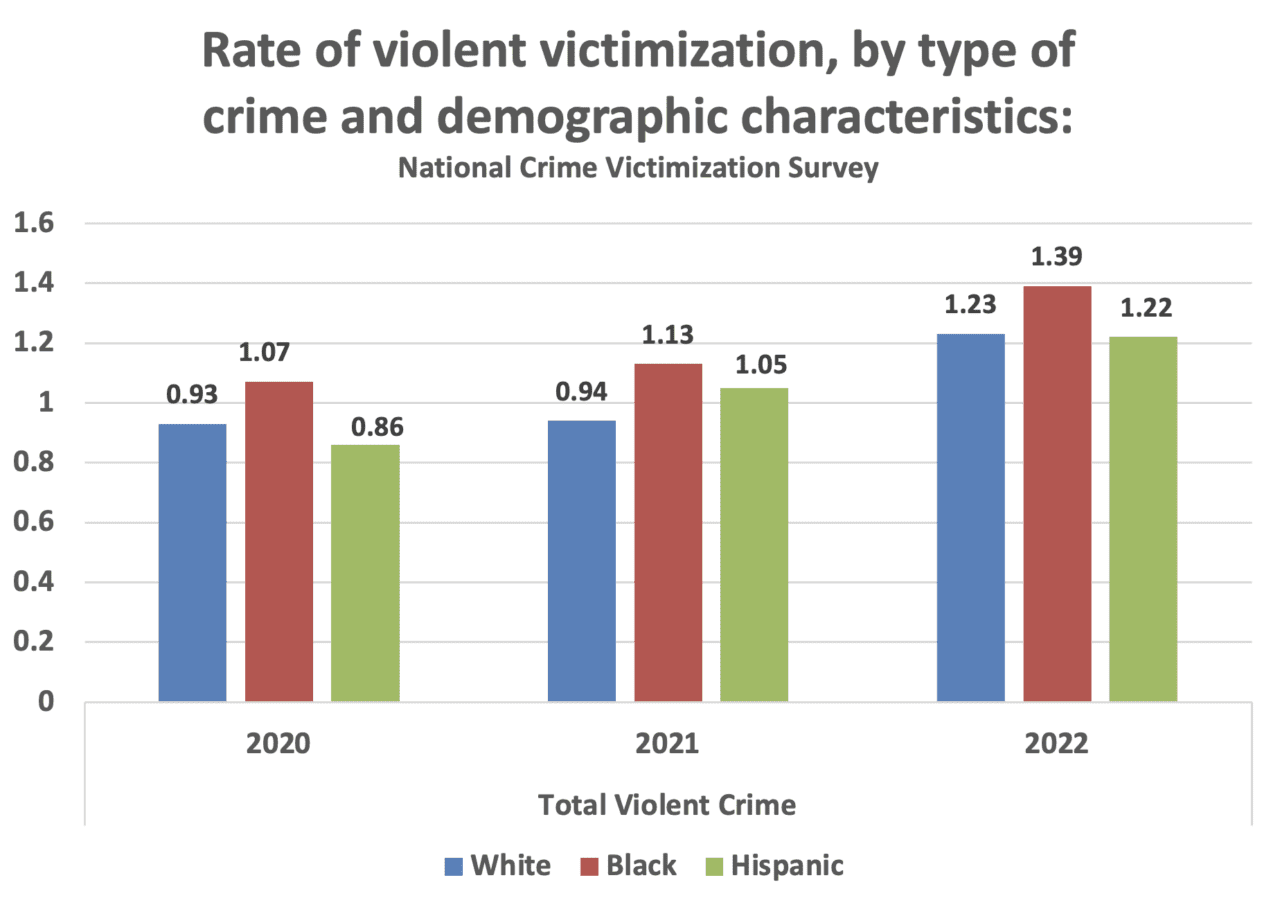
Federal crime statistics flow through a participatory system. Law enforcement agencies submit data voluntarily to the FBI, and participation rates vary significantly by jurisdiction and year. The SBR (Supplemental Briefing Report) program expanded racial categories around 2021, moving from a binary white/black classification to five distinct groups plus American Indian/Alaska Native as subcategories. This change caused disruption in time-series analysis because historical data does not map cleanly onto the new schema. Victimization data comes from a different pipeline entirely. The NCVS interviews roughly 240,000 people across 150,000 households every year. Respondents report crimes they experienced regardless of whether law enforcement was contacted. This produces estimates of the crime gap — the difference between crimes reported to police and those that remain unreported. Race-based analysis of NCVS data requires weighting adjustments because the sample design oversamples certain demographic groups to improve precision.
Common Interpretation Pitfalls
Raw arrest numbers by race are frequently cited without context, which produces misleading conclusions. Several factors complicate straightforward comparisons. First, population size matters enormously. A state with a larger Black population will naturally have more Black arrests in absolute terms, but the rate per capita tells a different story. Second, policing intensity varies by neighborhood and jurisdiction. Areas with higher police presence generate more arrests for the same underlying behavior compared to areas with minimal patrol coverage. Another issue that beginners miss is the treatment of "unknown" or "other" race categories. In some years and jurisdictions, a significant percentage of arrest records list race as unknown. If you exclude these records from analysis, you are implicitly assuming the missing data is random, which is rarely the case. I encountered this problem when analyzing a dataset where approximately 12 percent of entries had unspecified race, and the unknown category was disproportionately concentrated in particular offense types like drug violations.
Get the Full Details
Tools and Methods for Analysis
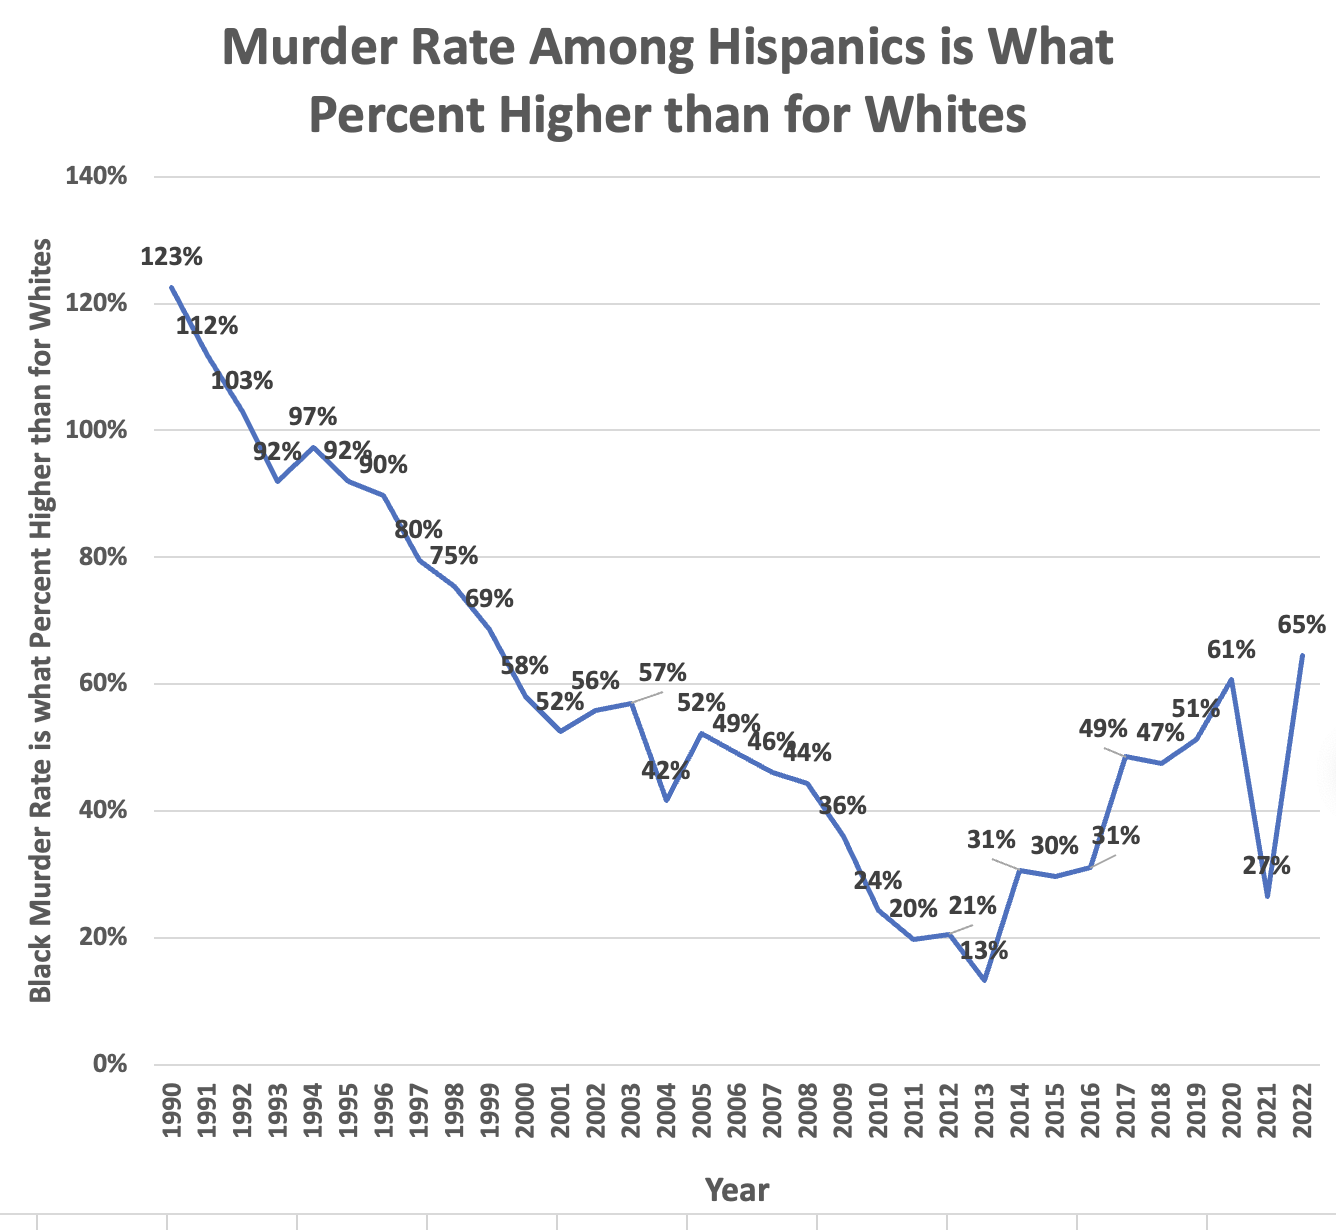
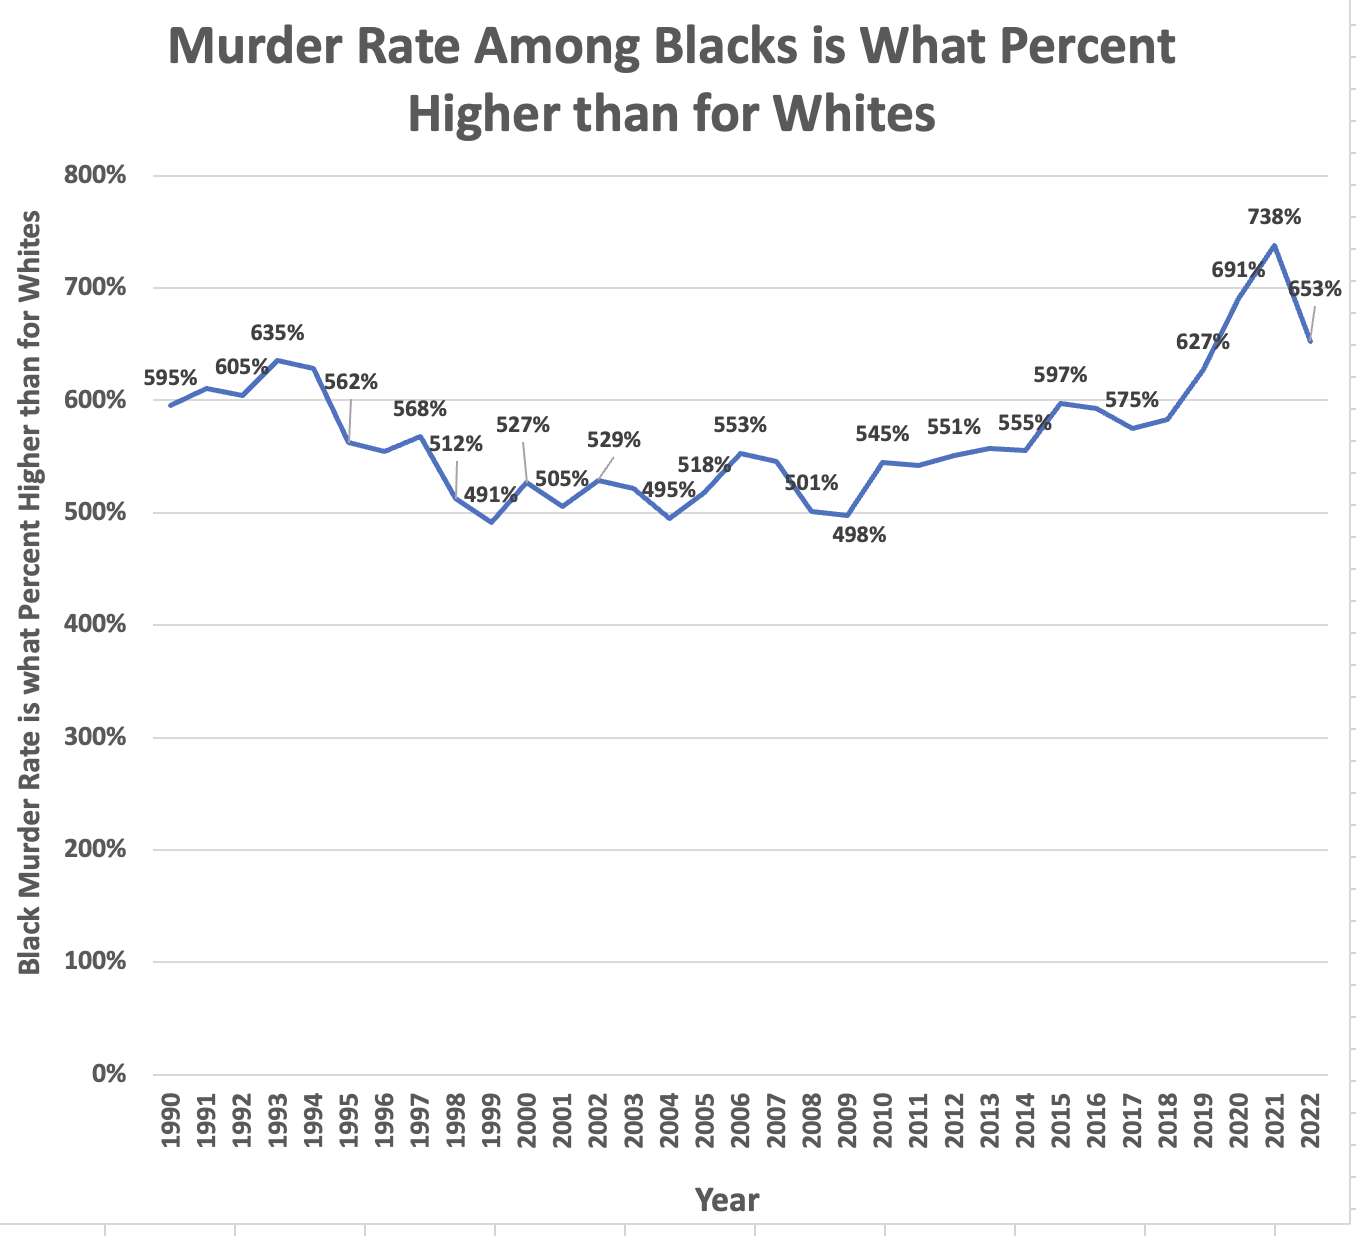
Researchers typically use statistical software like R, Python with pandas, or Stata to process crime data. The FBI provides data in both text and CSV formats, though the formatting is inconsistent across years. A practical approach involves writing a normalization script that handles the varying column structures, maps race categories to a standard scheme, and calculates rates using Census population denominators. The Census Bureau releases annual population estimates by race and age at the state and county level, which you can join to crime data using FIPS codes. For visualization, I recommend plotting crime rates as ratios rather than raw counts. A ratio of arrest rate to population share makes it immediately clear whether a demographic group is overrepresented or underrepresented in the statistics relative to their share of the total population. This approach also highlights how dramatically ratios shift depending on the offense category. Violent crime, property crime, and drug offense patterns look very different when examined separately.
Limitations and When the Data Fails You
US crime statistics have well-documented limitations that any serious analysis must address. The UCR program does not capture crimes that go unreported to police, which skews the picture for certain offenses like sexual assault and domestic violence. The NCVS fills some of this gap but relies on self-reporting, which introduces its own biases including memory decay and reluctance to disclose victimization. Another structural limitation is the lack of detailed socioeconomic controls in publicly available datasets. Crime rates correlate strongly with poverty, education, unemployment, and housing instability. When you compare rates across racial groups without controlling for these factors, you are conflating demographic differences with structural inequality. Some researchers use supplemental data from the American Community Survey to add poverty rates and other controls at the county level, but this increases the complexity considerably and may not be feasible for all analysis goals. For anyone looking to build a comprehensive race-and-crime dataset from scratch, the process typically takes one to two weeks for a first pass covering multiple states and several years of data. The time investment is worthwhile if you need publication-quality analysis, but for quick reference, the Bureau of Justice Statistics at bjs.gov offers pre-tabulated summaries that cover many common questions without the overhead of building your own pipeline.