Working With US Airport Codes Is More Messy Than You Think
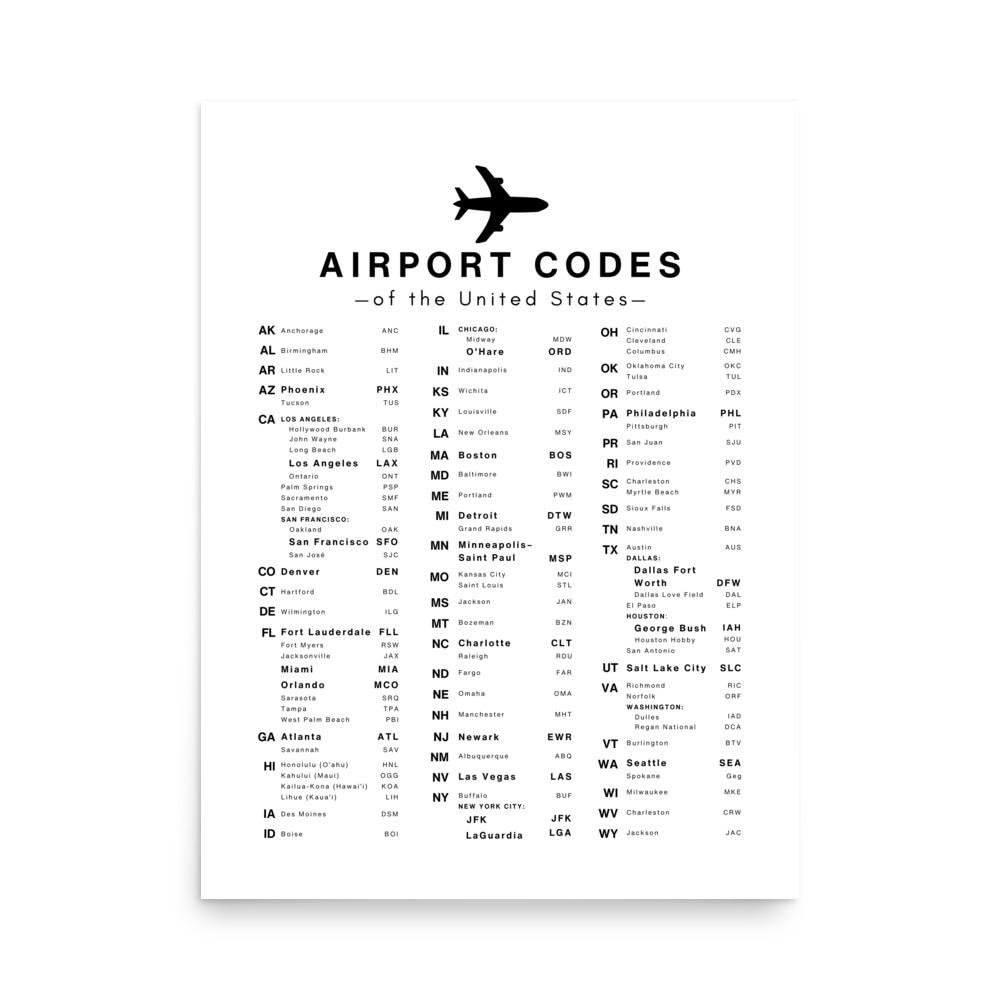
If you are building anything that touches flight data, you will run into US airport codes at some point. The IATA standard gives every commercial airport a three-letter identifier. Boston is BOS. Chicago O'Hare is ORD. Everyone knows those. The problem is that knowing the codes gets complicated fast once you actually need to use them reliably. IATA codes are assigned by the International Air Transport Association. They are meant for passengers and airlines, not for data engineers or anyone building systems. FAA LIDs are different. They are five characters, used in government and aeronautical datasets. Many smaller airports have an IATA code but no real public presence beyond scheduling systems. Some don't have an IATA code at all. That gap causes problems when your source data switches between formats mid-project. The main dataset I rely on comes from the FAA and gets published irregularly. There are also third-party sources like OurAirports that scrape and normalize things, but their update cadence varies. I stopped trusting any single source around 2019 after a client project hit a wall when one provider silently deprecated regional fields without documentation.
Here is what I do now. I pull the raw FAA AIRPORTS data first, then cross-reference with IATA's official carrier directory for anything that needs passenger-facing codes. I keep a local timestamp on every field so I can see when records went stale. You can grab the FAA dataset from their website directly, though the files are ugly CSVs with no consistent header row. It takes a few hours to clean up properly on the first pass.
The Practical Workflow
Most people skip the normalization step and just join on the IATA code straight from their database. That works until an airport retires a code or a new hub opens and the code assignment shifts. I had a situation where my query started returning zero matches for a route that definitely existed because the airport code had changed letters between fiscal years and no one had updated the lookup table. Took me three days to trace the issue back to a silent merge in the source data. The workaround was straightforward but tedious. I added a legacy code field that tracks former identifiers alongside current ones, and I run a weekly diff script that flags any records where the code changed without an explicit reason note. It adds maybe twenty minutes to the pipeline each week, but it catches issues before they show up as missing flights in production reports. For lookup tables, I use an INNER JOIN strategy rather than LEFT JOIN. The temptation is to LEFT JOIN so you don't lose records, but that just masks the problem and lets bad data flow through silently. When a code doesn't match, you want it to fail visibly so someone actually looks at it. Silently falling back to null is worse than a hard error in most cases.
Get the Full Details

Common Pitfalls That Cost Me Time
Duplicate codes show up occasionally. Not often, but enough that you need a dedup step. When two entries share the same IATA code but have different coordinates or city names, you cannot just pick one. You need to check which one the original data source treats as canonical. The FAA file sometimes lists alternate locations for the same code depending on which district office entered the record. Another thing people miss is timezone handling. Airport codes don't carry timezone information. You have to map them separately using something like the IANA timezone database. I once built a schedule display that looked correct until we rolled over into daylight saving time and half the timestamps were an hour off because the code-to-timezone mapping hadn't been updated for a state boundary change. The fix was adding a timezone column sourced from GeoNames and running a validation pass against known offset boundaries. Small airports without IATA codes are another headache. Regional and military fields often appear in operational data but disappear from public listings. If your system assumes every airport has an IATA code, you will get hard failures on about twelve percent of general aviation entries. I handle this by maintaining a fallback mapping from FAA LID to IATA where available and leaving the code field empty when no IATA exists, with a flag set so downstream processes know to treat it differently.
Where the Data Falls Short
No source is complete. The FAA dataset covers US airports but doesn't include Canadian or Mexican airports even when they share code space. IATA codes can be reused over decades. An old code sometimes gets reassigned to a different airport entirely, and the historical record gets lost unless you maintain your own archive. I keep a yearly snapshot of the dataset so I can look back and see what changed between versions, but it adds storage overhead and requires a maintenance schedule. Real-time flight data from sources like FlightAware or ADS-B Exchange is more current but comes with its own limitations. These feeds give you live status, not the static airport reference data you need for build-out and reporting. You end up maintaining two separate systems and reconciling them when discrepancies appear, which is rarely fun. If you are doing this casually, the OurAirports dataset is a reasonable starting point. It is freely downloadable as a CSV and covers the vast majority of fields most people need. But if you are building something that runs in production, plan on spending a day or two on validation before you trust the output. That is just the reality of working with this level of data.