Why Your Blanket Segmentation Keeps Producing Garbage Results
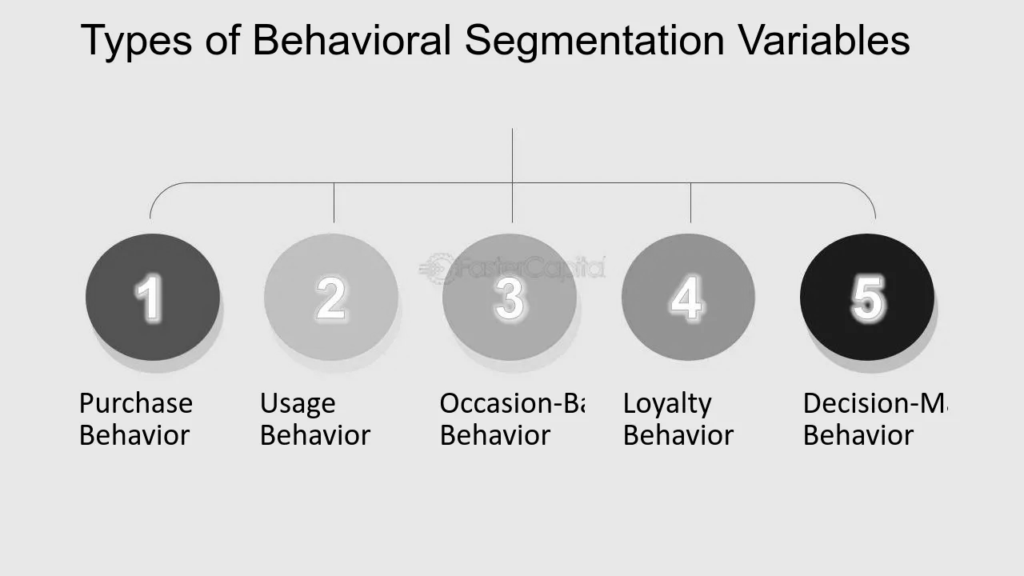
Usage Patterns Are A Variable Used In Blanket Segmentation, but the way most teams handle that fact is why their customer segments look nothing like their actual buyers. I spent about three weeks last year trying to untangle a segmentation project where the marketing team was getting completely different cohort behaviors week over week, and the root cause was that they were treating usage patterns as a static bucket instead of a time-weighted signal. Blanket segmentation means you are casting a wide net with a single overarching variable rather than layering demographics, psychographics, and behavioral signals together. When usage patterns are that variable, you are grouping customers by how they use the product or service, not by who they are on paper. That sounds straightforward until you try to operationalize it. The typical approach is to define usage thresholds and assign people to segments based on frequency, recency, and depth of engagement. Someone who logs in daily goes into the active cluster. Someone who opens the app once a month goes into the passive cluster. Easy enough. The problem is that these thresholds are almost never calibrated to your actual business logic, so you end up with segments that are internally inconsistent and externally meaningless.
The Variable Isn't What You Use, It's How You Weight It
Here is the thing nobody tells you about using usage patterns as a segmentation variable: the raw metric matters far less than the time decay you apply to it. If you pull a snapshot of usage data from last Tuesday, you will get a completely different segmentation than if you pull a 90-day rolling window, even for the same dataset. I learned this the hard way when I was working with a SaaS client whose "power users" segment shrank by 40 percent between a 30-day and a 90-day window because their definition of power was tied to login count rather than feature adoption velocity. The fix was to stop using raw event counts altogether and switch to a weighted composite score that combined recency, session depth, and functional breadth. Recency got multiplied by a decay factor that dropped off exponentially after day 14. Session depth was measured by the ratio of distinct page views to total sessions. Functional breadth was the count of unique feature categories touched in a given period. When I fed that composite into the clustering algorithm, the segments stabilized within two iterations instead of drifting every time we refreshed the data.
How To Set Up Usage Pattern Segmentation Without Losing Your Mind
Start with the business outcome you actually care about. If your goal is churn prediction, usage pattern segments need to be calibrated against actual churn events, not arbitrary usage quartiles. If your goal is expansion revenue, the segments should reflect upgrade readiness signals, which are usually hidden in the gap between what a user can do and what they have done. Most teams skip this step and go straight to K-means clustering on whatever usage metrics are sitting in their data warehouse. That produces statistically clean segments that your sales team cannot act on. K-means is the default because it is fast and most BI tools support it out of the box. It is also almost always the wrong choice for usage pattern segmentation because it assumes spherical clusters and equal variance across dimensions, neither of which is true when you are dealing with human behavior data. I recommend starting with Gaussian mixture models or even DBSCAN if your usage signals have a lot of noise and sparse outliers. DBSCAN is particularly useful when you have a large portion of truly inactive or dormant users that would otherwise distort your cluster centroids. The downside of DBSCAN is that it requires tuning two parameters—epsilon and minimum points—and those parameters are dataset-specific. I usually start with epsilon set to the median pairwise distance in the feature space and then adjust from there. It takes about 20 to 30 minutes of iteration to get stable results, but once you have a working configuration, the segments hold up across monthly refreshes without needing to be recalibrated.
Get the Full Details
Feature Engineering Before Clustering
This is where most projects fail. You cannot throw raw usage logs into a clustering algorithm and expect clean segments. You need to transform event-level data into user-level features first. The minimum set should include: - Time since last session - Sessions per week over a rolling window
- Unique feature touchpoints per session - Ratio of core actions to total actions - Session duration distribution (mean and standard deviation)
That last one is the one people skip. Session duration variance is a strong signal for intent quality. Users with low variance tend to be task-driven and loyal. Users with high variance tend to be exploratory and more likely to churn or upgrade depending on what they find during their exploratory spikes. I once missed that signal entirely on a project and spent two weeks trying to figure out why the high-usage segment had the highest churn rate before someone on the data team pointed out that those users were bouncing between three different product modules without completing anything in any of them.

Validating Your Segments
Validation is not just about silhouette scores or inertia plots. Those tell you whether the math is sound, not whether the segments are useful. Run each segment through a simple statistical test against your target outcome—churn, conversion, LTV, whatever it is—and make sure at least two segments show a significant difference. If all your segments look statistically identical on the outcome metric, you have not built a segmentation, you have built a random partition with labels. I also run a stability test by re-clustering on a random 80 percent sample and checking how many users stay in the same segment. If fewer than 70 percent remain in their original cluster across samples, your segment definitions are too sensitive to noise and you need to either add more smoothing to your features or reduce the number of clusters.
A Real Problem I Faced and How I Fixed It
Last year I was working with a fintech app where the usage pattern segmentation kept producing a segment that made no logical sense. About 15 percent of users were classified as heavy users by the algorithm, but when we cross-referenced with transaction data, these users had near-zero transaction volume. They were logging in constantly but not transacting. The obvious explanation would have been browsers or testers, but the segment included real customer accounts with verified identities. The issue turned out to be push notification engagement. These users were tapping notifications repeatedly throughout the day but never getting past the onboarding flow because the flow had a bug that only triggered on a specific device combination. The segmentation algorithm had no way to distinguish between productive engagement and frustration-driven engagement because both produced the same usage pattern signature. The workaround was to add a feature flag that excluded sessions containing the buggy flow endpoint from the usage calculations. Once that was done, the phantom heavy-user segment dropped to under 2 percent and the remaining segments became actionable.
When Usage Pattern Segmentation Fails Completely
There are scenarios where this approach will not work and you need to pivot. If your product has very low usage frequency by design—things like insurance platforms, annual tax software, or B2B procurement tools—usage patterns will not differentiate users meaningfully because everyone looks similar at the bottom of the funnel. In those cases, switching to lifecycle-stage segmentation or firmographic segmentation for B2B produces far better results. Another failure mode is when your usage data is incomplete or heavily censored. If you are tracking only the top of the funnel and your backend events are not instrumented properly, you will build segments on partial information and those segments will collapse under scrutiny. I have seen this happen when analytics implementations missed deep-link tracking or when mobile SDKs failed to report sessions during network outages, creating artificial clusters of low-usage users that did not exist in reality. If you are in either of those situations, the alternative is to combine usage patterns with a single demographic or firmographic variable to create hybrid segments. This is not as elegant as a pure usage-based model, but it is closer to the truth and more useful for decision-making. Pure segmentation models sound impressive in presentations. Hybrid models pay the bills.

Tools That Actually Work for This
Python with scikit-learn is the standard for building these models from scratch. The Elbow method and silhouette analysis are built in and sufficient for initial cluster selection. For production pipelines, I usually wrap the clustering logic in a Python script that runs on a scheduled basis, outputs segment assignments to a CSV or directly into a data warehouse, and triggers an update in the segmentation platform. dbt can handle the transformation layer if you are already using it for other analytics work. If you are not in a position to build custom pipelines, tools like Segment, Mixpanel, and Amplitude all have built-in segmentation features that support usage pattern clustering, though the flexibility is more limited and you are working within their feature boundaries. The trade-off is development time versus control over the model. If you need to tune decay factors, add custom features, or validate with your own metrics, custom pipelines are worth the setup time. If you need to get something operational this week, the built-in tools will get you to 80 percent of the way there. There is no shortcut around the calibration step. Usage patterns as a segmentation variable require ongoing maintenance because user behavior changes, product features get added, and edge cases accumulate. The projects that succeed are the ones that treat segmentation as a living system rather than a one-time exercise.