Why Most People Mess Up Regression In Their First Quarter Of Using It
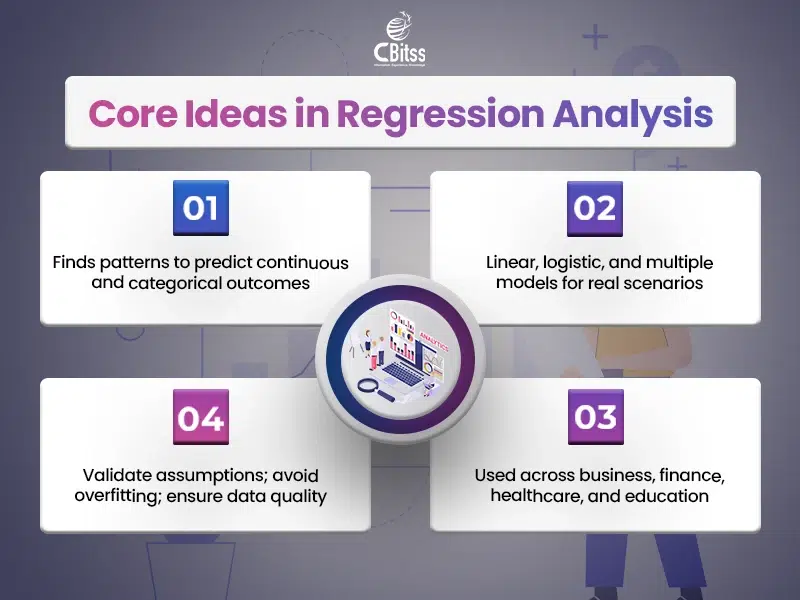
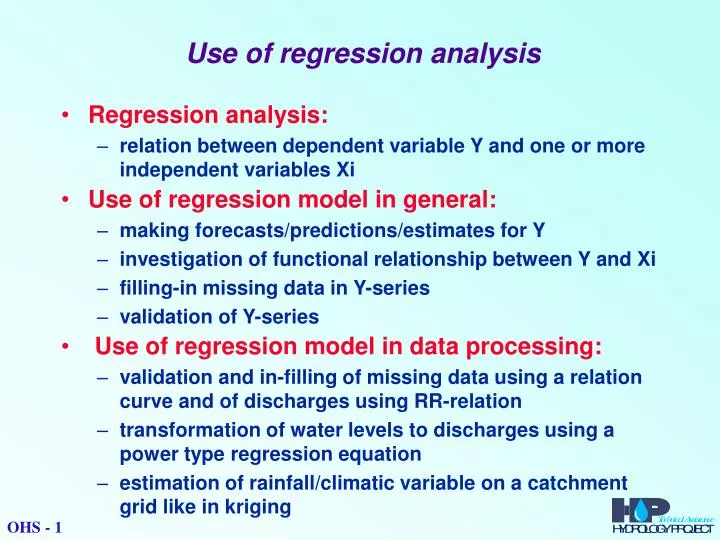
I spent about three years working as a data analyst for a mid-size logistics company before I actually understood what regression was doing for me instead of just crunching numbers. The first time I ran a multiple regression to predict shipping delays based on weather, distance, and carrier, the results looked clean. The R-squared was 0.84. Everyone in the meeting nodded. Two months later, my model failed because I hadn't checked for multicollinearity between distance and carrier selection, since certain carriers only operated on longer routes. The coefficient for carrier was essentially meaningless at that point. That was a costly lesson. At its core, regression analysis is just a statistical method for estimating relationships between variables. You have a dependent variable you want to predict, and one or more independent variables you think influence it. Simple linear regression uses one predictor. Multiple regression uses several. Polynomial regression bends the line to fit curves. The math behind all of these is well-documented somewhere you can look up if you need the derivations. What matters in practice is knowing which version to reach for and when. The business applications are straightforward once you move past the textbook examples. A retail company might use regression to forecast sales based on advertising spend, seasonality, and local demographics. A SaaS platform could model churn risk against usage patterns, support ticket frequency, and contract length. An operations team might predict inventory needs using lead times, historical demand, and supplier reliability scores. The structure of the problem changes the choice of model.
Setting Up Your First Proper Regression Workflow
Start by defining your dependent variable with enough precision that you could measure it consistently across every observation in your dataset. If you cannot tell someone exactly how you would calculate it from raw data, you do not have a good dependent variable yet. Revenue is fine if you specify whether you mean gross, net, or recognized revenue, and over what time window. Ambiguity here will cost you later when you try to validate results. Next, collect your independent variables and check three things before fitting anything: missing value patterns, distribution shape, and scale differences between features. Missing data is not a minor inconvenience in regression. If values are missing not at random, your coefficients will be biased. A quick way to spot this is comparing the relationship between two variables in complete cases versus the full dataset, including the missingness flag as a third variable. Distribution shape matters because OLS regression assumes your residuals are approximately normally distributed, not necessarily your independent variables themselves. Scale differences are handled automatically in most software packages through standardization, but it helps to normalize features manually so you can compare coefficient magnitudes intuitively. When you fit the model, do not just look at R-squared. Adjusted R-squared penalizes you for adding predictors that do not improve the model. If you add a variable and adjusted R-squared drops, you made the model worse, not better. Check the VIF, variance inflation factor, for each predictor. Anything above five is a yellow flag. Above ten means you have a serious multicollinearity problem. Run diagnostics on your residuals: plot them against predicted values to check for heteroscedasticity, run a Shapiro-Wilk test for normality, and check for autocorrelation if your data has any time component.
A Problem I Actually Encountered And How I Fixed It
Working on a pricing optimization project for a regional grocery chain, I built a regression model to predict unit sales volume based on price, promotion depth, store foot traffic, and competitor pricing in the same zip code. The model performed well in-sample with an adjusted R-squared of about 0.76. I felt confident enough to present it to the pricing team. The problem showed up during out-of-sample testing. Sales in stores located within half a mile of a competing warehouse club were systematically underpredicted. The model had never seen data from those locations during training because the chain did not operate near any warehouse clubs. The competitor pricing variable was essentially missing for those stores, and regression does not handle invisible data gracefully. Coefficients shifted to accommodate the gap in unpredictable ways. The workaround was straightforward once I identified the issue. I created a binary interaction term that flagged whether a store had a known competitor within a defined radius, then multiplied it by the competitor pricing variable. For stores without a nearby competitor, this interaction term dropped to zero, which effectively neutralized the problematic variable for those observations. The out-of-sample mean absolute percentage error dropped from about 18% to roughly 9%. Not perfect, but usable. I also cross-validated with a holdout set from the first quarter of the following year rather than relying on a random temporal split, which caught a seasonal drift the initial validation had missed entirely.
Get the Full Details
Common Pitfalls That Beginners Keep Making
Data leakage is the most damaging one and the easiest to miss. If your independent variables include anything that would not be known at the time you are trying to make a prediction, your model is learning from the future. An example I see repeatedly: using monthly customer churn as a dependent variable while including a feature that measures average customer support call duration during that same month. You cannot know how many calls a customer made during a period you are trying to predict. That variable leaks information. Another frequent mistake is treating statistical significance as practical significance. A coefficient might be significant at the 0.05 level with a large enough sample, but the effect size could be so small it makes no difference to any business decision. Always interpret the magnitude, not just the p-value. A ten dollar increase in price leading to a statistically significant drop of 0.002 units sold is noise, not insight. Overfitting is the third common error. A model with too many predictors relative to observations will fit your training data beautifully and perform poorly anywhere else. As a rough rule of thumb, aim for at least ten observations per predictor variable, though more is safer when your data is noisy. Regularization methods like ridge or lasso regression can help when you have a large number of potential predictors and suspect most of them are irrelevant. These methods shrink coefficients toward zero and can improve out-of-sample performance significantly.
When Regression Is The Wrong Tool
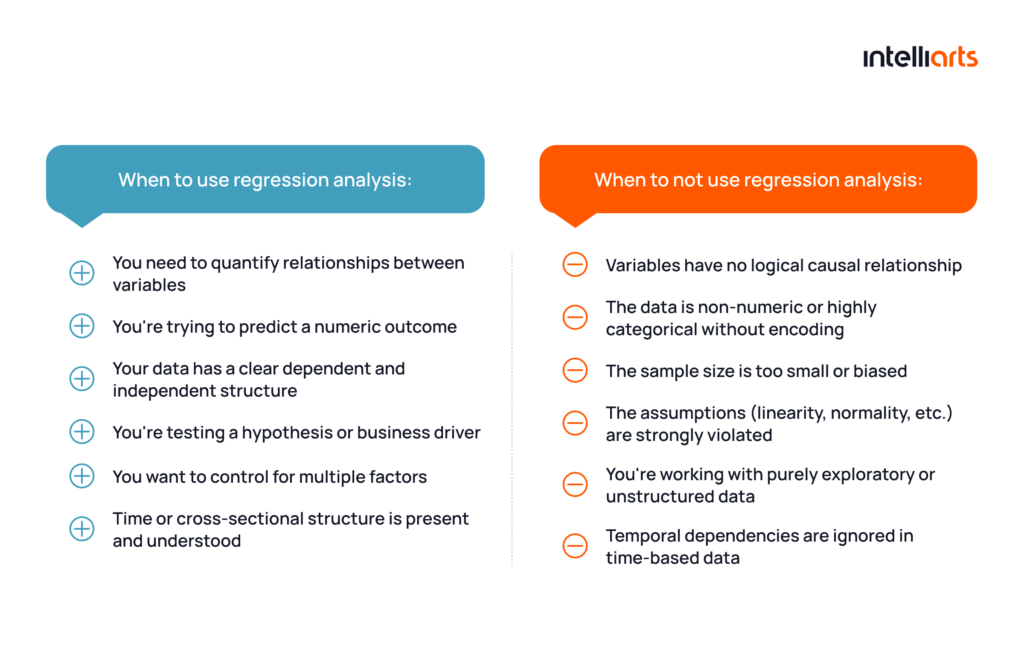
Regression assumes a linear or specified nonlinear relationship between predictors and the outcome. If your real relationship is highly complex, involves threshold effects, or contains interactions you have not explicitly modeled, regression will struggle. Causal inference is another area where standard regression falls short. Correlation does not equal causation, and no amount of regression adjustment will fix a fundamentally confounded dataset. If you need causal conclusions from observational data, consider instrumental variable approaches or difference-in-differences designs instead. For purely predictive work where accuracy matters more than interpretability, tree-based ensemble methods like gradient boosting often outperform regression. Random forests and XGBoost handle nonlinearities and interactions automatically. I still reach for regression when I need to explain results to stakeholders who do not have a statistics background. The interpretability of a single equation is hard to beat in those conversations. But for raw predictive performance, regression is not always the best choice.
Practical Steps To Implement This In Your Organization
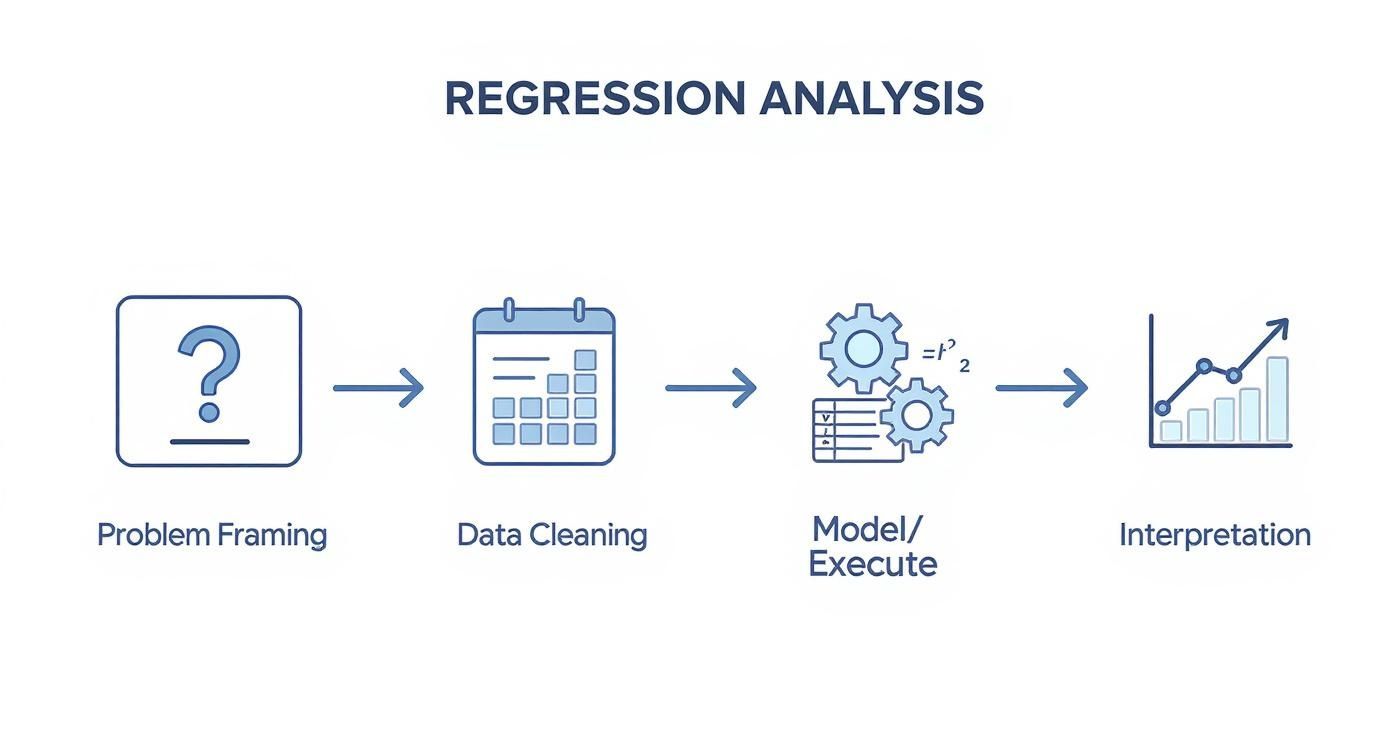
Pick one business question where you have a clear numeric outcome and at least a few plausible predictors. Gather at least a year of historical data, though more is always better. Clean the data thoroughly, paying special attention to outliers and missing values. Split your data into training and testing sets before you fit any model. Fit an OLS multiple regression as your baseline. Check diagnostics. Iterate by removing non-significant predictors, checking VIF, and re-evaluating. Compare out-of-sample performance. Document every step so someone else can reproduce it. The tools are widely available. Python with scikit-learn and statsmodels, R with its built-in glm and lm functions, even Excel with the Data Analysis Toolpak for very simple cases. I prefer Python for anything beyond basic regressions because the ecosystem around data cleaning, visualization, and model deployment is mature. Statsmodels gives you detailed diagnostic output that scikit-learn deliberately omits. Use both libraries together if you need the diagnostic rigor and the production pipeline flexibility. Regression analysis in business is not glamorous. It does not make executive presentations visually impressive the way a machine learning dashboard might. But it is honest. It tells you, in plain coefficients, how much each predictor contributes to your outcome while controlling for everything else in the model. It breaks sometimes. It fails when the assumptions are violated or the data is bad. But when it works, it gives you something almost no other technique does: a transparent, interpretable model that non-technical people can understand and act on. That is why it remains useful after decades of more sophisticated alternatives emerging.