Getting Started With R When You Actually Need To Get Work Done
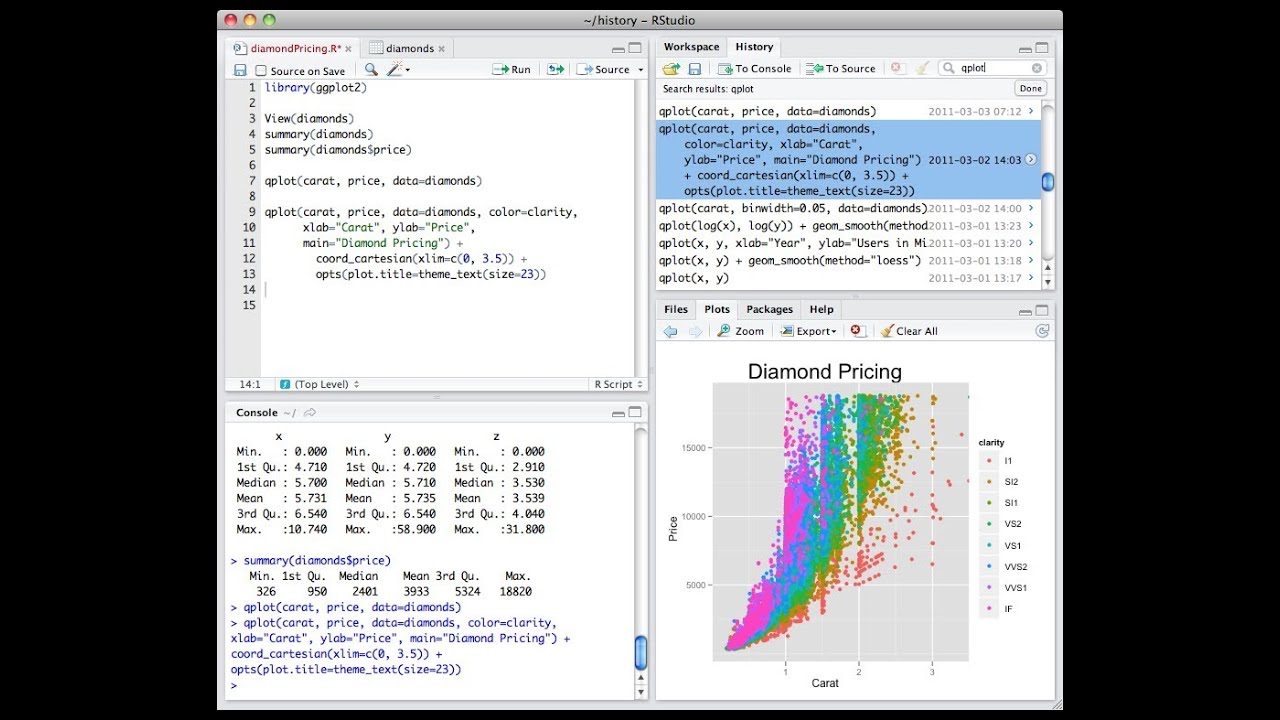
R is a programming language built around statistics. The R Foundation maintains it, and over the years it has accumulated a massive ecosystem of packages through CRAN. If you are pulling data from a CSV, cleaning it, running regressions, and producing publication-quality plots, R handles that path pretty well. The installation is straightforward. Go to the Comprehensive R Archive Network at cran.r-project.org, grab the installer for your operating system, and run it. On Windows it sets up the 64-bit binary by default. On macOS it works the same way. There is also RStudio now owned by Posit, which gives you an IDE with a console, file browser, plot window, and package manager all in one. Most people install both: R itself first, then RStudio on top.
The reason people keep coming back to R is not any single feature. It is the package structure. A package bundles functions, documentation, and sometimes compiled code together. When you install something like tidyverse, you are really installing about thirty individual packages that have been aligned around a common syntax philosophy. That alignment matters when you are writing real scripts instead of playing with toy datasets.
Use R For Data Analysis In Practice
I learned R because Python felt too generic for the kind of statistical modeling work my team was doing. We needed mixed-effects models with crossed random factors, survival analysis with time-varying covariates, and bootstrapped confidence intervals that actually accounted for clustering. Python had some of that scattered across three different libraries with incompatible APIs. R had it in lme4, survival, and boot, and they mostly talked to each other.
The learning curve is not steep at first. Basic operations feel almost familiar if you have done any math. But the moment you try to combine data from multiple sources, things get interesting. I spent about two weeks fighting factor levels after merging two datasets where one variable had been read as character in one file and as a factor in the other. Joining them created a cartesian explosion of dummy variables. The fix was straightforward once I realized what happened: I converted everything to character with as.character() before the merge, then re-factorized after. That lesson cost me a Friday evening I will not get back.
There are a few things most tutorials do not warn you about. First, R uses 1-based indexing, which drives people coming from Python absolutely insane for exactly one week and then becomes normal. Second, R has three kinds of equality operators and you will not use all of them. == for values, === never exists, and isTRUE() is what you actually reach for when something might be NA. Third, the garbage collector runs aggressively in interactive sessions and can make your script appear slower than it actually is. If your loop takes longer than expected, check whether you are creating large intermediate objects inside the loop body without assigning them anywhere. The memory churn is visible in the console as a flashing trash icon or just sudden pauses.
The tidyverse approach changed how I write R code more than anything else did. Before it, I used base R functions like merge(), subset(), and lapply(). After switching, my data manipulation reads closer to the actual question I am asking. Take the mtcars dataset as an example. If I want the average miles per gallon grouped by cylinder count, the base R version is about six lines with tapply or aggregate. The dplyr version is four lines with group_by and summarise. The difference seems minor until you are writing something with fifteen transformations chained together, at which point the pipe operator makes the whole thing readable instead of a nested nightmare.
library(dplyr)
mtcars %>%
  group_by(cyl) %>%
  summarise(mean_mpg = mean(mpg, na.rm = TRUE))
That runs instantly. The equivalent base R code does the same thing in roughly the same time. Performance differences between tidyverse and base R are usually negligible for datasets under a million rows. Once you cross that threshold, you start noticing it, and that is when you look at data.table or arrow packages instead.
I should mention the downsides because nobody does this fairly otherwise. R is slower than compiled languages for heavy numerical work. If you are doing matrix operations on large arrays repeatedly, R will be ten to fifty times slower than Julia or even well-written Python with NumPy. The workaround is usually to push the bottleneck into C++ via Rcpp or to use a package that already has optimized internals, like data.table or matminer. R also has a package dependency problem. Some packages depend on others depending on others, and updating one package can break two others. I have encountered this when upgrading the tidyverse suite and having ggplot2 suddenly refuse to load because a dependency shifted to a newer R version I had not updated yet. The fix is to pin package versions with renv or to use BiocManager for bioconductor packages separately from CRAN.
Another realistic problem is the NAMESPACE export system. When you install a package, only certain functions are exposed. Trying to call a function that looks like it should exist but returns "could not find function" means it is either not exported or you forgot the namespace prefix. The double colon operator fixes that. stats::lm() works even if you do not have stats loaded explicitly, because it is a base package. But dplyr::left_join() requires the package to be attached or loaded with library(). This is one of those things that seems arbitrary until you have spent an hour debugging a script that works on your machine but fails on a colleague's because their library path is different.
For visualization, ggplot2 is the standard. The grammar of graphics framework means you build plots layer by layer. Start with the data and aesthetic mapping, then add geometries, then facets, then themes. A basic scatter plot with a trend line looks like this:
library(ggplot2)
ggplot(data = mtcars, aes(x = wt, y = mpg)) +
  geom_point() +
  geom_smooth(method = "lm", se = TRUE) +
  theme_minimal()
That produces a clean plot. The default theme in ggplot2 is actually not terrible, which surprises people who expect default outputs to look like something from 2003. The theming system is extensive enough that you can reproduce journal formatting guidelines without manually adjusting every element.
When you move into statistical modeling, R remains strong. Linear models with lm(), generalized linear models with glm(), mixed models with lme4, Bayesian work with rstan or brms, and survival analysis with the survival package. The models all return similar S3 object structures, which means once you learn how to extract coefficients, residuals, and confidence intervals from one model type, the pattern transfers to almost all others. coef(), summary(), and predict() work across most model classes. broom is a package that standardizes this further by converting model output into tidy data frames, which makes it much easier to combine results from multiple models into a single table.
One advanced nuance that catches people off guard is how R handles formulas internally. The tilde operator creates a formula object that carries both the expression and the environment where it was defined. This is why random forests and gradient boosting packages in R can access variables from your workspace without you passing them explicitly. It is also why you sometimes get errors about object not found when you train a model inside a function and then try to predict on new data that lives outside that function's scope. The solution is usually to use the data argument in the modeling function or to explicitly pass the new data through the predict call.
Memory management deserves its own section because it is the most common source of production failures. R loads entire objects into RAM. A CSV file that is two gigabytes on disk might become eight gigabytes in R because strings become factors, factors become integers with label attributes, and character vectors get duplicated during certain operations. The data.table package handles this more efficiently by reading only the columns you need and using reference semantics, meaning modifications happen in place rather than creating copies. If you are working with datasets larger than your available RAM, data.table is not optional. It is the difference between the script finishing and your machine swapping to death.
There is also the question of reproducibility. Writing an R script that produces the same output six months later is harder than it sounds because package versions change, R itself updates, and CRAN occasionally yanks or replaces packages. renv solves this by snapshotting your environment into a lockfile that records exact package versions and repository URLs. Projects that share code with collaborators benefit enormously from this. Without it, you end up spending more time debugging version mismatches than actually analyzing data.
For web scraping or API work, R has rvest and httr, which are adequate but not as polished as Python equivalents. If your workflow depends heavily on interacting with REST APIs, you might find yourself frustrated by the lack of built-in async support. R does have futures and promises packages, but they require a different mental model than what you would use in Python asyncio. For batch ETL pipelines, Python or a dedicated tool like Airflow is usually more appropriate. R excels at analysis, not at infrastructure.
The R community is large and active. R-bloggers aggregates posts from hundreds of contributors. Stack Overflow has millions of tagged R questions. The #rstats community on social media posts tips, package announcements, and bug reports daily. Conferences like useR! and EuroRUC bring the community together in person. Learning resources range from free books like Advanced R by Hadley Wickham to paid courses on platforms like DataCamp. The quality varies, but the amount of available material is not a problem.
If you are deciding whether to invest time in R, consider what kind of work you actually do. If your day involves cleaning messy survey data, running regression models, and generating figures for papers or reports, R is genuinely efficient once you get past the initial syntax adjustments. If your work is mostly engineering-focused, building production systems, or working at extreme scale, you will likely outgrow R or choose a different primary tool. R sits comfortably in the middle: more structured than a general-purpose language for pure scripting, less rigid than domain-specific statistical software that locks you into a single vendor.
The download process for R itself takes about five minutes on a normal connection. RStudio Desktop, the free version, is also free to download and install. Most of the actual work happens after installation, in the space between reading documentation and writing code that does not crash. That gap closes with practice. A week of daily use usually gets you past the initial frustration. A month gets you competent. Beyond that, it becomes a tool you reach for without thinking about it, which is exactly what you want from software you use regularly.
Gallery Use R For Data Analysis
How to Use R Studio for Data Analysis and Reporting
Data analysis using R - GeeksforGeeks
Data Analysis Using R Programming | Data Analytics With R | R ...
Data Analysis in R - YouTube
Data Analysis with R Skool Community Statistics