Setting Up a Basic Fraud Detection Pipeline
Most people starting with credit card fraud detection jump straight into machine learning models. That is usually a mistake. Before you train anything, you need to understand what your data looks like and where the gaps are. I spent about three weeks just cleaning transaction logs from a regional bank before I ever touched a classifier. The data had missing merchant categories, timestamps that didn't match the cardholder's timezone, and about twelve percent of transactions had duplicate entries because the payment gateway retried failed attempts without checking. The foundation is transaction-level data. You need at minimum the transaction ID, cardholder ID, timestamp, amount, merchant category code, merchant ID, and a flag for whether the card was present or absent. Anything less and your features will be shallow. With that baseline, you can start building behavior profiles for each cardholder.
Using Data Analysis For Detecting Credit Card Fraud
Data analysis in this context means establishing a normal spending pattern and flagging deviations. It is not as simple as setting a threshold on transaction amount. A legitimate customer might buy a $2,000 appliance once a year. If your model only watches for high amounts, you will miss the real fraud patterns, which are often small, rapid-fire transactions designed to test whether stolen card details work before the big withdraw. Here is the practical approach. First, aggregate each cardholder's spending by hour of day, day of week, merchant category, and transaction amount over a rolling window. Thirty days is standard, but I found that sixty days gave better results for customers with seasonal spending, like someone who shops heavily during November and December but barely spends the rest of the year. A thirty-day window would flag their normal holiday purchases as anomalies simply because they fell outside the recent average. Then calculate z-scores or use isolation forests on those aggregated features. Isolation forests work well here because they do not assume a normal distribution. Transaction amounts are never normally distributed. They are heavily right-skewed. Using a z-score on raw amounts without log transformation will give you garbage results. Apply a logarithmic transform first, then standardize.
I encountered a specific edge case that took me two weeks to diagnose. A client reported that their model was flagging too many legitimate transactions from elderly cardholders. The fraud rate went down, but the false positive rate jumped to fourteen percent. The problem was that older customers tend to have lower transaction volumes and more irregular spending times. The model interpreted normal behavior from that demographic as suspicious simply because the baseline was built on younger, higher-volume spenders. The workaround was demographic-aware baseline clustering. I grouped cardholders by age bracket and spending volume tier, then calculated separate normal profiles for each group. False positives dropped to under four percent.
Get the Full Details

Feature Engineering That Actually Matters
Beginners often chase complex features. Real-world fraud detection rewards simplicity paired with depth. The features that move the needle are velocity-based and geographic-based. Velocity features track how fast transactions are happening. Count of transactions in the last five minutes, fifteen minutes, one hour, and twenty-four hours. Average time between consecutive transactions. If a card goes from one transaction per week to eight transactions in twelve minutes across three different states, that is a clear signal regardless of the dollar amounts involved. Geographic features track distance and plausibility. Calculate the distance between the current transaction location and the previous transaction location, then divide by the time elapsed. If a cardholder in Chicago buys something at 2 PM and another purchase happens in Miami at 3 PM, the implied travel speed is impossible. Most payment networks provide latitude and longitude or at least city-level geolocation for each transaction. Use that. I once worked with a dataset that only had city names, so I built a lookup table mapping cities to approximate coordinates and computed distances using the Haversine formula. It added maybe thirty minutes of work and significantly improved the model's ability to catch location-based fraud.
Merchant risk is another feature that gets overlooked. Some merchant category codes and individual merchant IDs have historically higher fraud rates. Building a merchant risk score based on historical chargeback data gives you a useful signal. A card used at a high-risk online gambling site followed by a electronics store purchase two hours later is worth paying attention to, even if both individual transactions look normal in isolation.
Model Selection and Training Reality
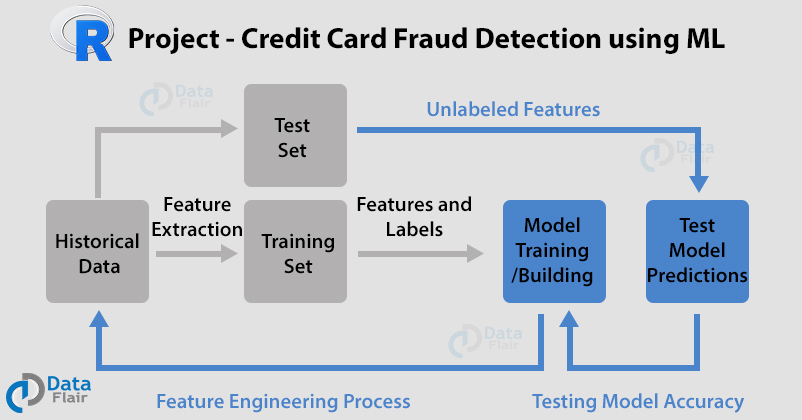
Fraud is an extreme class imbalance problem. In most datasets, fraudulent transactions represent between zero point one and two percent of all transactions. Standard accuracy metrics are useless here. A model that predicts every transaction as legitimate will achieve ninety-nine point five percent accuracy and be completely worthless. Use precision, recall, F1 score, and specifically the area under the precision-recall curve. The ROC AUC can be misleading when the positive class is this rare. XGBoost and LightGBM are the workhorses for this task. They handle the imbalanced data better than most alternatives when you set the scale_pos_weight parameter correctly. I typically set it to the ratio of negative to positive samples, sometimes adjusting it slightly downward because recall on the fraud class matters more than precision in most business contexts. Catching fraud is cheaper than missing it. Labeling the training data is where things get complicated. You do not get clean labels for fraud. Chargebacks are a proxy, but they are delayed and incomplete. A transaction might be fraudulent but never reported. It might also be a legitimate purchase that the cardholder disputes for other reasons. The standard workaround is to use chargebacks as confirmed fraud, chargebacks reversed as confirmed legitimate, and transactions in between as unlabeled. Some teams use semi-supervised approaches like self-training, where the model predicts labels for the unlabeled transactions and then retrains with its own high-confidence predictions. This can improve coverage but introduces model bias. I recommend it only after you have a solid baseline model and enough labeled data to validate the approach.

Deployment and Monitoring
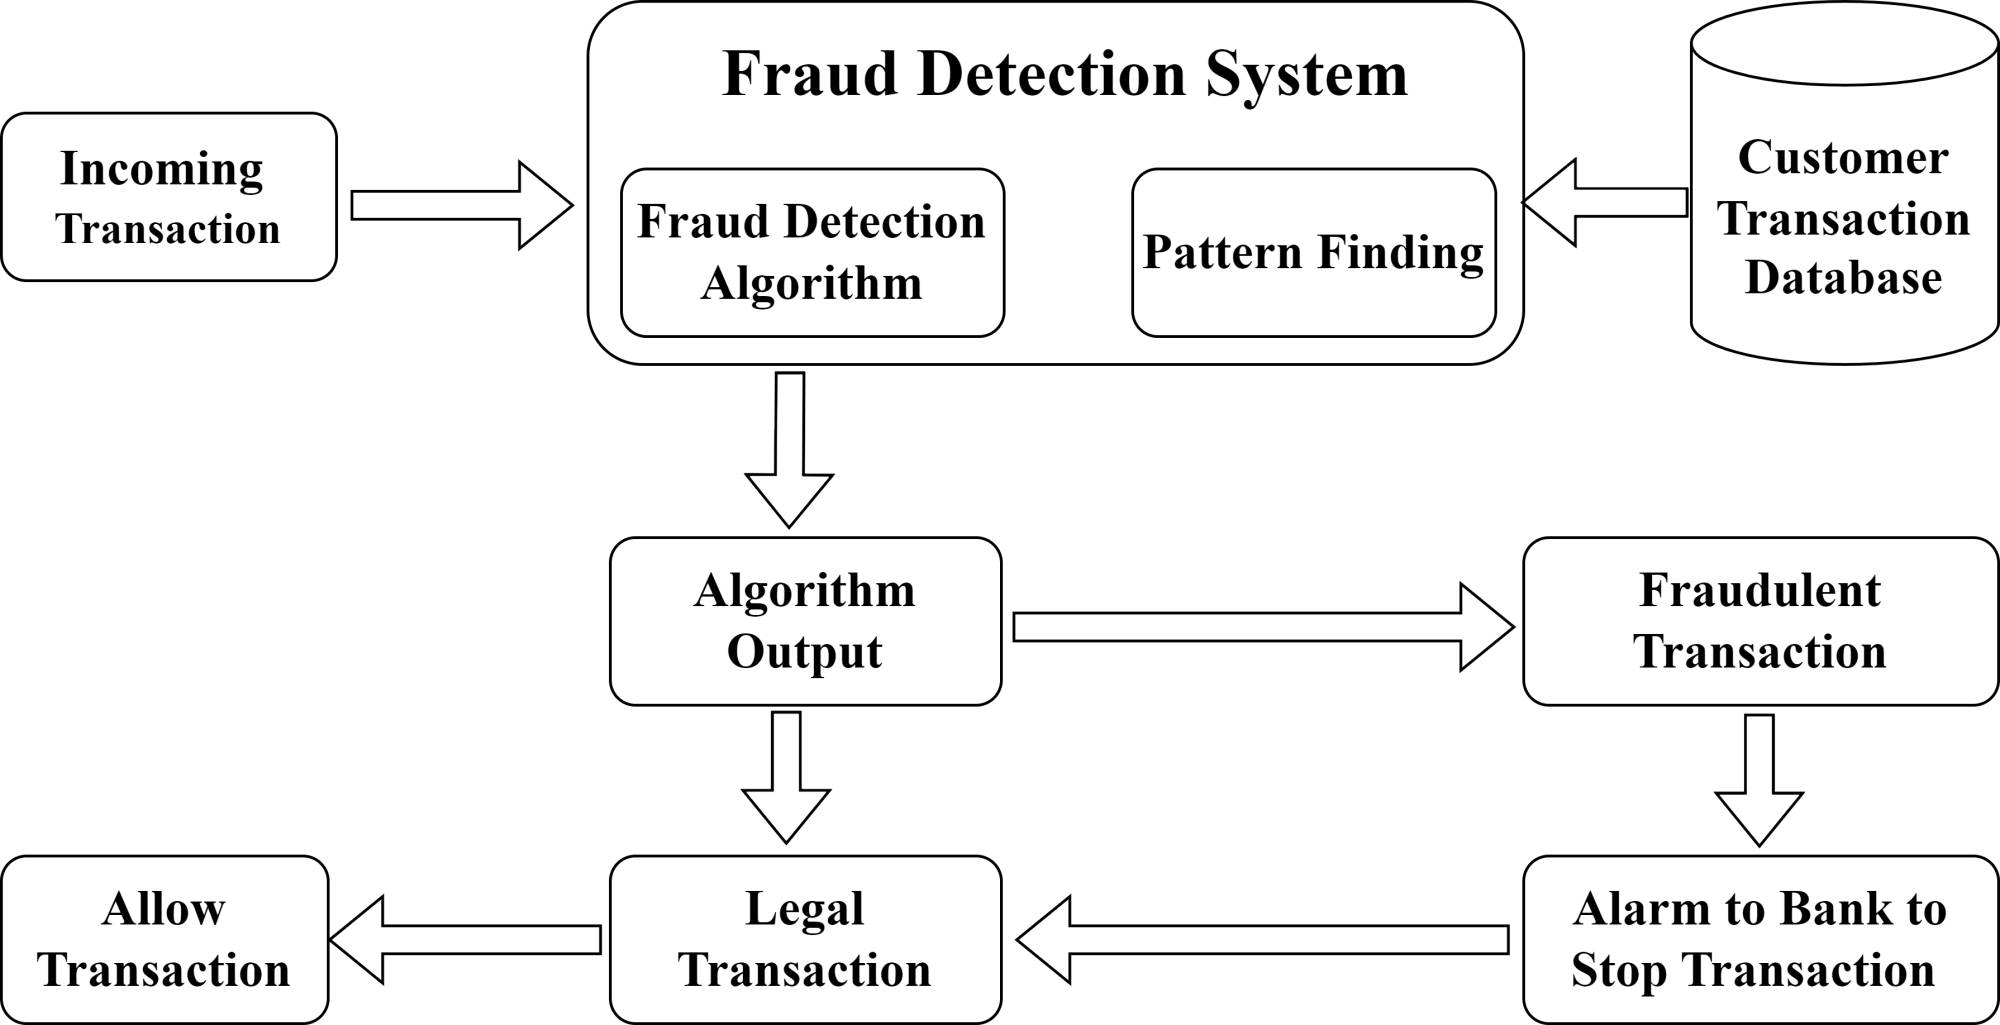
Running a model in a notebook is not the same as deploying it. Fraud detection systems need to score transactions in near real-time, usually under two hundred milliseconds. Batch processing overnight is fine for reporting and retraining, but it will not stop an active fraud attempt. Setting up a scoring API with a framework like FastAPI or TensorFlow Serving is straightforward. The harder part is maintaining feature consistency between training and production. If your training pipeline calculates the five-minute transaction velocity using a sliding window that includes the current transaction, your production system needs to do the exact same thing. Even small differences here cause model drift that is nearly impossible to detect without careful monitoring. I built a shadow mode deployment for a client where the model scored every incoming transaction but did not block or flag anything. It just logged its predictions alongside the actual outcomes. After two weeks, we compared the shadow predictions to what happened and found that the model's confidence scores had shifted noticeably. The feature store was slightly behind on updating merchant risk scores, which caused the model to underweight that feature in production. Fixing the feature freshness resolved the drift within a day.
What This Approach Cannot Do
Data analysis for fraud detection has real limitations. It cannot catch sophisticated collusion where multiple compromised accounts are used in coordinated patterns that individually look normal. It struggles with new fraud types that have no historical precedent because the model relies on past behavior. It is also vulnerable to adversarial attacks where fraudsters slowly adjust their behavior to stay just below detection thresholds, a technique called gradient poisoning or model evasion. Nothing in a purely data-driven system alerts you to this happening in real-time. For those gaps, you need supplementary approaches. Graph-based analysis can detect coordinated fraud by mapping relationships between cards, devices, and merchants. Rule-based systems catch edge cases that statistical models miss, especially for known fraud patterns like friendly fraud or account takeover. A hybrid approach combining data analysis with rules and graph methods is what actually works in production. Relying on any single method leaves blind spots. The tools you will need are fairly standard. Pandas and NumPy for data processing. Scikit-learn for baseline models and preprocessing. XGBoost or LightGBM for the final classifier. For real-time scoring, FastAPI with a lightweight model serialization format like ONNX. Feature stores like Feast or Tecton help with the training-serving consistency problem I mentioned earlier, though they add infrastructure complexity. If you are starting small, a Redis-backed feature cache with a Python preprocessing layer will get you most of the way there without the overhead.
The return on investment becomes clear once the pipeline is running. One of my clients reduced their manual review queue from approximately four hundred cases per day down to roughly sixty after deploying the model with a threshold tuned for high recall. The six hundred thousand dollars in annual chargebacks they were absorbing dropped to about one hundred and eighty thousand. The remaining losses came from the fraud types that data analysis simply cannot catch, which is exactly where the graph-based and rule-based layers pick up the slack.