Getting Your Head Around Uw Web Of Science
The University of Washington's access to Web of Science is one of those resources that sounds straightforward until you actually need it. You log in through the UW proxy, run a search, and then realize the results are somehow incomplete, duplicated, or missing the records you actually came for. It happens. I've spent enough time navigating this database across multiple research projects to know where it breaks down and how to work around it. Web of Science is Clarivate's flagship citation database. It indexes journals, conference proceedings, and books across the sciences, social sciences, and arts and humanities. The core value isn't the search results themselves. It's the citation network data, the impact factor information, and the ability to trace who cited whom across decades of literature. UW provides institutional access to the full suite: the core collection, the expanded citations, the analytical tools, and the export functions. The catch is that coverage is selective. Not every journal gets indexed. Not every conference gets captured. And certain disciplines, particularly regional journals and newer open-access publishers, have uneven representation. This is a known limitation that shows up constantly in systematic reviews.
How to Access It Through UW
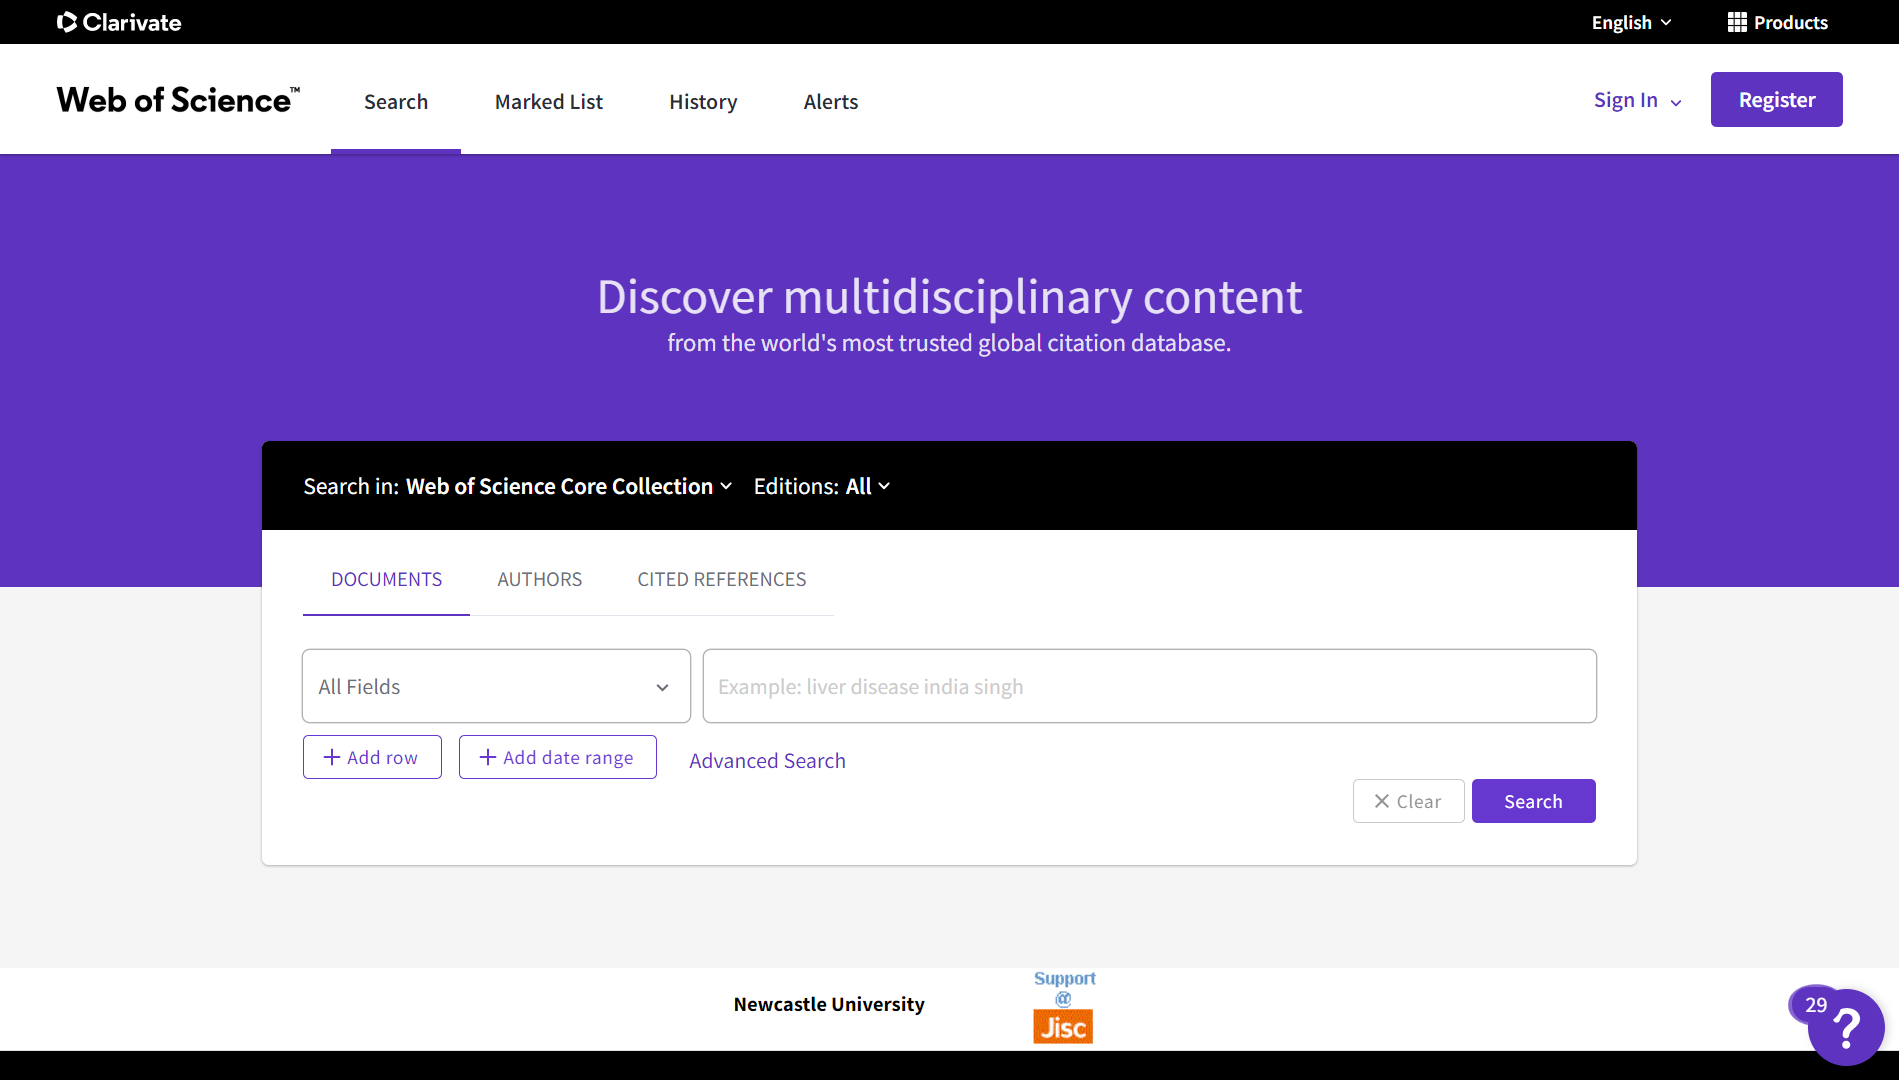
If you're at the University of Washington, you access Web of Science through the library proxy system. Navigate to the UW Libraries page and search for "Web of Science," or go directly to webofscience.clarivate.com and let the proxy redirect handle authentication. You'll need your UW NetID. Without it, you get the free trial interface with extremely limited functionality, which is mostly useless for actual research work. Once authenticated, the interface looks like this: a main search box, advanced search options, and a results panel with export and analysis tools along the right side. The default search is broad. Almost always, you need to switch to advanced search mode within the first thirty seconds, or you'll waste twenty minutes filtering through garbage results.
Setting Up an Effective Search Strategy
Web of Science uses a specific syntax that differs from what you'd use on PubMed or Scopus. The main fields you'll work with include TS for topic (title, abstract, keywords), TI for title, AU for author, SO for source publication, and PT for publication type. You can combine these with Boolean operators and proximity searching. Here's a practical example. If you're looking for recent work on machine learning applications in clinical diagnostics, a basic topic search returns thousands of results, many of them tangentially related. A refined query like TS=(machine learning AND diagnostic* AND clinician*) AND PY=(2018-2024) AND DT=(Article OR Review) typically drops that to a manageable range while keeping relevant papers intact. The exact count varies by the week you run it because new records get added constantly. The ResearcherID and ORCID linking features are also worth setting up if you plan to use this database regularly. They let you create a persistent author profile, merge duplicate name entries, and track your own citation impact. UW researchers sometimes skip this step, which causes headaches later when you're trying to export your own publication history or verify authorship for grant applications.
Get the Full Details

Exporting and Managing Your Results
When you're ready to pull records out, Web of Science gives you several export formats. EndNote, RIS, plain text, and tab-delimited are the standard options. For most people working in academic settings, RIS is the safest choice. It carries enough metadata to reconstruct references properly in EndNote, Zotero, or Mendeley without introducing corruption errors. One thing that catches people off guard: the default export only includes the bibliographic fields. Citation counts, Times Cited values, and full record data don't come through unless you explicitly select "Full Record and References" from the export options. I learned this the hard way during a literature review project when I exported three hundred records and then realized the citation counts were all blank. Re-exporting took another twenty minutes, which is time I don't get back.
Common Problems and How I Handle Them
The most frequent issue I encounter is the deduplication problem. Web of Science doesn't always merge records correctly when the same paper appears under slightly different author name formats or journal title variations. I ran into this specifically last year while compiling a bibliography on environmental policy interventions. The database split what should have been a single highly-cited paper into three separate entries with different citation counts attached to each fragment. The workaround was to sort by title, manually identify the duplicates across the results list, and then use the "Create Citation Report" function to see which version had the highest Times Cited count. That highest-count version was usually the correct merged record. Another issue is the gap in conference proceedings coverage. If your field relies heavily on conference publications rather than journal articles, Web of Science will underserve you. Computer science is the classic example. The Core Conference list helps somewhat, but many proceedings simply aren't indexed. In those cases, you need to supplement with Scopus or IEEE Xplore. I keep a cross-reference sheet where I note which databases returned which results during any serious search, so I'm not claiming completeness where none exists.
When Uw Web Of Science Falls Short
Be honest about what this database cannot do. It does not cover every discipline equally. It has known gaps in non-English language publications, though the Core Collection does include some multilingual coverage. It misses many preprint servers. It doesn't include gray literature like government reports or industry white papers unless they were published in an indexed source. If your research question depends on any of those materials, Web of Science alone will give you an incomplete picture, and you'll waste time convincing yourself the database is broken when it's actually doing exactly what it was designed to do. For systematic reviews, the PRISMA guidelines recommend searching at least two or three databases precisely because of these coverage gaps. I've seen reviewers who relied solely on Web of Science and then faced peer review criticism for incomplete search strategy documentation. Don't be that reviewer.
A Few Practical Details That Save Time
The saved search feature is underused. If you're running iterative searches over weeks or months, save your query strings and set up email alerts for new results. The alerts go to your UW email and usually arrive within forty-eight hours of new indexing. This replaces the old habit of manually re-running searches every Friday afternoon. The Cited Reference Search is another feature that people overlook. Instead of searching for a paper by title, you can search by the references it contains. This is useful when you only know a key paper's content or its bibliography but not its exact title. It's slower than a standard topic search, but it catches papers that a keyword approach would miss entirely. For bulk operations, the "Send to Clipboard" function lets you accumulate records across multiple searches before exporting. I typically run three or four related searches, add the relevant results to the clipboard from each, and then export everything at once. It's more efficient than exporting individual search results separately, especially when you're dealing with databases that impose per-export record limits.
The interface changes occasionally. Clarivate adds features, retires others, and rearranges menus without much announcement. What worked six months ago might be in a slightly different location now. The underlying search syntax hasn't changed significantly, which is the only thing that matters when you're trying to reproduce a search strategy for a methods section or a reproducibility supplement.