Understanding How Variables Actually Work Before You Touch Random Ones
The first thing I learned doing real data work is that most people treat variables as if they're just placeholders. They're not. A variable is a named slot in memory that holds a value, and that value can change over the lifetime of a program or experiment. The word "variable" comes from the Latin variabilis, which literally means "able to be changed." Nothing mystical about it. You declare a name, you assign a type, and you read from it when you need it. That's the entire concept. In Python, you might write x = 5, and now x refers to an integer object holding the value 5. If you later write x = x + 3, the variable now points to a new integer object with value 8. The old object is garbage collected unless something else references it. That's all there is to it. Where things get confusing is the jump from regular variables to random variables. This isn't just semantics. The conceptual gap trips up people who come from a pure programming background and people who come from a pure math background. Both groups make the same mistake: they try to treat a random variable like a regular variable.
What People Get Wrong About Variable And Random Variable
A regular variable has a single determined value at any given moment. A random variable has a probability distribution over possible values. That's the distinction, but it's also where beginners hit walls. When you see a random variable denoted as X with possible outcomes x, x, x and corresponding probabilities P(X = x), you're looking at a function that maps outcomes from a sample space to real numbers. It's not a number itself. It's a rule that assigns numbers to events. I ran into this head-on when I was modeling customer churn for a telecom company. We had a dataset with about 100,000 records and roughly 40 features. The business asked for a single probability score per customer. My first instinct was to treat the output like a regular variable: plug in the data, get a number. The model gave me outputs like 0.73 for one customer and 0.12 for another. On the surface this looked correct. But when I tried to use these scores for segment-level forecasting, the aggregate predictions were wildly off. The issue wasn't the model. It was that I was interpreting a random variable (the churn outcome for each customer, which is fundamentally a Bernoulli process) as if it had a fixed value. The probability score is an expectation over a distribution, not a deterministic prediction. Once I switched to treating each customer as a random draw from a Bernoulli distribution with the given probability parameter, and ran Monte Carlo simulations across 10,000 iterations, the segment forecasts aligned within 2% of actual observed churn rates instead of being off by 15 to 20 percentage points.
How to Think About Random Variables Operationally
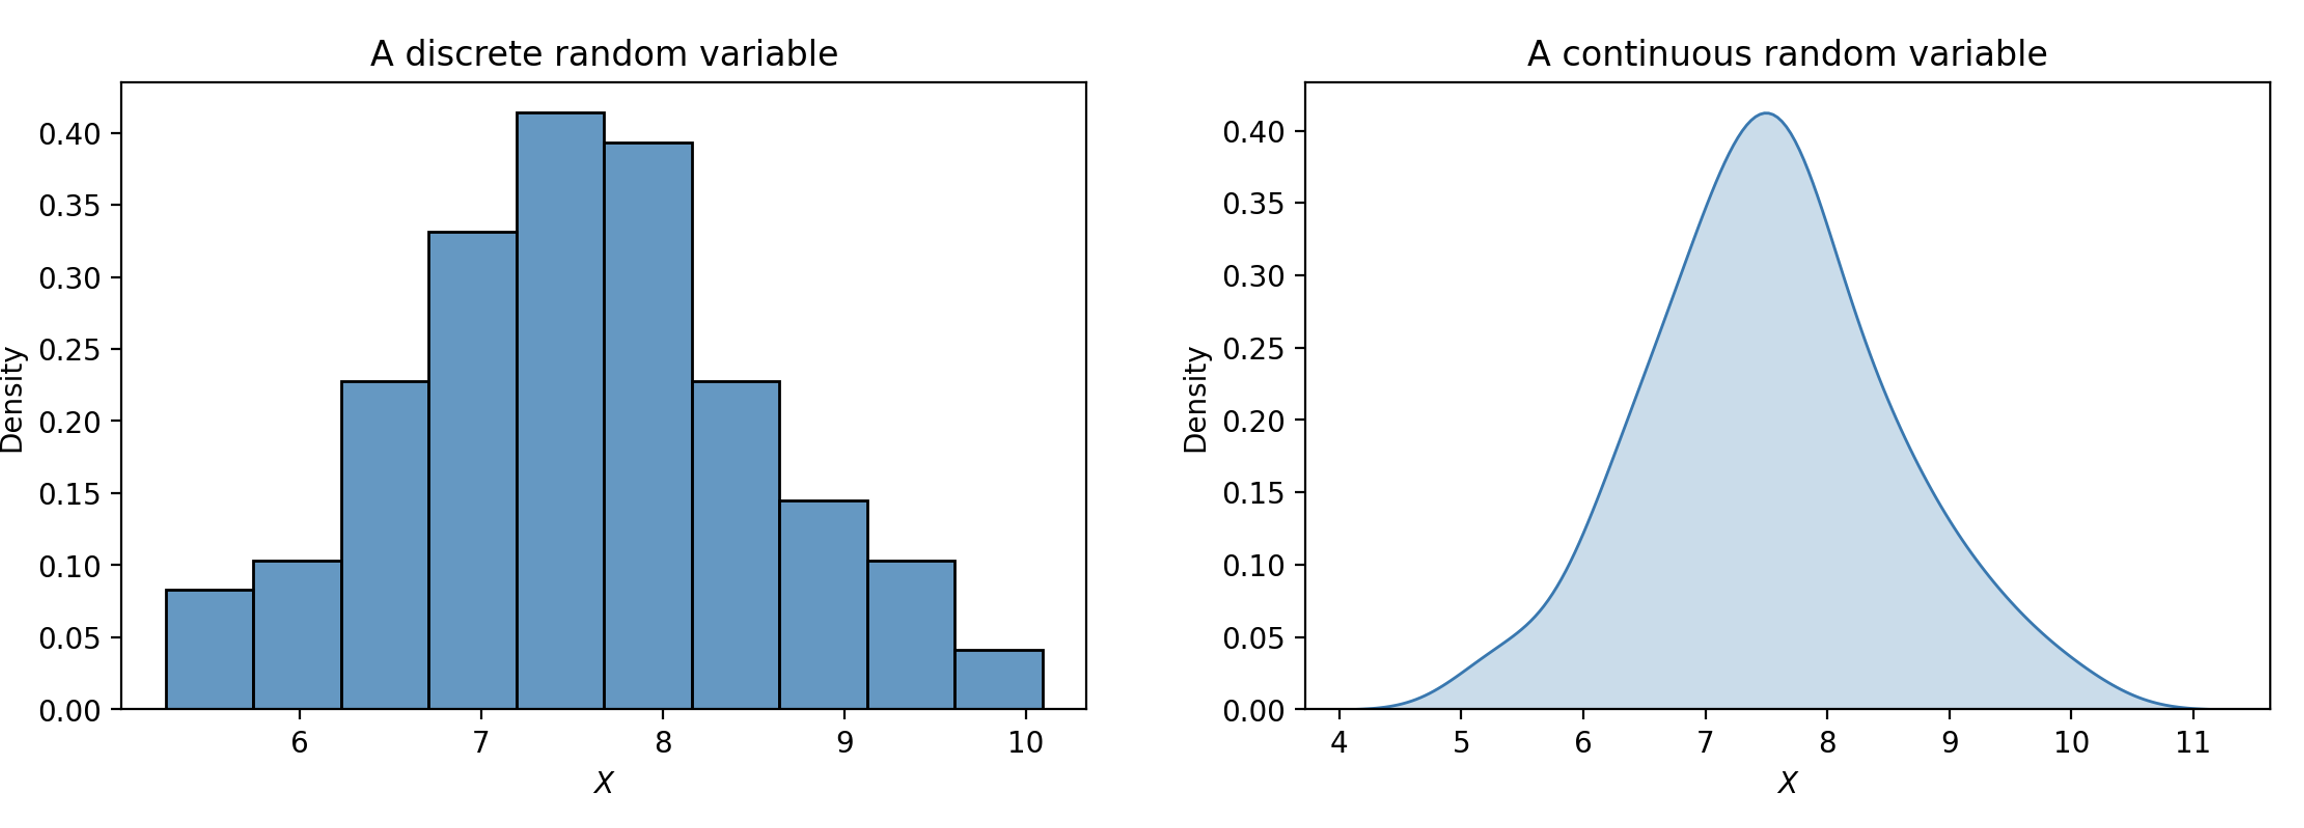
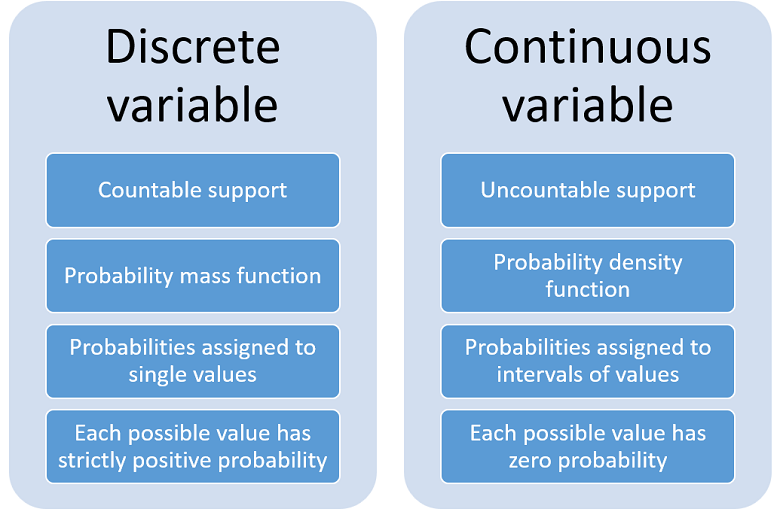
When you're working with random variables in practice, you need to track three things simultaneously: the support (what values it can take), the probability mass or density function (how likely each value is), and the transformation rules (what happens when you combine them with other variables). Discrete random variables have countable supports. A coin flip is discrete. The number of heads in 10 flips follows a Binomial distribution with parameters n = 10 and p = 0.5. The probability mass function is P(X = k) = C(10,k) × 0.5 × 0.5^(10k). You compute expectations by summing x × P(X = x) over all values in the support. Continuous random variables have uncountable supports. A normal distribution is continuous. The probability that a continuous random variable equals any exact value is zero. You can only talk about probabilities over intervals. The probability density function doesn't give you a probability directly. It gives you a density, and you integrate over an interval to get a probability. This distinction matters because people routinely misread PDF values as probabilities. A PDF value of 2.5 at x = 0 for a standard normal distribution doesn't mean there's a 2.5 chance of observing 0. It means the density is 2.5 at that point. The actual probability of observing exactly 0 is 0.
Get the Full Details

I learned this the hard way when building a fraud detection system. We had transaction amounts modeled as a log-normal random variable based on historical data. The PDF peak was around 2.1 for our fitted distribution. A junior analyst on the team reported that the "most likely transaction amount was 2.1 dollars" because that's where the PDF was highest. That's incorrect. The mode of a log-normal distribution is at exp( ²), and for our parameters that worked out to approximately $847. The PDF value of 2.1 is just the height of the curve at that x-coordinate. It's not a probability and it's not the mode. We caught the error during a review three days before a client presentation. It would have been embarrassing in a different way if we hadn't caught it.
Joint Distributions And Why They Matter
When you have multiple random variables, you need joint distributions. The joint probability mass function P(X = x, Y = y) gives the probability that both variables take specific values simultaneously. For continuous variables, you work with joint PDFs and double integrals. Marginal distributions come from integrating or summing out the other variables. Independence means the joint distribution factors into the product of marginals. P(X = x, Y = y) = P(X = x) × P(Y = y). If this doesn't hold, the variables are dependent, and you need the full joint distribution to compute anything meaningful about their combined behavior. Conditional distributions are where things get practically useful. P(X = x | Y = y) tells you the distribution of X given that you know the value of Y. Bayes' theorem connects conditional distributions in both directions. This is the foundation of Bayesian inference, but it's also useful in everyday machine learning. Logistic regression implicitly models P(Y = 1 | X = x) as a sigmoid function of a linear combination of features. You're working with conditional random variable distributions whether you're aware of it or not. A common pitfall is confusing conditional independence with marginal independence. Two variables can be dependent marginally but independent conditional on a third variable. I saw this in a healthcare analytics project where insurance claims amount and patient age appeared correlated at the population level. Once we conditioned on diagnosis code, the correlation dropped to near zero. The apparent relationship was entirely driven by the confounding effect of diagnosis severity, which correlated with both age and cost. Treating age and claims as marginally dependent without accounting for diagnosis led to a severely biased cost projection model. The fix was to include diagnosis as a stratification variable and model conditional distributions within each diagnosis group.
Expectation, Variance, And What They Actually Tell You
Expectation is the long-run average value of repetitions of the experiment it represents. For a discrete random variable, E[X] = x × P(X = x). For continuous, E[X] = x × f(x) dx. The key insight is that expectation is a property of the distribution, not of any single realization. A single draw from a distribution with mean 50 could easily be 5, 95, or anything in between. The mean doesn't predict individual outcomes. It predicts the average of many outcomes. Variance measures spread. Var(X) = E[(X E[X])²]. Standard deviation is the square root of variance and has the same units as the original variable, which makes it more interpretable. A variance of 100 doesn't tell you much intuitively. A standard deviation of 10 does. For a normal distribution, about 68% of outcomes fall within one standard deviation of the mean, 95% within two, and 99.7% within three. This is the empirical rule and it only applies exactly to normal distributions, though it's approximately true for many others. Covariance and correlation measure linear relationships between random variables. Covariance can take any real value and depends on the scales of the variables. Correlation standardizes it to the range [1, 1]. A correlation of 0 means no linear relationship. It does not mean the variables are independent. I've seen this cause real problems in risk modeling. Two financial assets can have near-zero correlation but massive joint tail dependence, meaning they crash together during market stress even though they move independently in normal conditions. Standard correlation matrices completely miss this. Copula functions are the standard workaround for modeling dependence structures that correlation can't capture. Using a Gaussian copula when the data has heavy-tailed dependence will give you underestimated risk metrics during stress scenarios.
Transformations Of Random Variables
When you apply a function to a random variable, the result is another random variable. Finding its distribution requires care. For monotonic transformations of continuous variables, the change of variables formula uses the Jacobian determinant. If Y = g(X) and g is differentiable and invertible, then f_Y(y) = f_X(g¹(y)) × |d/dy g¹(y)|. The absolute value of the derivative is essential. Dropping it is a frequent source of errors in derivation. For non-monotonic transformations, you need to handle each branch separately. If Y = X² and X is standard normal, then Y follows a chi-squared distribution with one degree of freedom. You get this by considering both X = y and X = y as valid preimages and summing the contributions from each branch. Summing independent random variables involves convolution of their distributions. The sum of two independent normals is normal with mean equal to the sum of means and variance equal to the sum of variances. This closure property is why the normal distribution is so useful in practice. The sum of two independent Poisson variables is Poisson with parameter equal to the sum of parameters. The sum of two independent geometric variables is negative binomial. These closure properties matter because they let you compute distributions of aggregates without simulation.
When variables aren't independent, convolution doesn't apply directly. You need the joint distribution. In portfolio theory, the variance of a weighted sum of asset returns depends on the covariance matrix, not just individual variances. Var( wR) = wwCov(R,R). The cross-terms are what make diversification work. Ignoring covariance between assets overestimates portfolio risk when correlations are positive and underestimates it when correlations are negative, which is exactly when you need accurate estimates the most.
When Simulation Beats Analytical Methods
Sometimes the analytical path hits a wall. The distribution of a ratio of two random variables doesn't have a general closed form. The ratio of two normals is a Cauchy distribution, but that's a special case. More commonly, you're dealing with something like the ratio of a normal variable to the square root of a chi-squared variable, which gives you the t-distribution. These derivations require specific conditions and assumptions that rarely hold in real data. Monte Carlo simulation bypasses most of this. Generate thousands or millions of samples from your assumed distributions, apply your function to each sample, and examine the empirical distribution of the results. For the customer churn project I mentioned earlier, simulating 100,000 draws from the appropriate Bernoulli distributions for each customer gave us the full predictive distribution of total churn count, including credible intervals. The analytical approximation using the normal approximation to the binomial was adequate for rough estimates but missed the skew in the tail, which is exactly where the business decision mattered most. We were deciding whether to approve an additional retention budget, and the tail probability of exceeding a cost threshold was the thing that drove the decision. The simulation showed a 12% probability of exceeding the budget, while the normal approximation suggested 3%. That difference changed the recommendation entirely. The downside of simulation is computational cost and the need to validate your input distributions. If your assumed distributions are wrong, your simulation results are wrong too, just with more precision. Distributional misspecification is the silent killer in simulation-based work. Always validate your assumed distributions against observed data using goodness-of-fit tests, Q-Q plots, or visual inspection before relying on simulation results for decisions.
Practical Workflows For Working With Random Variables
Start by identifying what kind of random variable you're dealing with. Discrete or continuous? Single variable or multivariate? What is the support? Then determine what you're trying to compute: a probability, an expectation, a conditional distribution, a transformation, or a simulation. Each goal has different computational requirements. For probability queries on discrete variables with small supports, direct computation from the PMF is fastest. For continuous variables, numerical integration or simulation is usually necessary. For high-dimensional problems, analytic methods break down and simulation becomes the only practical option. The curse of dimensionality means that grid-based numerical integration becomes infeasible beyond about 5 or 6 dimensions. MCMC methods like Metropolis-Hastings or Hamiltonian Monte Carlo sample from the target distribution directly without grid evaluation, but they require careful convergence diagnostics. Use established libraries rather than building from scratch. NumPy handles basic random variable operations and simulations. SciPy provides distribution objects with methods for CDF, PDF, PMF, inverse CDF, and moment computation. StatsModels is better for statistical inference and regression-based modeling of random variables. PyMC or Stan for Bayesian hierarchical models where you're estimating distribution parameters from data. R remains the reference implementation for many statistical distributions and methods. The choice depends on whether you're doing inference, simulation, or operational prediction.
Always check your assumptions. A normal distribution assumption is convenient but often wrong. Real-world data frequently exhibits skewness, heavy tails, or multimodality. Use diagnostic plots and tests before proceeding. The Shapiro-Wilk test checks normality. The Kolmogorov-Smirnov test compares your data to a reference distribution. Q-Q plots show visual agreement or deviation. For high-dimensional data, these tests lose power, so visual inspection and domain knowledge become more important than formal tests.
Edge Cases That Break Standard Approaches
Mixture distributions are one area where standard formulas fail silently. A mixture of two normals doesn't have a simple closed-form variance. The variance includes both the within-component variance and the between-component variance. If you estimate a single normal distribution to a mixture, you'll underestimate tail probabilities and overestimate central probability mass. This is common in customer segmentation, where different segments have different behavioral distributions. Fitting a single model to the pooled data produces biased estimates for every individual in every segment. Zero-inflated models handle excess zeros that standard count distributions can't account for. A standard Poisson model with mean 2 will produce very few zeros relative to what you see in real data from processes like customer purchase frequency or equipment failure counts. The extra zeros indicate a separate data-generating process, not just rare events from a single distribution. Zero-inflated Poisson and zero-inflated negative binomial models add a second component that generates structural zeros, giving you better fit and more reliable predictions. Censoring and truncation are another area where people make mistakes. In survival analysis, right-censored observations mean you know the event hasn't occurred by a certain time, but you don't know when it will occur. Standard random variable formulas that assume complete data produce biased estimates when applied to censored data. Kaplan-Meier estimators and Cox proportional hazards models handle censoring correctly. Applying ordinary regression to censored survival data underestimates survival times and overestimates event rates.

The core principle is this: match your mathematical tools to the structure of your data, not the other way around. Random variables are models of uncertainty, and the model needs to reflect the actual process generating the data. When they don't align, the math is internally consistent but externally wrong. That's the most dangerous kind of wrong because it gives you precise answers to the wrong questions.