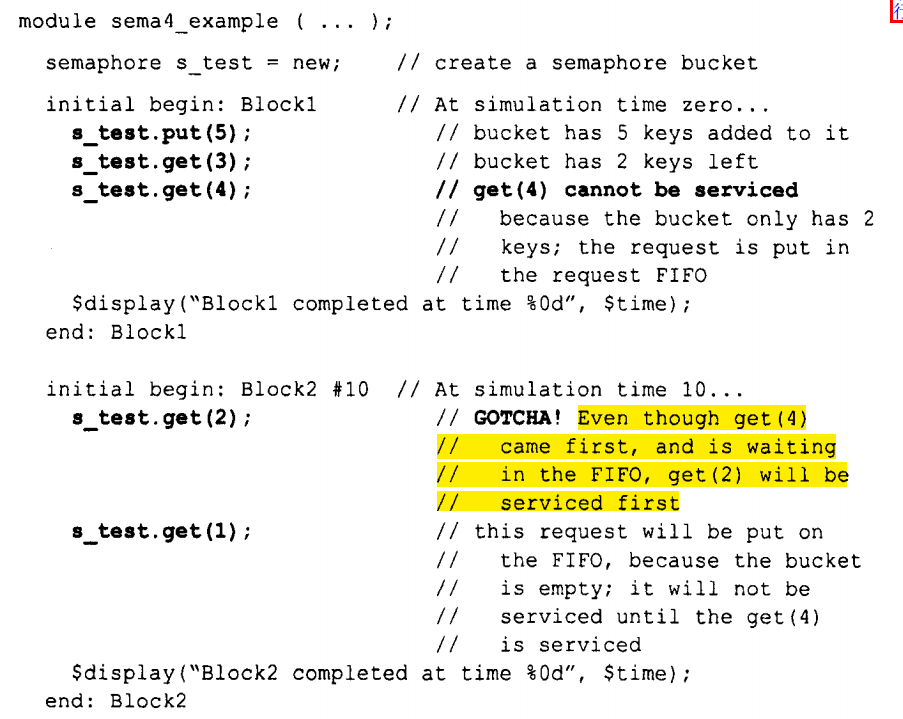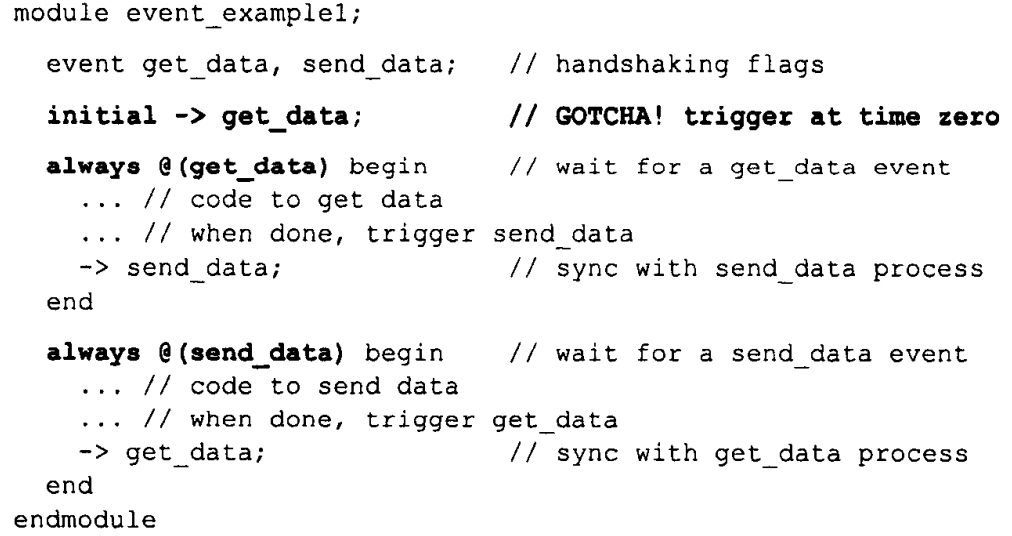
Most Verilog Bugs Aren't Logic Errors
They're synthesis ambiguities that silently compile into the wrong hardware. I spent three weeks debugging a UART FIFO that randomly dropped bytes on an Artix-7. The RTL looked correct. The simulator passed. The issue was a single inferred latch hidden inside a combinational always block with an incomplete sensitivity list. Got fixed in ten minutes once I stopped looking at the code and actually ran the synthesis tool's lint checks. Blocking vs non-blocking assignments is the oldest gotcha in the book but it keeps killing people. The rule is straightforward: use non-blocking (
=) for sequential logic and blocking (=) for combinational logic. The reason matters more than the rule itself. Non-blocking assignments evaluate the right-hand side at the start of the timestep and schedule the update for the end. Blocking assignments execute immediately and synchronously. When you mix them in the same always block, the evaluation order becomes unpredictable across simulators and synthesis tools. I once saw a state machine where two registers updated with blocking assignments produced different results between VCS and Vivado. Same code, different tools, different behavior. SystemVerilog made this slightly better by introducing variables and the var keyword, which default to wire-like behavior when used in combinational always blocks. It's still worth being explicit. Assigning with = in a combinational always@* block is fine as long as you never use
= in that same block. Once you do, you're playing Russian roulette with simulation synthesis mismatch.
Incomplete Sensitivity Lists
This is the latch-inference problem that eats up entire weekends. A combinational always block in Verilog must list every signal that appears on the right-hand side of its assignments. If you miss one, the synthesis tool infers a latch. Latches are illegal in most modern ASIC flows and cause timing nightmares in FPGAs. SystemVerilog's always_comb resolves this because the tool derives the sensitivity list automatically from the block contents. Here is the practical version of the fix that actually works in my experience. Stop writing always @(*) blocks entirely. Use always_comb for everything that should be combinational and always_ff for everything that should be sequential. The only time I use always @(*) now is when I'm maintaining legacy code written before 2008. Even then I convert it immediately. The tool will flag any missing signals as a compilation error instead of silently inferring hardware you didn't intend. I had a design where a multiplier output fed into a conditional assignment inside an always @(*) block. The multiplier input wasn't listed in the sensitivity list because it only appeared on the right side of an if statement. The tool inferred a latch. The post-synthesis simulation failed. The gate-level netlist took another week to debug. After switching to always_comb, the same design compiled cleanly and matched simulation on the first attempt.
Width Mismatches That Don't Warn You
Verilog does not require operand widths to match during assignment. If you assign a 32-bit signal to an 8-bit register, the tool truncates the upper bits without warning. This is by design in the language spec but it's one of the most destructive silent failures in digital design. I remember a project where a 16-bit address bus was accidentally driven by a 32-bit register. The upper 16 bits contained control flags. The truncation meant the address space wrapped around unpredictably. The chip worked at room temperature and failed intermittently at elevated temperature because timing paths through the unused bits affected the clock tree differently. SystemVerilog added the == and !== operators and strengthened assignment checking with some tools, but this is still tool-dependent. The practical workaround is to define all bus widths using parameters and then enforce those parameters with linting. I use Verilator's -Wwidth lint flags in pre-synthesis CI checks. Any width mismatch fails the build before it ever reaches simulation. This catches about 90 percent of width-related bugs that would otherwise surface during post-route timing closure.
Get the Full Details
Reset Style Wars
Asynchronous versus synchronous reset is the kind of debate that starts wars in verification meetings. Asynchronous reset clears flip-flops immediately when the reset signal asserts, regardless of the clock edge. Synchronous reset only clears on the active clock edge. Both are valid. The wrong choice for your target technology is what causes problems. FPGA vendors like Xilinx and Intel explicitly recommend synchronous reset because their flip-flop primitives don't support reliable asynchronous reset inference. ASIC libraries vary. Some standard cell libraries optimize for asynchronous reset because it reduces clock tree load. The real issue isn't which one is better. It's mixing styles within a single design. If your top-level reset is asynchronous and an internal module expects synchronous reset behavior, you get recovery time violations that simulation won't catch because most simulators model reset with ideal zero-delay behavior. The approach I use now is to define a single reset policy per project and enforce it with a coding standard. All top-level resets are synchronous. Internal modules accept both and map the external reset through a synchronous synchronizer chain. I use three flip-flops for the sync chain to meet MTBF targets on metastability. This adds about 3 clock cycles of reset deassertion delay, which is usually acceptable. If your design has hard timing constraints on reset release, you'll need to analyze the specific path delays rather than relying on the synchronizer chain.
Generate Blocks and Scope Confusion
Generate blocks in Verilog-2001 and SystemVerilog are powerful but they create separate scopes that trip up anyone who hasn't worked through a full parameterized module instantiation before. Signals declared inside a generate block are not visible outside it. This means you can't directly connect a generate-block-internal signal to a port map in the same scope. You have to route it through a wire declared at the parent level. I encountered a bug where a parameterized multiplier bank had 16 instances controlled by a generate-for loop. The output wire was declared inside the generate block. When I tried to feed it into a downstream adder tree, the tool silently created new intermediate wires instead of connecting them. The resulting hardware had floating outputs on half the multiplier banks. The fix was to declare a separate output bus at the module level and assign it from within the generate block using a continuous assignment. It adds two lines of code per generate structure but eliminates an entire class of connection bugs.
Case Statement Default Behavior
A missing default case in a combinational case statement doesn't always infer a latch. It depends on the tool and the Verilog standard version. In Verilog-1995, a missing default creates a latch for any output bit that isn't assigned in all branches. In SystemVerilog, the behavior is more consistent but not universally safe. Some tools will emit a warning and infer a latch. Others will silently assume an all-zeros default. This inconsistency is why linting tools exist and why you should never rely on tool defaults for safety-critical logic. The specific example that taught me this was a priority encoder where the encoding table had 15 out of 16 possible input combinations covered. The uncovered case was an invalid state that shouldn't occur in normal operation. The tool inferred a latch that held the previous encoding value. During a stress test with randomized stimulus, the FSM entered the uncovered state. The latched output persisted until the next valid input, causing a data corruption window that lasted approximately 200 nanoseconds. Post-synthesis simulation caught it but gate-level simulation took another three weeks to set up and run. Adding a default case with a safe value eliminated the latch and reduced the regression failure rate to zero.

SystemVerilog Assertions Without Coverage
Assertions are supposed to catch protocol violations and illegal states. They work well when they're actually checking something meaningful. The common mistake is writing assertions that pass in simulation but don't cover the failure conditions you care about. A cover property that only samples one edge of a handshaking protocol tells you nothing about race conditions on the opposite edge. An assert that checks for NULL pointers in a UVM environment won't catch a transaction that arrives one cycle too late. The workaround I use is to pair every assertion with a coverage point that tracks the same condition. If the assertion fires, the coverage should also increment. If the coverage doesn't increment after extended simulation, the assertion isn't exercising the condition it claims to check. This dual-track approach takes about 20 percent more code but catches assertion-only verification gaps that conventional functional coverage misses entirely. I've seen teams cut verification time from six weeks to three weeks using this method on a moderately complex AXI interconnect project.
Clock Gating Without Verification
Clocked gating saves power. Most FPGA and ASIC designs use it. The gotcha is that manual clock gating structures behave differently from what the synthesis tool generates when you leave it to infer clocks gates automatically. A manually instantiated AND gate as a clock gate will hold the clock low indefinitely if the enable signal is asynchronous to the clock. The flip-flop downstream sees no clock edge and the state machine freezes. The tool might not flag this because the gate structure itself is technically valid. The standard workaround is to use the vendor's dedicated clock gating cell. Xilinx calls them CDCE or IBUFGCE depending on the architecture. Intel calls them integrated clock gates. These cells include built-in transparency logic that prevents the enable signal from changing near a clock edge. Using them adds negligible area overhead and eliminates the entire class of frozen-state bugs. I switched an entire project from manual AND-gate clock enables to vendor IG cells and immediately lost two clock-domain crossing bugs that had been latent for months.
Multi-Clock Domain Crossing Without Proper Synchronization
Crossing signals between different clock domains is fundamentally a metastability problem. A single flip-flop synchronizer reduces the failure rate but doesn't eliminate it. The formula for mean time between failures involves the metastability time constant, clock frequency, and the number of synchronizer stages. Two stages typically give MTBF in the range of hundreds of years for moderate clock frequencies. One stage gives MTBF measured in days or weeks depending on the frequency ratio. The mistake I see most often is assuming that a two-stage synchronizer solves all CDC problems. It doesn't. A synchronizer only protects the first flip-flop from metastability. If you're transferring a multi-bit value, each bit might metastabilize independently and reach a stable state at different times. The receiving logic sees a temporary invalid value. The fix is to use a handshake protocol or a Gray code counter for multi-bit transfers. Single-bit control signals can use a synchronizer. Everything else needs a proper protocol. I debugged a SPI-to-AXI bridge where the write data was transferred across clock domains using a simple two-FIFO approach without Gray encoding the pointer. The FIFO appeared to work in simulation because the testbench used ideal zero-skew clocks. On silicon, the clock phase difference caused the read and write pointers to briefly disagree on multiple bits simultaneously. The FIFO reported empty when it was actually full. Data corruption occurred at a rate of approximately one byte per thousand transactions. The fix was converting the pointer to Gray code before synchronization. It added four gates and eliminated the corruption entirely.

Timing Constraints That Don't Match Reality
Static timing analysis is only as good as the constraints you provide. A common pattern is to constrain the clock period based on the nominal frequency without accounting for clock uncertainty, input delay, or output delay. The tool reports positive slack and you ship the design. Post-route timing fails because the actual corner conditions weren't modeled. The practical approach is to constrain every clock domain explicitly, include setup and hold uncertainty values from the datasheet, and define input and output delays based on the actual board routing and partner chip specifications. I typically add a 10 to 15 percent margin on top of the theoretical maximum frequency. This rarely causes issues in synthesis and almost always prevents timing closure surprises during implementation. The trade-off is slightly lower achievable frequency, which is usually acceptable compared to the cost of a respin.
Finite State Machine Encoding Choices
Verilog allows you to specify state encoding through directives like synopsys state_encoding or systemverilog enum with attribute hints. The default encoding is usually binary or gray depending on the tool. The choice affects logic depth, power consumption, and timing. One-hot encoding uses more flip-flops but reduces combinational logic depth. Binary encoding uses fewer flip-flops but may require more complex next-state logic. The right choice depends on the constraint you're optimizing for. I had a FSM with 64 states running at 200 MHz on a high-performance FPGA. The default binary encoding created a combinational path that violated timing by 0.8 nanoseconds. Switching to one-hot reduced the path to 0.3 nanoseconds and met timing with 1.2 nanoseconds of slack. The flip-flop count increased from 6 bits to 64 bits, which was acceptable because the FPGA had abundant resources. This type of trade-off analysis should happen during the architecture phase, not after timing fails during implementation. The fundamental issue across all of these gotchas is that simulation doesn't catch hardware-level problems. The simulator runs fast enough that you can verify functional correctness. It doesn't model timing, metastability, synthesis inference quirks, or tool-specific behavior differences. Every bug described above survived simulation and surfaced during or after implementation. The mitigation strategy is consistent: lint early, constrain properly, use vendor-recommended primitives, and never assume the tool will warn you about something it shouldn't have silently done.