What This Actually Is
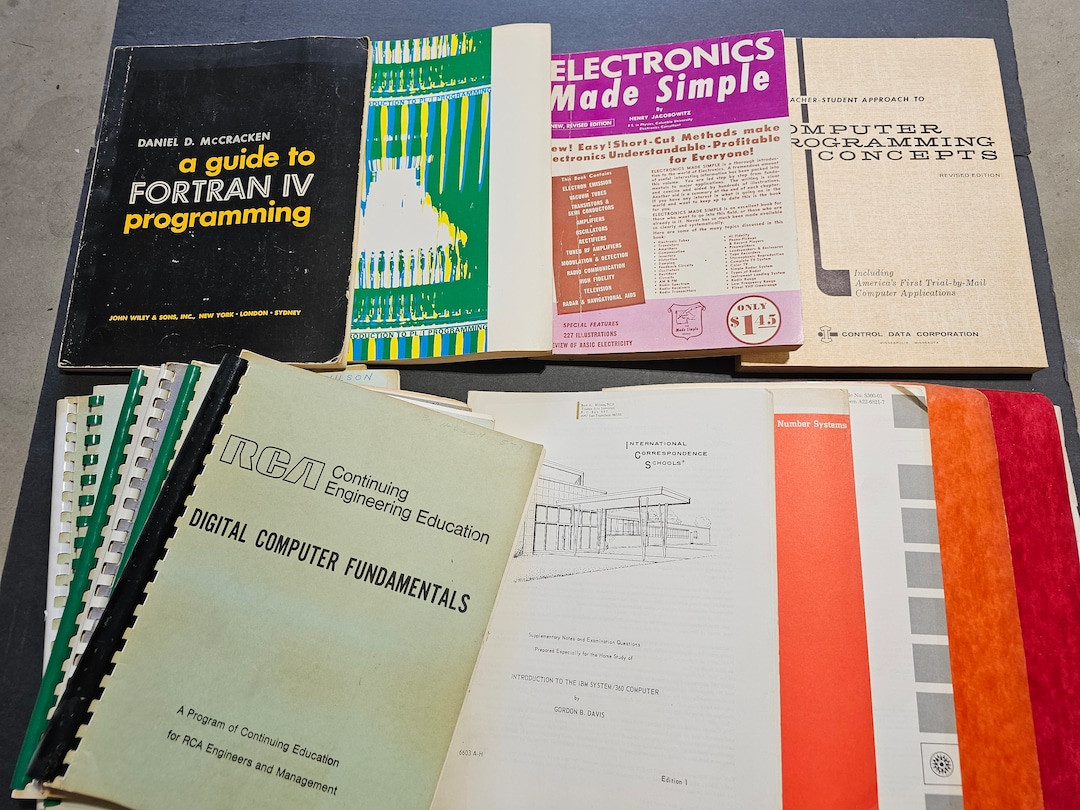
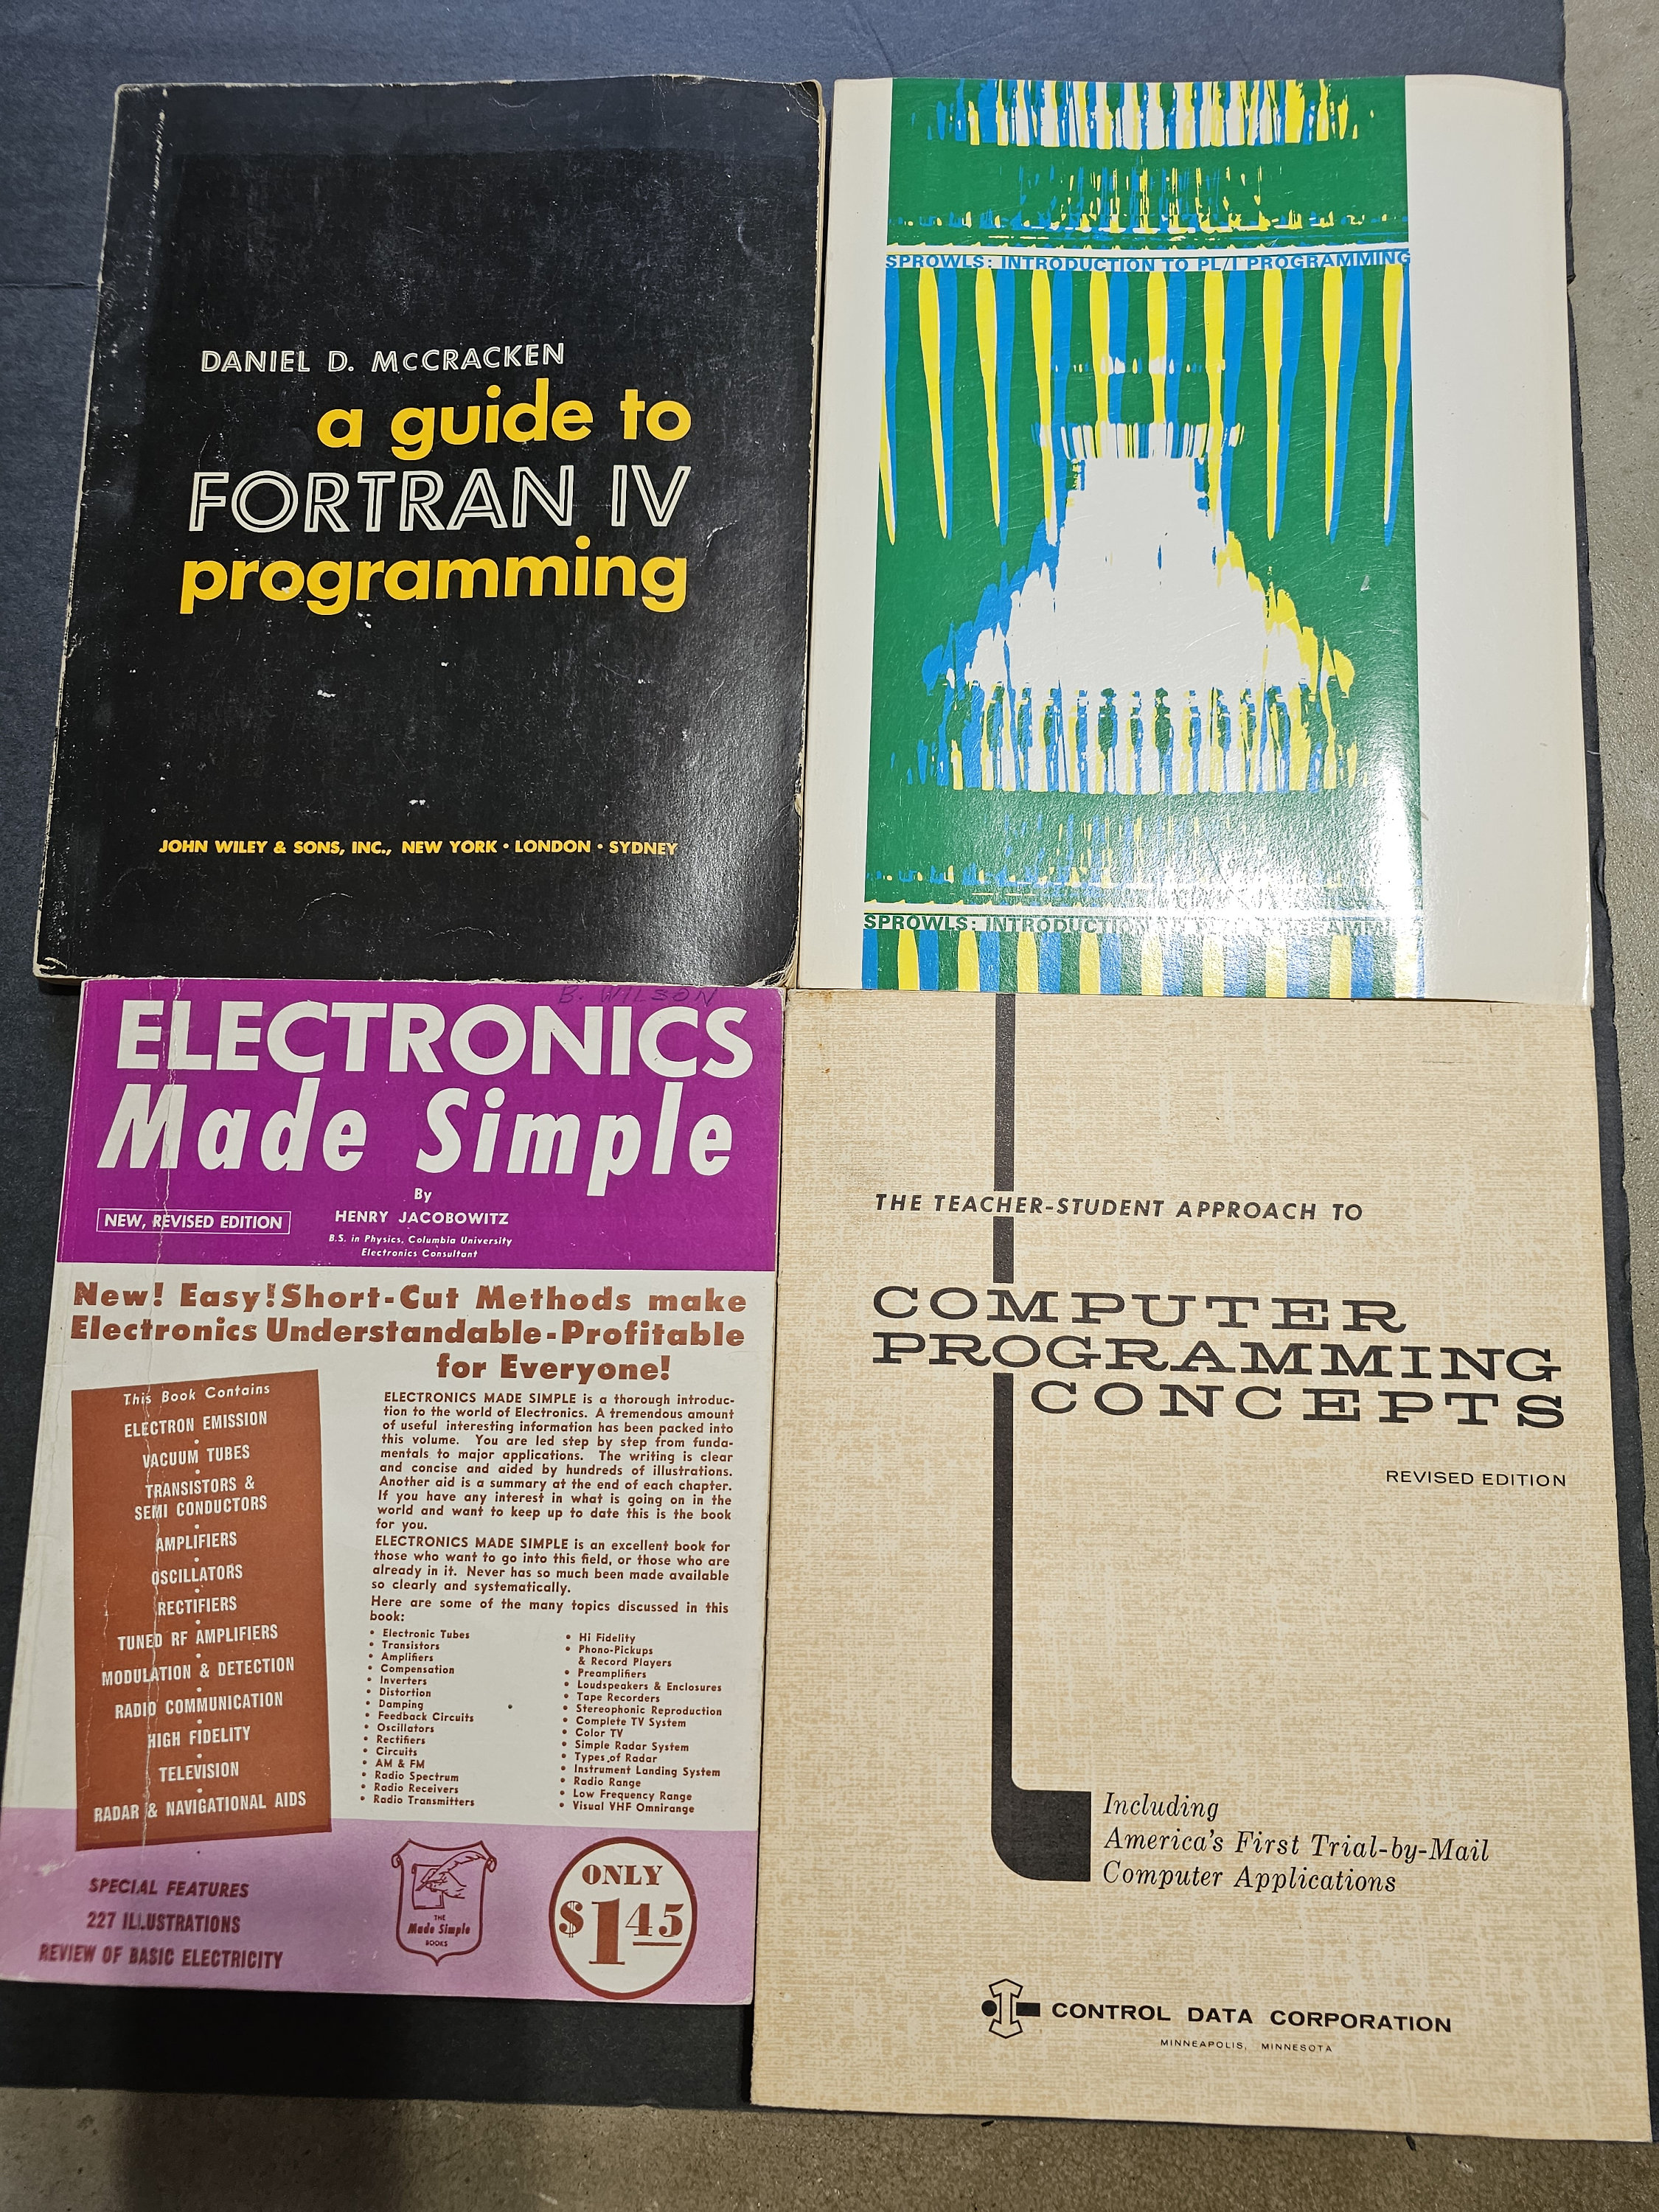
Vintage Coding Pdf is a term that keeps floating around in legacy software circles. It refers to compiled or archived documentation from older programming environments—think COBOL mainframe manuals, punch-card era reference guides, and early microcomputer programming books that were digitized into PDF format. These aren't always official publications. A lot of what circulates under this name comes from scanner dumps done by hobbyists, archive groups, and people who spent years maintaining old code repositories before moving on. The file itself is usually just a PDF, but the content inside can vary wildly in quality. Some are clean scans of actual technical documentation. Others are haphazardly OCR'd text files with tables broken apart and footnotes dropped. If you've ever tried to work from one of the bad ones, you know the feeling of searching for an index that doesn't exist.
Vintage Coding Pdf
I've been pulling from these archives for a while now, mostly because companies still have production COBOL and Fortran systems running that nobody under forty knows how to touch. One thing I learned the hard way: always check the file timestamp and compare it against known publication dates. A lot of "vintage" PDFs are actually recopies of recopies, degraded through multiple scans and re-uploads. The text becomes unsearchable, the margins get cropped, and the page numbers stop matching the original document. I once spent three hours trying to trace a syntax error in a 1987 RPG II manual only to realize the PDF I was reading was a blurry scan of a photocopy of a scan from 2003. Switched to the original published version from the ACM Digital Library and the same section was crystal clear. The workaround for this is to cross-reference page numbers and table of contents entries against at least two independent sources before committing to a file. Another thing nobody talks about is font encoding. Older PDFs sometimes use custom or embedded fonts that don't map correctly to standard Unicode. Copy-pasting from these documents often produces garbage characters, especially around special symbols like division signs, Greek letters, or COBOL-specific notation. If you need to quote or reference specific code snippets, use the search function instead of copying. It's slower but it actually works. The practical use case for this material is mostly around migration projects and legacy system maintenance. If you're dealing with a system that hasn't been updated since the nineties and the original documentation is lost, a Vintage Coding Pdf can fill gaps that no modern source will cover. But there are real limitations. A lot of these files don't include the diagrams, schematics, or hardware connection charts that came with the originals. They were scanned as text-only. If your problem involves physical wiring, pinouts, or timing diagrams, you're going to be stuck unless you track down the full version somewhere else.
I also found that some of the more useful documents circulate under different names depending on which archive you find them in. The same IBM AS/400 programming manual might show up as "QPTI Programming Guide," "Control Tower Reference," or just a numbered filename with no context. Building a personal index with cross-references between these alternate titles saved me probably twenty hours over a year of searching. I keep a simple spreadsheet with columns for original title, alternate titles, approximate year, source URL, and file quality notes. It's not glamorous but it works.
Get the Full Details