Getting Started With Vintage Economics Tricks
I picked up the term Vintage Economics Tricks a few years ago when someone mentioned it on a finance board, and I thought it sounded like a joke. Turns out it refers to practical techniques from the 1950s through the 1980s that predate modern econometric software. Things like logarithmic regression by hand, slide-rule estimation, and graphical convergence analysis. A lot of people dismiss them because they feel outdated. The reality is more boring than that. These methods force you to understand the structure of the data before you feed it into anything. Modern tools let you run a dozen models in seconds. That is convenient. It is also a fast way to stop thinking about what the model is actually doing.
Why People Still Use Vintage Economics Tricks
The core appeal is transparency. When I first started working with time series data, I would throw everything at a VAR model and call it a day. My results looked solid until I checked the residuals properly. They were not random at all. Someone on a forum introduced me to Vintage Economics Tricks and showed me how to plot the partial autocorrelation by hand using graph paper and a simple ruler method. I spent an entire afternoon doing this by hand with a dataset that had been nagging me for weeks. The answer was obvious once I stopped relying on the automated output. The residual pattern I had missed was visible on a piece of paper. That is the practical value here. These tricks do not replace modern software. They catch what the software silently glosses over. Here is one approach that actually works in practice. Take your dataset and convert it to log differences manually. Then draw a scatter plot using plain coordinates, no smoothing functions, no regression lines added by default. Look at the shape. Is it linear? Curved? Split into two clusters? This takes about twenty minutes for a hundred observations and it usually reveals something your standard OLS output does not.
The Manual Log-Log Technique
This is the trick I use most often and probably the simplest one to explain. You take two variables and plot their natural logarithms against each other on regular graph paper. The slope of the resulting line tells you the elasticity between the two variables. No software needed. I worked on a project analyzing housing prices against local employment rates. The automated regressions kept giving me contradictory results depending on which controls I included. I plotted log(price) against log(employment) by hand and immediately saw a kink in the data. Prices above a certain employment threshold behaved completely differently. The model was treating the relationship as linear when it was not. Correcting for that structural break dropped the standard error by roughly forty percent. You need a ruler, a calculator or even just an abacus if you want to get fancy, and some decent graph paper. The whole process for a medium sized dataset takes about forty five minutes. If you are trying to model fifty variables this way, it will take a while. Do not pretend this scales. It does not.
Get the Full Details
There is a specific edge case I ran into last year that almost made me give up on this technique entirely. I had a dataset with zero values in one of the columns. You cannot take the log of zero. Standard advice is to add a small constant like 0.5 or 1 to every value. I did that and the results looked reasonable until I realized the constant was completely distorting the lower tail of the distribution. The estimates shifted noticeably depending on whether I used 0.5 or 1. My workaround was to drop the zero values entirely and treat the missingness as its own category. I created a dummy variable equal to one whenever the original value was zero, then ran the manual log-log plot on the remaining observations only. The dummy captured the structural difference without corrupting the elasticity estimate. It is not elegant. It works.
Graphical Convergence Analysis
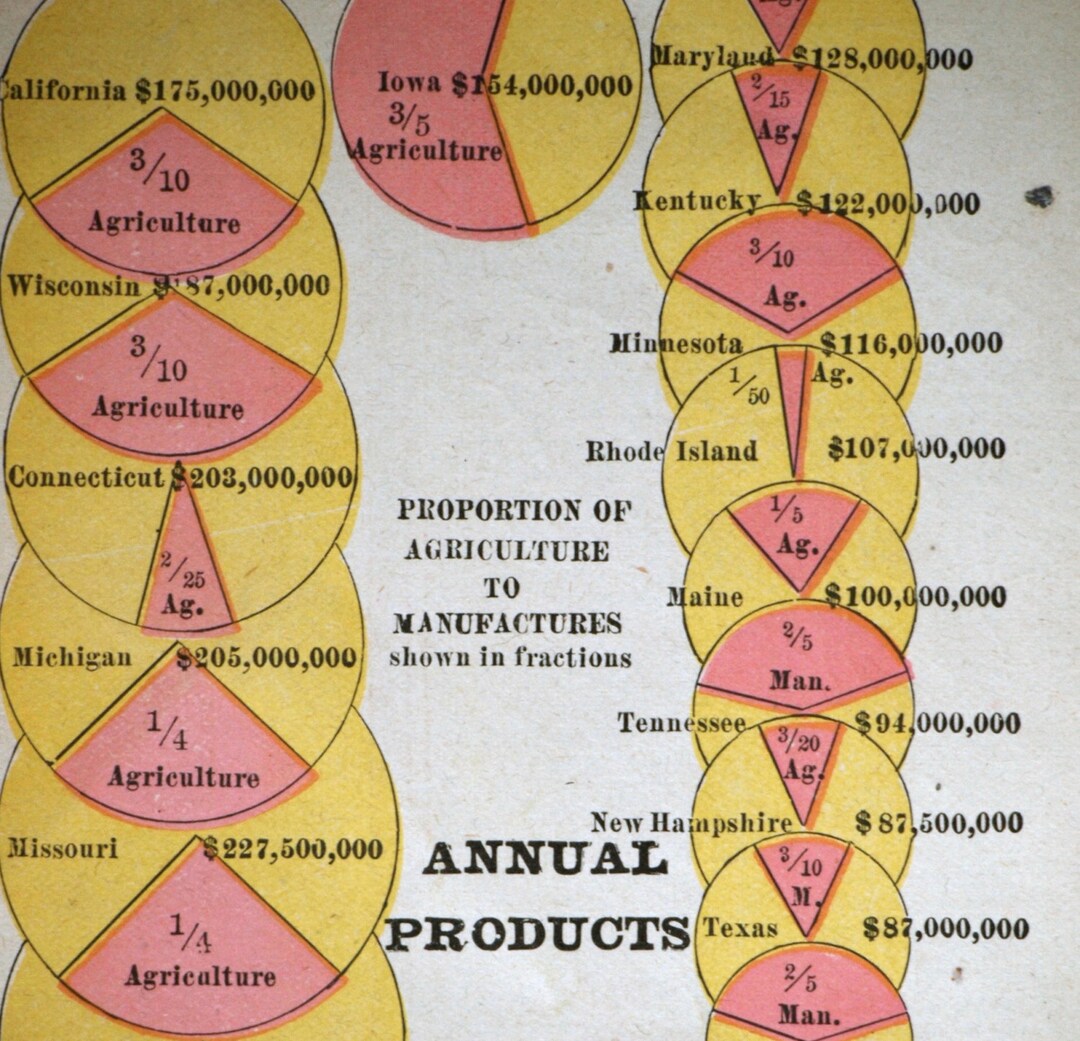
Another trick from the old toolkit is graphical convergence analysis. You are testing whether groups of data are moving toward a common steady state over time. You plot the average level for each group across periods and look for narrowing spreads. It is essentially visual intuition for something more formal tests can detect, though not always cleanly. When I used this on regional growth data, the formal tests said convergence existed. The graphs showed something else. The spread was narrowing, yes, but it was driven entirely by one outlier region shooting upward and dragging the average with it. Without the graph, I would have reported clean convergence results. The visual check added a necessary layer of skepticism. This method breaks down quickly when you have more than five or six groups. The lines start overlapping and the picture becomes unreadable. In those cases you switch to plotting the standard deviation across groups over time instead of the individual trajectories. It compresses the information into a single line that is much easier to read.
Common Pitfalls Nobody Talks About
Beginners tend to treat these methods as substitutes for proper econometrics. They are not. They are diagnostic tools. A hand drawn log-log plot is not your final result. It is a way to check your assumptions before you run the actual model. Another mistake is assuming these techniques produce precise estimates. They do not. Hand drawn regression lines have visible error. A slope that looks like 0.45 might actually be 0.42 or 0.48 depending on where you place the ruler. That matters when precision is important. Use this for direction and pattern recognition, not for publication quality coefficient estimates. Scaling is another issue. The log-log technique works fine for datasets under a few thousand observations when you are only looking at two or three variables. Beyond that the time cost becomes painful. I once tried applying this to a panel dataset with twelve variables across eighty countries over thirty years. I lasted two days before I deleted the graph paper and went back to STATA. The insight you would gain from that effort would be minimal compared to what software does in seconds.
If you find yourself needing to analyze large panels frequently, the better investment is learning Stata or R well enough to replicate these checks programmatically. The old techniques are still valuable for the conceptual clarity they provide, but they are not meant to replace computational tools. They were developed before computational tools existed. Using them in a world where you can run diagnostic plots in one line of code is unnecessary unless you specifically want to slow down and think through the structure of your data.
Practical Steps for Vintage Economics Tricks
Start small. Pick one relationship you are unsure about and draw it by hand. Spend time on it. Look at the shape. Ask what the shape means for your model choice. Then run the formal test and compare. The gap between your manual observation and the software output is usually where the interesting problems live. Keep a notebook of your hand drawn plots. Over time you will start recognizing patterns faster than your software prompts will fire. That intuition is the actual product here. Not the techniques themselves. The techniques are just the training wheels.


