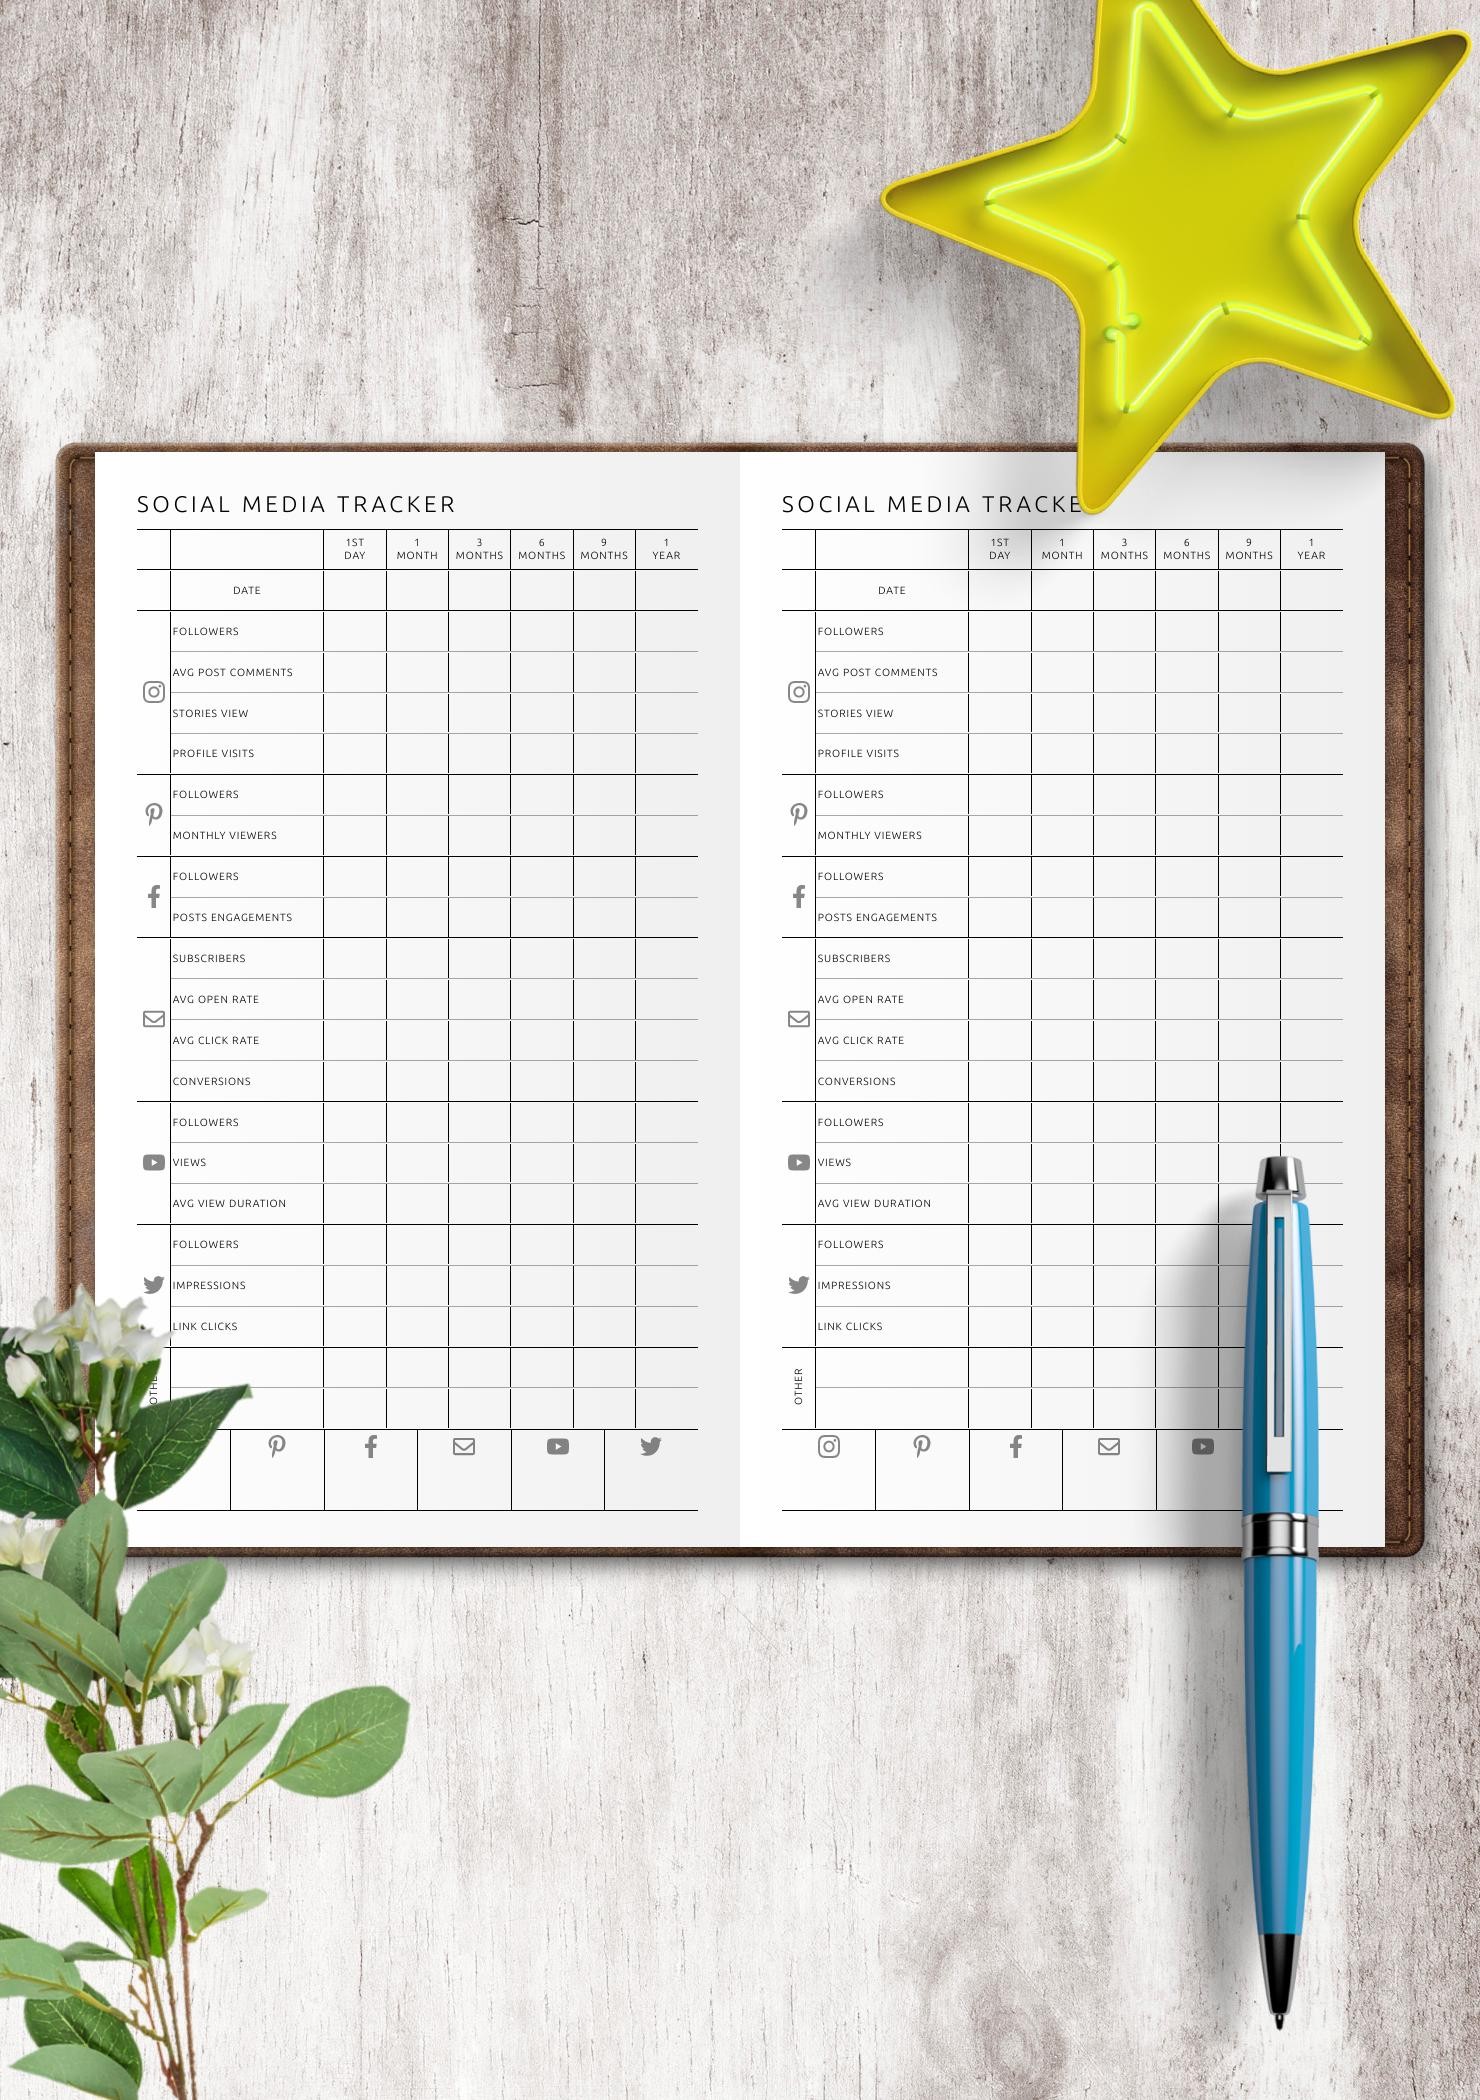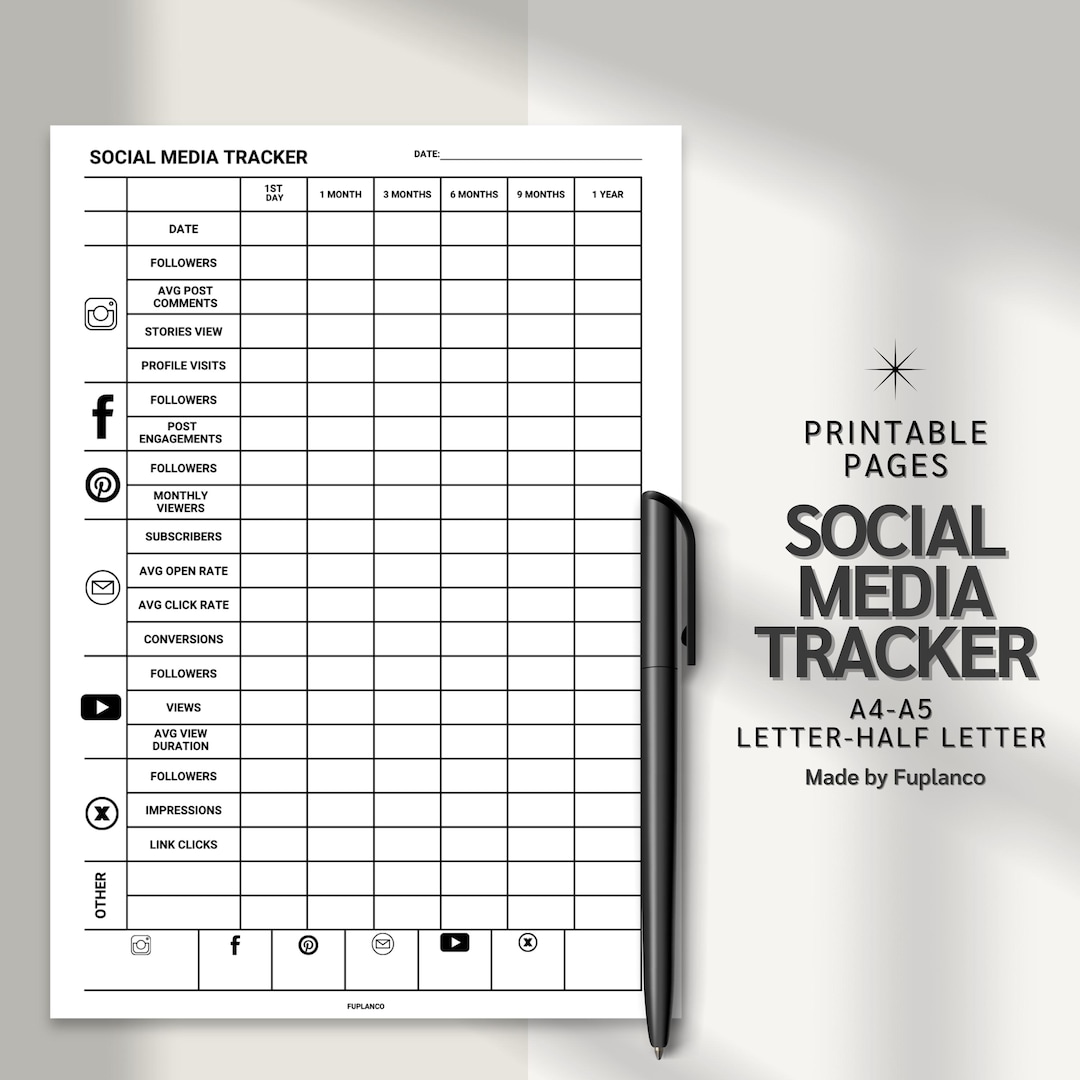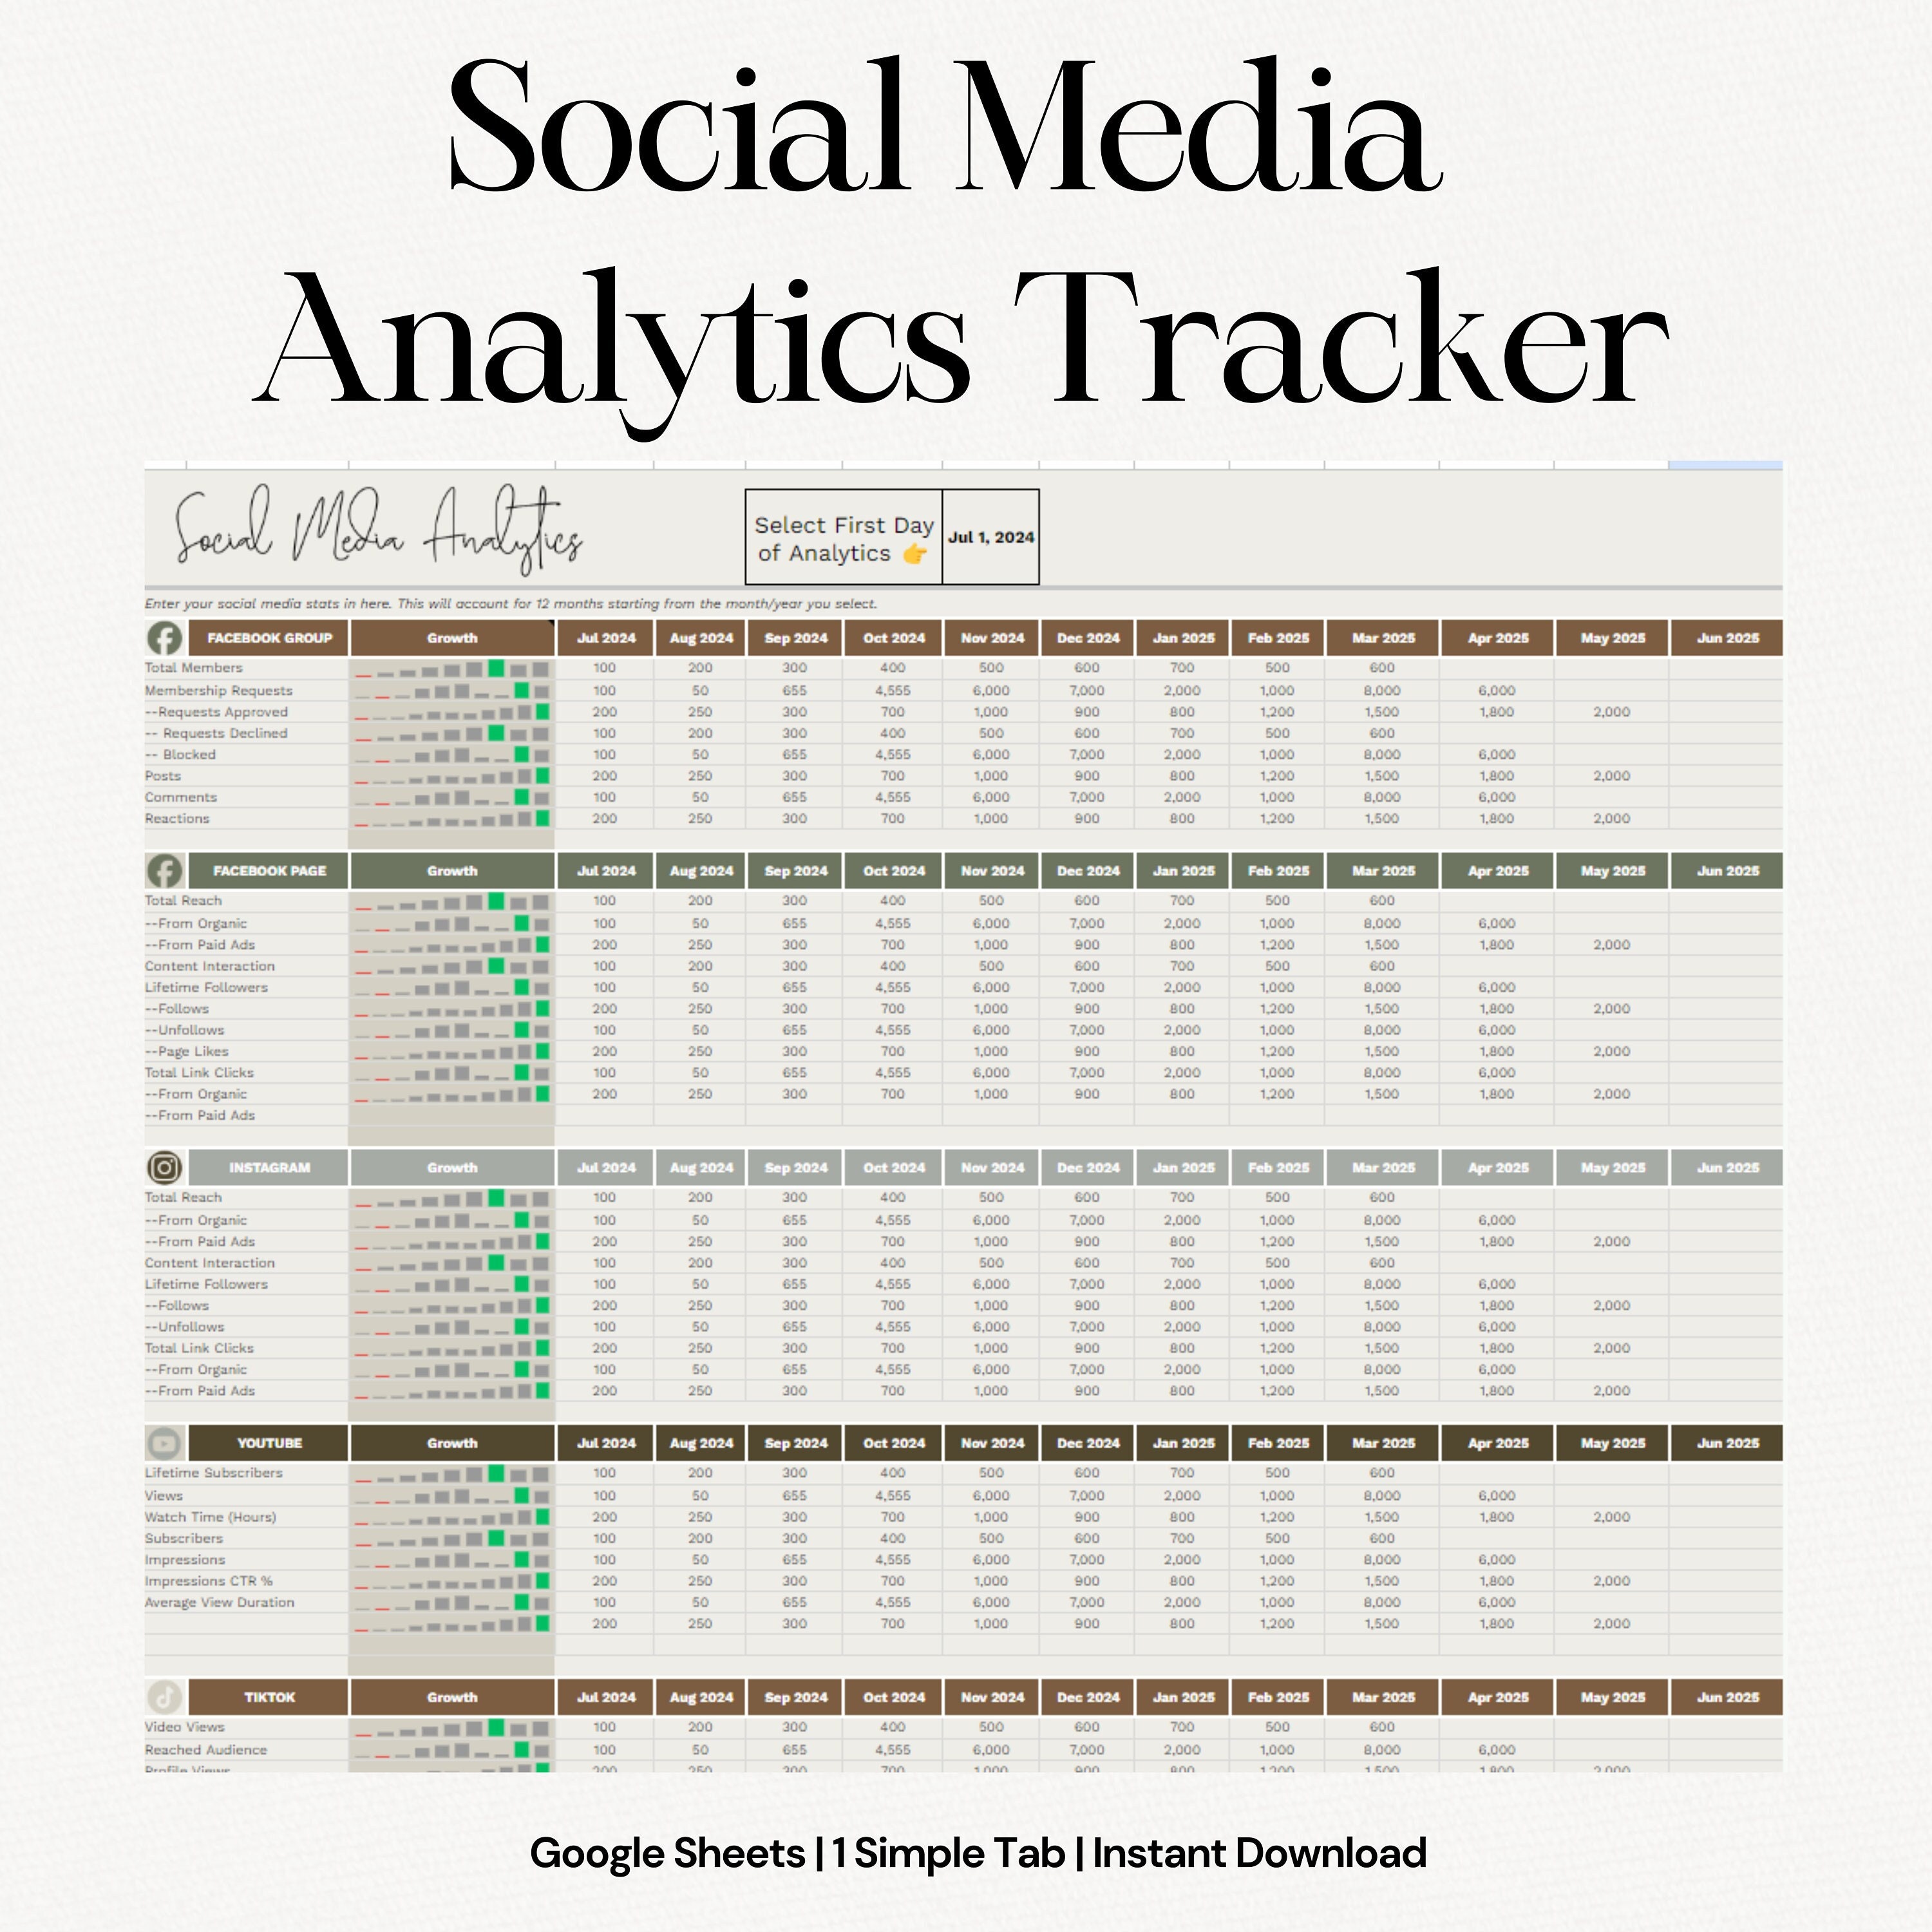
Setting Up a Vintage Social Media Management Tracker
Most people try to build a tracking system from scratch using spreadsheets, and it takes about three days to make it look decent and another month to realize it doesn't actually work when you have more than five accounts. A Vintage Social Media Management Tracker is essentially a retro-styled dashboard for monitoring social performance across multiple platforms without relying on modern SaaS subscriptions that charge per seat and break when APIs change. The appeal isn't nostalgia. It's that these systems are typically self-hosted, database-driven, and don't require your data to leave your server. At its core, it's a combination of a cron job pulling platform data through legacy or open API endpoints, a lightweight web interface styled to look like a 2012-era admin panel, and a SQLite or PostgreSQL backend storing daily snapshots. You define your platforms, set your tracking windows, and the system aggregates reach, engagement rate, follower delta, and top-performing content into a consistent report. Nothing fancy. That's the point. I built one for a client managing twelve accounts across four clients back in 2019. They wanted something they could audit themselves without trusting a third-party tool. We went with a Python backend pulling from the Twitter API v1.1 endpoint and Facebook's graph API, storing daily aggregates in PostgreSQL. The interface was Django-admin with a custom template. Total monthly hosting cost: eight dollars on a DigitalOcean droplet.
How to Build and Run One
The stack I keep going back to is Python with Flask or Django, cron-based pulls, and SQLite for solo use or PostgreSQL for multi-client setups. Here's the working process: Start with a requirements.txt file containing requests, schedule or APScheduler, and either psycopg2 or sqlite3. Build a scraper module for each platform. Instagram won't give you clean API access anymore unless you're on a Meta Business partnership tier, so most people in the vintage tracker space scrape their own dashboard exports or use the IFOSS toolchain. LinkedIn is the same story. For Twitter, the v1.1 API still works for read-only account stats if you have an old developer account. Facebook graph API v12+ still returns page insights. YouTube Data API v3 works fine for channel metrics. TikTok is the hardest one to track without official access, so I just pull from their analytics export feature manually and feed the CSV into the system. The database schema is straightforward. One table for account metadata, one for daily snapshots with columns for date, platform, account_id, followers, reach, engagements, impressions, and content_posts_count. Another table for individual post-level data if you want granular analysis. Index the date and account_id columns. Without proper indexing, queries across six months of daily data on twelve accounts will make your SQLite database crawl at around four seconds per report instead of the usual two hundred milliseconds.
The cron job runs once per day, preferably between 2 AM and 4 AM local time when API rate limits are least likely to be an issue. The script authenticates against each platform, pulls the day's snapshot, upserts it into the database, and then the frontend renders the dashboard. I use a simple Jinja2 template with Chart.js for line graphs and a table view for raw numbers. Deployment is literally rsync to a VPS and setting up the cron. Nginx reverse proxies port 80 to your Python app on port 5000. That's the whole infrastructure.
Get the Full Details

The Problem Nobody Warns You About
Here's a specific issue I ran into that took me a week to figure out. When you run daily follower counts for Twitter accounts, the API returns the follower count as of the exact second the request fires. If you run it at 9:15 AM on a Tuesday, your Tuesday snapshot is at 9:15 AM, but Wednesday's is also at 9:15 AM. That part seems fine. The problem is timezone handling. My PostgreSQL database was defaulting to UTC while my VPS was on EST. I thought the data looked wrong because one account showed a sudden drop of four hundred followers on a Tuesday. It wasn't a drop. It was a UTC-to-EST conversion error in my query template. The followers were fine. The display was off by twelve hours, which shifted data points between dates. The workaround was explicit timezone anchoring. I added a column to store the UTC timestamp of each snapshot and then used a WITH clause in my SQL to convert to the account owner's timezone before rendering. I also switched to running all cron jobs at midnight UTC and storing everything in UTC, then doing the timezone conversion only at the presentation layer. That eliminated the drift entirely.
Counter-Intuitive Insights
Most people optimize their tracker for reporting. They should optimize it for alerting. A system that just shows you pretty graphs doesn't help until something goes wrong. The real value is catching API auth token expirations before they silently stop pulling data, detecting when a platform's API structure changes and your scraper starts returning empty fields, and flagging when engagement rates drop below two standard deviations from your rolling thirty-day mean. I set up email alerts for the last two and log rotation alerts for the first. That saved me from losing an entire quarter of data on a client account because the Facebook access token had expired three weeks prior and no one noticed. The second thing beginners miss is that daily granularity is usually overkill. Most strategic decisions on social media happen on weekly or biweekly cycles. Storing daily data for two years on twelve accounts means you're sitting on roughly eight thousand rows per account. That's manageable, but if you add post-level data, which is where things get heavy, you're looking at hundreds of thousands of rows within a year. I switched to storing daily snapshots for thirty days and then aggregating to weekly buckets after that. The query complexity dropped significantly and the storage footprint shrank by about sixty percent. Retention policy matters more than people expect.
When This Approach Fails Completely
If you need cross-platform competitive intelligence, sentiment analysis, or real-time monitoring, this system isn't going to help you. It tracks your own accounts. Period. There are plugins you can add, but they bloat the setup and usually break when platforms update their authentication flows, which happens quarterly now. If you're managing more than twenty accounts across five different platforms and you need automated posting, content calendars, and team collaboration features, just buy a tool like Later or Sprout Social. A vintage tracker won't save you money at that scale. It's for people who need to see their own numbers in one place without paying forty dollars a month per seat or handing their credentials to a third-party service. The biggest bottleneck is maintenance. Every time Twitter or Facebook changes their API structure, which is more often than they advertise, your scrapers break. You need at least an hour a month checking logs and updating endpoints. If you're not prepared to do that work, the system will silently degrade and you'll be looking at incomplete data without knowing it until you need it most.
Getting the Code and Resources
There are a few open-source repos on GitHub that get close to a complete Vintage Social Media Management Tracker setup. The one I reference most often is a project called social-dashboard by a developer in Berlin who maintains it with community contributions. It covers the database schema, the cron integration, and a basic Flask frontend. You'll need to add your own platform-specific scrapers since those tend to rot faster than the core architecture. I keep a private fork with fixes for the current state of each API. The repo is licensed under MIT, so you can modify it without restrictions. If you don't want to build from scratch, there's also a Dockerized version that bundles Python 3.11, PostgreSQL, and nginx. It reduces the initial setup time from about six hours to roughly forty-five minutes if your server is already configured. The Docker Compose file handles the database initialization and volume mounts for persistent storage. Worth it if you're deploying more than one instance.
Quick Implementation Checklist
Get a VPS with at least two gigabytes of RAM and twenty gigabytes of SSD storage. Ubuntu 22.04 LTS is stable enough. Install Docker and Docker Compose. Clone the base repository. Set up environment variables for each platform's API credentials. Run the container stack. Check the daily cron output in the logs. Verify the first snapshot appears in the dashboard within six hours. Set up email notifications for failures. Review the data after two weeks and adjust your retention policy if you're approaching storage limits. That's roughly a two-day setup if nothing breaks on the first attempt, which it usually doesn't, but account for one evening of debugging the PostgreSQL connection string if you're new to it.