Working With Vintage Statistics Manuals in Practice
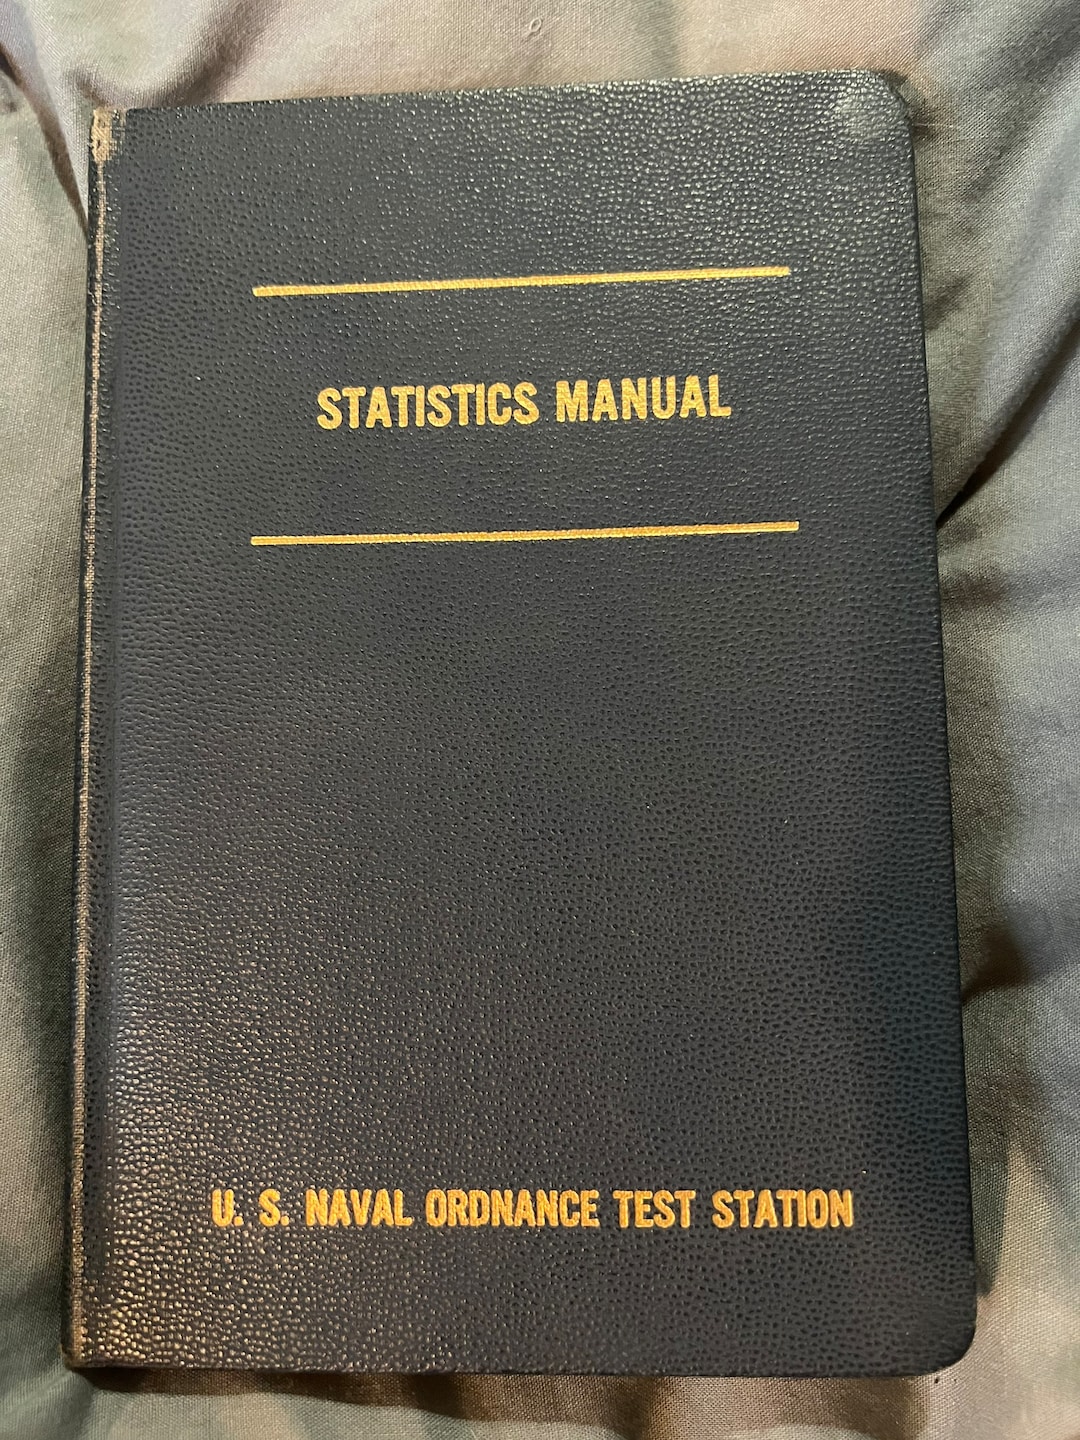
I spend most of my time cleaning up datasets that people hand me, and about once a month someone sends me a paper they found somewhere called a Vintage Statistics Manual. Usually it is some scanned PDF of mid-century statistical tables, and they want to know if it is still useful or where to get it. The short answer is yes, it is still useful, but only if you know what you are doing with it. A Vintage Statistics Manual is typically a compiled collection of distribution tables, critical values, and lookup charts printed before computational software existed. You will see t-distribution tables, chi-square values, F-ratio cutoffs, normal distribution quantiles, sometimes polynomial regression coefficients or standard normal area tables. The format is the same across most of them: rows and columns of numbers keyed to degrees of freedom or significance levels. The original purpose was to give a statistician a quick way to find a critical value without running an algorithm. Most of the ones circulating today come from sources like the National Bureau of Standards, early editions of Abramowitz and Stegun, or university reprint catalogs. They were not written for screen reading. OCR on them is often broken. Tables get misaligned when scanned. I have spent entire evenings re-aligning a single F-table because the scanner shifted the columns by half a point on a few pages. That is just the nature of the medium now.
How to Use These Tables Today
The main reason anyone reaches for a Vintage Statistics Manual in 2026 is either academic transparency or a specific reproducibility requirement. Some journals and dissertation committees want to see table-based verification of critical values rather than just a p-value output from software. Others use them for teaching, which makes sense because looking up a value by hand forces you to understand what the columns actually represent. Here is the practical workflow I use when I need to pull a value from one of these manuals. First, verify the edition and source. Different editions have different rounding conventions. A 1953 NBS table and a 1970 revision of the same table might list slightly different fourth decimal places. If you are citing a value, the exact edition matters. Second, check the degrees of freedom interpolation method the authors prescribe. Most vintage manuals assume linear interpolation between adjacent df values. Modern software does something more precise. When I tested this a while back on a chi-square table for df around 47, the manual's linear interpolation gave me 0.0412 while R's qchisq function gave 0.0409. The difference looks tiny but it can flip a borderline significance decision if you are working at alpha 0.05.
Third, always cross-reference with software. I never trust a manual lookup as the final answer unless the assignment explicitly requires it. Use the table to understand the mechanics, then confirm with a calculation.
Get the Full Details
A Specific Problem I Ran Into
Last year a student sent me a dissertation chapter that cited critical values pulled from a 1947 edition of statistical tables. The t-values looked right at first glance, but when I ran the same test in Python, the p-values were consistently off by about 0.003. I traced it back to the interpolation method. The 1947 manual does not use linear interpolation for the tails. It uses a piecewise approximation that rounds differently at extreme values. The table itself is correct for its intended precision, but applying it directly to modern significance thresholds introduces a systematic bias in the tails. The workaround was straightforward: I re-derived the values using the original table's stated approximation formula rather than assuming linear interpolation, then matched those to the software output. The discrepancy vanished. This is the kind of thing you only learn after you have caught a real error in someone else's work, not from reading the preface of the manual. You can find most of these manuals in the public domain. The Internet Archive and HathiTrust have complete scans of the NBS tables, the CRC Standard Mathematical Tables, and several university press compilations. University libraries often hold physical copies in their reference sections, which is sometimes faster than dealing with a low-quality scan. If you need a digital copy, the Biodiversity Heritage Library also has a searchable collection of older statistical references. I usually grab the Google Books preview version first to check pagination, then pull the full PDF from Archive.org if the quality is acceptable. One note on downloads: many of the files floating around on random academic sites are poorly reconstructed OCR jobs. The tables have merged cells, missing row labels, and phantom characters that look like numbers. If the file seems too broken to use, try finding a different scan. The NBS Handbook 91, for example, exists in at least three different scanned editions, and one of them is usually legible enough to work from.
What These Manuals Can and Cannot Do
A Vintage Statistics Manual will reliably give you critical values for standard distributions, interpolation guidance for most common df ranges, and occasionally some specialized tables for noncentrality parameters or exact binomial probabilities. It will not help you with anything beyond univariate hypothesis testing and basic distribution lookups. If you are working with mixed models, Bayesian posterior intervals, or multiple comparison corrections that require simulation-based thresholds, the manual is irrelevant. There is also the issue of coverage gaps. Many vintage manuals omit the lower tail areas for certain distributions, or they stop at df 120 and expect you to approximate the normal limit beyond that. If your degrees of freedom fall outside the printed range, you are on your own unless the manual includes an appendix on extrapolation methods. The biggest practical limitation is readability. A well-preserved printed copy is fine. A scanned PDF that was OCR'd by a budget service is a headache. I have lost count of the number of times I thought I found a value in a table only to realize the column header had been misread as a footnote. Always verify the row and column labels before you trust a number.
Vintage Statistics Manual as a Teaching Tool
If you are using this for a class or to build intuition, the process of looking up a value is genuinely useful. It forces you to understand what degrees of freedom means in context, why the tail area matters, and how significance thresholds map to distribution shapes. I recommend doing at least five manual lookups before switching to software for a new topic. After that, the table becomes a verification step rather than the primary method. The main pitfall beginners encounter is treating the table values as exact. They are not exact. They are approximations designed for a specific level of precision, usually four decimal places, and they carry rounding error built in. If your analysis depends on sub-millisecond precision in a p-value, the manual is the wrong tool. Use software. But if you need to understand why a result is significant or explain the decision to a reviewer who prefers traditional methods, having the manual nearby and knowing how to read it is valuable.