Generating Viral Haircuts Aesthetic With Stable Diffusion
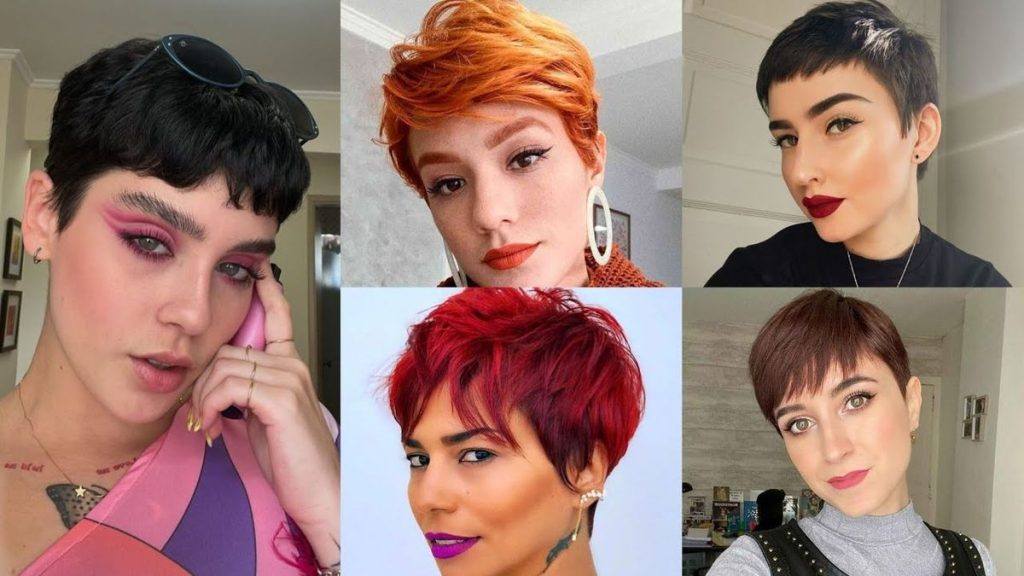
I have spent the last year running diffusion models through gradio interfaces, and the haircut aesthetic space has gotten crowded fast. Everyone wants that sharp anime-to-real crossover look, the windblown undercut, the soft gradient dye fade that trends on TikTok and Instagram. The problem is that most people are doing it wrong, or they are using the same five prompts and getting the same five generic results. The Viral Haircuts Aesthetic as a concept breaks down into three main visual pillars: strong directional lighting that carves out hair texture, precise strand-level definition rather than blurry smears, and a color grading style that leans slightly desaturated with high contrast on the edges. That is the summary. The execution is where things get fiddly.
Viral Haircuts Aesthetic
Here is the workflow I actually use when generating these. I start with a base checkpoint like RevAnimated or DreamShaper because the training data in those models handles hair geometry better than the default SD 1.5 models. Then I load a LoRA if one exists for the specific haircut variant I want. The LoRA weights should stay between 0.6 and 0.8. Going higher introduces artifacts that are very visible in close-up shots. The prompt structure matters more than most people realize. Put the haircut description early in the positive prompt, not buried in the middle. A typical setup looks like this: "short textured undercut with side fade, windblown layered top, individual hair strands visible, studio lighting from the left, shot on 85mm lens, sharp focus on hair texture, natural skin tones, slight film grain." Negative prompts should include things like "blurry hair, smooth plastic skin, overexposed, bad anatomy, fused strands, oversaturated." Sampler selection changes the output quality significantly. DPM++ 2M Karras gives the most consistent results for hair detail, and setting the steps to around 30 to 35 is the sweet spot. Going beyond 40 steps usually does not improve anything and just wastes time. CFG scale should sit around 7. Anything above 8 starts making the images look too harsh and the hair strands become overly defined in an unnatural way.
Batch Generation and Upscaling Strategy
Once you have a decent base image, do not just crop it and call it finished. The resolution is almost always too low for the detail level you are going for. I run the image through a 4x upscaler with the hires fix enabled in Automatic1111. Set the denoising strength to 0.45. Higher values will regenerate the hair in a way that loses the structure you carefully prompted for. Lower values and you are not really upsampling anything meaningful. If you are generating multiple variations, use the seed locking feature. Lock your base seed and then vary only the prompt weighting and the sampler steps. This gives you a family of images that share the same composition and lighting, which is useful when you need consistency across a series. The alternative is getting five completely different looking faces and wondering which one fits your project.
Get the Full Details
Specific Problem and Workaround
Last month I was working on a project where I needed a specific mullet-inspired cut with subtle blue undertones in the highlights. The model kept blending the blue into the background instead of keeping it in the hair. I spent about two hours just adjusting the prompt weights. What finally worked was splitting the color instruction into a separate weighted clause: (blue tinted highlights:1.3) placed after the haircut description but before the lighting terms. I also added a region-specific control net using a depth map of the original generation to keep the color confined to the hair area. It added about ten minutes to the pipeline but solved the problem completely. Most people overwrite their prompts with too many conflicting descriptors. Asking for "blonde balayage" and "jet black roots" in the same prompt creates a confused model that produces something muddy in the middle section. Pick one color direction and commit to it. If you need variation, generate separately and pick the best result. Another issue is relying too heavily on reference images without adjusting the denoising strength properly. If you use img2img with a reference photo and set the strength above 0.6, the model starts inventing its own hair structure and you lose the reference entirely. Below 0.4 and the output barely changes from the original. The functional range here is narrower than most tutorials suggest.
Do not ignore the batch size implications. Generating eight images at once sounds efficient but your GPU memory usage spikes and you start seeing quality degradation on later samples in the batch. I usually generate in batches of four and check each one before moving on. It is slower but it prevents having to redo entire batches because of a subtle quality issue that only appears after the fact.
Where This Approach Falls Short
The main limitation with this method is that it requires decent GPU hardware. Running stable diffusion with the upscaling pipeline described here needs at least 8GB of VRAM, preferably 12GB or more if you are doing batch work. On lower-end hardware you will be reducing resolution and simplifying prompts, which noticeably affects the final quality. The hair detail is the first thing to suffer when you cut corners on memory allocation. Another honest drawback is the randomness factor. Even with identical seeds and prompts, slight variations in system state can produce different results between runs. This is not a bug, it is just how the current models work. You need to generate multiple variations and pick the best one rather than expecting consistent results on the first try. For users who need more control over specific haircut elements, the open source alternatives like ComfyUI workflows with explicit node-based conditioning can offer more precision. The learning curve is steeper but the results tend to be more reliable for professional work. If you are just doing casual generation, the gradio interface with the settings I mentioned above is sufficient.
The downloadable resources for this are scattered across platforms like Civitai and Hugging Face. Look for LoRA files tagged with haircut or hairstyle keywords and check the created date. Models older than six months may not perform well with newer checkpoints due to training data differences. Version compatibility is something the community does not always document well, so test before committing to a particular LoRA for a production project. Running this workflow properly takes practice. The first few attempts will look wrong in ways that are hard to diagnose. Adjust one variable at a time. Change the sampler, then the CFG, then the prompt weight distribution. Keep notes on what works. The community threads on this topic tend to be either too vague or overly enthusiastic about results that are not reproducible. Take the practical details and discard the rest.