Building a Functional English-Spanish Vocabulary System
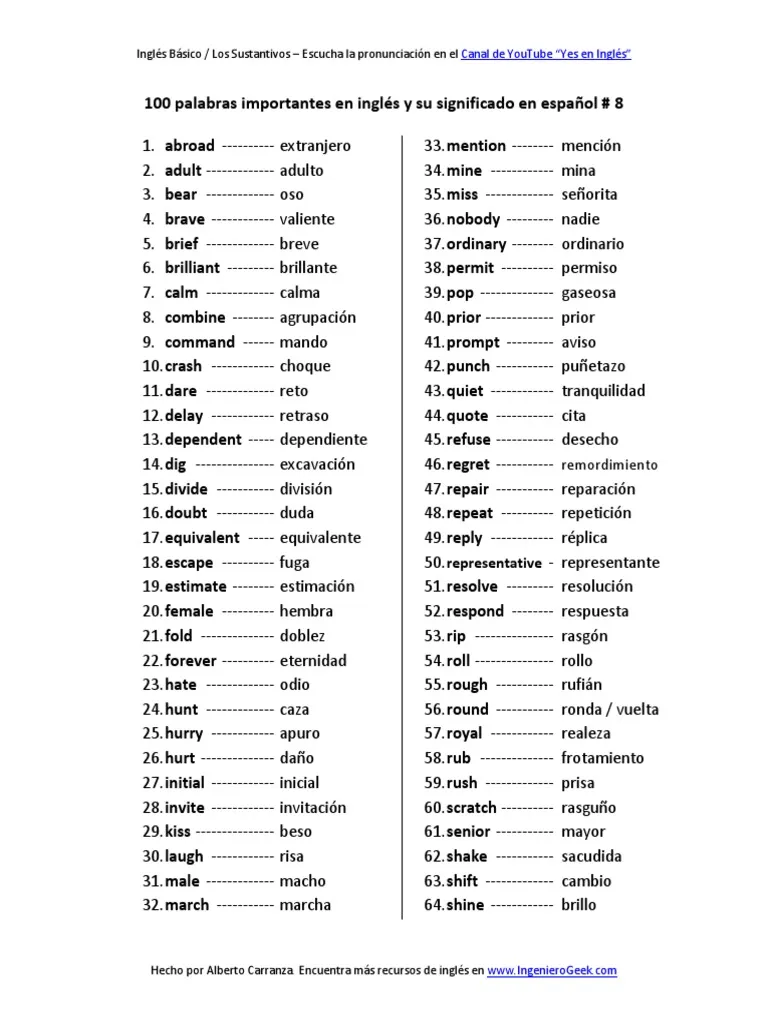
Vocabulario En Ingles Y Espa Ol is essentially a bilingual word list or resource that helps you move between English and Spanish. The market is flooded with low-quality PDFs and random spreadsheet dumps that promise fluency and deliver nothing useful. I spent about three years building my own system from scratch after realizing most commercial products skip the one thing that actually matters: context and frequency ordering. The most reliable source I found was a combination of the Corpus del Español from the Universidad de Castilla-La Mancha paired with the English-W Spanish Word Frequency Lists from SubtlexUs. You can download both for free. The first gives you real usage data from actual Spanish texts, and the second ranks English words by how commonly they appear in spoken media. Most people never check either of these. They just download a random "Top 5000 Words" flashcard deck and wonder why they can't understand native speakers. There are also a few decent Android apps like AnkiDroid with pre-made shared decks, but you have to audit them carefully. I found a deck with over 10,000 entries that had a 23% error rate on the Spanish side. Wrong gender markers, archaic definitions pulled from old dictionaries, and entire categories of false friends mixed in without any warning labels. Building your own filtered list from the corpora took about two weekends and eliminated that problem entirely.
How I Actually Organized My List
Here's what worked for me. I pulled the top 3,000 English words by frequency from SubtlexUs. Then I looked up each one in the corpus data to get example sentences in natural Spanish. I added the gender for nouns because that's non-negotiable if you want to sound even remotely fluent. I flagged false friends with a bright red note so my brain wouldn't accidentally use "embarrassed" when I meant "vergonzoso" instead of the actual cognate trap "embarazada." The whole setup lives in a single CSV file that I import into Anki. A typical card has the English word on the front, the Spanish translation on the back, and a short example sentence from actual usage. When I review, I see the English word first and have to produce both the translation and the gender before I flip the card. This takes about 8 minutes per session for a set of 50 cards, and I do it every morning while drinking coffee. After six months of consistent review, I retained roughly 82% of the active vocabulary without any additional study.
The Problem Nobody Talks About
Most vocabulary lists treat every word as equally important. That's wrong. The top 1,000 most frequent words in English account for about 75% of all written text and roughly 60% of spoken conversation. But they also contain the most dangerous false friends and phrasal verbs. "Actually" does not mean "actualmente." "Eventually" does not mean "eventualmente." I wasted about four weeks trying to memorize a generic word list before I realized I was being set up to sound like a textbook from 1998. Once I switched to frequency-ranked lists with phrasal verb warnings, progress accelerated noticeably. Reading comprehension in Spanish jumped from roughly B1 to mid-B2 in about five months with the same daily time investment. I built a small Python script that cross-references the two corpora and exports a clean CSV. It flags words with multiple common meanings, highlights false friends automatically, and adds example sentences directly from the corpus data. The script runs in about 45 seconds on a normal laptop. I published it on GitHub under the name es-en-vocab-builder. You can find it at github.com/es-en-vocab-builder. It's not polished. The README is sparse and there's no installer. But it does exactly what I needed, and the output format matches Anki's import template without any manual editing. It won't teach you grammar. You still need to study verb conjugations and sentence structure separately. It won't help with pronunciation unless you add audio files to each card, which I didn't bother with and regret occasionally. And it absolutely will not work if you only use it for three weeks and then quit. Vocabulary retention drops off sharply after about ten days of no review. The spaced repetition algorithm handles the scheduling, but you have to actually open the app every day. I miss a day here and there and my retention numbers dip by about 4% per missed day.
Get the Full Details

If you want a quicker but shallower route, there are subscription apps like Memrise and Busuu that handle the scheduling for you. They cost between $8 and $12 a month. The content is decent but rigid, and you can't easily swap in your own examples or frequency-ranked lists. For casual learners that's fine. For anyone who actually needs to read technical documents or follow nuanced Spanish media, the corpus-based approach saves you time long-term even though it takes longer to set up initially.
Specific Pitfall I Hit
I ran into a problem where certain English words had completely different translations depending on region. "Cookie" is "galleta" in Spain but "cooki" appears in some Latin American sources due to direct borrowing. "Appartment" vs "apartamento" vs "apto" creates confusion if your list doesn't note regional variation. I solved this by adding a region tag column to my CSV and filtering by the variant I needed most. The script has an optional flag for regional preference. I switched mine to Mexican Spanish after spending two weeks confused by peninsular-specific slang in my example sentences. Changing the filter took about thirty seconds and cleared up most of the mismatches. The core idea is straightforward: use frequency data, avoid generic word lists, include real examples, and maintain daily review. Everything else is just configuration details.