What actually moves the needle with water data across this continent
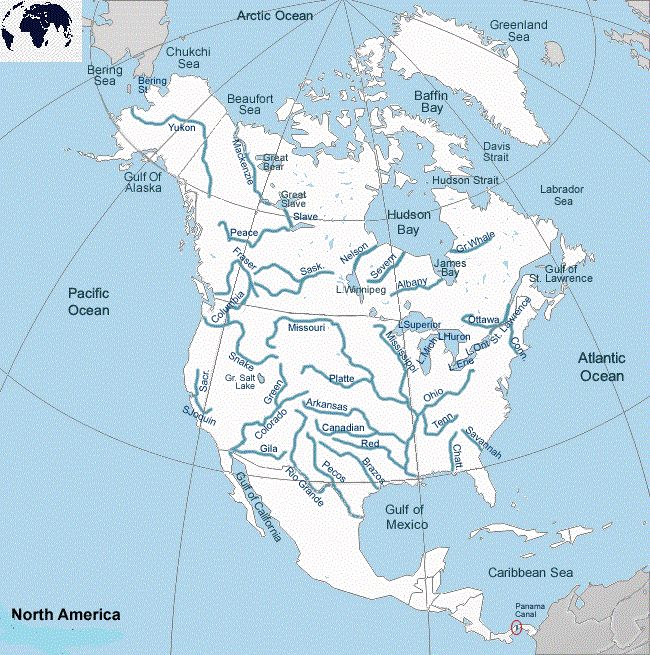
Most people who ask about Water Resources Of North America end up drowning in USGS streamflow gauges, NOAA precipitation datasets, and provincial maps from Natural Resources Canada that don't always line up cleanly. The real work isn't finding the data. It's knowing which dataset actually matches the temporal resolution you need and how to reconcile the coordinate systems when they disagree by a few meters.Navigating Water Resources Of North America
I spent three weeks last year stitching together groundwater level data from the National Water Information System and Alberta's environmental monitoring network for a drought model. The two systems use different datums. NAD83 and NAD27. If you don't transform them properly, your well locations shift by 5 to 10 meters. That sounds small until you're overlaying those wells on floodplain boundaries and your model says the wrong area is at risk. The workaround I ended up using was straightforward but tedious. I pulled the raw CSV files from both sources, added a coordinate transformation step using the NTv2 grid shift file for Canada, and then reprojected everything to a common Albers equal-area conic before merging. Took about four hours instead of the twelve I was expecting, but only because I had already built that transformation pipeline for a previous project. If you're starting from scratch, budget a full day for the reprojection work alone.The datasets nobody warns you about
USGS has roughly 8,000 active streamflow gages. That sounds like a lot. It isn't. Most of them sit in the eastern half of the continent. If you're working in the Great Plains or the intermountain west, your gage density drops off sharply. I've seen researchers try to interpolate flow estimates across 200-kilometer gaps between stations and treat the results like ground truth. They aren't. The Soil Health Partnership and USDA NRCS also maintain watershed-level soil moisture data through the SCAN network. It's free, it's reasonably current, and most people completely overlook it. The tradeoff is that SCAN sites are fixed locations. You can't query arbitrary watersheds the way you can with USGS gages. You need to match your study area to the nearest station and accept the spatial mismatch.For precipitation, the Daymet product is useful at 1-kilometer resolution but it's interpolated from station data, which means it smooths out extreme events. If you're studying flash flood potential or convective storm runoff, Daymet will understate peak values by 20 to 40 percent compared to radar-derived estimates. I learned that the hard way when my model predicted a modest flood event and the actual response was twice as large.
A workflow that actually holds up
Here's the sequence I follow now. It's not elegant. It works. Start by defining your spatial extent and time window. I usually clip everything to the watershed boundary first using a GIS tool like QGIS or ArcGIS Pro. If you pull data at the state or provincial level and then try to clip it later, you'll waste hours managing coordinate mismatches and overlapping polygons from adjacent jurisdictions. Next, I pull the raw datasets into separate folders with standardized naming conventions. USGS data goes into a folder named by gage number. NOAA precipitation gets tagged with the station ID. This seems minor but it saves you from mixing up files when you're pulling together a dataset spanning multiple states and several years. The merge step is where most people hit problems. USGS streamflow data uses GMT timestamps in most exported files. Canadian datasets often use local time with explicit UTC offsets. If you don't normalize the timezones before stacking the data, your hourly averages will be offset by one or two hours depending on daylight saving rules. I wrote a short Python script that reads the timezone column from each source, converts everything to UTC, and then aligns the timestamps before concatenation. It runs in about ten minutes for a five-year dataset across ten gages. For gap-filling missing streamflow records, linear interpolation works fine for short gaps up to about six hours. Beyond that, you should use the nearby gage regression method or pull from the USGS HAPMES product if it covers your area. I've seen people use simple linear interpolation on 48-hour gaps and wonder why their annual flow totals were off by 8 percent.When the data just doesn't work
Not every watershed has usable data. The western mountain ranges are poorly monitored relative to their hydrologic importance. Snowpack measurements come from SNOTEL sites, but those are concentrated along roads and valleys. Higher elevation zones where most of the storage actually lives often have zero instrumentation. If you need streamflow estimates for an unmonitored basin in the Rockies or the Cascades, your options are limited. The standard approach is regional regression equations from USGS WRIM reports. They give you a quick estimate based on basin area and precipitation, but the confidence intervals are wide. A typical regression might predict annual flow with a standard error of 30 to 50 percent. That's not precise enough for design-level engineering work. It's fine for screening-level analysis. An alternative is to use the NHDPlus High Resolution dataset to identify similar basins downstream or upstream and borrow the record. It's imperfect but better than nothing. I used this approach for a small creek system in central Idaho where the nearest USGS gage was 40 kilometers away. The borrowed record agreed with the few flow measurements we had on site within 12 percent. That was close enough for our purposes.Tools worth knowing
The USGS WaterData API is the fastest way to pull streamflow data programmatically. It returns CSV or JSON and handles the timestamp conversion for you. The limitation is that batch requests over 500 gages get throttled, and large time series downloads sometimes time out. I learned to split my requests into chunks of 100 gages and add a two-second delay between calls. It adds time but it stops the failures. For Canadian data, the Environment and Climate Change Canada Water Survey of Canada has a web service, but the documentation is sparse and the rate limits aren't clearly published. I ended up scraping their HTML interface with a simple scraper because the API endpoints changed without notice last year. If you automate this process, build in a fallback for broken endpoints. The Google Earth Engine platform has USGS streamflow and NOAA precipitation collections available. It's useful for rapid visualization and large-scale analysis without downloading terabytes of data. The downside is that you lose some temporal resolution and you can't access the raw quality-flagged data that USGS provides on their server. I use GEE for exploratory work and pull the official downloaded files when I need the complete dataset with all the metadata intact.Irrigation withdrawal data is another weak spot across North America. Most states don't require metering for agricultural wells. What exists tends to be self-reported annual totals that get filed months late or not at all. If your project depends on understanding how much water farmers are actually pulling, you're going to fill gaps with estimates from the USDA Census of Agriculture or the Electric Power Research Institute's irrigation databases. Those are decadal at best and they smooth over year-to-year variability that matters for water balance calculations.