Static Practice Targets First
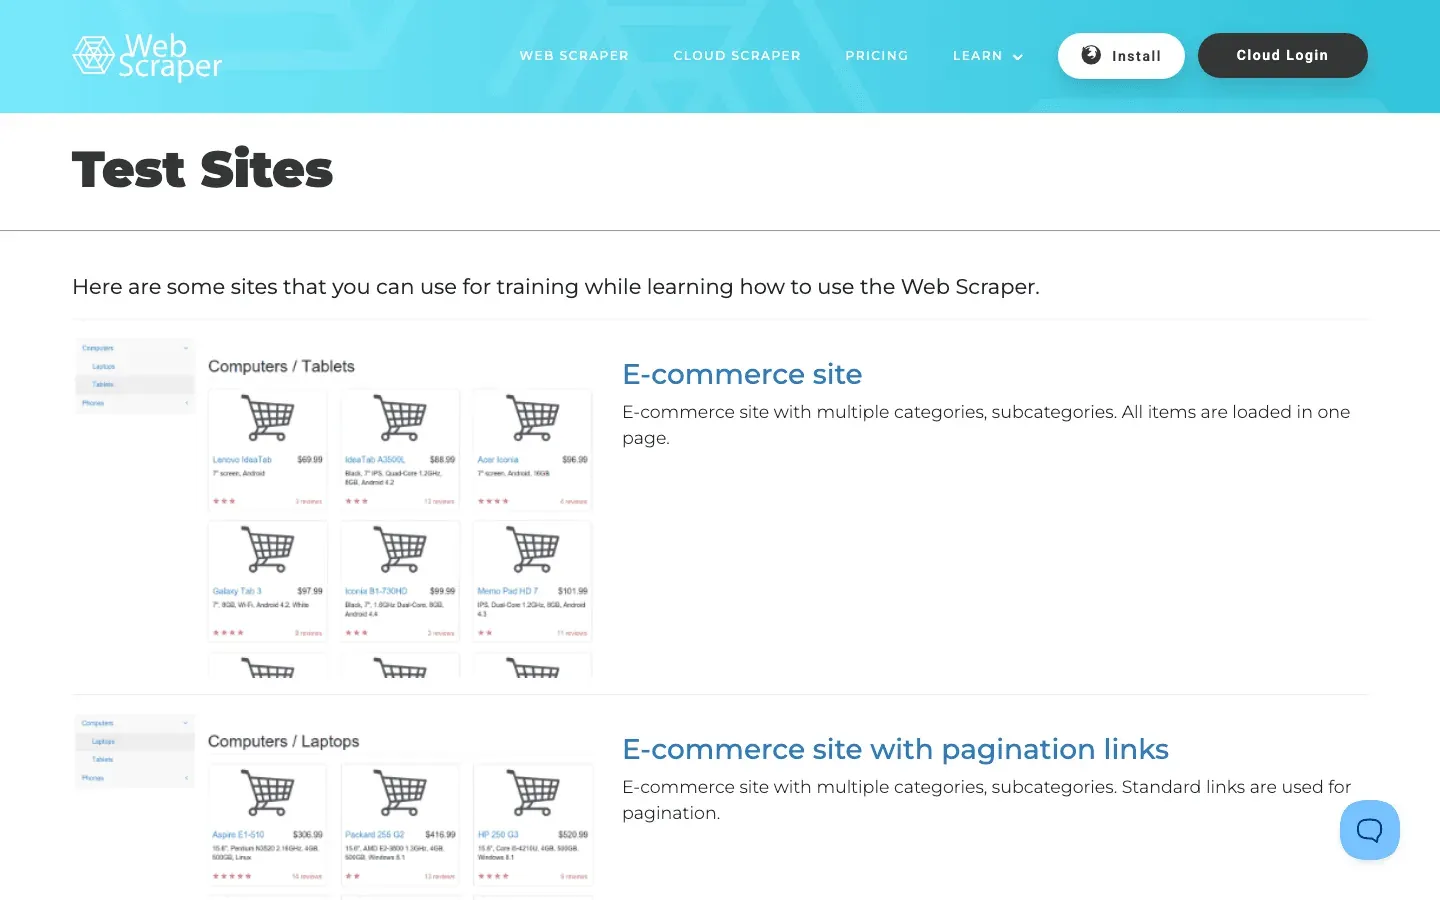
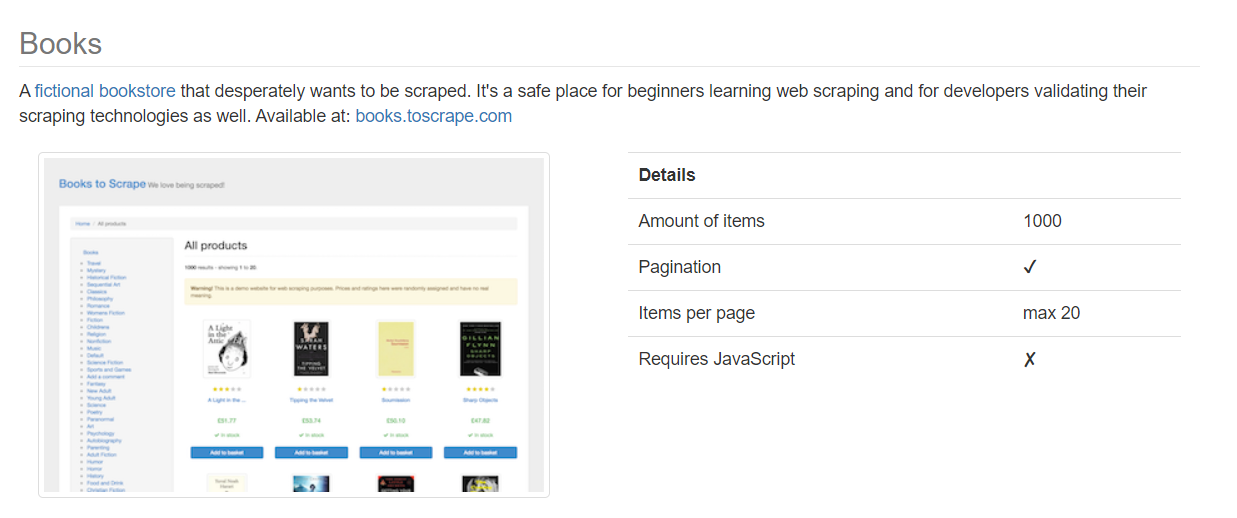
Most people start with scraping the official documentation sites because they don't change often and have predictable HTML structures. Scrape Hero, Web Scraper's demo pages, and BookToScrape (part of ScrapingClub) are the usual suspects. These sites exist specifically for practicing scrapers without dealing with rate limits, login walls, or JavaScript rendering. I've watched people spend three weeks trying to debug why their Selenium script keeps failing when they could have moved on to real targets after one afternoon on BookToScrape. The problem with relying only on these is they train bad habits. The HTML is clean. Elements are consistently named. There's no anti-bot protection whatsoever. When you eventually hit a real site, you'll be completely unprepared for anything beyond a simple GET request. That transition is where most beginners stall out. I've seen it happen repeatedly, usually around month six of "learning to scrape."
Websites To Practice Web Scraping With Real Complexity
Once you can reliably extract data from static demo pages, you need environments that simulate real-world friction. lxml.dev has intentionally broken practice sites with pagination, infinite scroll, and varied response structures. Zenrows' practice pages include CAPTCHA challenges and bot detection simulations. ReqBin's test endpoints are useful for practicing against JSON APIs rather than HTML, which is where most actual production scraping happens anyway. API Ninjas and Public APIs Directory give you structured endpoints to parse instead of wrestling with DOM selectors. I ran into a specific edge case last year working on a project that seemed straightforward. The target site used server-side rendered HTML for the first page but switched to lazy-loaded JavaScript for subsequent results. My initial scraper, built entirely on requests and BeautifulSoup, pulled the first batch without issue, then returned empty results. The data was there in the browser network tab, just delivered through an undocumented XHR endpoint. I spent about two days reverse-engineering the API by watching Chrome DevTools network traffic, found the correct pagination parameters, and switched my scraper from HTML parsing to direct API requests. That cut the runtime from roughly four minutes per query down to about twelve seconds. Lessons like that don't come from static demo sites.
The JavaScript Problem Nobody Warns You About
Static pages are easy. The moment a site loads content via JavaScript, everything changes. Most beginners reach for Selenium or Playwright at this point, which works but introduces massive overhead. A Selenium-based scraper might take thirty to sixty seconds per page compared to two to five seconds with a pure HTTP approach. That difference compounds fast if you're pulling more than a hundred pages. The counter-intuitive part is that you rarely need the full browser. In most cases, the JavaScript is fetching data from an API behind the scenes. Chrome DevTools Network tab filtered to XHR/Fetch will usually show you the raw JSON. If the API returns the same data the page displays, you skip headless browser automation entirely. This approach failed for me once on a site that genuinely rendered everything client-side with no underlying API. I had no choice but to run a headless Chrome instance with Playwright, and even then the site detected it through navigator.webdriver flags. The fix was using the undetected-chromedriver package, which patches those detection vectors. It added maybe ten minutes to the setup but prevented the scraper from getting blocked on the first request.
Get the Full Details
Rate Limits and Ethics Matter More Than You Think
Practice sites won't throttle you. Real sites will. A common mistake is writing a scraper that hammers a target without any delay between requests. I once had a colleague build a scraper that pulled data from a small e-commerce site and got their entire IP range blocked within twenty minutes. The site had maybe fifty requests per minute limits, and his script was making roughly two hundred. Adding a random delay between one and three seconds between requests solved the problem instantly. It also made the scrape slower, but a slow scraper that actually works beats a fast one that gets banned. Another thing people gloss over: checking robots.txt and terms of service before scraping anything. Some sites explicitly prohibit automated access. Not because they're being difficult, but because the infrastructure cost of your scraper hitting their servers ten thousand times an hour is real. I always recommend starting with a polite delay, preferably checking if the site offers an official API first. Many larger platforms have developer APIs that are more reliable and legally safer than any scraper you build yourself.
What Actually Works Long Term
The practice sites I mentioned are fine for learning syntax. They won't teach you resilience. Real scraping involves handling timeouts, partial responses, changed selectors, CAPTCHAs, and IP rotation. If you want to build something durable, practice on sites that intentionally fight you. Death Match from ScrapingClub throws multiple anti-bot measures at you. Scraper's Trap sites online are designed to detect and block common scraping patterns. Working through those scenarios early saves you from painful production failures later. The tools themselves matter less than understanding what you're actually requesting. BeautifulSoup parses HTML. lxml is faster but less forgiving of malformed markup. Playwright handles dynamic content but requires more resources. Requests library is fine for static pages. Knowing which tool fits which situation matters more than memorizing syntax for all of them. I typically default to requests plus BeautifulSoup for anything renderable without JavaScript, Playwright only when the data lives behind a JS render, and direct API calls whenever I can find the endpoint. That pattern covers maybe ninety percent of real-world scraping jobs. Start simple. Build something that breaks. Fix it. Then build something that fights back. The practice sites are a starting point, not the destination.