The boring truth about assessment tools
Most people think assessment tools are some kind of magic box that spits out verdicts. They aren't. An assessment tool is just a structured way of collecting data about something you care about and turning it into something readable. That's it. The tool doesn't decide anything. It organizes evidence so a human can make a decision faster and with less bias than they would guessing off the top of their head.
I've spent years watching teams misuse these things. The worst mistake I see is treating the output as objective truth. It's never objective. Every assessment tool embeds the assumptions of whoever built it. If the rubric was written by people who only understand one style of work, it will penalize people who work differently. I learned that the hard way about seven years ago when we rolled out a performance review system at a software company and it systematically undervalued senior engineers who didn't document everything in the same format the managers expected. The workaround was adding a peer testimony component that weighted collaboration and mentorship equally with shipped deliverables. The scores shifted noticeably within the first quarter. At their core, assessment tools are instruments designed to measure, evaluate, or gauge knowledge, skills, performance, or attributes. They come in many forms depending on what you're trying to measure and in what context. A diagnostic exam in a classroom uses multiple choice and short answer questions to determine baseline understanding before instruction begins. A 360-degree feedback instrument in a corporation collects ratings from peers, subordinates, and managers to map leadership effectiveness. A skills rubric in a trade apprenticeship tracks progress across physical and cognitive benchmarks over months or years. The category is broad because the concept is simple. You have something you want to know more about. You build or borrow a mechanism to gather signals about it. You interpret those signals. The mechanism is the tool.
Reliability and validity are the two numbers that actually matter. Reliability is whether the tool gives consistent results under consistent conditions. Validity is whether the tool measures what it claims to measure. These are not the same thing. I've seen tools with great reliability and terrible validity more often than the other way around. A test that gives the same score every time but measures nothing useful is almost worse than a messy test, because people trust it blindly. Here's a detail most guides skip: you should run a pilot before scaling any assessment tool. Not a full rollout. A small group that represents the diversity of the population you'll eventually assess. In one project we were implementing a technical skills assessment for a customer support team and the initial version failed on non-native English speakers. The questions weren't harder technically but the reading load created a comprehension barrier that had nothing to do with troubleshooting ability. We cut the average sentence length by forty percent and added visual references to the scenario descriptions. The pass rate distribution stayed the same for native speakers and the tool finally measured what it was supposed to measure.
Types you'll actually encounter
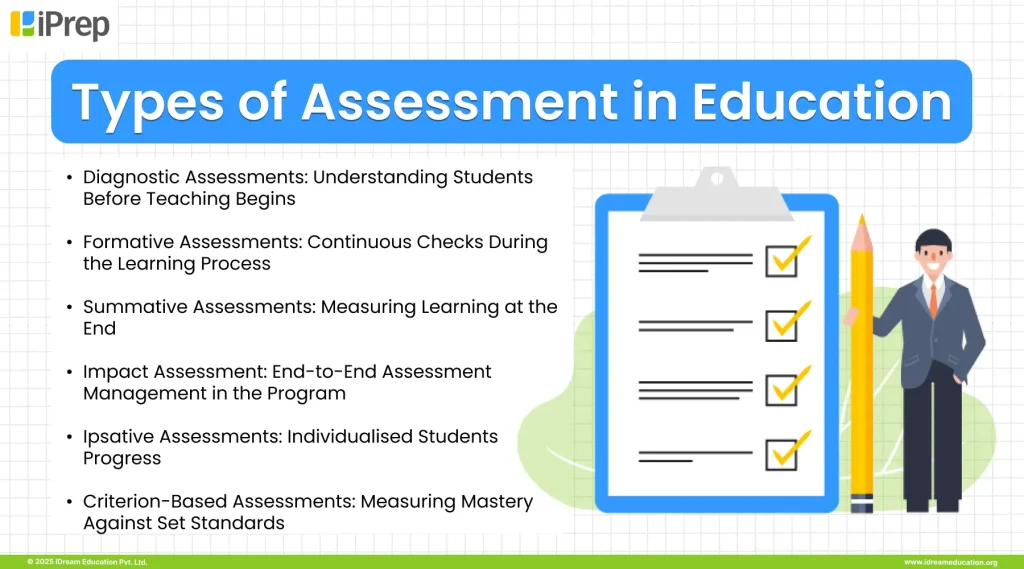
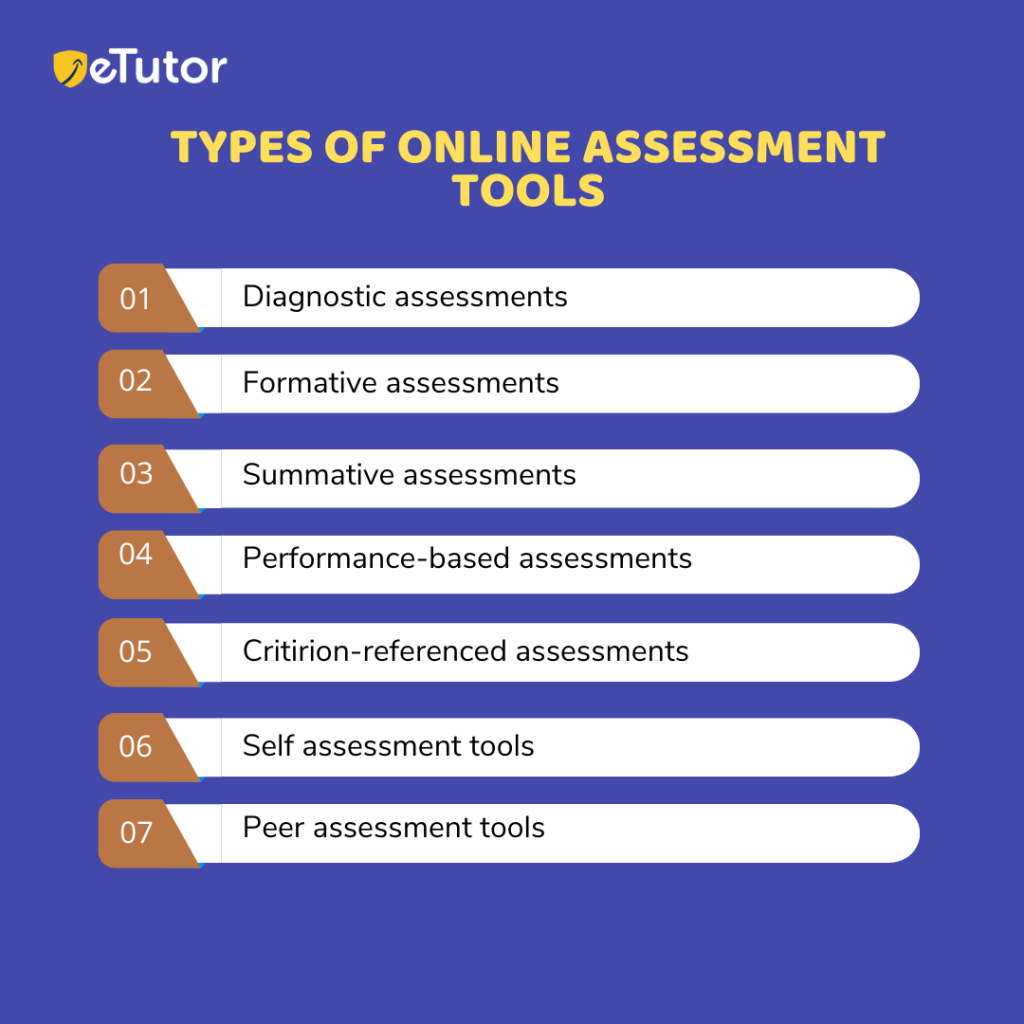
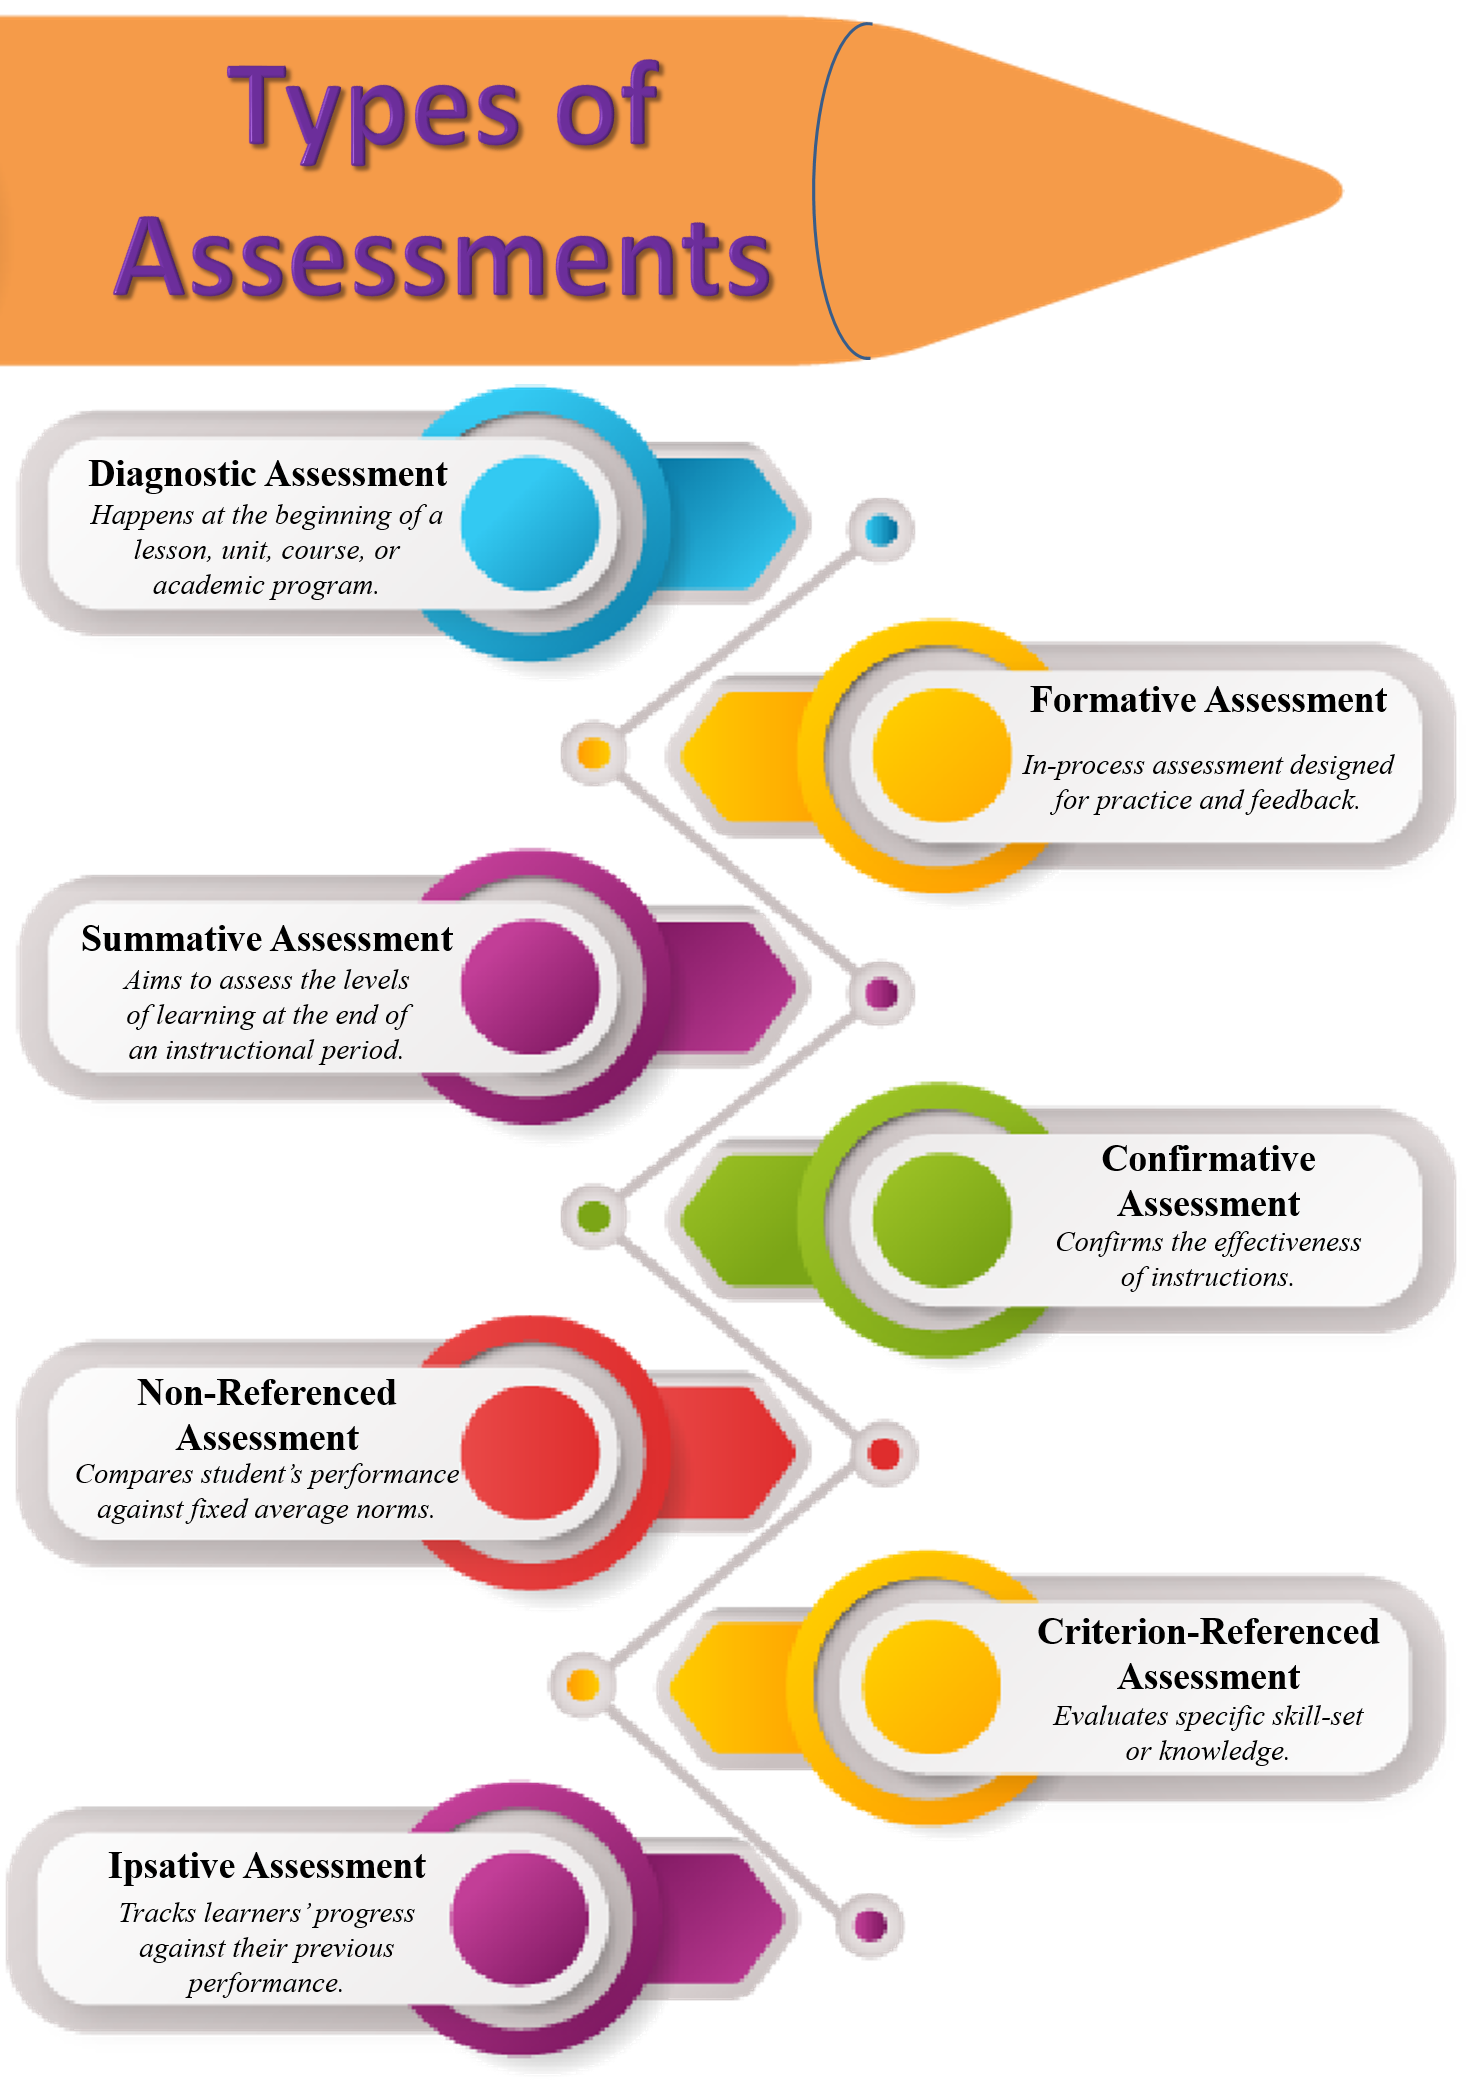
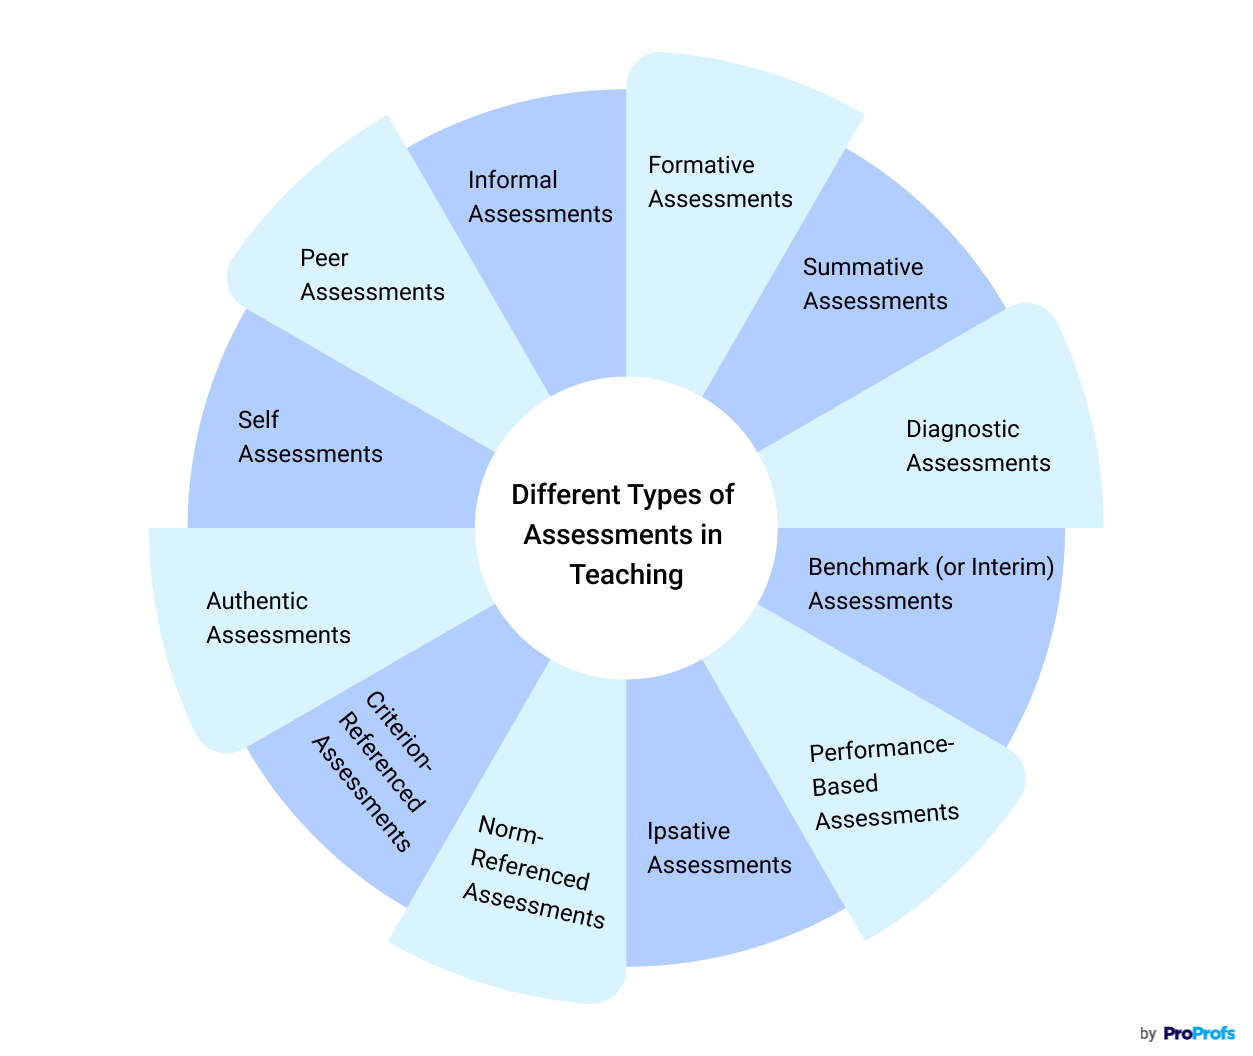
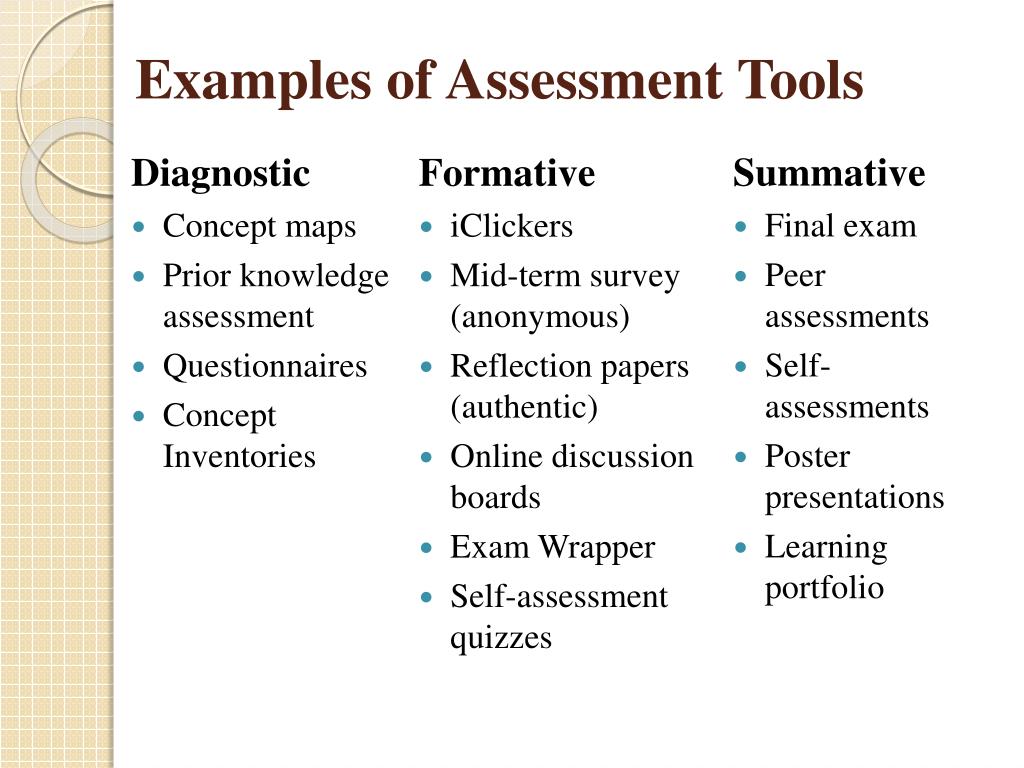
Formative assessments happen during a process to guide improvement. Summative assessments happen at the end to make a judgment. Standardized assessments control for external variables so results are comparable across groups. Diagnostic assessments identify starting points before instruction or intervention begins. Authentic assessments place the subject in a realistic scenario rather than asking them to recall abstract knowledge. The distinction between formative and summative matters more than people admit. I once watched a manager try to use a formative development tool as a summative ranking tool. The participants caught on quickly and stopped being honest about their gaps because honesty would lower their score. The data became noise. If you're using an assessment for high-stakes decisions like promotion or placement, tell people upfront and design for it. If you're using it for coaching, make the stakes low enough that people will be truthful. Performance-based assessments are where most organizations struggle. They require more time to administer and score, which means they're more expensive and harder to standardize. But they tend to have higher predictive validity for actual job performance than paper tests. A coding exercise that mirrors real work tells you more about how someone will perform on the job than a multiple-choice quiz about programming concepts ever will. The tradeoff is scoring consistency. Two raters can disagree on a coding exercise in ways they wouldn't on a bubble sheet. Calibration sessions between raters reduce this drift but they don't eliminate it.
Get the Full Details
Building or choosing one
Start by defining the decision the assessment will inform. This sounds obvious but most people reverse the order. They find a tool online and then figure out what problem it solves. The result is usually a mismatch between what the tool measures and what the organization needs to know. Write down the exact question you need answered before you write a single item or select a vendor. If you're building your own, anchor each item to a competency or learning objective. Don't ask a question unless you can trace it back to something specific. I use a simple mapping spreadsheet with columns for item, competency, Bloom's taxonomy level, and the decision it supports. It keeps the tool honest when scope creep happens, which it always does. Item difficulty matters more than item count. Twenty well-calibrated items beat sixty mediocre ones every time. Use classical test theory or item response theory depending on your scale. For small organizations with limited sample sizes, classical test theory is fine. Once you have a thousand or so responses and you're running assessments regularly, IRT gives you better measurement precision and allows you to build adaptive versions that adjust difficulty based on the respondent's answers.
Cut any item that doesn't discriminate between high performers and low performers. If both groups gets it right or both groups gets it wrong, the item isn't adding information. It's just adding noise or taking up time. I go through every new assessment and flag items with a point-biserial correlation below zero-point-two. They usually come from poorly worded questions or competencies that were too vague during the design phase.
Common pitfalls that ruin good tools
Cultural bias is a real problem in workplace assessments. Questions that assume familiarity with specific idioms, scenarios, or reference frames disadvantage people who don't share that background. A leadership assessment that uses baseball metaphors implicitly advantages people who grew up playing or watching baseball. It sounds minor until you look at the demographic breakdown of your scores. Over-reliance on a single tool is dangerous. No assessment captures everything about a person's ability or knowledge. Triangulate with other data sources. Combine a skills test with work samples and manager observations. The combined signal is stronger than any single measure. Correlation between different assessment types should be moderate, not perfect. If they're perfectly correlated you're probably measuring the same thing twice. If they're uncorrelated you might not understand what each one is actually measuring.
When assessment tools fail completely
They fail when the stakes are too high relative to the tool's validity. Using a personality quiz to hire a surgeon is bad. Using a short situational judgment test to place someone in a critical security role is also bad. No single assessment tool should be the sole determinant for high-consequence decisions. Use them as one input among many. They fail when the population is too small to validate the tool properly. If you're assessing twenty people per year, you don't have enough data to calibrate reliably. Standard errors will be large. In that case, qualitative methods or structured interviews often produce better decisions than a quantitative assessment tool built on insufficient evidence. They fail when leadership treats the score as the outcome instead of the score as information. I've watched executives push for score improvement targets without improving the underlying conditions. Training people to take the test better without giving them actual resources or support is a well-documented way to inflate scores while real performance stagnates. The numbers look good. Nothing changed.
The best assessment tools are simple, transparent, and used honestly. They acknowledge their own limitations. Anyone who tells you their tool is flawless is selling something. The tools that survive in practice are the ones that get revised every year based on what the data actually shows rather than what management hopes it shows.