Why Your Project Fails at Step Three
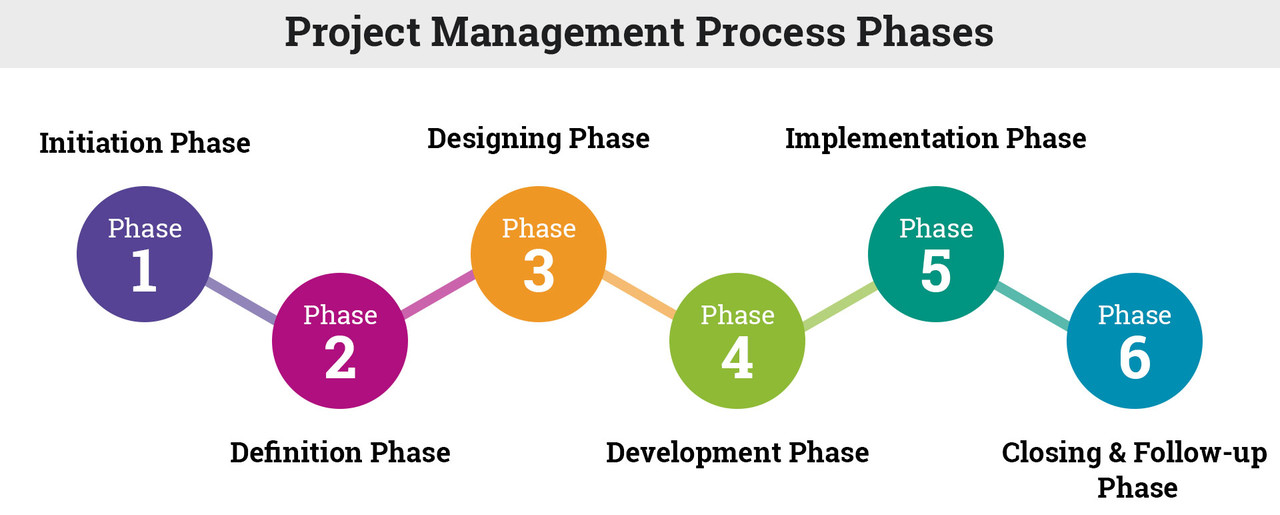
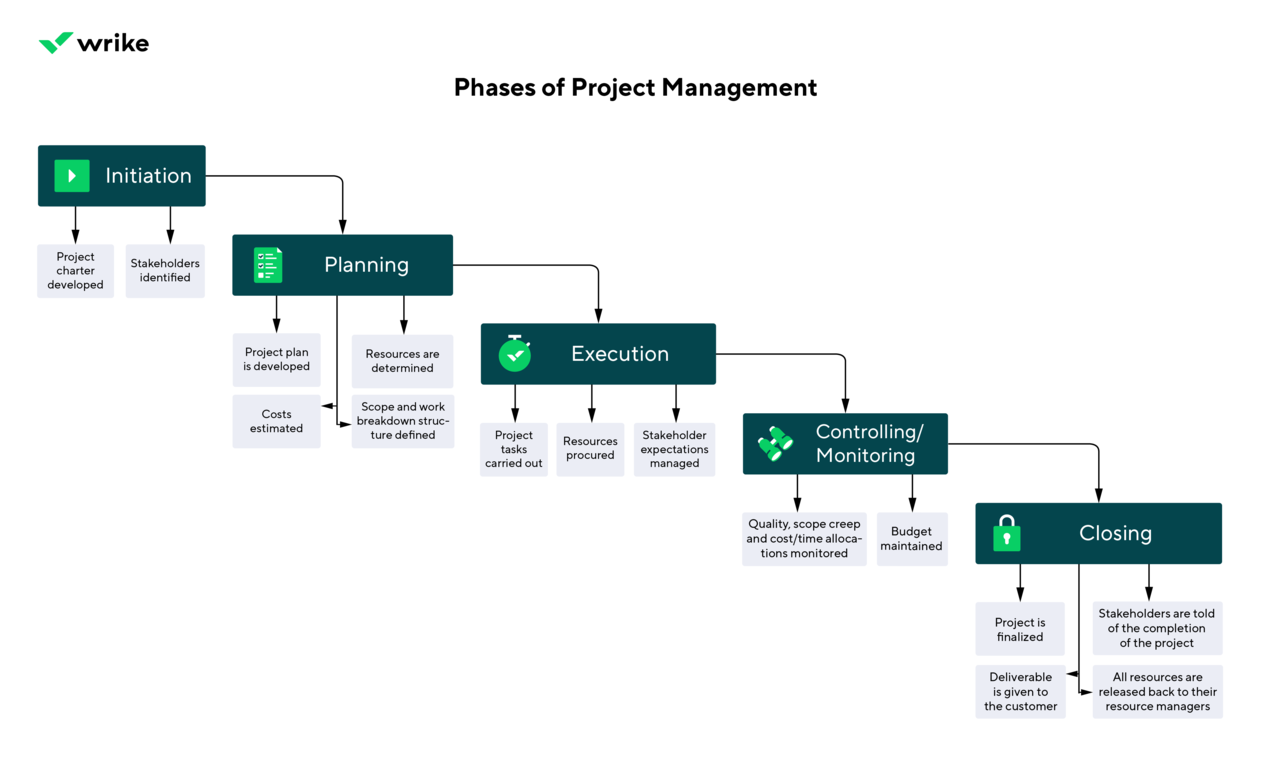
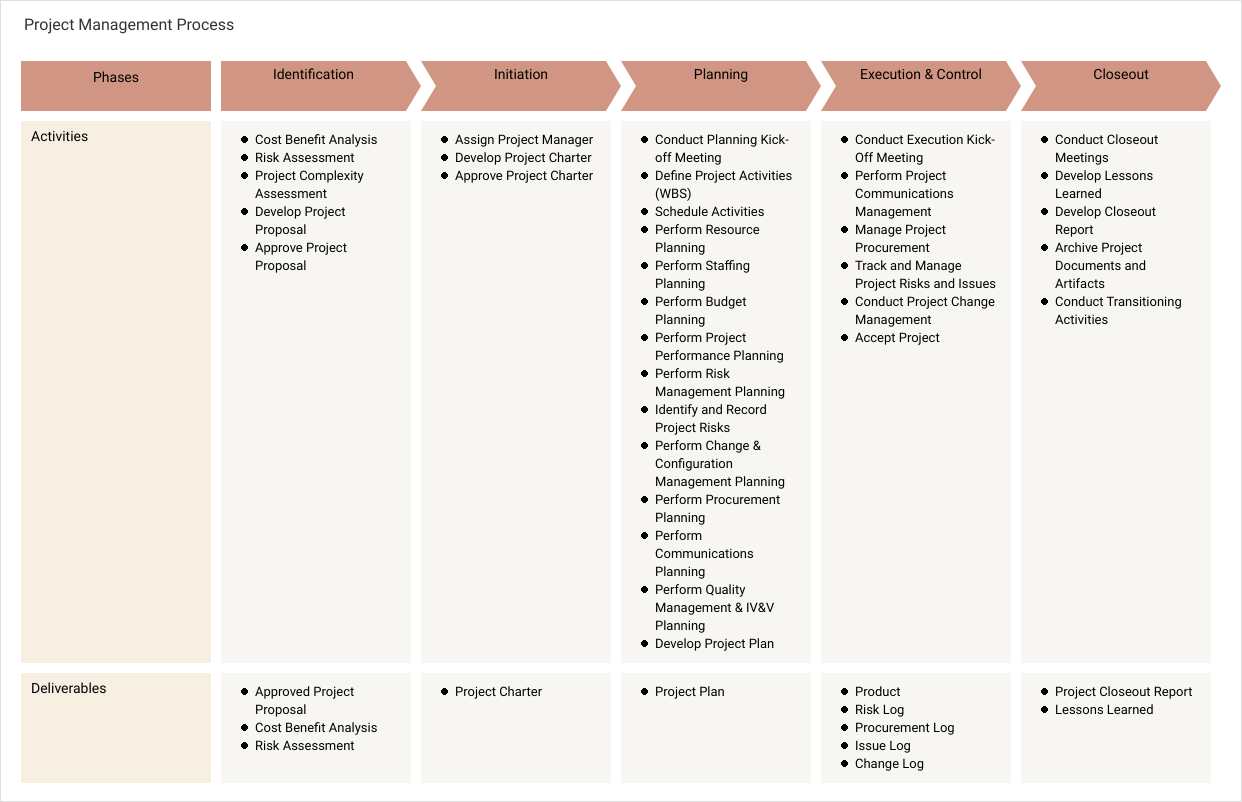
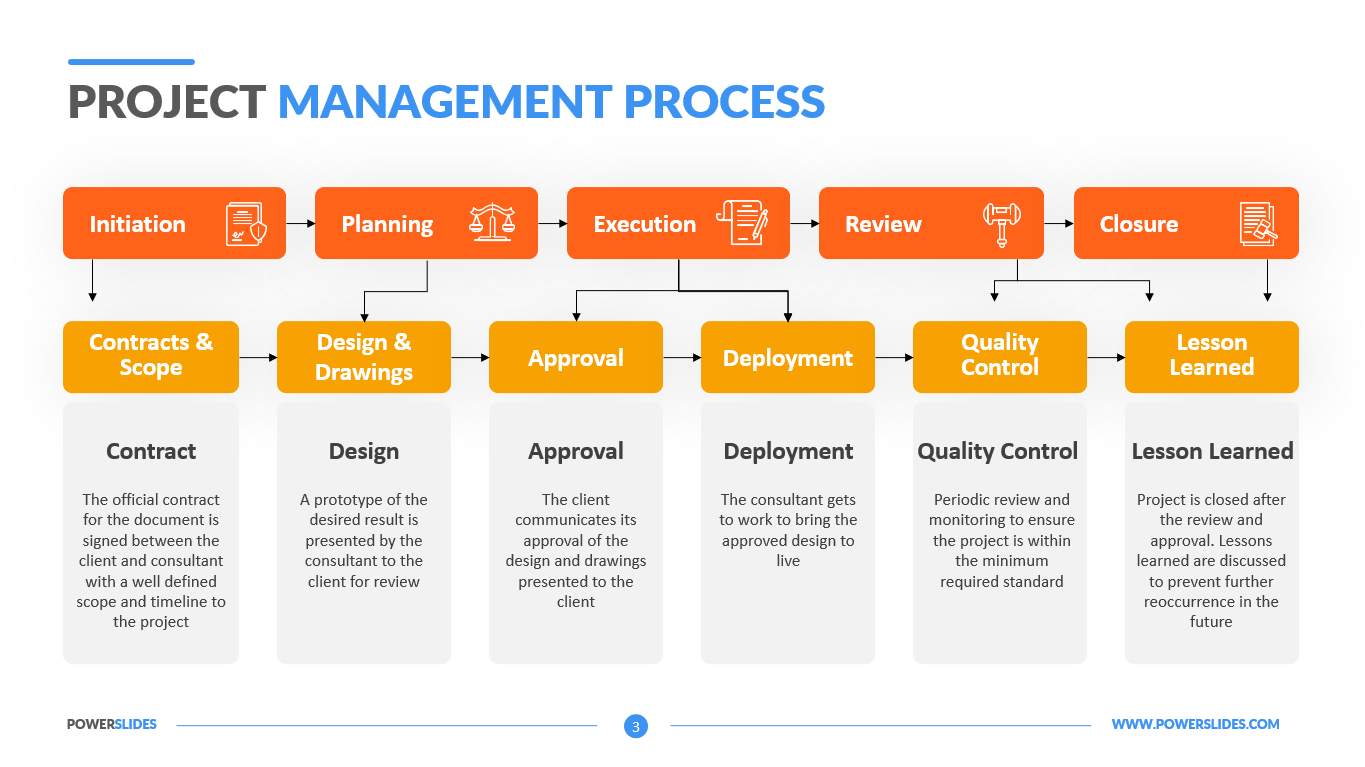
I spent six years managing infrastructure migrations for mid-size companies before I stopped trying to force every project into the same template. The short version is that project management processes are just the documented steps a team agrees to follow so work doesn't collapse under its own weight. But here is what nobody tells you: the process itself matters far less than which parts of it you enforce and which parts you quietly abandon. They are the repeatable sequences for initiating, planning, executing, monitoring, and closing work. The PMBOK breaks them into knowledge areas like scope, schedule, risk, and procurement. That framework was built for large organizations with dedicated PMO teams, not for a four-person team shipping a feature by Friday. I learned that distinction the hard way when I tried to run a full risk register on a three-month web migration that had two stakeholders who answered emails once a week. The actual breakdown most teams need looks like this. Initiation is just defining what problem you are solving and who cares if you solve it. Planning is where you figure out the sequence, the resources, and the acceptance criteria. Execution is the work itself, which is usually where everything goes sideways. Monitoring and controlling is tracking progress against the plan and adjusting. Closing is documenting what happened so the next project does not repeat the same mistakes.
I used to spend four hours building Gantt charts for projects that would have been fine with a shared task list and a weekly sync. That habit ended when my manager at a logistics company asked why a $40,000 warehouse software rollout had 200 tasks and still missed its launch date. The chart gave us the illusion of control while the actual work stayed invisible. We moved to a Kanban board with explicit WIP limits and the project finished two weeks early.
The Parts People Get Wrong
Risk management is the biggest area where beginners waste time. Most people create risk registers full of generic entries like technical challenges or budget concerns. Those entries are useless. A real risk register needs a probability rating, an impact rating, a named owner, and a concrete mitigation step. If you cannot write a specific action that reduces either the likelihood or the consequence, it is not a risk, it is a worry, and worries do not belong in the document. Scope creep is the second classic problem. The standard advice is to implement a formal change control process with signed paperwork. That works in government contracting. In a typical tech startup environment it means three people spend four hours debating whether a new feature request constitutes a change order. The practical alternative is simpler. Maintain a visible prioritized backlog. Any new request gets added to the back unless someone explicitly trades it for something of equal size. No meetings required. Just a public decision on what drops when something new arrives. Communication plans are another place where process becomes performative. I used to write detailed stakeholder matrices showing who needed what information and when. It lasted about three iterations before nobody read it. What actually worked was a single status page updated every Monday morning with four sections: what shipped last week, what is blocked, what is coming next week, and decisions needed from leadership. One page. Five minutes to update. People actually checked it.
Get the Full Details

When the Process Itself Becomes the Problem
Every methodology has breaking points. Waterfall falls apart when requirements change frequently and you cannot afford three-month feedback loops. Agile collapses when you need hard deadlines with fixed scope, like regulatory compliance work or hardware manufacturing. Hybrid approaches sound reasonable until you realize you are running two conflicting systems and your team spends more time reconciling them than doing work. The specific failure I keep seeing is using project management processes for operational work. Running a help desk, maintaining production servers, managing customer accounts, those are ongoing operations with continuous flow. Applying project lifecycles to them creates artificial start and end points that do not exist. You get teams pretending a support ticket triage system is a project because someone in leadership wants to see a timeline. It is not. It is work. Treat it like work with standard operational metrics, not project milestones. Another edge case is small projects with high uncertainty. When you cannot estimate what the work involves, creating a detailed process around it is just theater. A two-week discovery project with a blank-slate architecture decision does not need a risk register or a communication plan. It needs someone competent making calls and a direct line to the person who pays the bills when those calls turn out wrong. I stopped applying full process frameworks to anything under eight weeks and under $50,000. The overhead was eating more time than the process saved.
A Practical Workflow That Actually Stays Alive
Here is what I use now. It applies to projects between two weeks and six months with a team of two to ten people. Anything outside that range gets modified or dropped entirely. Step one: Write a one-page project brief. Title, objective, success criteria, key stakeholders, estimated budget, and target date. That is it. No appendix. If the brief cannot fit on one page, you do not understand the project well enough to start it. Step two: Break the work into deliverables, not tasks. Deliverables are tangible outputs like database schema, API documentation, or deployed infrastructure. Tasks are the daily activities that produce those outputs. List the deliverables first. Fill in the tasks later during sprint planning or weekly setup. Beginners reverse this and plan tasks that disappear when priorities shift.
Step three: Identify the critical path. Not every deliverable matters equally. Find the sequence that determines the earliest possible completion date. Protect that sequence. Everything else can flex. I used to track every dependency across the entire project until I realized half the dependencies were on work that could slip two weeks without affecting the launch. Tracking those false dependencies created work for zero benefit. Step four: Set up a single source of truth. One tool for tasks, one for documents, one for communication. I have seen teams split tasks across Jira, documents across Google Drive, and updates across Slack channels. Nobody can see the full picture. Merge it into one place even if that place is not the fanciest tool available. Step five: Run a fifteen-minute daily check-in or a twice-daily async update. The goal is not status reporting, it is blocking issue identification. What is in your way? What did you finish yesterday? What are you doing today? That is all the information you need. Anything longer turns into a meeting that steals time from actual work.
Step six: Document decisions, not just tasks. A decision log takes five minutes per week and prevents the same debate from resurfacing three months later when the original context is gone. I once spent two weeks reimplementing a feature because the original architecture decision was lost and the team assumed it had been changed. A one-page log would have saved fourteen billable hours.
The Metrics That Actually Matter
Most teams track vanity metrics like task completion percentage or hours logged. These measure activity, not progress. Instead track schedule variance, which tells you if you are ahead or behind plan. Track burn rate versus budget to catch cost overruns early. Track defect escape rate after launch to measure quality. Track stakeholder satisfaction at three points: kickoff, midpoint, and close. Not at the end only, by which time complaints are too late to act on. Cycle time is the most useful metric most teams ignore. It measures how long work takes from start to finish for a single item. If your average cycle time is twelve days and you claim your projects deliver on schedule, you are either lying or your definition of done is wrong. I use cycle time data to set realistic timelines instead of optimistic guesses. A team that delivers features in four days on average should not commit to a twelve-day timeline because they are leaving buffer that invites scope expansion.
When to Drop the Process Entirely
There are honest-to-goodness situations where a lightweight approach beats any formal process. Emergency responses, incident recovery, crisis communications, those require speed and direct authority, not committees and sign-offs. The process in those cases is the escalation path and the decision rights, nothing more. I managed a production outage response where the incident commander made seventeen decisions in ninety minutes without writing a single status report. The documentation came after. The structure was a whiteboard and a phone tree. That is still a process, just not the kind you find in a textbook. Similarly, research and development projects with exploratory goals resist traditional process frameworks. You cannot plan the deliverables when you do not know what you are looking for. The closest thing to a process here is a structured hypothesis cycle with clear go/no-go gates at each stage. If the hypothesis fails, you stop and reassess rather than continuing because the project plan says you should. The reason people over-process is fear. Fear of losing control, fear of being held responsible for failures, fear that without documentation there is no accountability. Those fears are real but the remedy is not more paperwork. It is clearer decision rights, better information flow, and honest post-mortems that focus on system failures rather than individual blame. A team that learns from mistakes without punishment improves faster than a team that follows every process perfectly while hiding problems.