The Problem With Teaching Machines to Be Good
Most people think technology ethics is about writing a code of conduct and hoping engineers read it. It is way more boring and way more painful than that. It is the process of figuring out what happens when a system makes a decision that affects real humans, and then dealing with the fallout when you get it wrong. At its core, technology ethics is the practice of identifying, evaluating, and mitigating the real-world harm that software systems cause before that harm becomes a headline. Not the philosophical version. The operational version. When you ship a model that ranks loan applications, ethics is the question of why your validation set looks different from your production data. When you design a content recommendation engine, ethics is understanding that engagement metrics will optimize for outrage unless you explicitly build constraints against it. I spent three years working on automated decision systems for a mid-size fintech company. The ethics work was never about grand principles. It was about edge cases that kept showing up at 2 AM.
Where It Actually Happens
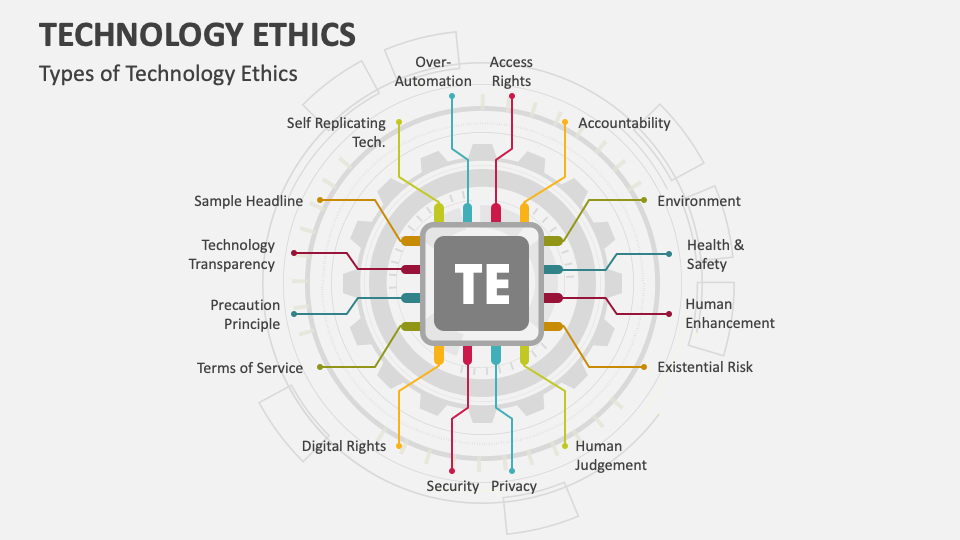
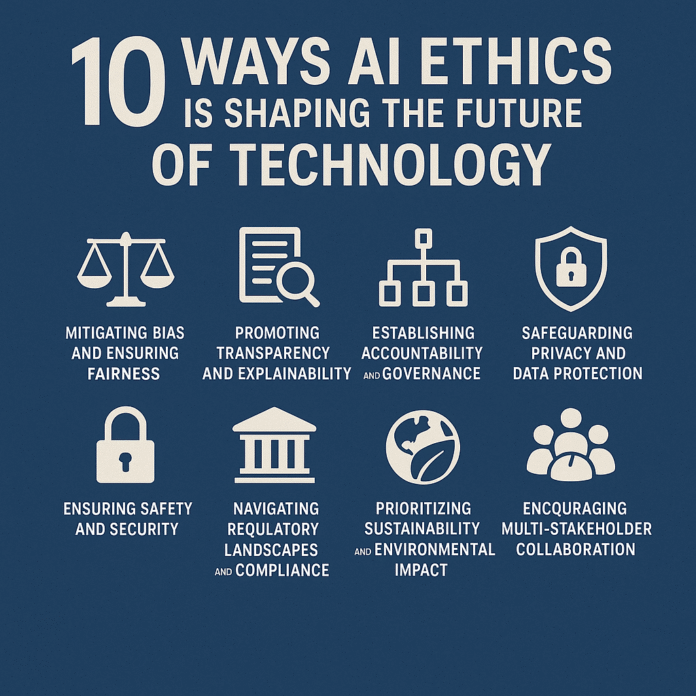
Technology ethics in practice lives in four concrete areas, and they are not equally distributed. Data provenance and bias propagation. This is the first place things go wrong and the hardest place to fix after the fact. If your training data reflects historical inequality, your model will encode that inequality as mathematical objectivity. I once reviewed a credit risk model where the false positive rate for applicants from certain zip codes was nearly three times higher than others, even after controlling for income and employment history. The engineer who built it had no idea. The data just looked clean on the surface. We ended up implementing stratified error analysis across demographic proxies, which caught the drift that overall accuracy metrics completely missed. That took about two weeks of work and saved us from a regulatory review that would have shut the product down. Transparency versus trade secrets. There is a genuine tension here that most ethics frameworks gloss over. You cannot meaningfully audit a system if the company guarding it classifies the architecture as proprietary. The practical workaround I learned is to demand interface-level transparency: what inputs go in, what outputs come out, and what the confidence distributions look like. That gives auditors enough to work with without handing over source code. It is not ideal. It leaves gaps. But it is better than nothing and it is what most regulatory bodies actually accept today.
Accountability chains. Every automated system needs a documented escalation path. When I was on a recommendation systems team, we had a incident where the algorithm started promoting borderline content because the engagement signal was too noisy. No one on call knew how to turn it off fast enough. The fix was simple in hindsight: a kill switch with hard latency requirements and a named owner who could authorize it without management approval. The real work was getting legal and engineering to agree on who that person was. Long-term societal impact. This is the area everyone talks about and almost nobody measures. Social media algorithms are the textbook example. The ethics question is not whether the platformModerate content. It is whether the incentive structure of the business model makes certain types of harm inevitable. You can add content policies all day. If the revenue model depends on maximizing time-on-site, the system will find the path of least resistance to keep people scrolling, and that path often runs through outrage and misinformation.
Get the Full Details
A Practical Framework That Does Not Suck
Here is what actually works when you need to operationalize ethics review without turning it into a theater exercise. I use a modified version of what the EU AI Act calls a risk-based approach, but simplified for teams that do not have a compliance department. First, classify every system you ship by its potential harm level. Low harm: internal dashboards, logging tools. Medium harm: customer-facing recommendations, scheduling algorithms. High harm: hiring tools, medical diagnostics, lending decisions, content moderation at scale. This classification determines how much review overhead you apply. Low harm gets a checklist. High harm gets a full audit trail. Second, require a data sheet for every model. Not a pretty one-page summary. A document that records where the data came from, what preprocessing steps were applied, what the known gaps are, and what demographics or edge cases are underrepresented. I have seen this cut model deployment time by about forty percent once teams stopped treating it as paperwork and started using it as an actual diagnostic tool.
Third, build adversarial testing into your CI/CD pipeline. Run your models against crafted edge cases before every deployment. Test for bias across protected attributes. Test for jailbreaks on generative systems. Test for distributional shift in production data. This is not optional for high-harm systems. It takes about an hour to set up properly and maybe five minutes per deployment run. Fourth, document every decision and the rationale behind it. When something goes wrong, you need to be able to answer three questions: what did we know at the time, what did we choose to ignore, and who made that choice. If you cannot answer any of those, you are already behind.
When It Completely Fails
None of this works if your organization treats ethics as a cost center rather than a system property. I have watched companies hire ethics consultants for a single workshop and then return to shipping features at full speed. The consultant wrote a nice document. Nobody read it. The same bias patterns appeared six months later in production, only harder to catch because the team had convinced themselves the problem was solved. The framework also breaks down in resource-constrained environments. Small teams cannot afford full adversarial testing pipelines or dedicated ethics reviewers. In those cases, you prioritize: focus on the highest-harm systems first, use open-source auditing tools like Google's What-If Tool or IBM's AI Fairness 360, and partner with academic institutions that sometimes offer free audits for smaller companies. It is not perfect. It is practical. There is also a genuine limitation with interpretability. Some of the most effective models today, particularly large language models and deep ensembles, are fundamentally difficult to explain. You can run fairness metrics and bias tests all day, but you still might not understand why the model made a specific decision. The honest answer is that for some high-stakes applications, this uncertainty is a reason not to deploy the system at all, not a reason to deploy it and hope for the best.
The Uncomfortable Truth
Technology ethics is not a problem you solve. It is a problem you manage continuously. The systems get more complex, the deployment speed increases, and the gap between what the technology can do and what society considers acceptable tends to widen, not shrink. The best teams I worked with were not the ones with the most impressive ethics policies. They were the ones that treated ethics as an ongoing engineering discipline with the same rigor as security or reliability. That meant budgets, timelines, and accountability. Everything else was just performative.