Continuity Management Isn't Just a Framework, It's Your Lifeline When Shit Hits the Fan
Most people think continuity management is about writing documents and filling out spreadsheets for auditors. That's not what it is. It's about making sure your organization doesn't flatline when something goes wrong. I've been through enough IRPs that never got used and BC plans that fell apart on day one to know the difference between theater and actual preparedness. The ISO 22301 standard gives us a structure to work from, but the real steps come from years of people like me learning what breaks and what holds.
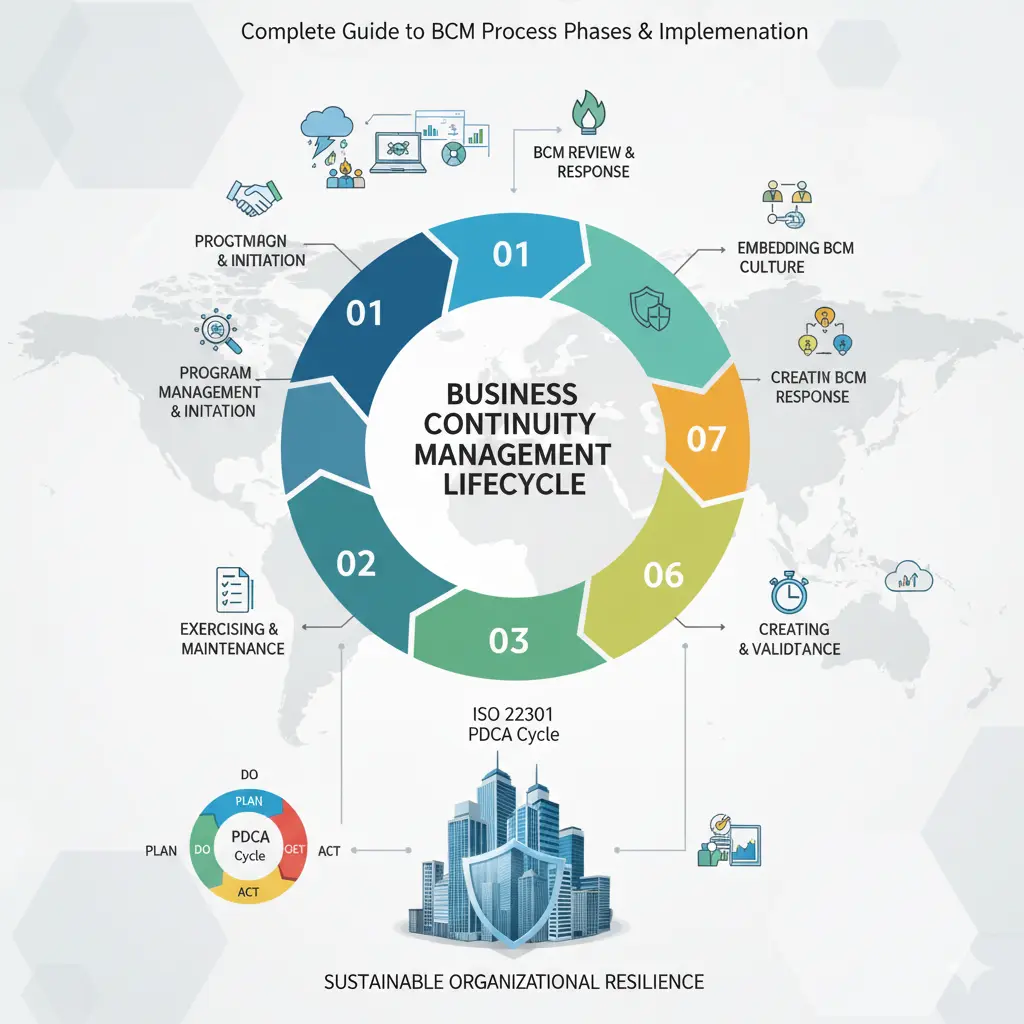
What Are The 7 Steps Of Continuity Management
1. Policy and Program Management This is the foundation. You need documented policy that defines scope, objectives, roles, and responsibilities. Without this, everything else is just opinions with paperwork. I once saw a company try to launch a business continuity program without a signed policy from executive leadership. The IT director took it seriously. The facilities team did not. Within six months the program was invisible to anyone outside three people in compliance. Get the policy signed, get the budget attached, and move on. 2. Business Impact Analysis (BIA)
The BIA is where most programs go off the rails. People confuse it with a risk assessment. It isn't. A BIA answers a very specific question: what happens if this process stops, and how bad does it get over time? You need to identify critical business functions, determine their RTO and RPO, and understand the cascading dependencies. I spent three weeks once on a BIA for a mid-market manufacturer only to discover their "critical" ERP system was dependent on a single outsourced payroll vendor who had no backup site of their own. That vendor wasn't in any of their contracts. We had to build a workaround involving manual processes and a secondary data feed until they could negotiate proper SLAs. That's the kind of thing a BIA reveals, and it's also the kind of thing most BIAs miss because someone filled out a questionnaire instead of walking the floor. Run interviews. Trace data flows. Don't rely on self-reported dependency maps. They are wrong more often than you think. 3. Risk Assessment
Get the Full Details
Now you look at what could actually threaten those critical functions. This is where you layer threat scenarios onto your BIA findings. Natural disasters, cyber incidents, supply chain failure, regulatory changes, key person loss. The key insight most people miss is that risk assessment and BIA are separate exercises. One tells you what matters. The other tells you what could hurt it. Do not merge them into a single document. They serve different purposes and require different stakeholders. I ran a risk assessment for a healthcare client where they had identified flood risk as their top environmental threat, but their actual RTOs were being driven by a single third-party cloud provider whose SLA allowed 72 hours for restoration. The flood scenario was irrelevant. The provider concentration was the real risk. Fixing that required a multi-region failover strategy, not sandbag recommendations for the basement server room. 4. Incident Response and Emergency Management
This step is about the immediate response. When something happens, you need a clear chain of command, communication protocols, and escalation procedures. Most organizations get this wrong by building elaborate incident response plans that nobody can remember under stress. I've seen plans with twelve escalation tiers. By the time someone worked through tier seven, the problem had already been sitting unaddressed for four hours because nobody knew who tier seven even was. Keep it simple. Define the incident classification, name the people who make decisions, and give them contact information that works when the primary systems are down. Paper phones. Burner numbers. Signal usernames. Something that doesn't depend on the thing that just broke. 5. Business Continuity Planning
Now you build the actual recovery plans. These are process-level documents that tell specific teams how to keep operating or resume operations within their RTO windows. A BCP for the finance team looks nothing like a BCP for the shipping department. They address different functions, different dependencies, and different recovery strategies. The mistake here is treating BCP as a template exercise. Copy-pasting a template across departments produces documents that look good in a folder and are useless in an incident. I spent a day with a logistics team once and found their BCP called for rerouting shipments through a port that had been underwater for three weeks during the actual scenario they were planning for. They'd written the plan from an office desk without checking current conditions. Plans need to be living documents with verification triggers, not filed artifacts. 6. Training, Awareness, and Exercises

This is where most programs die. You can have the best policies, BIAs, risk assessments, and plans in the world, but if nobody knows how to use them, they don't exist. Training isn't an annual compliance checkbox. It's the difference between a team that freezes and a team that executes. I ran a table-top exercise for a retail client where the designated incident commander couldn't find their contact list because it lived on a network drive that was offline. The assistant Incident Commander, who had never been named in any plan, took over by default and made better decisions in twenty minutes than the formal IC had made in two hours of panic. That exercise taught me more about organizational resilience than three years of documentation reviews. Run exercises that break things. Stress-test assumptions. After action reports are mandatory, not optional. The people who skip AARs are the same people who repeat the same failures every time.
7. Review, Audit, and Continuous Improvement The final step is the one nobody does well. You need to periodically review the entire program, audit against your standards, and make improvements based on what you've learned from exercises, incidents, and organizational changes. This isn't a once-a-year event. It's an ongoing cycle. My approach is brutal simplicity: after every exercise, every real incident, and every major organizational change, update the relevant plans and document what changed and why. Keep a change log. If your program hasn't been updated in six months, something is wrong. People get promoted. Systems change. Vendors get acquired. The plan becomes stale and the next incident exposes it.
Why This All Falls Apart in Practice
Continuity management has a fundamental weakness that no textbook admits: it assumes you can predict the next disruption. You can't. The 2020 pandemic exposed this clearly across every industry. Organizations that had run COVID-specific tabletop exercises two years earlier fared noticeably better than those that hadn't, but even the prepared ones struggled because the scale and duration exceeded every model they had built. The workaround is building flexibility into your plans rather than specificity. Instead of writing a plan that says "switch to Site B at 2 PM," write a plan that says "if primary site is unavailable, here are the decision criteria for activation and here's who makes the call." Decision rights matter more than scripted sequences. Another structural problem is that continuity management competes for attention against everything else in the organization. The person responsible for it usually has five other jobs. The result is a program that exists in documentation but not in operational reality. The fix is ownership. Someone needs to own this full-time, or the program needs executive sponsorship that includes budget authority, not just signature authority.

I've seen single-threaded continuity managers carry programs for organizations of four thousand people. It doesn't work. The scope exceeds one person's capacity regardless of how competent they are. Either hire properly or distribute ownership across functional leads with a central coordinator. The seven steps aren't a checklist. They're a framework for building organizational resilience. The difference matters when the phone rings at 3 AM and you need to know whether your organization will survive the next hour, let alone the next quarter.


