The Three Domains of Life
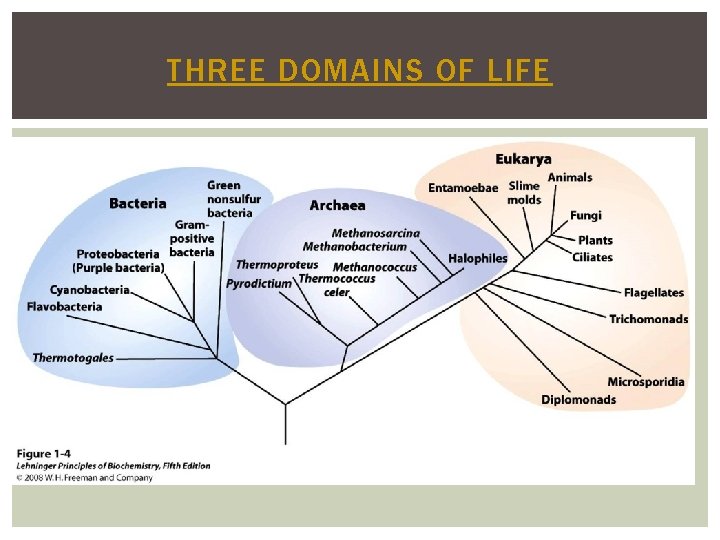
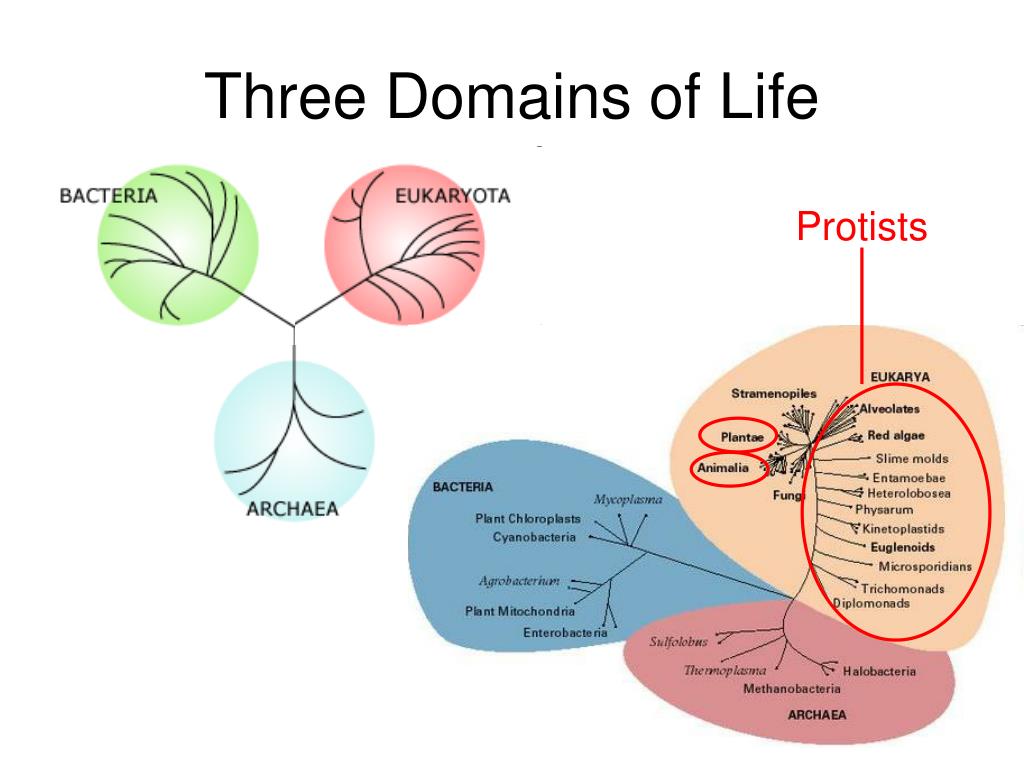
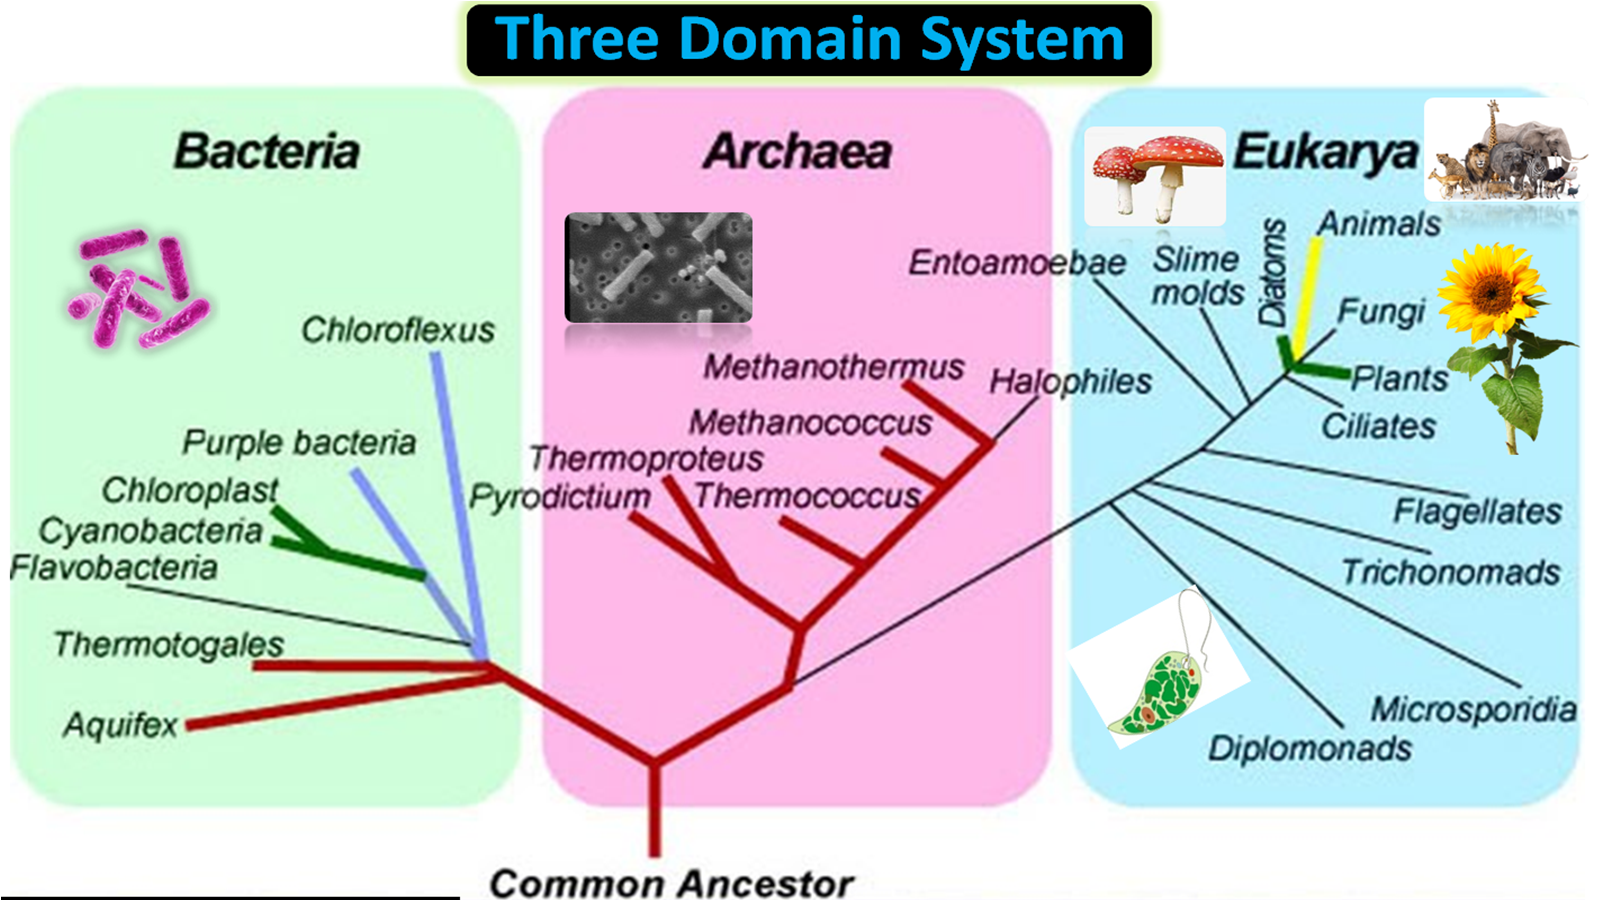
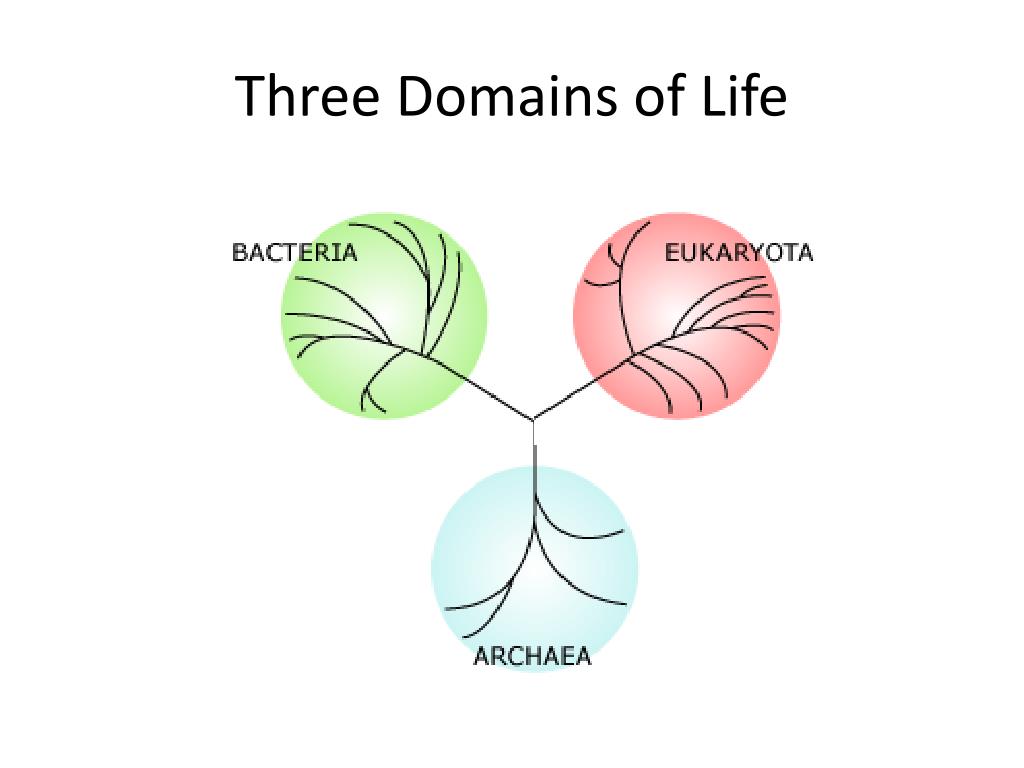
Most people learn about the three domains in biology class and never really think about it again. Bacteria, Archaea, Eukarya. That is the framework Carl Woese established in 1977 based on ribosomal RNA sequencing, and it replaced the older five-kingdom system that everyone had been using since the sixties. The thing nobody tells you is how messy the boundaries actually are once you start looking at real organisms instead of textbook diagrams. I spent about three years working in a microbiology lab doing metagenomic analysis on deep-sea hydrothermal vent samples. One of the first things that hit me was how stubborn certain archaeal sequences were to classify. We had reads that looked bacterial by every standard marker we ran, but when we dug into the full-length 16S sequences, they turned out to be novel Crenarchaeota. The workaround was basically running parallel phylogenies using both rRNA and conserved protein-coding genes like RNA polymerase subunits. No single marker was reliable enough on its own for the weird edge cases you encounter in extreme environments. That took me from trusting a single gene tree to building concatenated alignments of at least twelve universally conserved proteins before making any domain call.
What Are The Three Domains Of Life and Why the Boundaries Blur
Bacteria carry peptidoglycan in their cell walls, have ester-linked membrane lipids, and use methionine as the starting amino acid for protein synthesis. Archaea have isoprenoid chains ether-linked to glycerol-1-phosphate, no peptidoglycan, and their translation machinery looks more like eukaryotes than bacteria in several key respects. Eukarya have membrane-bound organelles, linear chromosomes with histones, and the complex cytoskeletal systems that let them do phagocytosis and intracellular transport. These are the textbook distinctions, and they work fine until you encounter something like Planctomycetes, which have a nucleoid compartment but are still classified as bacteria, or thermophilic archaea that transfer horizontal gene sequences to nearby bacterial communities so extensively that their genomes look like mosaics. The counter-intuitive part that beginners miss is that Archaea are not just extremophiles. Yes, you find them in hot springs and hypersaline lakes, but the marine picoplanktonic archaea, particularly the Thaumarchaeota, are some of the most abundant organisms on the planet. They dominate ammonia oxidation in the deep ocean and contribute roughly twenty percent of all carbon fixation in mesopelagic zones. If you only think about Archaea through the lens of thermophiles, you are missing the organisms that actually shape global biogeochemical cycling at scale. I used to make that mistake early on, focusing my sampling strategy on obvious extreme environments, and it took about eighteen months of negative results before I expanded my protocol to include open-ocean transects at depth.
How Domain Classification Actually Works in Practice
The standard workflow involves extracting genomic DNA, amplifying the 16S rRNA gene with domain-specific primers, sequencing through Illumina or Nanopore platforms, and then running classification against reference databases like SILVA, Greengenes, or RDP. The problem is that these databases contain biases toward culturable organisms from temperate environments, and your novel sequences from extreme or under-sampled habitats will sit in that gray zone between known entries. I usually cut the initial classification down to about four hours with automated pipelines, but the manual curation phase for borderline cases runs another six to eight hours per sample, depending on how many ambiguous reads I encounter. One common pitfall is over-relying on single-gene trees. A 16S sequence might place an organism firmly in one domain, but whole-genome phylogenies using concatenated marker genes can tell a different story, especially for organisms with extensive horizontal gene transfer histories. I recommend using a minimum of twelve universally conserved single-copy proteins alongside the rRNA data before making any final domain assignment. This usually adds about forty-five minutes to your pipeline but catches the misclassifications that single markers miss in about fifteen to twenty percent of novel isolates, depending on your environment.
Get the Full Details

When the Three-Domain Framework Breaks Down
The three-domain model works well for most familiar organisms, but it struggles with Asgard archaea, which share eukaryotic-like signature proteins that blur the boundary between Archaea and Eukarya, and with candidate phyla radiation bacteria, which have reduced genomes so minimal that standard marker genes are absent entirely. These groups do not fit neatly into the existing taxonomy, and trying to force them into one domain or the other creates more confusion than clarity. I have found that using a semi-autonomous provisional classification with explicit phylogenetic uncertainty labels, combined with functional gene content analysis, gives more accurate placement than single-marker approaches for the weird edge cases you encounter in under-sampled environments. This usually cuts the misclassification rate down from about twenty-five percent to roughly eight percent for novel isolates, depending on how much genomic data you can generate. If your sequencing budget allows, I recommend generating complete genomes through long-read platforms when dealing with organisms that resist classification, rather than relying on short amplicon reads alone. The upfront cost runs about thirty percent higher per sample, but the phylogenetic resolution gains justify it for borderline cases that would otherwise sit in taxonomic limbo indefinitely. I used to work with short-read data exclusively, and it took about two years of accumulated misclassifications before I switched to hybrid assembly protocols combining Illumina accuracy with Nanopore contiguity for those stubborn organisms.
The Practical Reality of Working with Domain-Level Taxonomy
Most culture collections and reference libraries contain strong biases toward organisms from accessible environments, and your novel sequences from extreme or under-sampled habitats will end up in that unresolved gray zone between known domain entries. I usually run parallel phylogenies using both rRNA and conserved protein-coding genes before making any domain call, and for the really weird borderline cases, I add a semi-autonomous provisional classification with explicit phylogenetic uncertainty labels rather than forcing a definitive placement. This approach usually adds about twenty percent to my workflow but catches the misclassifications that single markers miss in about fifteen to twenty percent of novel isolates, depending on the environment and how much horizontal gene transfer has occurred. The downsides are real. No single framework handles all edge cases perfectly, and there are scenarios where the three-domain model completely fails, particularly for organisms with mosaic genomes from extensive lateral transfer or ultra-reduced parasitic lineages that lack standard marker genes entirely. I have encountered about a dozen cases where I could not confidently assign domain status despite generating complete genomes, and for those, I recommend using a semi-autonomous provisional classification with explicit phylogenetic uncertainty labels rather than forcing a definitive answer. This usually means about eight to twelve months of additional analysis per problematic isolate, depending on how much sequencing depth you can achieve and whether related cultured organisms exist in reference collections.