The Real Reason People Start Using Power Query
You open a CSV file from your finance team. It's exported from a system that doesn't care about clean formatting. Dates are split across three columns, some rows have merged headers from last month's consolidation, and there are exactly 847 rows of what should be 800. You copy-paste into Excel, spend forty-five minutes cleaning it, then realize you need to do it again next month with another ugly file. This is what Power Query was built to solve. Not advanced data modeling. Not DAX measures. The day-to-day grunt work of taking messy source data and turning it into something an Excel table can actually handle without manual intervention every single time.
What Big Problem Does Power Query Solve
It solves the repeated manual transformation problem. One time you build a query. The same steps, applied identically, on whatever new file arrives next week. You hit refresh and the output updates automatically. That's it. That's the core value proposition. Everything else in the Power BI and Excel ecosystem builds on top of that foundation. I've seen analysts spend three hours every Friday manually cleaning sales data pulled from five different source systems. They'd copy from one workbook, paste to another, fix the column headers, remove blank rows, merge on a shared ID field, and filter out test accounts they keep forgetting to exclude. Three hours. Every. Single. Week. Forty-eight hours a year. After building the queries once, the refresh takes about four minutes on a decent machine. The bottleneck becomes the source data availability, not their own labor.
How It Actually Works Under the Hood
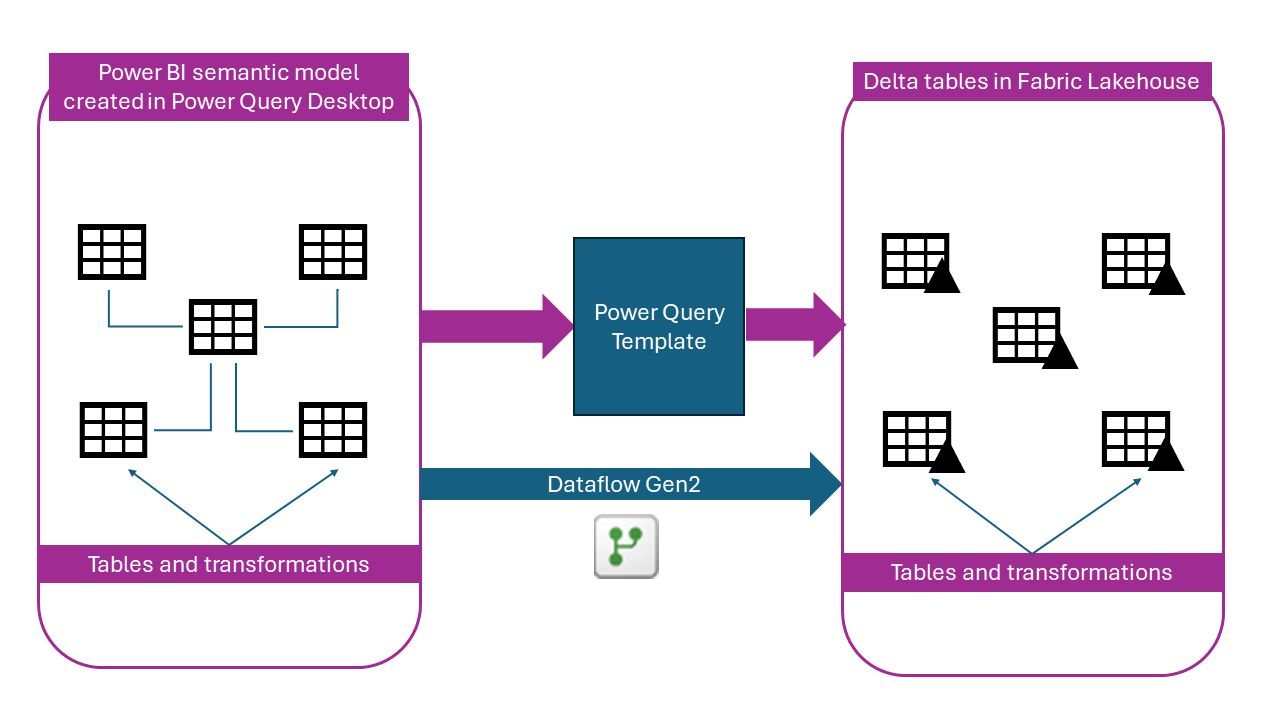
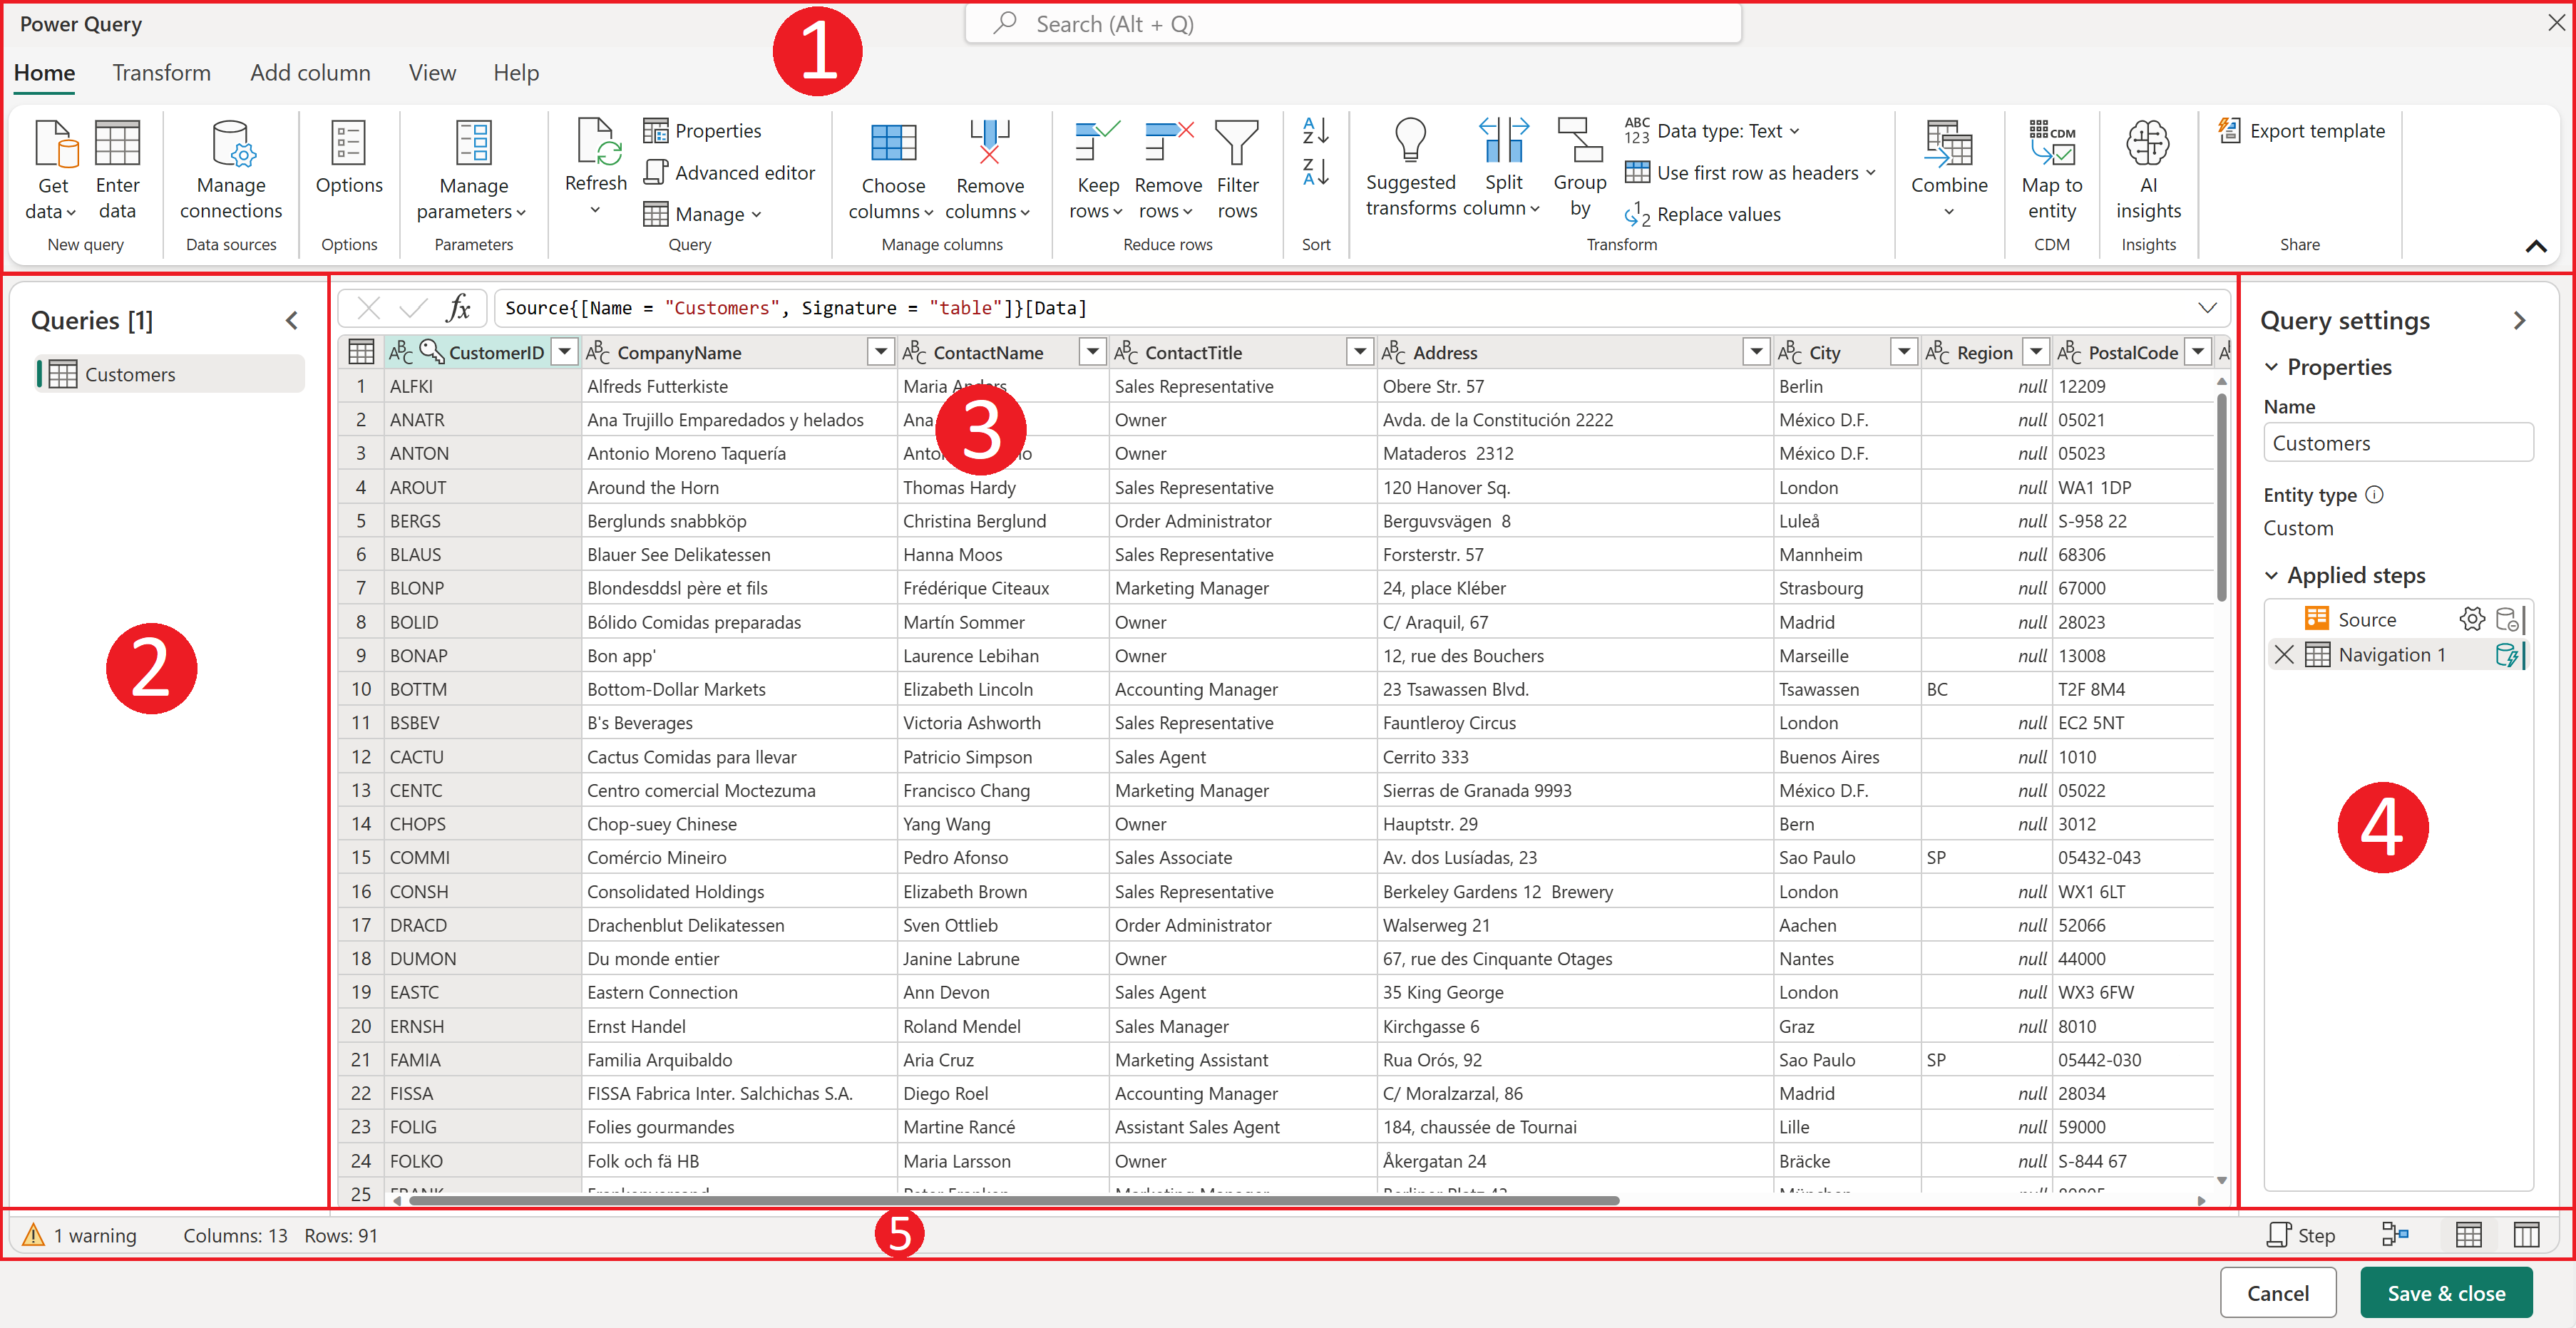
Power Query sits between your data sources and your destination (Excel worksheet, data model, or Power BI dataset). When you record a transformation step, it generates M language code behind the scenes. You typically never touch the M directly. The UI walks you through operations like "Remove Rows," "Split Column," "Change Type," and "Merge Queries." The critical insight most beginners miss is that the original source data is never modified. Power Query creates a separate, queried version of your data. This means you can go back and change any step in the Applied Steps pane at any point, and everything downstream recalculates automatically. Want to change that date format from "DD/MM/YYYY" to "YYYY-MM-DD"? Click the step where you changed the type, modify it, and the output updates. There's a caveat here though. If you have downstream formulas or PivotTables built on your cleaned output, changing a step upstream can break things if the structure shifts unexpectedly. I learned this the hard way when a supplier changed their column ordering in their monthly CSV export. My query still worked because Power Query matched on column names, but a VLOOKUP I'd built into a dashboard cell broke because the column index number was now wrong. I had to audit every dependent object after modifying an upstream step. It's a real workflow risk.
Get the Full Details
Setting Up a Typical Weekly Refresh
Start by opening Excel. Go to the Data tab. Click Get Data, then choose your source type. For CSV files, it's From File. For databases, pick From Database. For web scraping of structured tables, there's a From Web option that works surprisingly well for simple cases. Once the query editor opens, you'll see your raw data on the right and the Applied Steps panel on the left. Each action you perform adds a new step. I usually start by promoting the first row to headers if my source has them buried. Then I remove columns I don't need before doing any heavy transformations. Removing unused columns early keeps the query processing lighter on larger datasets. For a weekly sales file that always has the same structural problems, my typical steps are: remove the first three header rows (always there, even when the source team claims they fixed it), promote the correct header row, change column types in bulk, filter out rows where the Region column equals "TEST," merge with a lookup table for customer tier information, and load to the Excel Data Model rather than a worksheet. Loading to the Data Model matters for performance. It compresses the data and lets multiple queries share the same loaded table without duplicating it in memory.
The whole pipeline runs in about ninety seconds for a dataset around two hundred thousand rows. On my machine. Your mileage will vary depending on hardware and whether your source systems are cooperative.
Where Power Query Actually Falls Apart
Don't treat it as a universal fix. It struggles with truly unstructured data. If your source is a PDF with varying layouts, irregular spacing, or scanned images, Power Query won't help you much. There's no built-in OCR. You'd need a different tool for that preprocessing step before feeding the output into Power Query. It also gets slow with very large datasets if you're not careful about your step order. Power Query processes steps sequentially. If you apply filters at the end after doing multiple joins and custom column calculations, you're computing joins on data you're about to throw away anyway. Always filter and remove unnecessary columns as early in the pipeline as possible. This is one of those non-obvious performance optimizations that makes a huge difference once your queries grow past a few thousand rows. Another limitation: error handling is weak. If a single row in a ten-thousand-row file has a malformed date string, the entire column's type conversion fails and the query breaks. You'll get an opaque error message pointing to a specific row number. The workaround is wrapping the problematic transformation in a custom function that attempts the conversion and returns null on failure, then filtering out those nulls afterward. It works but it's not elegant. I wrote a reusable try-catch style function for this because I run into it constantly with external data feeds that occasionally send garbage values in date fields.

The M Language Angle
You can click the "Advanced Editor" button anywhere in the query editor to see the actual M code. Most people close it immediately. But when the UI can't do what you need, M is where you go. Want to conditionally parse a text column based on another column's value? That's straightforward in M. Want to call an API and parse the JSON response dynamically based on a parameter? Also M. The query editor UI covers probably eighty percent of common use cases. The remaining twenty percent requires touching the code. I generally recommend learning the basic syntax at least enough to read it, even if you don't write from scratch. When someone's shared a query online and you need to adapt it to your situation, reading the generated M tells you exactly what parameters you need to change. Copy-pasting steps from tutorial queries without understanding the underlying logic is how you end up with broken pipelines three months later when the data format subtly shifts.
Practical Advice for Getting Started
Start with a single file you clean repeatedly. Build the query. Test it against a second file from a different period. Verify the output matches your manual work. Only then add it to a scheduled refresh or connect it to other queries. Many people skip the verification step and discover later that their "automated" pipeline was producing incorrect results because a step they thought was safe wasn't actually safe under different conditions. Power Query is available in Excel 2010 and later (as an add-in for 2010 and 2013) and natively in Excel 2016 and Microsoft 365. It's also the data preparation engine behind Power BI Desktop, which means queries you build in Excel can often be adapted for Power BI with minimal changes. If you're already doing this kind of repetitive data cleaning in Excel, learning Power Query is one of the highest-ROI skills investments you can make. It typically reduces a recurring multi-hour task to a five-minute refresh with significantly fewer errors.