The Mechanics of Chain Growth
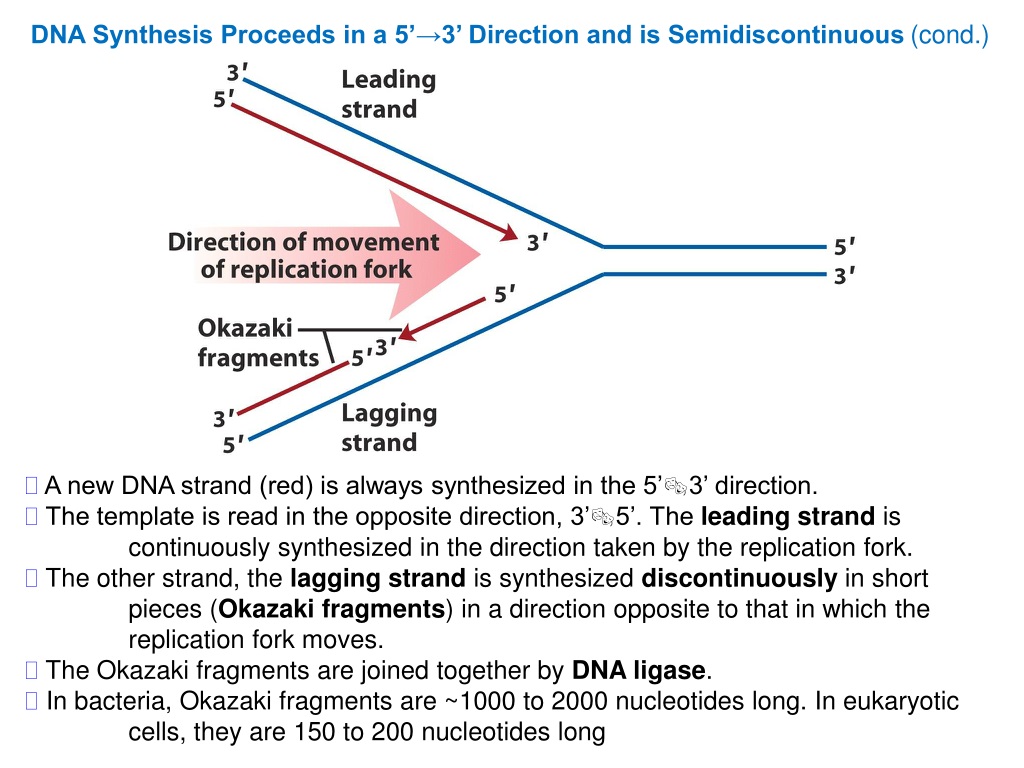
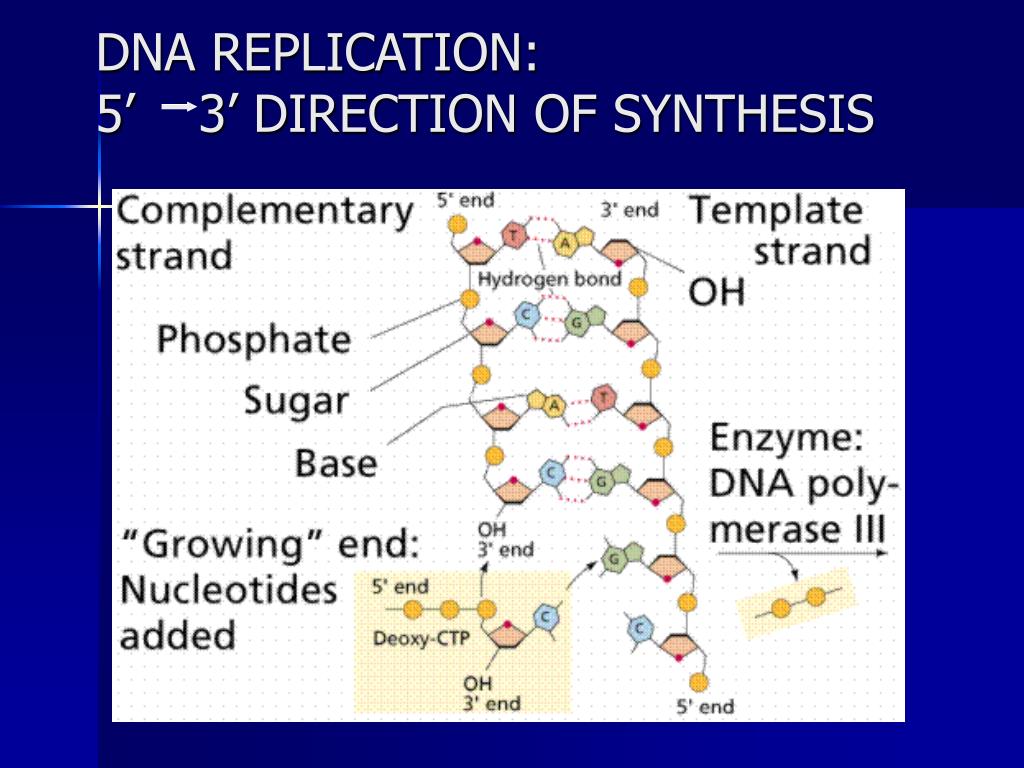
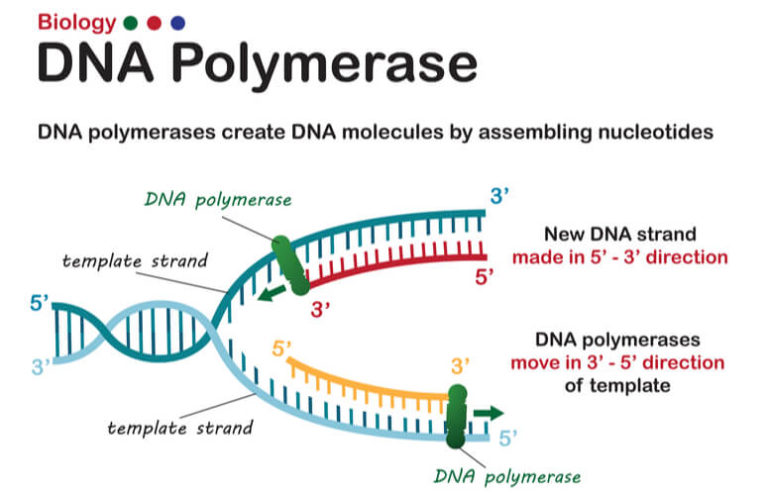
DNA polymerase adds nucleotides only to the 3' hydroxyl end of a growing strand. This means new DNA is always synthesized in the 5' to 3' direction. It is not a choice the enzyme makes. The chemistry dictates it. The incoming nucleoside triphosphate pairs with the template strand, and its alpha phosphate reacts with the free 3' OH group. A phosphodiester bond forms, pyrophosphate is released, and the chain extends by one base. That is the entire reaction. It repeats until the polymerase falls off or hits a terminus. Five prime to three prime. Always. There is no biological exception to this in standard replication or transcription-coupled repair. Some people get confused because the two strands of the double helix run antiparallel, and that creates the leading-lagging strand problem during replication. The leading strand is built continuously toward the replication fork. The lagging strand is built in short Okazaki fragments away from the fork, each one still going 5' to 3', just packaged backwards relative to fork movement. The direction never changes. Only the geometry does. I spent a week troubleshooting a ligation failure in a cloning project back when I was doing manual subcloning before NGS made everything trivial. I had gel-extracted a PCR product and a digested vector, both supposedly clean, and T4 DNA ligase refused to join them despite checking every condition. The issue was that one primer had been designed with a three-base 3' overhang that created a nick the polymerase couldn't fill in the right context. The fragment was technically 5' to 3' like everything else, but the 3' end was non-phosphorylated and the ligase needed that phosphate to work. I ran a quick alkaline phosphatase kill on the vector to prevent self-ligation, then treated the insert with T4 polynucleotide kinase to add the phosphate back. Ligated on the next try. Cost me about four hours total instead of the full week of wondering what went wrong.
Here is something most textbooks gloss over. The 5' to 3' rule applies to polymerization, but there are real exceptions when you look at how certain repair pathways and viral mechanisms actually operate. Some RNA-dependent RNA polymerases in viruses can read through structures that would stall a standard DNA polymerase, and the directionality constraint still holds, but the kinetic behavior is dramatically different. More importantly, terminal deoxynucleotidyl transferase (TdT) adds nucleotides without a template at all, and it still goes 5' to 3'. Template independence does not mean direction independence. Another thing people miss: the 3' to 5' exonuclease activity that most high-fidelity polymerases carry is a proofreading function, not a synthesis direction. When the enzyme hits a misincorporated base, it pauses, backs up, chews the wrong nucleotide from the 3' end, then resumes forward synthesis. The excision moves 3' to 5', but the actual bond formation still proceeds 5' to 3'. Confusing the two activities leads to bad experimental design, especially when you are picking a polymerase for a specific application. If you need a fast, blunt-ended product for TOPO cloning, a polymerase with strong 3' to 5' proofreading can actually hurt you because it trims the A-overhangs that TOPO relies on. You want a standard Taq in that case, not a Phusion or Q5. In practice, synthetic biology has pushed this constraint into interesting territory. Enzymes likephi29 polymerase with its strand displacement ability let you do rolling circle amplification, which generates long concatemers of repeated sequence. The synthesis direction is still 5' to 3', but the enzyme goes around a circular template repeatedly, displacing the newly made strand ahead of it. This is how some isothermal amplification methods work, and it is useful when you do not have a thermocycler. The tradeoff is that phi29 has a higher error rate than some of the engineered high-fidelity blends, so you pay accuracy for convenience.
Chemical DNA synthesis on a synthesizer machine is a different beast entirely. It goes 3' to 5' because it is solid-phase chemistry, not enzymatic. Each cycle adds one nucleotide to the 5' end of the growing chain that is anchored at the 3' end to a solid support. The directions are opposite, and the reasons are pure practicality. The 3' end needs to be tethered, and the 5' hydroxyl needs to be deprotected and coupled in each cycle. Enzymatic synthesis in the 5' to 3' direction is harder to automate on a chip because you need a free 3' OH to extend from, and anchoring that while cycling reagents through is messy. That is why most commercial oligo synthesis is still chemical, not enzymatic. The limitation of chemical synthesis is well known. Yield drops sharply after about 150 to 200 nucleotides. Each coupling step is maybe 98 to 99.5% efficient, and that compounds multiplicatively. A 200mer at 99% per step gives you roughly 13% full-length product. You get a mess of deletions and truncations that makes assembly difficult without careful purification. Enzymatic methods like rolling circle or nick translation are being developed to push past this, but they are not yet routine for long custom genes. If you need something longer than 200 bases, you either order shorter fragments and assemble them, or you pay for gel extraction and hope the band you cut out is mostly full length. Gene synthesis companies handle this by splitting your sequence into overlapping oligos, usually 60 to 100 bases each, and using an assembly method like Gibson or Golden Gate. The directionality rule still applies during the polymerase fill-in step of Gibson assembly. Each fragment is extended 5' to 3' across the overlap region, creating complementary overhangs that anneal and get sealed. The final product is a continuous double-stranded DNA molecule, but the construction process is essentially a puzzle where every piece has to be oriented correctly. If you mix up the order, you will get the right bases in the wrong arrangement, and sequencing is the only way to catch it.
Get the Full Details
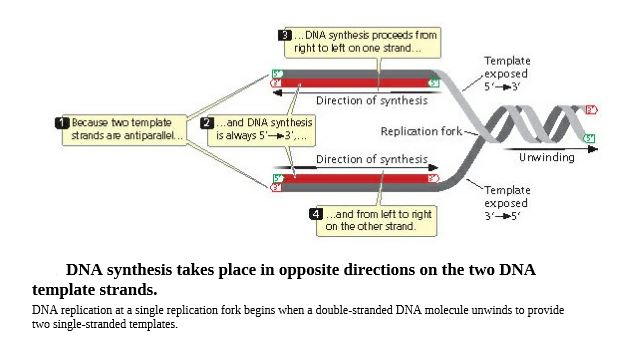
PCR itself is just repeated cycles of 5' to 3' synthesis by a thermostable polymerase. Forward primer binds, polymerase extends toward the reverse primer. Reverse primer binds, polymerase extends toward the forward primer. Each cycle doubles the target. The primers define the boundaries, and the polymerase fills between them. It is mechanically simple, which is why it remains the most widely used technique in molecular biology despite being around since the mid-1980s. One practical detail worth noting: when you design primers, the 5' end of your primer can have arbitrary overhangs for restriction sites or homology arms, but the 3' end must be perfectly complementary to the template for efficient extension. A single mismatch at the 3' terminal position can reduce amplification efficiency by an order of magnitude or more, depending on the sequence context. This is why primer design software weights the last few bases heavily. The polymerase does not care about your overhangs. It only cares about the 3' end being properly paired.