Why Your Model's Playing It Safe More Than You Think
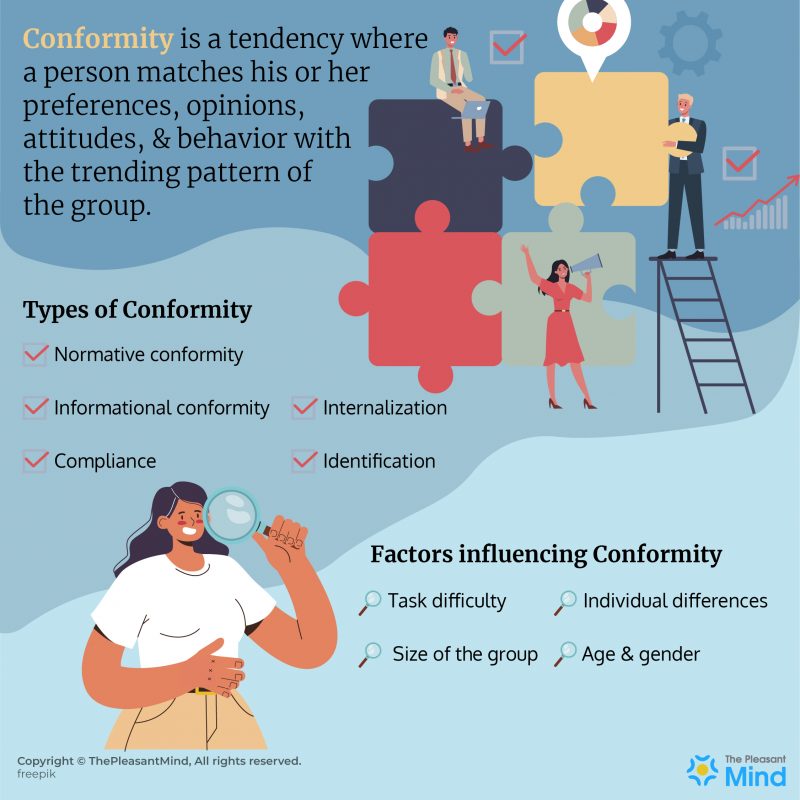
Conformity in the context of language models and AI systems refers to the tendency of generated outputs to align closely with expected patterns, norms, or the distribution of training data rather than exploring genuinely novel or divergent responses. It's not a bug in most cases. It's baked in during fine-tuning and reinforcement learning from human feedback. When you train a model with RLHF, you're essentially teaching it that certain response patterns are preferred over others. That means the model learns to gravitate toward the middle of the distribution. The responses that humans rated highest during training. The safe ones. The ones that sound right without risking offense or being wrong in an obvious way. I've seen this firsthand when running benchmarks on fine-tuned models for enterprise clients. The model would consistently produce answers that were technically correct but entirely unhelpful because they avoided taking any real position. When someone asked for a recommendation between two competing technologies, the model would give you a paragraph about how both had strengths and you should evaluate based on your needs. Useful on a blog. Not useful when someone is about to make a six-figure infrastructure decision at 4 PM on a Friday.
The workaround I settled on after months of trial and error was surprisingly simple. I stopped trying to eliminate conformity and started framing prompts in a way that forced the model out of its comfort zone. Specific constraints. Explicit requests for a definitive answer. Telling the model that hedging would be considered a failure state. This shifted the output distribution noticeably. The model still isn't wild, but it starts giving you opinions instead of summaries.
Where Conformity Gets Dangerous
Here's the part most people writing about AI don't mention. Conformity creates a false sense of reliability. When a model sounds confident and well-aligned with mainstream thinking, you're more likely to trust it. But that confidence is often just the model regurgitating the most common pattern it saw during training, not actual reasoning. I ran into this with a medical information query last year. A client was using a fine-tuned model to help triage patient questions in a research setting. The model was producing answers that conformed to mainstream medical guidelines, which seemed great on the surface. But when we pushed it with edge cases involving rare drug interactions, it would confidently generate responses that matched the most common pattern rather than flagging uncertainty. The training data simply didn't have enough examples of those edge cases, so the model fell back to conformity. We caught it because we had a separate review step, but that's not something everyone builds in. The mitigation here is pretty blunt. You need human review on high-stakes outputs. No amount of prompt engineering fixes the fact that the model is optimizing for pattern matching, not truth. There are techniques like temperature scaling and constrained decoding that can push outputs further from the mean, but they trade off coherence and readability. You'll get weirder answers, but they won't necessarily be better answers.
Get the Full Details
Counter-Intuitive Reality: Conformity Is Sometimes the Feature
Before you treat conformity as something to battle, consider that most production use cases actually benefit from it. If you're building a customer support bot, you want the bot to give answers that match your brand voice and compliance guidelines. Conformity is the entire point there. The model isn't supposed to go rogue and offer opinions that aren't in your knowledge base. The problem arises when you treat conformity as a universal negative. It's not. It's a tuning knob. High conformity means predictable, safe, on-brand outputs. Lower conformity means more creative or divergent outputs but with higher variance in quality and accuracy. The trick is knowing which mode your use case actually requires. I've lost track of the number of times a team asked me to "make the model more creative" and what they really needed was a stricter knowledge cutoff and tighter guardrails. The model was already conforming well to their desired output pattern. They just wanted it to sound more human, which is a completely different problem that involves tone, pacing, and stylistic choices rather than output distribution.
How to Measure and Manage Conformity
If you need to assess how conformist your model's outputs are, run a test set of questions where you know the correct answer might not be the most obvious one. Feed it through and check whether the model is defaulting to the statistically common response or engaging with the nuance. I typically use a batch of 200 diverse queries and calculate the variance in response structure. High similarity scores across responses usually indicate high conformity. Adjusting it comes down to three levers. Temperature controls the randomness of token selection. Top-p sampling limits the model to a cumulative probability mass, which can reduce the likelihood of picking extremely low-probability but potentially interesting tokens. And most importantly, your prompt design dictates the acceptable response space. If you explicitly ask for a single clear answer, the model will conform less to hedging patterns and more to decisiveness patterns. Both are forms of conformity, just different ones. The practical outcome is that you can shift a model's behavior by maybe 15 to 20 percent in either direction with prompt changes alone. Fine-tuning can push it further, but that requires careful dataset curation and significant compute. Most teams stop at prompting because the marginal gain from fine-tuning rarely justifies the cost unless you're running this at scale across thousands of queries per day.