Understanding Homophones in Practice
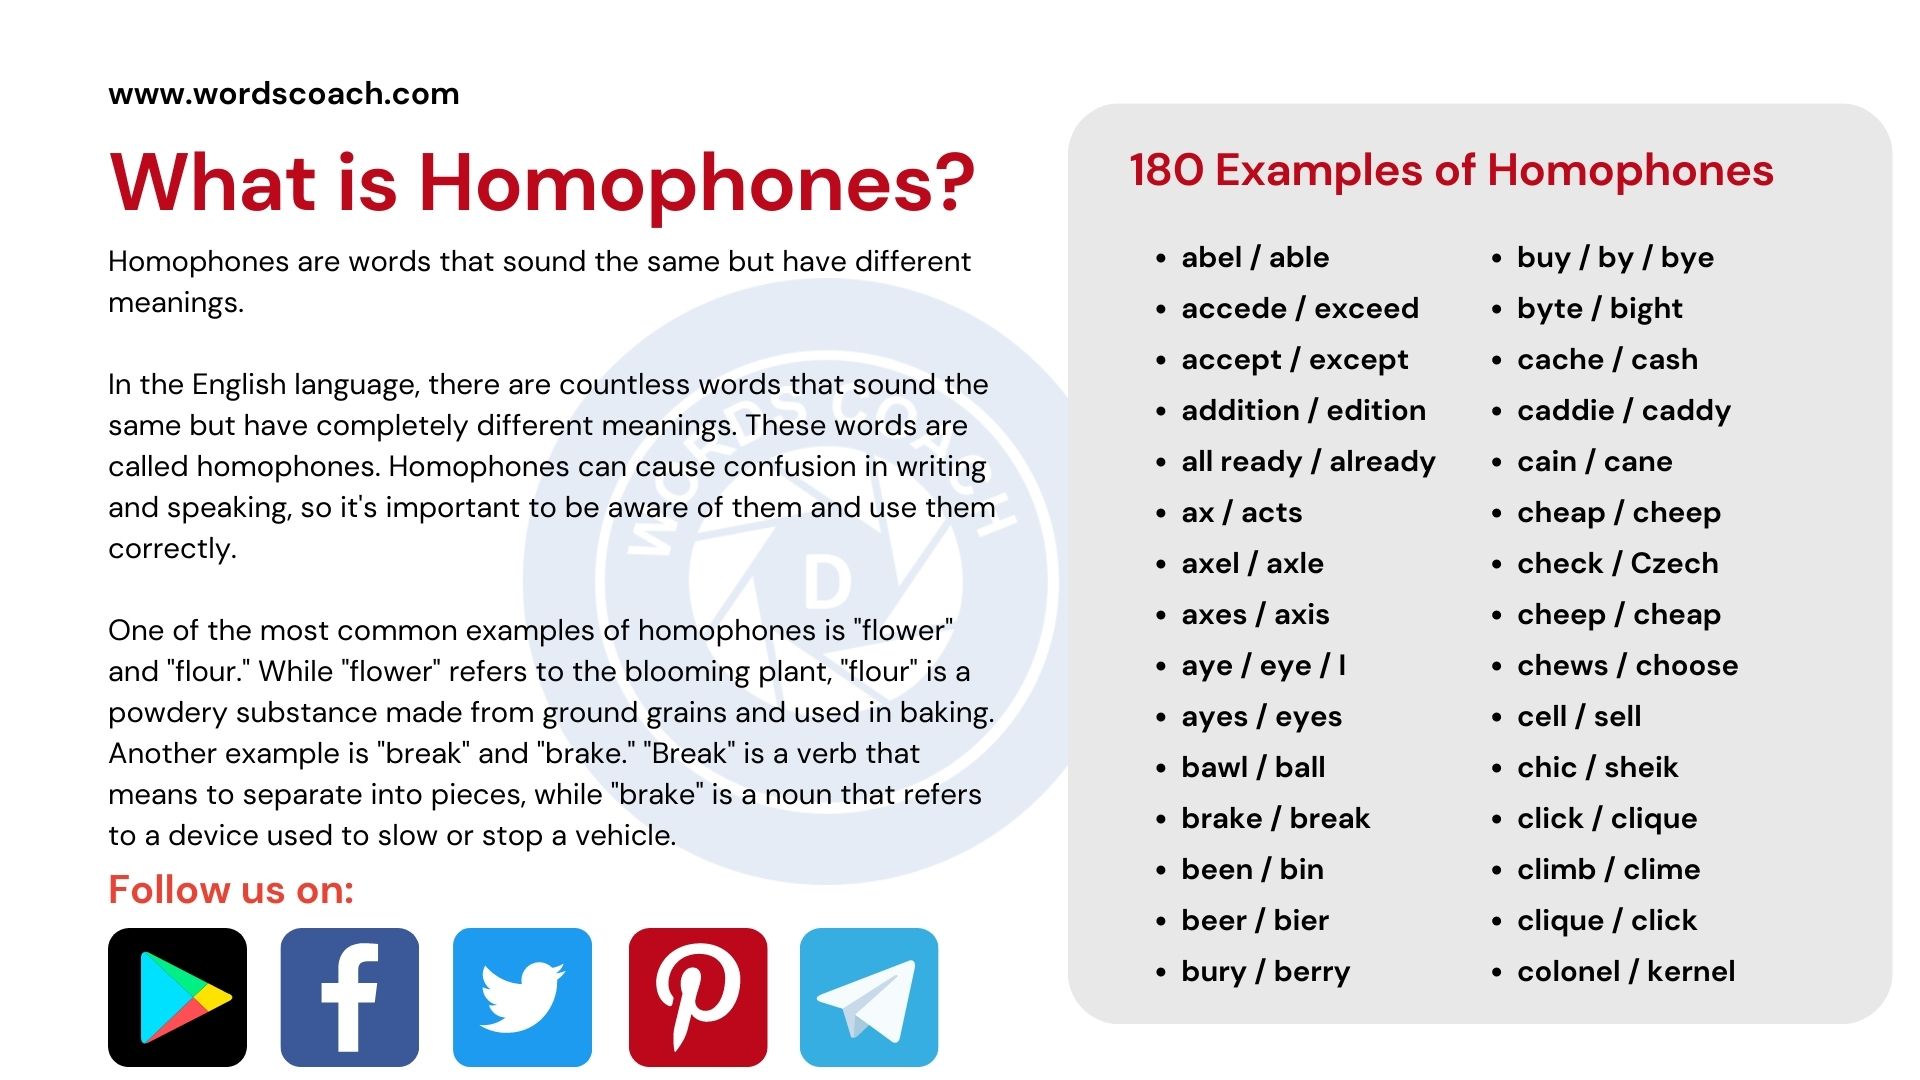
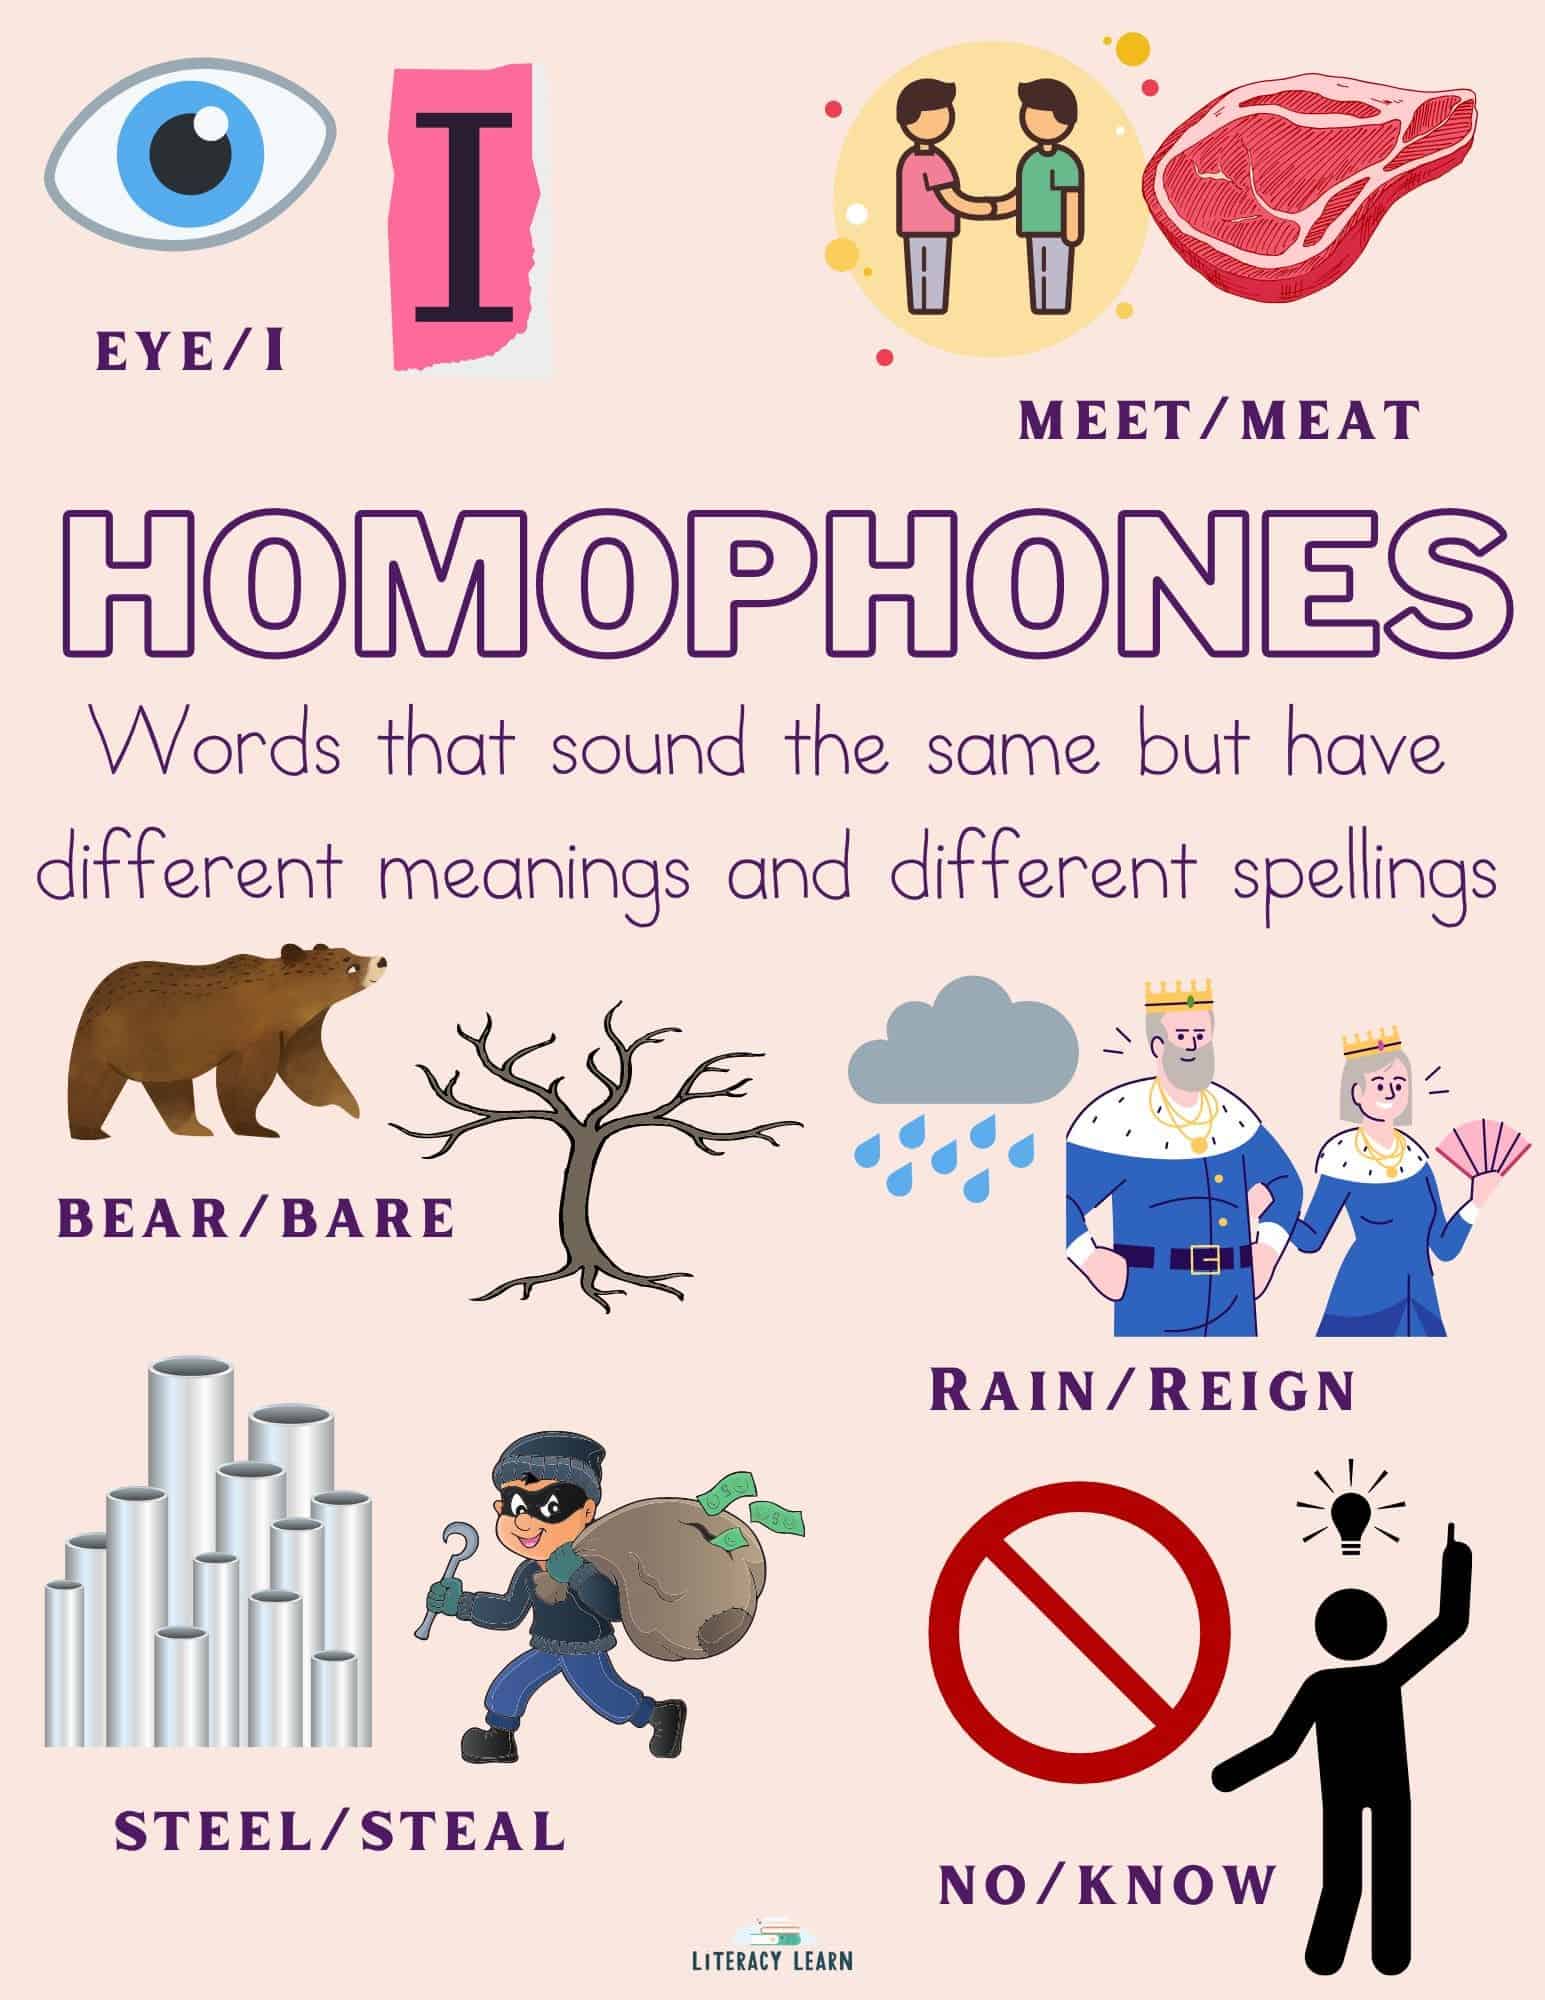
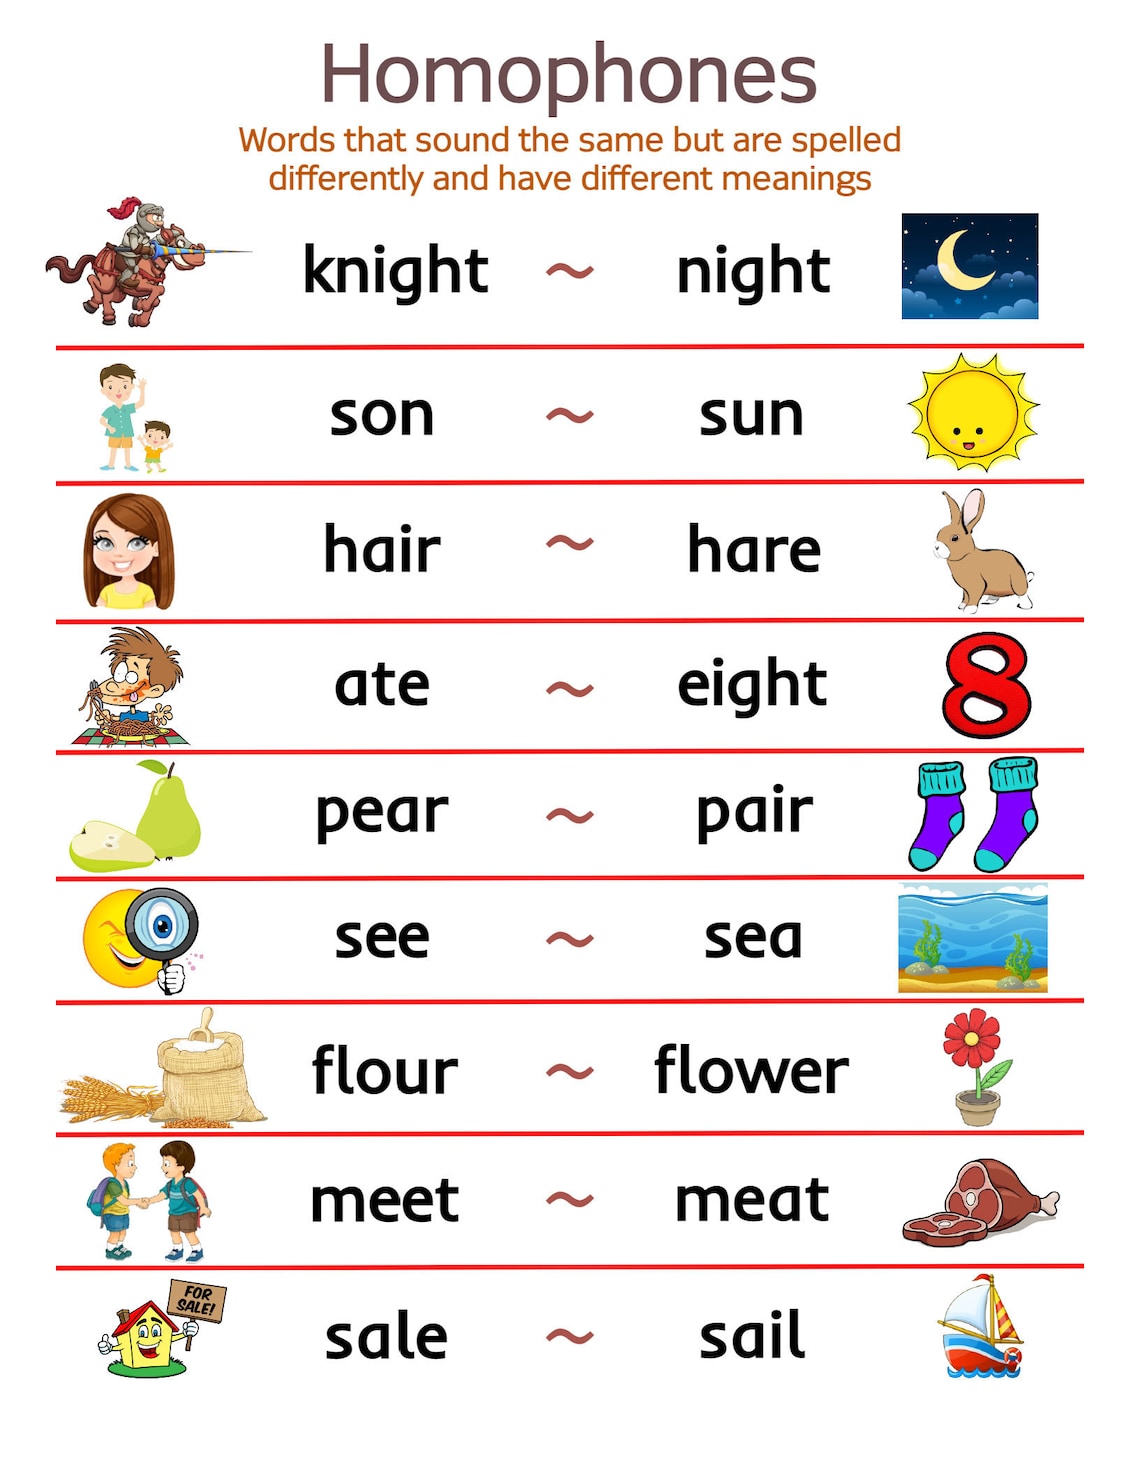
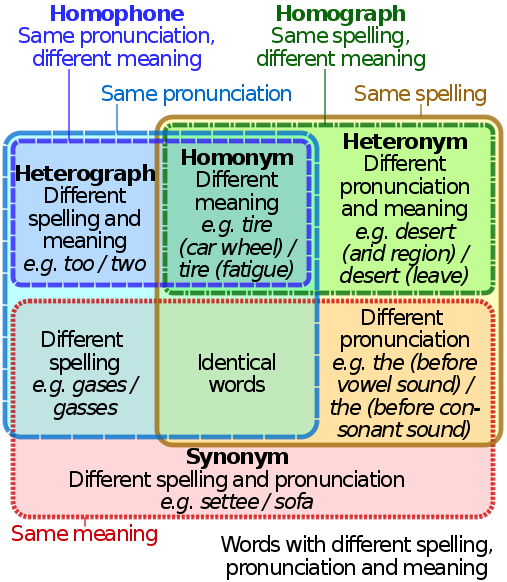
Homophones are words that sound the same but have different meanings and usually different spellings. That's the textbook definition. In real life, they show up constantly in editing work, transcription projects, and any situation where you're relying on audio alone without visual context. I learned this the hard way when working on a legal transcription job about three years ago. The audio had a witness saying "I saw the bear in the woods" — was it an animal or the verb meaning to delay? Without seeing the written page, I had to figure it out from context clues, which took me back through four minutes of surrounding testimony. That's the actual challenge with homophones, not the simple definition. The term comes from Greek roots: homos meaning "same" and phone meaning "sound" or "voice." So literally, same sound. Common examples include pairs like "their," "there," and "they're" — three words that sound identical but function completely differently in a sentence. Then you have "to," "too," and "two." Or "peace" versus "piece." These aren't rare edge cases. They appear in every piece of written English at significant frequency. Here's what most people miss when they're just learning about this concept. Homophones create genuine ambiguity in speech-to-text technology, automated captioning systems, and even human listening under poor audio conditions. I spent a week troubleshooting a dictionary app that kept misreading "write" as "right" in user-submitted example sentences. The issue wasn't the audio quality — it was that the algorithm had no contextual weighting, so it defaulted to whichever word appeared more frequently in its training data. "Right" won out every time, even in sentences clearly about composing text.
Why Homophones Matter Beyond Grammar Class
In technical writing and documentation, homophone confusion can cause real problems. I worked on a software manual where the team kept mixing up "affect" and "effect" throughout the entire document. The result was sentences like "The affect of this change will effect your settings" — which is backwards from what they meant. It took two full revision passes to catch every instance. That's roughly forty errors across eighty pages, and honestly, some slipped through anyway. The deeper issue with homophones involves homographs, which are related but distinct. Homographs are words that share the same spelling but have different meanings and often different pronunciations. Think of "tear" (to rip) versus "tear" (from your eye). Those aren't homophones at all since they're pronounced differently. But "lead" the metal versus "lead" to guide? That's a homograph pairing where one is pronounced "led" and the other "leed." Confusing these categories leads to sloppy writing and weak editing decisions.
How to Handle Homophones in Your Own Writing
There's no shortcut around actually knowing the difference between homophone pairs. Reading helps, proofreading helps, but the most reliable method I've found is reading your work backward, sentence by sentence, from the end to the beginning. This forces your brain to process each sentence in isolation rather than gliding over errors because the overall narrative feels correct. When I use this technique on documents longer than ten pages, I typically catch three to five homophone errors that standard forward-reading passes miss entirely. Digital tools can assist but have serious limitations. Spell checkers in Word and Google Docs will flag some homophone mistakes if you pick the wrong word, but they won't catch every case. Grammar checkers like Grammarly have homophone detection built in, and they're reasonably accurate, though not perfect. In my experience, automated tools catch about sixty to seventy percent of homophone errors. The rest require human judgment, which means you still need to know your "its" from "it's" and "your" from "you're." One practical tip that actually works: keep a personal list of the homophone pairs you personally struggle with most. Everyone has a weak spot. Mine was "lose" versus "loose" for years. I finally got it right consistently after writing out fifty example sentences by hand. The physical act of writing seemed to cement the distinction in a way that reading alone never did. If you have a recurring homophone problem, try that same approach.
Get the Full Details
Homophones in Different Languages and Dialects
Not all homophones exist across every English dialect. The classic example is "cot" and "caught," which sound identical to many American speakers due to the cot-caught merger, but remain distinct in other dialects like Canadian English or parts of the Northeast. This matters for transcription and localization work. I once watched a British transcriber struggle with an American client's audio where "dance" and "dans" (the French plural, used in a code-switching sentence) were being treated as homophones by the speaker's dialect. The transcriber marked it as unclear when it was perfectly clear in context. Even within standard American English, regional pronunciation differences create homophone pairs that don't exist everywhere. "Sugar" and "chure" might merge in some Southern dialects. "Armor" and "umored" could sound identical depending on how you roll your R's. If you're working with audio from diverse speakers, assuming a universal homophone set will cause errors.
When Homophones Break Down Completely
Some words that appear to be homophones aren't actually pronounced identically by enough speakers to count as true homophones. Take "colonel" and "kernel." They sound the same to many people, but not everyone. A speaker who pronounces "colonel" with a clearer first syllable isn't making an error — they're just not part of the homophone pair in their accent. This creates real friction in educational settings where teachers insist all students must hear these as identical sounds. The biggest limitation of homophone awareness is that no amount of study eliminates error under time pressure. I've seen experienced editors miss homophone mistakes in documents they reviewed within hours of publishing. Fatigue, speed requirements, and the natural brain tendency to read what you expect rather than what's actually written all combine to make homophone errors persist despite best efforts. The best you can do is build habits — backward reading, slow proofreading passes, and peer review — and accept that some errors will always slip through.