The sorting trick most people skip
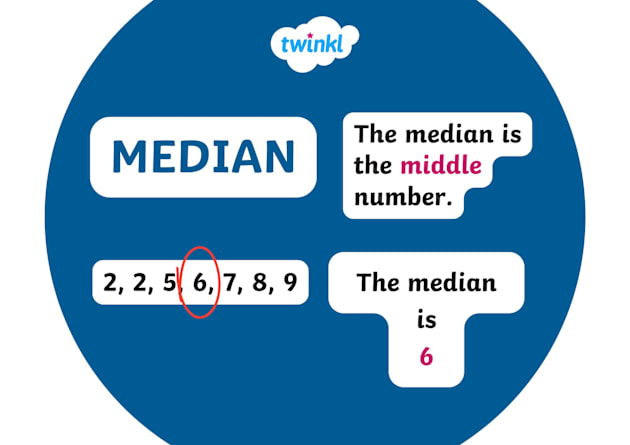
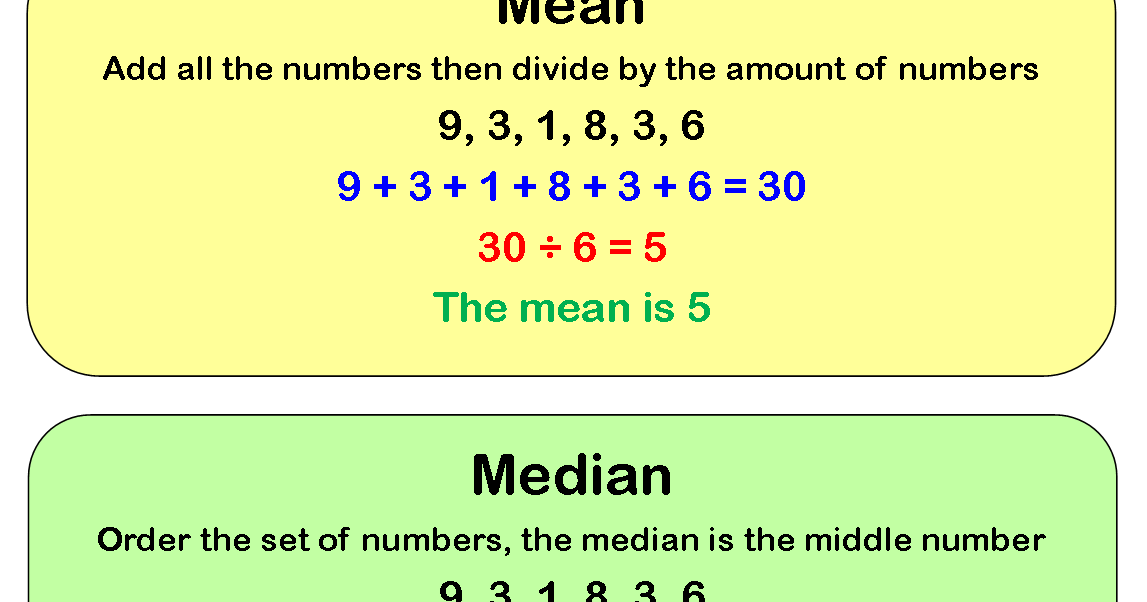
When I first had to explain median to junior analysts at my old job, everyone immediately jumped to the wrong conclusion. They'd look at a dataset of server response times — 12ms, 45ms, 3ms, 890ms, 22ms — and say the median was around 35 or 40. That's the mean, not the median. The actual median requires you to sort the data first, then pick the middle value. For that same set, sorted it becomes 3, 12, 22, 45, 890, and the median is 22. That middle number is the whole point. It sounds obvious in theory, but in practice I've seen people calculate medians from unsorted data in spreadsheets all the time. Not because they don't know how, but because they're used to trusting the AVERAGE function without thinking about what it's actually telling them. The median doesn't care how extreme your outliers are. That 890ms reading barely moves the median at all. The mean, on the other hand, gets dragged toward it like a weight on a rope.
What Does Median Mean in practice
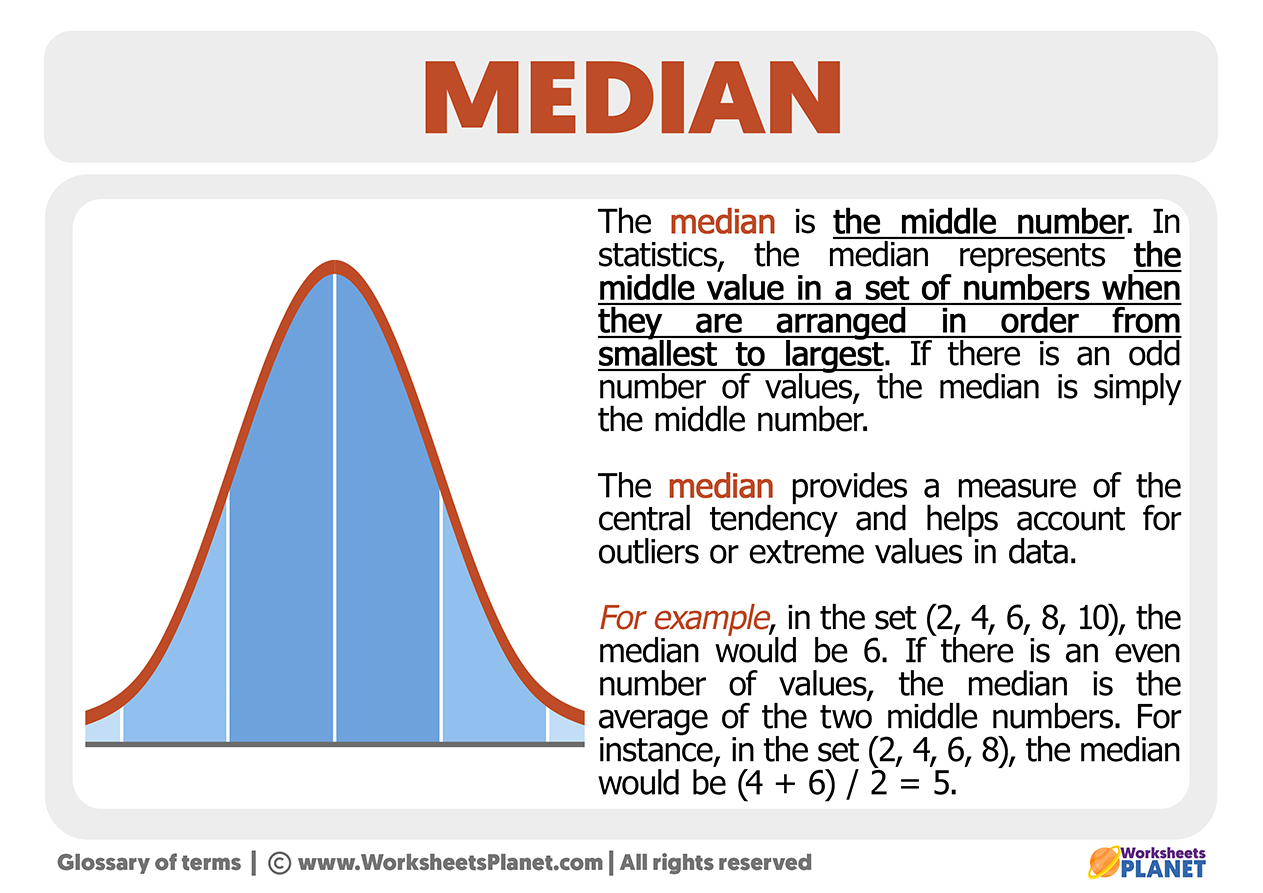
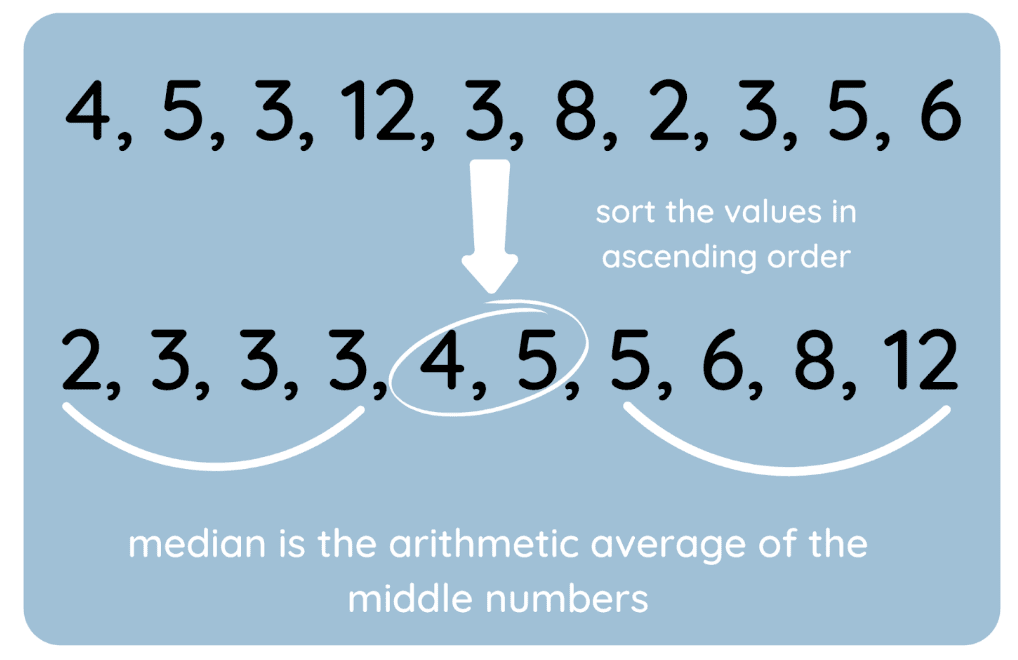
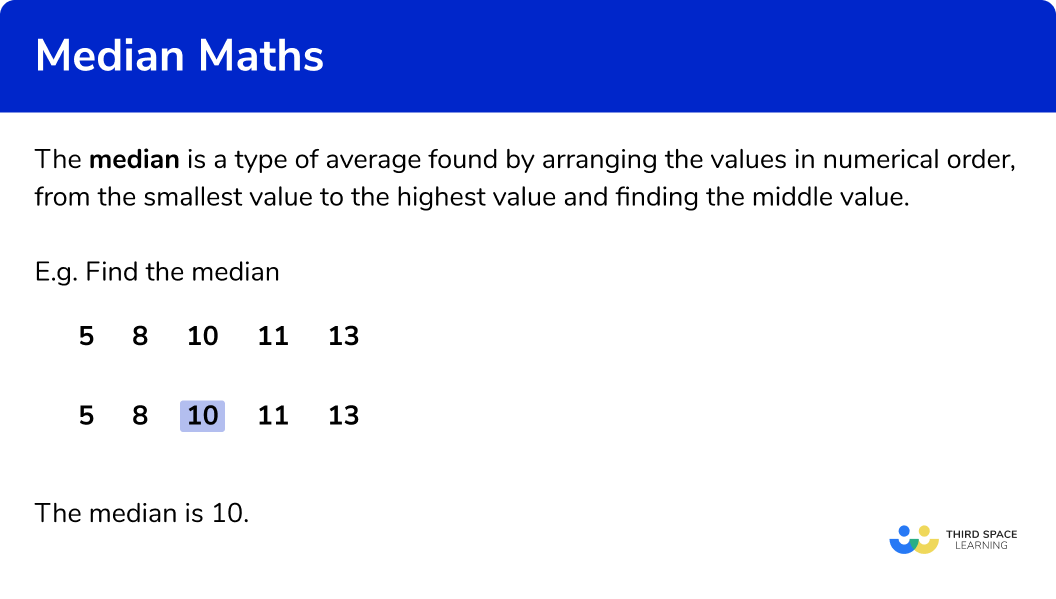
The median is the value that splits a dataset in half when everything is arranged in order. Half the observations fall below it, half fall above it. That's it. No fancy algebra. For an odd number of observations, you take the exact middle value. For an even number, you average the two middle values. In the example above with five numbers, position three is the median. With six numbers, positions three and four get averaged. Here's a scenario I ran into recently that most tutorials don't cover. I was working with income data for a small neighborhood survey — 47 households. Three of those households reported incomes over $2 million because there was a hedge fund manager and two inherited wealth situations on the block. The mean income came out to about $380,000, which made it sound like anyone living there was comfortably well off. The median came out to $87,500. That $87,500 figure actually told you something useful about the typical household. The mean was lying to you by a factor of four. I also dealt with a weird edge case involving zero-values. You have a dataset like 0, 0, 0, 1, 2, 3, 4. Seven values. The median is 1. But if someone asks "what's the median spend per customer" and most customers spent zero, reporting just 1 feels misleading even though it's technically correct. The median doesn't account for frequency distribution within categories. In that situation, I started supplementing the median with a simple zero-rate percentage so stakeholders understood the shape of the data instead of fixating on a single number.
How to calculate it without overcomplicating things
Sort your data. That's step one and honestly the step most people mess up. Then count your observations. If n is odd, the median sits at position (n + 1) / 2. If n is even, you take positions n/2 and n/2 + 1, then average them. Don't overthink the formula. Just sort and count. For large datasets, Excel's MEDIAN function handles this instantly, but it has a quirk worth knowing about. It ignores text and logical values in ranges, which is fine unless your data accidentally contains text-formatted numbers. I once spent forty minutes debugging what I thought was a calculation error before realizing someone had copy-pasted some cells as text instead of values. The median came back as zero because the function silently skipped those entries. Checking your data types before running the function saves hours of confusion. SQL users should note that most databases now support MEDIAN as an aggregate function, but older versions of Oracle and MySQL didn't have native support, which meant writing custom subqueries or window functions. PostgreSQL handles it fine now. If you're on an older system, the workaround is sorting the data with ROW_NUMBER() and then filtering for the middle position. It's not elegant but it works.
Get the Full Details

When the median is the right tool and when it's not
The median shines when your data is skewed or contains outliers. Income, house prices, website load times, response latencies, transaction sizes — these all tend to have long right tails where a few extreme values distort the mean. The median stays stable. That's its main advantage and the reason it's the standard metric for things like housing market reports and salary surveys. But the median has real limitations. It throws away information about the distribution shape. Two datasets can have the exact same median but look completely different. One could be tightly clustered around the center while the other is uniformly spread across a wide range. The median alone won't tell you that. If you're making decisions based solely on the median without checking variance or interquartile range, you're working with an incomplete picture. Another issue: the median is unstable with very small samples. With only three observations, changing one value can shift the median dramatically. With a sample of ten, it's a bit more reliable but still sensitive. I've seen people report medians from samples of five or six and present them with the same confidence they'd use for a mean calculated from hundreds of observations. That's not justified. Small-sample medians are rough estimates at best.
For normally distributed data, the mean, median, and mode are essentially the same, so there's no real advantage to using the median. In those cases, the mean is preferable because it uses every data point and has better mathematical properties for inference and hypothesis testing. Using the median on symmetric data doesn't hurt, but it doesn't help either. You're just giving up information.
A practical example with real numbers
Let's work through a concrete case. Say you're analyzing turnaround times for a customer support ticket system. Your data looks like this: 4, 7, 7, 9, 12, 15, 18, 22, 31, 45. Ten values, so you need the average of the fifth and sixth positions. Those are 12 and 15. The median is 13.5 hours. Now add an outlier. Change that last value from 45 to 450. Your sorted data is now 4, 7, 7, 9, 12, 15, 18, 22, 31, 450. The median is still 13.5. The mean jumps from about 14.9 to about 62.3. That's the difference the median makes in a skewed distribution. It resists the pull of extreme values while the mean chases them. This matters when you're reporting to stakeholders. If leadership asks "what's our typical turnaround?" and you say the mean, they'll think the problem is worse than it is for the majority of cases. If you say the median, they'll get a better sense of what most customers actually experience. Neither number is wrong. They answer different questions.
Common mistakes to avoid
Don't confuse median with midrange. The midrange is just (minimum + maximum) / 2, which is a completely different calculation and rarely useful. Don't report a median from unsorted data. Don't use the median when you need to sum or aggregate — it doesn't have that property. Don't treat it as a substitute for understanding your full distribution. The biggest mistake I see is people calculating the median of grouped data without accounting for class boundaries. If you only have frequency tables and not raw data, the median falls somewhere inside a class interval, and you need to interpolate. The formula is straightforward but easy to botch if you're rushing. Use the cumulative frequency column, find where 50% falls, and interpolate within that class. It adds a few minutes but prevents systematic bias in your estimate. Another thing: median is not additive. The median of combined groups is not the same as combining the medians of individual groups. If group A has a median of 10 and group B has a median of 20, the combined median could be anywhere between 10 and 20 depending on the sizes and distributions of each group. I've seen this mistake in monthly reporting where departments would report their own medians and then someone would try to average those medians for a company-wide figure. The result was meaningless.
The median is a solid, reliable measure of central tendency for skewed data and outlier-heavy datasets. It's not a magic bullet, and it's not appropriate for every situation. Know what your data looks like before you decide which number to report.