Mode is the value that shows up most often in a dataset
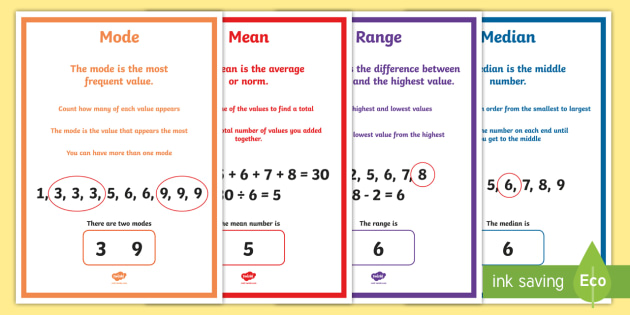
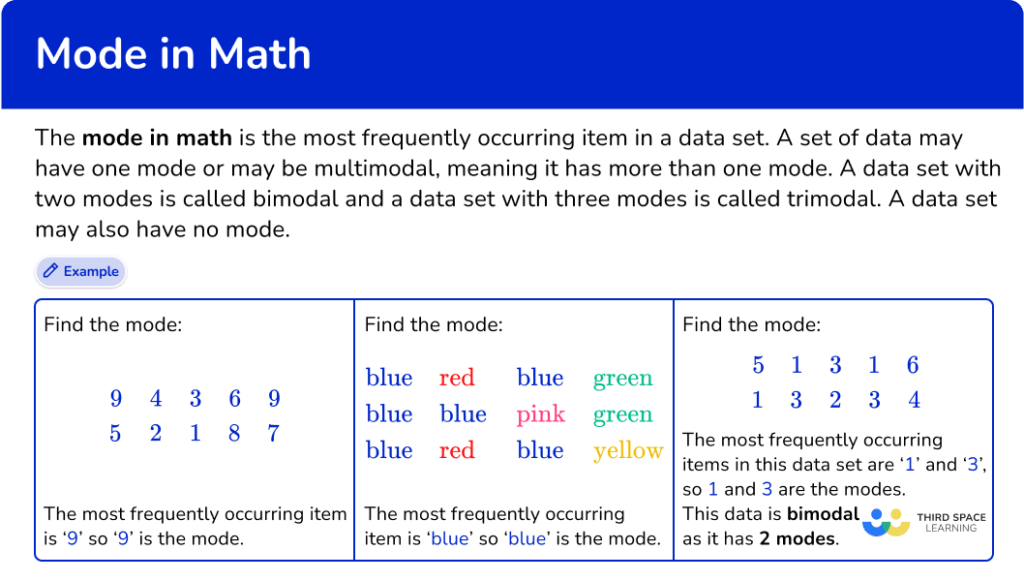
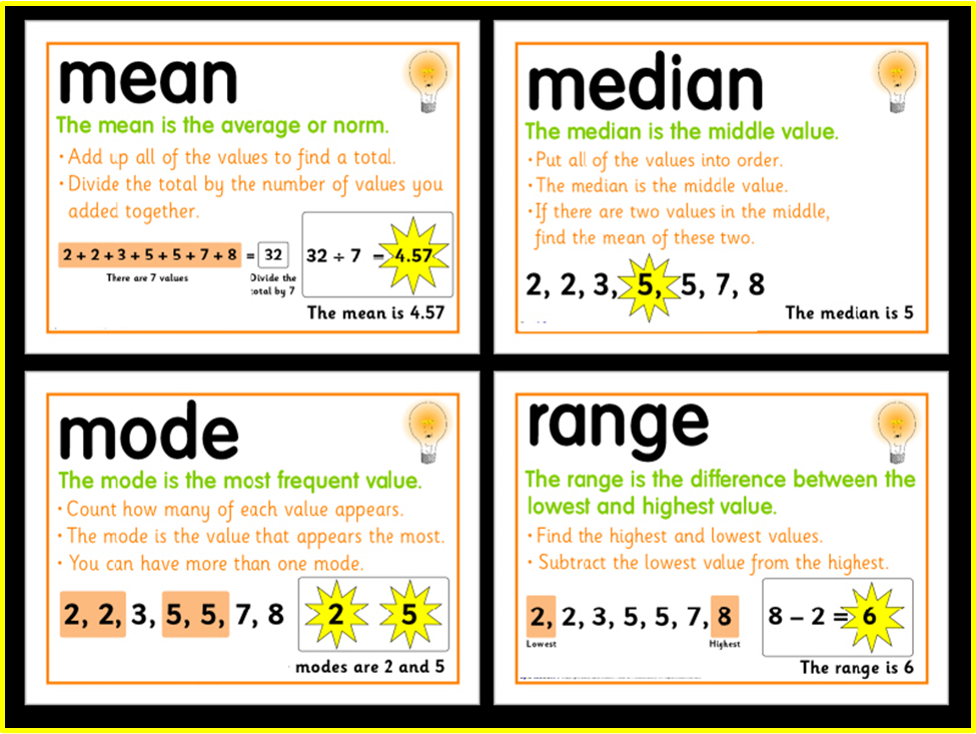
You look at your numbers, count how many times each one appears, and pick the one with the highest frequency. That's it. In elementary statistics, mode is introduced alongside mean and median as one of the three basic measures of central tendency, but it works differently than the other two. Mean requires addition and division. Median requires sorting. Mode only requires counting. It's the simplest measure to calculate by hand, which is why it appears first in most textbooks, but simplicity doesn't always make it the right tool. Here's how you actually find it. Take the dataset: 4, 7, 2, 7, 9, 4, 7. Count each value. Four appears twice. Seven appears three times. Two and nine appear once each. The mode is seven. Done. With grouped frequency data—say you have intervals like 10–19, 20–29, 30–39—the modal class is simply the interval with the highest frequency count. You don't need a fancy formula for that part. If you want a precise modal value within that class interval, you can use the interpolation formula: Mode = L + ((fm - f1) / (2fm - f1 - f2)) × w, where L is the lower boundary, fm is the modal class frequency, f1 is the frequency before it, f2 is after it, and w is the class width. But honestly, for most practical work, knowing the modal class is enough. I worked on a manufacturing quality audit once where we were tracking defect types across 50,000 units on a production line. The dataset had categories like scratch, dent, discoloration, misalignment, and incomplete seal. The mode told us immediately that "incomplete seal" was the most frequent defect, appearing 18,400 times. That single number directed our entire investigation toward the sealing station rather than spreading resources across all five defect types. The mean and median weren't even meaningful here since the data was categorical, but mode cut straight through to what mattered.
One thing people don't always catch: mode can be multimodal. A dataset like 3, 3, 5, 8, 8, 8, 12, 12 has a clear mode at 8. But 3, 3, 7, 7, 9, 9 is bimodal—both 3 and 7 are modes. Three modes makes it trimodal. And if every value appears exactly once, there is no mode. That's not a failure of the concept; it's a valid result that tells you the data has no concentrated frequency, which is itself useful information about uniformity. Another nuance that trips people up: mode works with non-numeric data. Customer satisfaction ratings on a Likert scale, product color preferences, brand choices—these all have modes. Mean and median require ordered numeric data. Mode doesn't care. This is actually one of its real strengths in market research and survey analysis where the data is inherently categorical. The limitation is that mode ignores the distribution shape entirely. A dataset of 1, 1, 1, 1, 1, 100, 200, 300, 400, 500 has a mode of 1, but that value represents almost nothing about the overall spread. The mode will always be one of the actual data points, which means it can't represent the center of a continuous distribution the way mean can. If you're working with temperature readings that vary by fractions of a degree, your mode might be 23.1°C while half your data sits between 24 and 28. The mode is telling a partial truth at best.
For continuous data specifically, you should bin or group the values before looking for mode, or use kernel density estimation if you need a smooth approximation. Raw continuous data with no repeated exact values will have no mode, and reporting that as "no mode exists" without explaining the grouping issue will make you look careless in any technical setting. Mode is also the only measure of central tendency that works with open-ended distributions. If your data has an open upper class like "65 years and older," you can still identify the modal class. Mean is impossible to calculate without knowing exact values, and median may be estimable but imprecise. Mode handles the ambiguity gracefully. Use mode when you need the most typical category, when working with nominal data, or when you want a quick robust measure that isn't distorted by extreme values. Don't use it as your sole summary statistic for numerical data, especially if the distribution is spread out or multimodal. Pair it with median and mean, or report the full frequency distribution if the data is small enough to display.
Get the Full Details