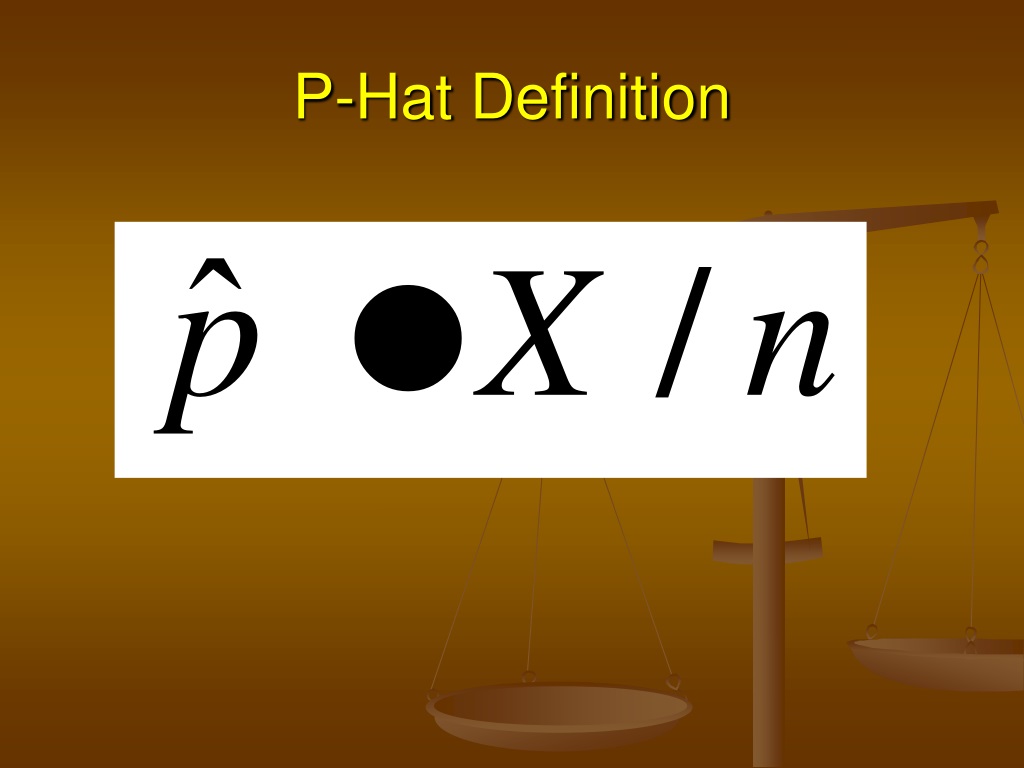
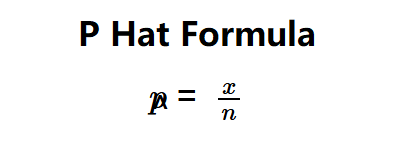So You Keep Seeing P-Hat on Your Stats Homework
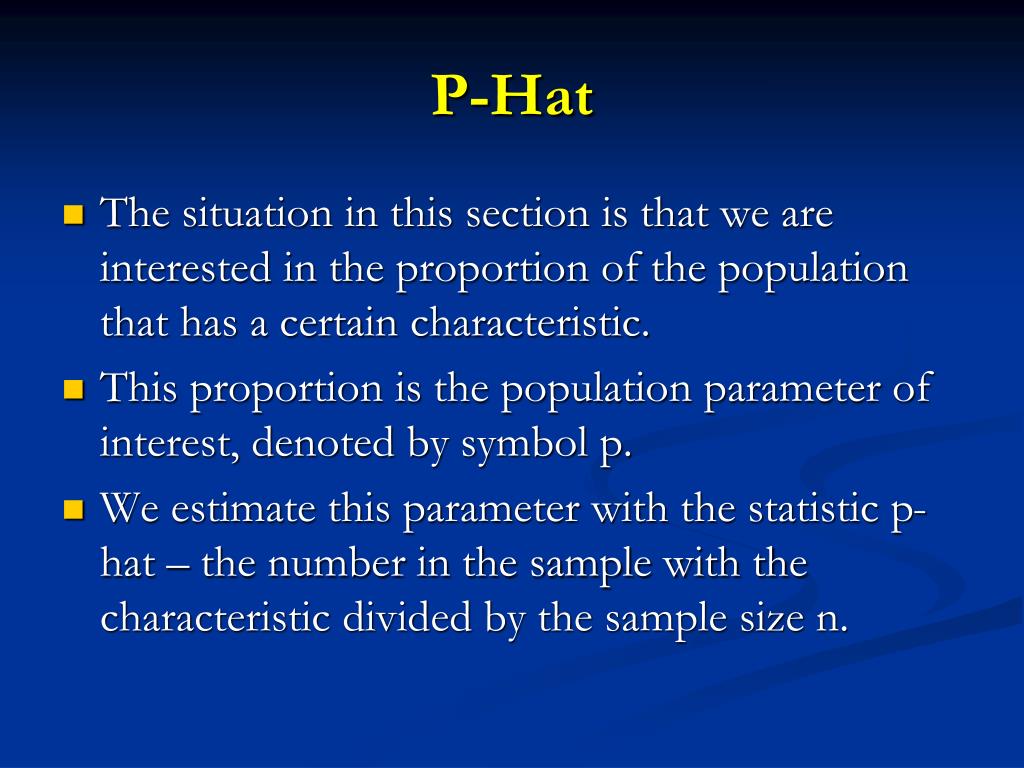
p is just the sample proportion. You count how many items in your sample have the characteristic you're tracking, then divide by the total sample size. That's it. If you survey 200 people and 68 say yes to something, p = 68/200 = 0.34. No mystical symbolism here. It's literally a hat over the population parameter p because we're using a sample to estimate a population value. The hat notation in statistics means "estimated version of." I've been grading stats assignments and looking at research reports for years, and the confusion around p usually isn't about the definition itself. It's about what people try to do with it afterward. The standard formula for a confidence interval is p ± z* × sqrt(p(1-p)/n). That's the thing everyone memorizes and then immediately forgets the assumptions behind. The normal approximation fails when your sample size is small or when p is near 0 or 1. I've seen people plug p = 0.02 with n = 50 into the standard formula and report a confidence interval like it was completely valid. The interval went negative. Yes, negative for a proportion. That should have been your first clue something was wrong. The Wilson score interval or the Agresti-Coull "plus four" method handles those edge cases without collapsing like that. I just add two successes and two failures to the data and proceed. It's simple and it keeps the math from breaking.
How to Actually Use P-Hat Without Messing Up
Start by checking your conditions. For the standard large-sample confidence interval, you need np 10 and n(1-p) 10. These aren't suggestions. They're the reason the sampling distribution looks close enough to normal for the z-method to work. If either condition fails, switch to the plus-four adjustment or use an exact binomial method. Modern calculators and software like R or Python's scipy can do exact intervals in a single line. Here's a concrete walkthrough. Say you're testing a new manufacturing process. You pull a sample of 150 units and find 12 defects. p = 12/150 = 0.08. Check conditions: 150 × 0.08 = 12, which is 10, and 150 × 0.92 = 138, also 10. The normal approximation is fine here. The standard error is sqrt(0.08 × 0.92 / 150) = sqrt(0.0736 / 150) = sqrt(0.0004907) 0.02215. For a 95% confidence interval, z* = 1.96, so the margin of error is 1.96 × 0.02215 0.0434. Your interval is 0.08 ± 0.0434, or roughly 0.037 to 0.123. That means we're 95% confident the true defect rate is between 3.7% and 12.3%. For hypothesis testing, p shows up in the test statistic formula: z = (p - p) / sqrt(p(1-p)/n). Note the denominator uses p, the null hypothesis value, not p. This trips people up constantly. The null distribution is built around p, so the standard error under the null is calculated with p. Using p in the denominator here gives you the wrong answer and you won't catch it unless you're checking your work against hand calculations or a known solution.
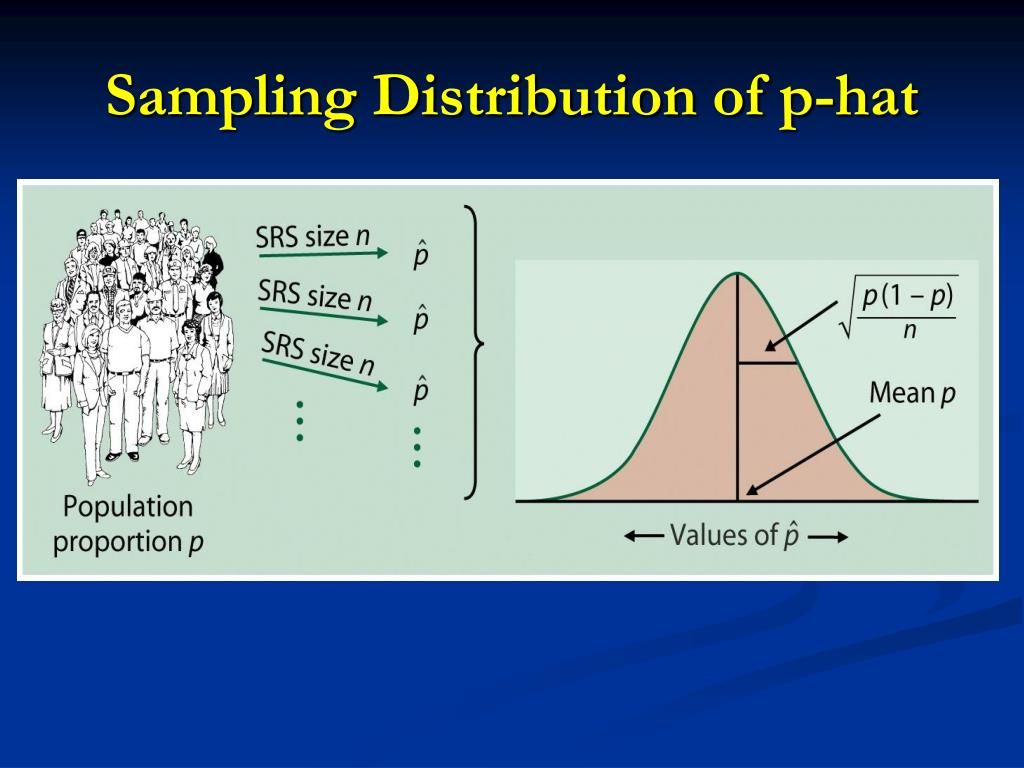
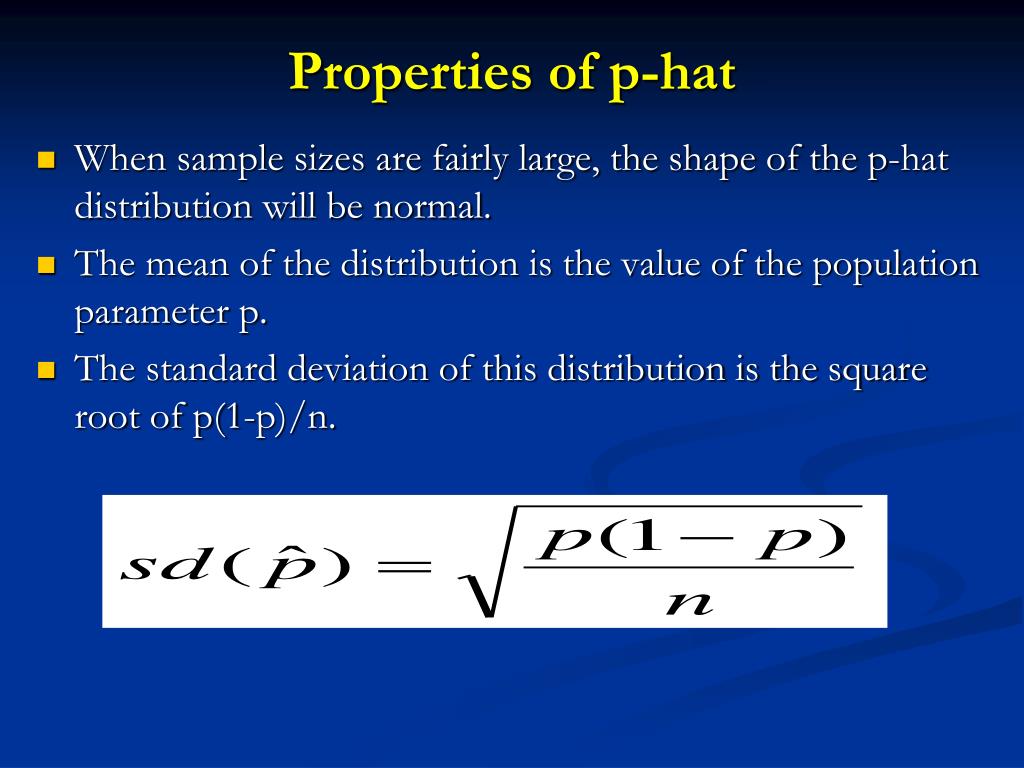
One more thing that nobody emphasizes enough: p is a random variable before you collect data. Once you take your sample, it becomes a fixed number. But when you're setting up the sampling distribution or deriving properties, p has a mean of p and a variance of p(1-p)/n. That's why the confidence interval and the hypothesis test use different standard errors. The confidence interval acknowledges uncertainty about where p actually sits relative to our observed p, while the hypothesis test evaluates how extreme our p would be if p were exactly p. They're answering different questions with slightly different formulas. If your sample is under 30 or your proportion is extremely skewed, don't fight it with the normal approximation. Use an exact method. R's binom.test function handles this directly. In Python, statsmodels.proportion_confint with method='binom_exact' does the same. The output might take a second longer to compute, but you'll get a correct interval instead of something that looks plausible but is systematically biased. I've watched people publish incorrect intervals in internal reports because they defaulted to the quick formula without checking the conditions. It happens more often than you'd think.
Get the Full Details