How The Modern Machine Actually Works Under The Hood
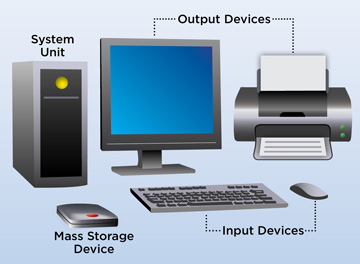
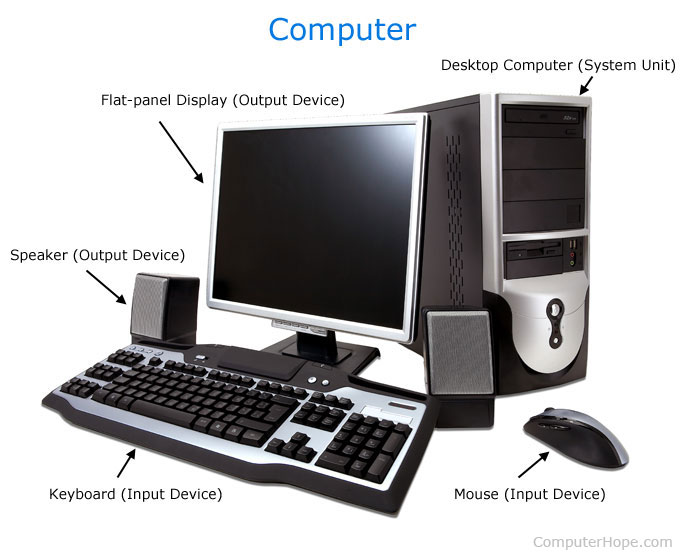
A computer is a programmable device that takes input, processes it through arithmetic and logic operations, and produces output. That definition covers everything from a calculator app to a server rack, but it's not very useful when you're actually trying to understand what's happening at any given moment. Let's get past the textbook stuff and talk about how these things function in practice. At the physical layer, a computer is an arrangement of transistors switching on and off billions of times per second. Those switches represent binary states — one or zero. Everything you interact with, every image, every document, every line of code, gets translated into those binary states at some point before the machine can process them. The CPU is where the actual work happens. It fetches instructions from memory, decodes what they mean, executes the operation, and stores the result. This cycle repeats continuously, governed by a clock signal that keeps everything synchronized. I spent years troubleshooting systems at a low level, and one thing that always tripped up people was understanding why software that worked perfectly on one machine would fail on another with similar specs. The issue usually came down to architecture differences — x86 versus ARM, little-endian versus big-endian byte ordering, or how different CPUs handle floating-point calculations. A piece of code that assumes a certain memory layout or instruction set behavior will compile fine but produce garbage results at runtime. You need to understand your target architecture before writing anything that depends on low-level assumptions.
Memory hierarchy matters more than most beginners realize. Data moves between registers, L1 cache, L2 cache, L3 cache, RAM, and storage, and each level has a different speed and capacity trade-off. The CPU can process data from its registers in a single clock cycle, but pulling something from RAM might take 100 to 300 cycles. Going to SSD storage adds thousands of cycles. This is why algorithms and data structures that keep working sets small and access patterns predictable run significantly faster than ones that thrash memory, even when both solutions are theoretically correct. I remember a specific case where a Python script I wrote for processing log files took about 47 minutes to run on a dataset of roughly 2 million entries. The bottleneck wasn't the language or the algorithm itself — it was that I was reading the entire file into memory as a list of strings and then iterating through it multiple times. The fix was switching to a generator-based approach that processed the file line by line, keeping only the current line in memory at any given time. That dropped the runtime to about three minutes. The logic stayed exactly the same. Only the memory access pattern changed. The operating system sits between your applications and the hardware, managing resources and providing abstraction layers. It handles scheduling which process gets CPU time, allocates memory, manages file systems, and controls peripheral devices. Without an OS, you'd be writing direct hardware drivers for every component you wanted to use. With an OS, you call functions and the system figures out the hardware details. This convenience comes at a cost — there's overhead in every layer of abstraction, but for most applications that overhead is negligible compared to the productivity gain.
The Software Layer And Why It Complicates Things
Software is what turns raw hardware into something useful. The compiler or interpreter translates human-readable code into machine code that the CPU can execute. Different languages operate at different levels of abstraction. Assembly language gives you direct control over every instruction and register. C gives you control over memory while hiding some of the assembly complexity. Python and JavaScript hide even more, handling memory management and type checking automatically. The trade-off is always the same: more abstraction means less control and more overhead. One counter-intuitive thing about computers that people rarely expect is that they're actually terrible at randomness. Every number a computer generates is pseudorandom — produced by a deterministic algorithm that starts from an initial value called a seed. If you know the seed and the algorithm, you can predict the entire sequence. This is fine for games and simulations but catastrophic for cryptography. Security-critical applications use hardware-based random number generators that sample physical phenomena like thermal noise or radioactive decay, because those processes are genuinely unpredictable. Standard library functions like Python's random module should never be used for anything involving security. Another thing that surprises people is how much computers lie to you about time. System clocks can jump forward or backward due to NTP adjustments, daylight saving time changes, or virtual machine migration. If you're doing anything that depends on accurate timing — distributed systems, financial transactions, logging — you need to account for the possibility that time moves unevenly. Comparing two timestamps from different sources without normalization is a common source of bugs that can take days to track down.
Get the Full Details
I once debugged a distributed caching system where the inconsistency was caused by a subtle time-of-check-to-time-of-use race condition. One node would check if a cache entry was valid at timestamp T1, and another node would invalidate it at T2, but because their clocks were skewed by 200 milliseconds due to an NTP correction, the first node would read the stale data as still valid. The fix wasn't to make the clocks more accurate — it was to implement a proper versioning scheme using vector clocks instead of relying on wall-clock time for consistency checks. That system handled thousands of concurrent operations without issues after the change.
What Actually Happens When You Press A Key
When you type on a keyboard, a scan code gets generated and sent to the operating system through the input subsystem. The OS maps that scan code to a character based on your current keyboard layout and active input method. The character gets placed in a buffer associated with whichever application currently has focus. The application reads from that buffer and processes the character according to its own logic. If it's a text editor, the character appears on screen. If it's a game, it might trigger a movement command. If it's a terminal, the shell interprets it as part of a command string. This pipeline introduces latency at every stage. Keyboard hardware polling rate, USB or Bluetooth transmission, OS interrupt handling, application event loop processing, and rendering all add up. A gaming mouse with a 1000Hz polling rate reports its position every millisecond. A typical office keyboard might only report key presses every 8 to 16 milliseconds. For most applications this difference is invisible, but it matters in competitive gaming or real-time control systems where every millisecond counts. The display side works in reverse. The GPU renders frames into a buffer, and the display controller reads from that buffer at a fixed refresh rate, typically 60Hz, 120Hz, or higher on modern monitors. If the GPU can't produce frames fast enough to match the refresh rate, you get tearing — where the display shows parts of two different frames simultaneously. VSync or adaptive sync technologies like G-Sync and FreeSync solve this by synchronizing the GPU output to the display's refresh cycle, though they can introduce input lag as a side effect.
The Storage Reality Most People Ignore
Storage is one of the biggest bottlenecks in computing, and it's something most users never think about until something breaks. Traditional hard disk drives have moving parts — a spinning platter and a read/write head that physically moves to the correct track. Seek time, the time it takes for the head to reach the right location, can be 5 to 15 milliseconds on a good HDD. Random read operations on an HDD are measurably slower than sequential reads because the head has to physically reposition for each operation. Solid state drives eliminate this mechanical delay entirely, with access times measured in microseconds instead of milliseconds. But SSDs have their own limitations. They wear out over time based on how much data you write to them. Each cell can only endure a limited number of program-erase cycles before it degrades. Modern SSDs use wear leveling and over-provisioning to extend their lifespan, and for most consumer workloads an SSD will outlast the computer it's installed in. Enterprise workloads with heavy write patterns can wear out an SSD in a few years. Understanding your write amplification factor — the ratio of actual data written to the SSD versus the data the host requests to be written — helps predict drive longevity more accurately than looking at terabytes written alone. There's also the issue of file system fragmentation. On HDDs, when files are deleted and new ones created, free space gets scattered across the disk, forcing the read head to jump around and slowing things down. Defragmentation reorganizes the data to restore sequential access patterns. SSDs don't benefit from defragmentation and can actually be harmed by it because it creates unnecessary write operations. File systems like Btrfs and ZFS handle this differently by using copy-on-write and periodicTrim operations to maintain performance without traditional defragmentation.
Networking And The Hidden Complexity
A computer connected to a network becomes something entirely different from an isolated machine. The network stack translates high-level operations like loading a web page into packets that travel across cables or radio waves. Each layer of the OSI model adds its own headers and processing. The application layer handles the actual data. The transport layer manages reliability and flow control. The network layer handles addressing and routing. The link layer handles physical transmission. One thing that catches people off guard is how much network latency costs in distributed systems. A round-trip time of 50 milliseconds between two servers means that any synchronous operation taking more than a few parallel calls will add up to seconds of total execution time. This is why database queries get optimized, why caches exist, and why asynchronous communication patterns are so common in production systems. Calling a remote API from within a loop is almost always a mistake — you're turning a few milliseconds of work into potentially hundreds. IP address exhaustion is a practical constraint that everyone using IPv4 eventually runs into. The available address space was designed when computers were rare enterprise assets, not when every phone, appliance, and sensor needs one. NAT and private address ranges let multiple devices share a single public IP, but this breaks end-to-end connectivity and complicates peer-to-peer applications. IPv6 solves the address shortage but deployment has been slow due to the infrastructure changes it requires. Many organizations still run dual-stack environments where both protocols coexist.
I worked on a project where we needed to communicate between containers on different hosts in a Kubernetes cluster. The overlay networking solution we chose — Calico — was working fine until we started seeing intermittent packet loss under high load. The root cause was the MTU mismatch between the overlay tunnel and the underlying physical network. Container traffic was being encapsulated in VXLAN headers, adding 50 bytes to each packet. When these oversized packets hit a network interface with a standard 1500-byte MTU, they got fragmented or dropped depending on the hardware. The fix was to reduce the pod network MTU to 1440 bytes across the cluster, which prevented the fragmentation entirely. It was a two-line configuration change that resolved weeks of troubleshooting.
Security And What Computers Actually Can't Do
Computers do exactly what you tell them to do, which sounds like an advantage but is actually a fundamental limitation. They have no understanding of intent, context, or security policy. If your code has a buffer overflow, the computer will happily overflow the buffer. If your authentication logic has a bypass, the computer will happily let unauthorized users through. The machine is amoral and indifferent to correctness — it only cares about executing instructions efficiently. This is why security is never a feature you add at the end. It has to be built into every layer of the system. Input validation, least privilege, encryption in transit and at rest, secure boot chains, and regular patching are all necessary because any one of them failing doesn't necessarily compromise the system, but the absence of any of them creates exploitable gaps. The concept of defense in depth exists because no single mechanism is sufficient on its own. Another limitation worth noting is that computers cannot solve the halting problem — they cannot determine whether any given program will eventually finish running or loop forever. This isn't a practical limitation for most software, but it becomes critical in formal verification and automated theorem proving, where you need to prove properties about program behavior. Certain questions about program execution are fundamentally undecidable, no matter how much computational power you throw at them.
Computers also struggle with ambiguity. Natural language is full of it. Programming languages eliminate ambiguity by design, which is why they're easier for machines to process but harder for humans to write. The gap between what you mean and what you express in code is where most bugs live. Static analysis tools catch some of these gaps, but they catch only a subset. Human review remains necessary because the tools can't understand the intent behind the code — only its structure. The bottom line is that a computer is a tool with well-defined capabilities and well-defined limitations. It excels at repetitive, precise, high-volume computation. It fails at reasoning about context, understanding intent, and handling genuinely novel situations without explicit programming. Understanding both sides of that equation is what separates someone who uses a computer from someone who understands it.