Running Experiments Right
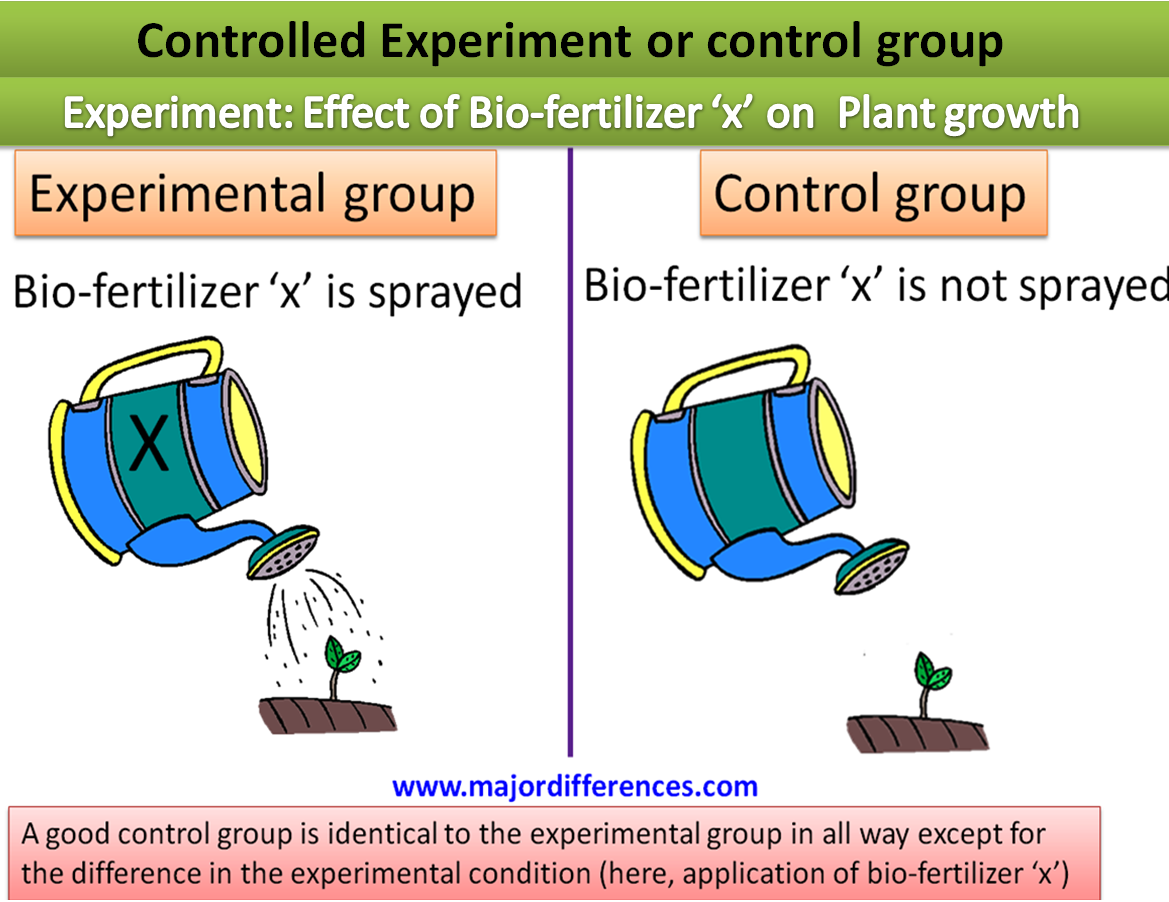
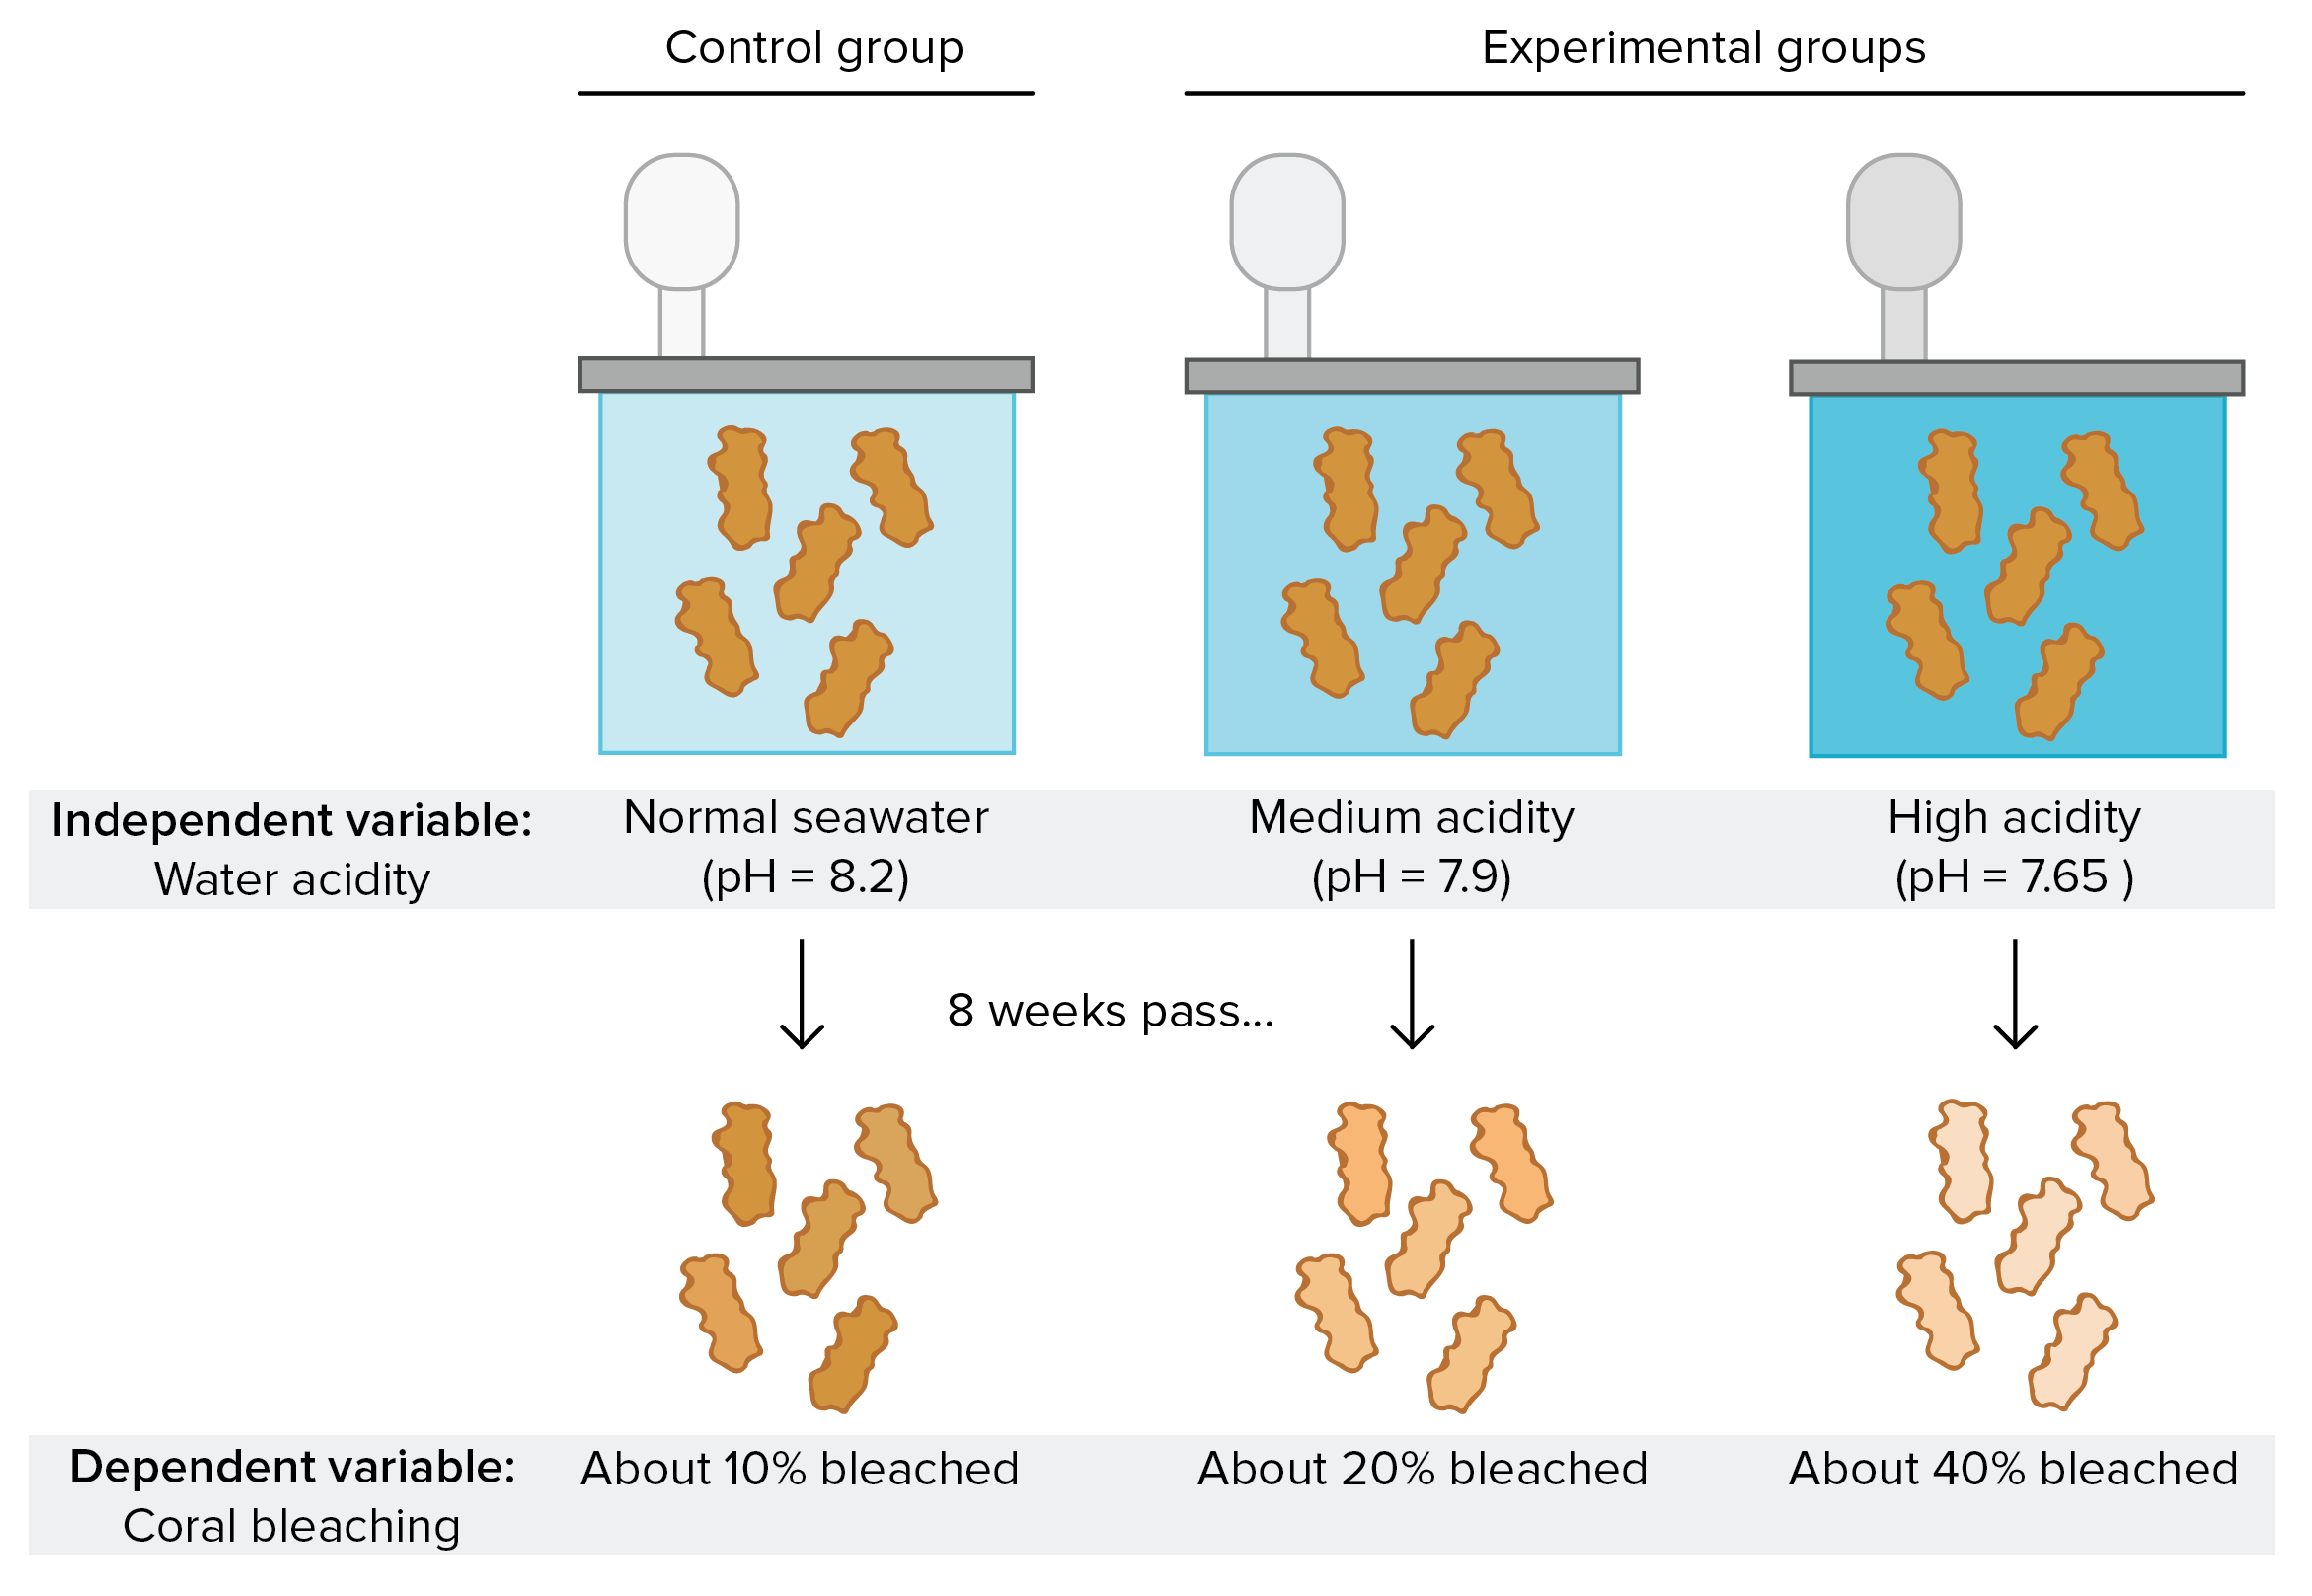
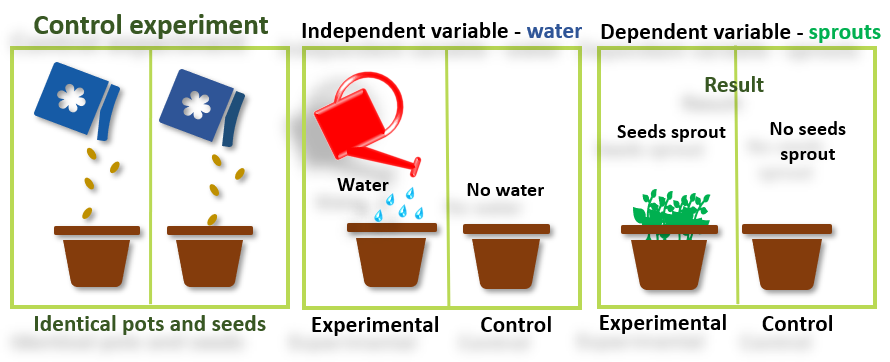
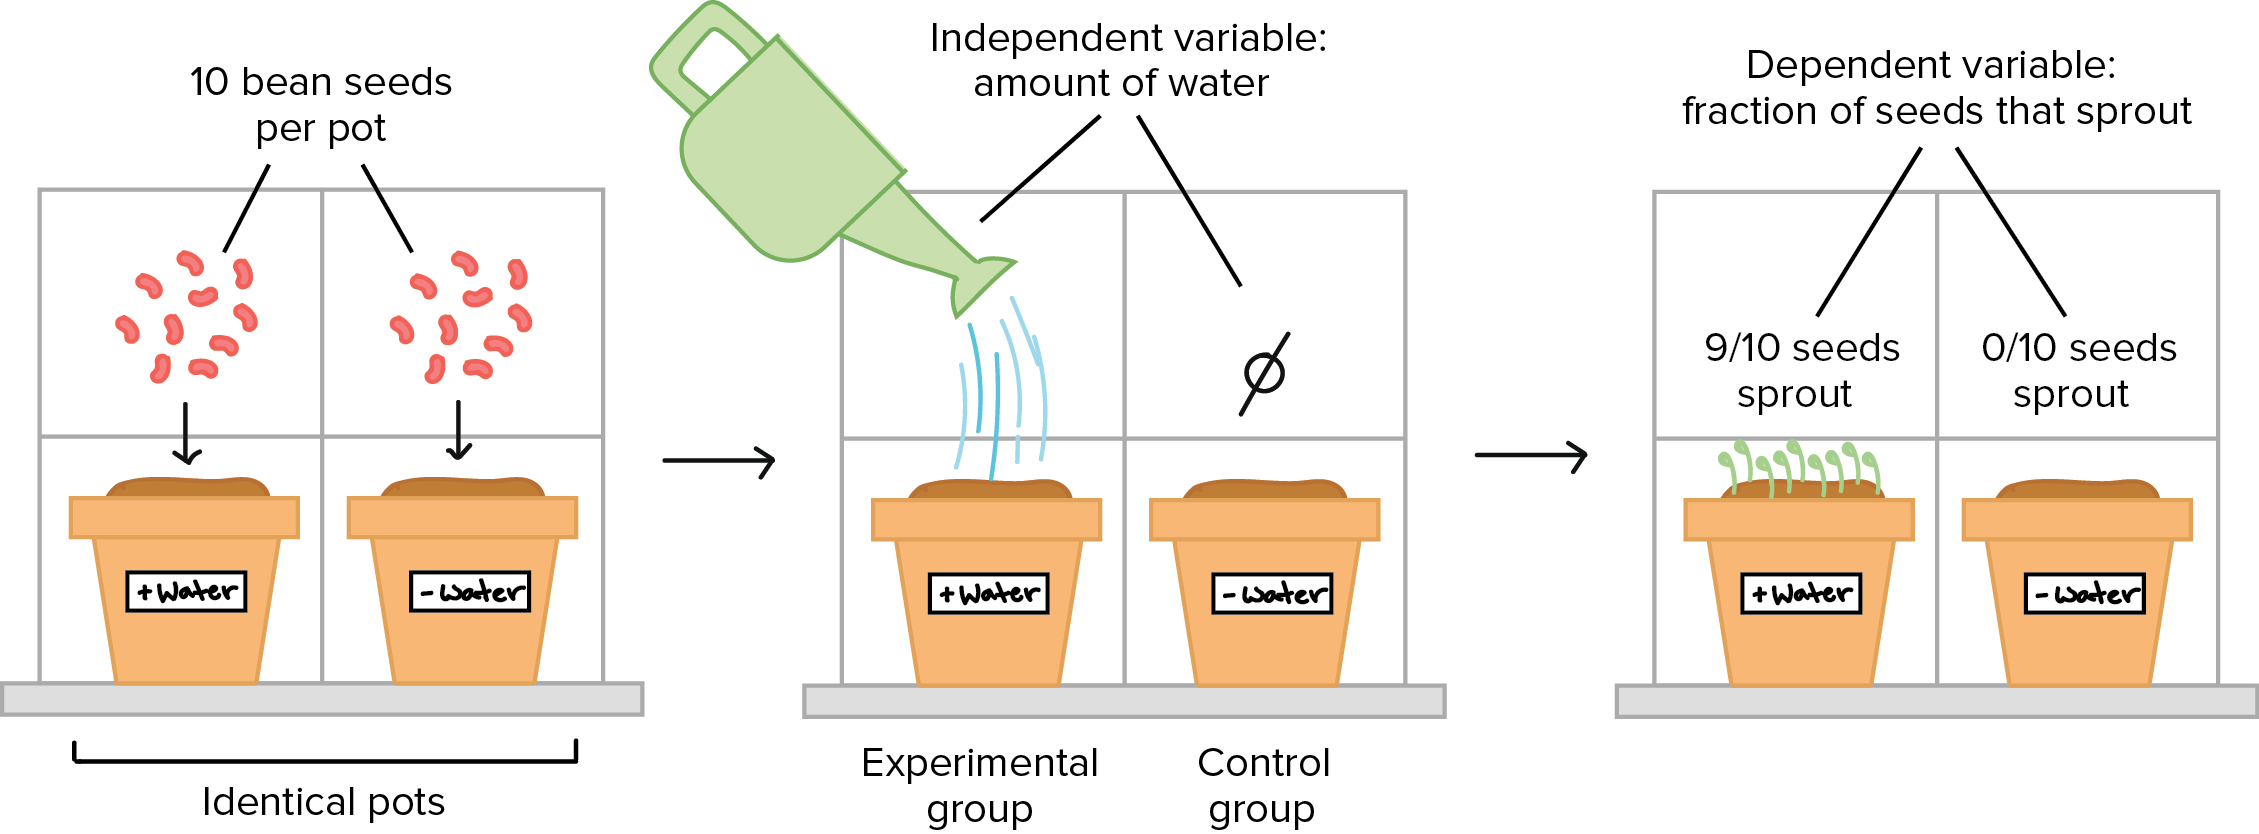
I spent years watching teams waste months on tests that proved nothing because they didn't actually understand what they were measuring. The concept itself is straightforward, but the execution is where almost everyone messes up. Here is what I learned doing this work repeatedly over a long time. A controlled experiment is a test where you change exactly one variable while keeping everything else constant, so you can attribute any observed difference to that single change. The control group experiences the baseline condition. The treatment group experiences the change. You compare results between the two. That is the entire mechanism. The hard part is convincing yourself that you are actually only changing one thing. In practice, that is nearly impossible to guarantee perfectly, but you need to get close enough that the signal isn't drowned out by noise. I have seen people run what they called a controlled experiment while simultaneously redesigning the checkout flow, changing copy, and adjusting load times. That is not a controlled experiment. That is chaos with extra steps.
Here is how the actual process works. You start with a hypothesis. It should be specific and measurable. "Changing the button color from blue to green will increase click-through rate" is a proper hypothesis. "Making the page better" is not a hypothesis. It is a hope. Next you define your primary metric. This is the single number you will use to determine success or failure. Revenue per visitor, conversion rate, time on page, whatever it is. Pick one. Do not pick five and then celebrate when three of them move in the right direction. That is called p-hacking and it will destroy your credibility if anyone important notices. Then you split your traffic. Randomization is critical here. If you can send half your users to version A and half to version B randomly, you are on solid ground. If you are assigning users based on geography, device type, or any other systematic factor, your groups may differ in ways unrelated to your treatment. I once ran a test where the control group happened to include more mobile users because of how our CDN routed traffic. The treatment variant appeared to perform worse by twelve percent. It was not a real effect. It was just a routing quirk. I lost three weeks troubleshooting a ghost before someone pointed out the CDN config.
After the split runs for long enough to reach statistical significance, you analyze the results. Statistical significance means the probability that your result happened by random chance is low enough that you can treat it as a real effect. The standard threshold is p less than zero point zero five. That means there is less than a five percent probability the result is noise. Some fields use stricter thresholds. The principle is the same regardless. One thing most guides do not tell you about sample size is that the required duration depends heavily on your baseline conversion rate and the magnitude of effect you are trying to detect. If your baseline conversion rate is one percent and you want to detect a half percent absolute lift, you might need hundreds of thousands of visitors. If your baseline is ten percent and you are looking for a one percent absolute lift, the required sample is still substantial. Small effects require massive samples. Large effects require smaller ones. This is basic statistics, but it is easy to ignore when you are under pressure to ship something quickly. I have also seen people fall into the novelty trap. A new interface element might boost engagement for a few days because users are reacting to change rather than to the actual improvement. Running a test for seven days instead of twenty-eight can produce wildly misleading results. Wait long enough. At least two full business cycles, preferably four to eight weeks depending on your traffic volume and the metric in question.
Get the Full Details
There are legitimate limitations to this approach. Controlled experiments fail when the treatment effect is too small to detect within reasonable sample sizes. They fail when your user population is too homogeneous to generalize findings. They fail when the act of measurement changes the behavior you are trying to measure, which happens more often than people admit. Survey-based controlled experiments have this problem especially badly. People answer differently when they know they are being studied. When controlled experiments are not viable, there are alternatives. Regression discontinuity designs exploit natural cutoffs in your data. Instrumental variables can isolate causal effects in observational data. Multivariate testing lets you evaluate multiple factors simultaneously, though it requires exponentially larger samples as you add variables. Each alternative has tradeoffs. Controlled experiments are not the only valid approach to causal inference, even though they are the most widely understood one. The core idea remains useful precisely because it forces you to be explicit about what you think is happening and then actually check whether you are wrong. Most teams skip that last part. They confirm what they already believed and call it insight. That is not science. That is just decoration around a pre-existing opinion.