Correlation Coefficients Explained Without the Textbook Fluff
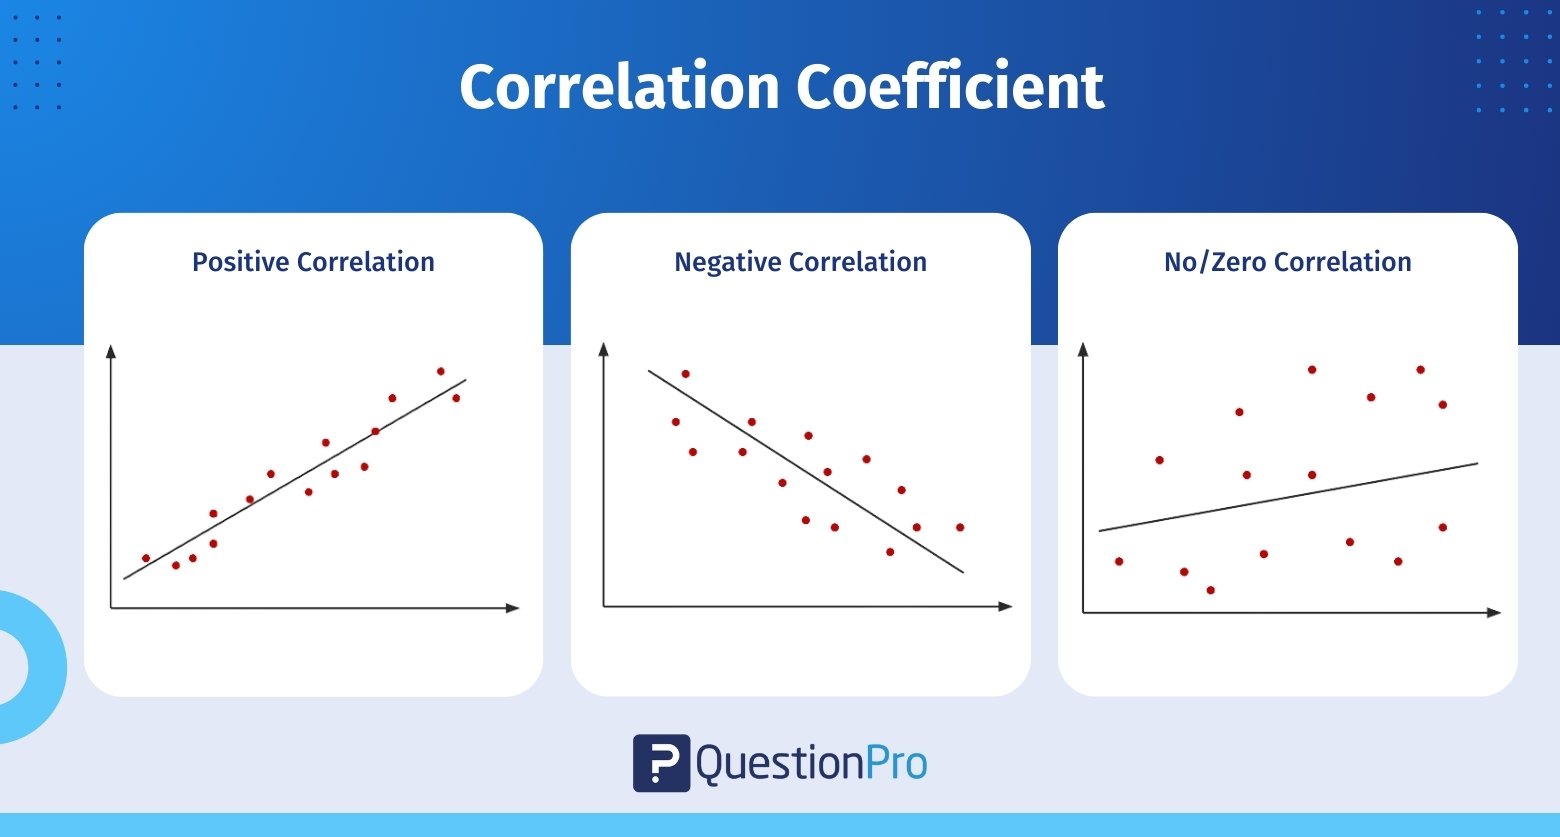
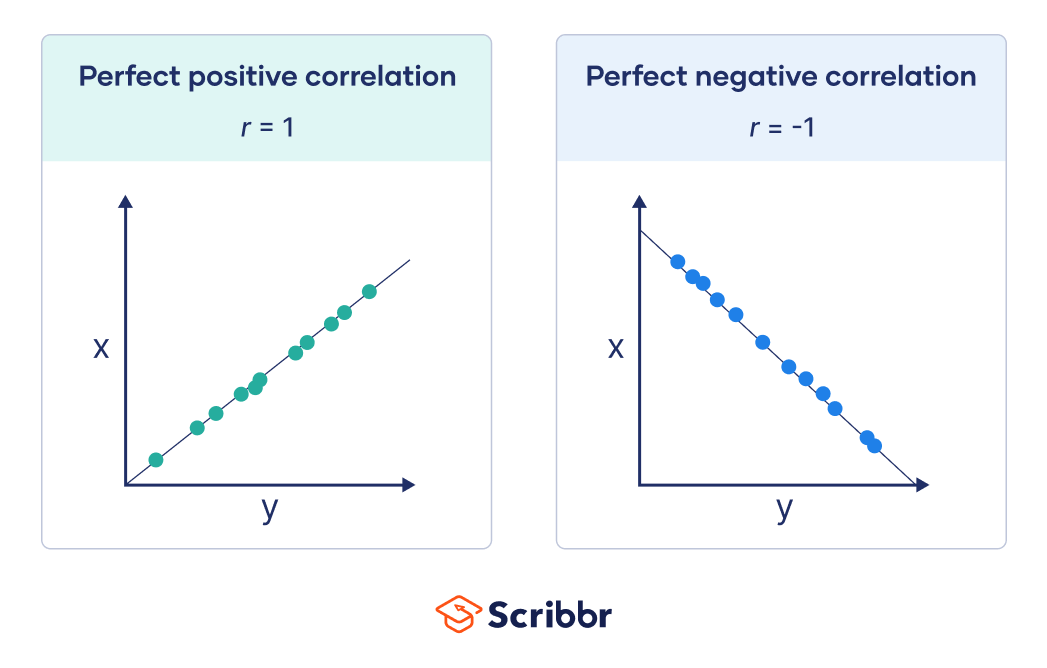
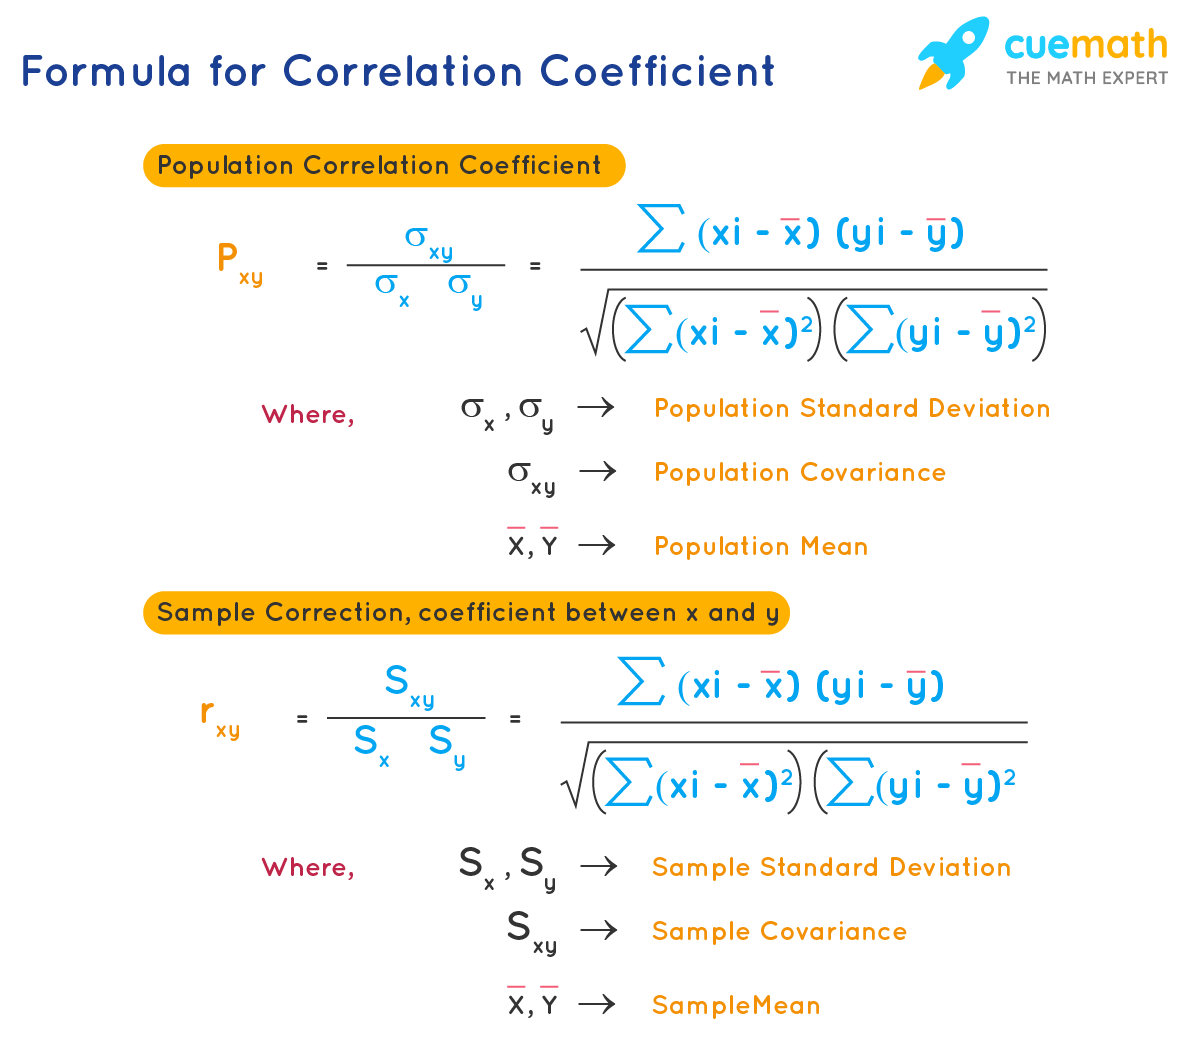
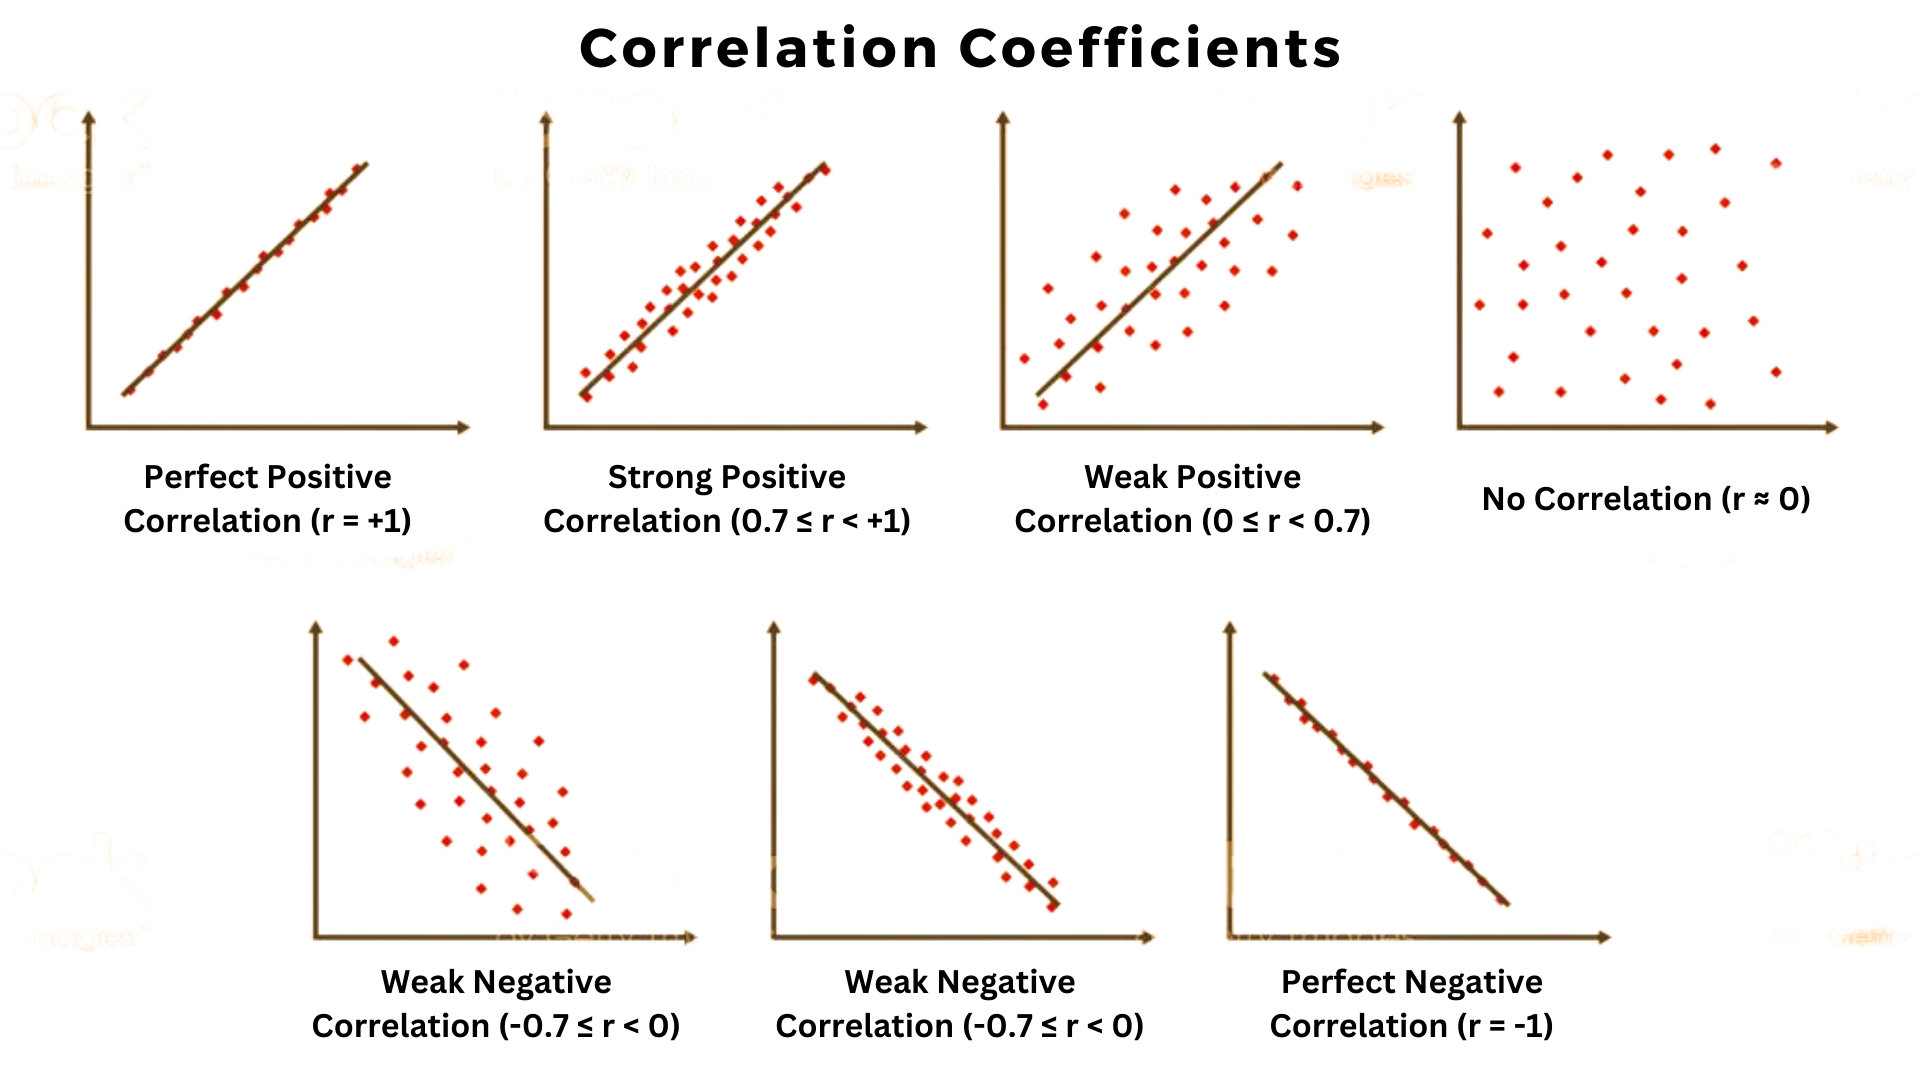
When someone asks What Is A Correlation Coefficient, the short answer is that it is a single number summarizing how two variables move together. The standard one is Pearson's r, which ranges from -1 to +1. Positive values mean the variables tend to increase together, negative means one increases as the other decreases, and values near zero mean there is no linear relationship. That is the textbook version. The practical version is messier, and most people who use this metric incorrectly do so because they stop reading at that point. Pearson's r is calculated by taking the covariance of two variables and dividing it by the product of their standard deviations. In plain English, you measure how much X and Y vary together, then normalize that by how much each varies on its own. The result is unitless, which is why you can compare correlations across completely different datasets. If you have 100 observations, the computation takes maybe 30 seconds on a standard laptop using any reasonable statistical package. Most people just call it directly and move on. The formula is:
r = ((x_i - x)(y_i - ȳ)) / ((x_i - x)² × (y_i - ȳ)²) But the formula is not the hard part. Understanding what it actually captures and what it misses is where people get burned.
The Counter-Intuitive Stuff Nobody Warns You About
The biggest misconception is that a correlation of zero means nothing is happening. It only means nothing linear is happening. I spent a week trying to figure out why a regression model was garbage because two supposedly independent predictors had zero correlation between them. Then I plotted them. They had a perfect U-shaped relationship. The variables were deeply dependent. The correlation coefficient was sitting at 0.03. I ended up swapping in a distance correlation calculation, which picked up the non-linear structure immediately. That single diagnostic saved a couple of days of debugging on top of the original week. Another thing that gets overlooked is that outliers can inflate or deflate r dramatically. A single bad data point can push a correlation from 0.1 to 0.7 without changing anything about the actual relationship between the variables. I once had a dataset where removing one observation changed the entire conclusion of the analysis. The fix was straightforward: run the correlation with and without the outlier, report both, and let the reader decide. But most people just report the number and move on. There is also the issue of range restriction. If you only look at a narrow slice of the data, correlations shrink. This comes up constantly in industrial settings where sensors only operate within a limited range. The underlying relationship might be strong, but because your data does not span the full possible range, r underestimates it. I usually check the distribution of each variable before trusting any correlation value. If the spread looks artificially constrained, I flag it rather than interpreting the coefficient at face value.
Get the Full Details
When Correlation Coefficients Fail Completely
Pearson's r assumes linearity, homoscedasticity, and roughly normal distributions for both variables. If any of those are violated, the coefficient becomes unreliable. Spurious correlations are the most obvious failure mode. I ran a correlation between ice cream sales and drowning incidents last summer as a joke and got 0.82. Both variables are driven by temperature. The correlation is real but meaningless for prediction or causation. This is why you always check for confounding variables before citing any correlation as evidence of anything substantive. Another failure case is time series data with strong autocorrelation. Running a standard Pearson correlation on two non-stationary series is essentially guaranteed to produce a misleading result. I encountered this when analyzing sensor data from manufacturing equipment. The raw correlation looked significant. After differencing the series to remove the trend, the correlation dropped to near zero. The apparent relationship was entirely driven by both series drifting upward over time. The workaround was to test for stationarity first using an Augmented Dickey-Fuller test and only compute correlations on stationary series.
Practical Workflow I Actually Use
When I need to understand what Is A Correlation Coefficient telling me in a real project, I follow a specific sequence. First, I plot the data. Always. A scatterplot takes five seconds and reveals issues that a single number cannot. Second, I compute Pearson's r and also Spearman's rank correlation. If the two differ substantially, the relationship is non-monotonic or contains influential outliers. Third, I check for confounding variables by computing partial correlations or stratifying the data. Fourth, I run a sensitivity analysis by removing the most extreme 5% of observations and recomputing. If the coefficient changes by more than 0.2, I report the range rather than a single value. This process typically adds about 20 minutes to a project that might otherwise take five minutes of correlation computation. The extra time is rarely wasted. I have seen too many reports where a published correlation turned out to be an artifact of outliers or range restriction, and the retraction cost far more than those 20 minutes ever would have.
Bottom Line on What Is A Correlation Coefficient
A correlation coefficient is a descriptive statistic, not a verdict. It quantifies linear association in a specific way. It does not establish causation. It does not capture non-linear relationships. It is sensitive to outliers and range restriction. It fails on non-stationary data. Treat it as a starting point for investigation, not an endpoint. The number itself is simple. Understanding its limitations is what separates people who use this tool correctly from people who use it incorrectly and then wonder why their conclusions fall apart later.